• bitcoinBitcoin(BTC)$81,314.001.43%
  • ethereumEthereum(ETH)$2,637.793.13%
  • tetherTether(USDT)$1.000.03%
  • binancecoinBNB(BNB)$769.811.71%
  • rippleXRP(XRP)$1.445.60%
  • usd-coinUSDC(USDC)$1.000.02%
  • solanaSolana(SOL)$111.652.80%
  • tronTRON(TRX)$0.337874-0.29%
  • zcashZcash(ZEC)$1,531.624.52%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.030.33%
  • HyperliquidHyperliquid(HYPE)$92.552.09%
  • dogecoinDogecoin(DOGE)$0.0889382.07%
  • moneroMonero(XMR)$578.717.62%
  • RainRain(RAIN)$0.01394010.64%
  • whitebitWhiteBIT Coin(WBT)$83.140.94%
  • USDSUSDS(USDS)$1.000.00%
  • chainlinkChainlink(LINK)$12.494.02%
  • cardanoCardano(ADA)$0.2272364.71%
  • leo-tokenLEO Token(LEO)$8.890.19%
  • stellarStellar(XLM)$0.2003385.53%
  • uniswapUniswap(UNI)$9.034.60%
  • bitcoin-cashBitcoin Cash(BCH)$252.880.38%
  • Ethena USDeEthena USDe(USDE)$1.000.02%
  • nearNEAR Protocol(NEAR)$3.59-0.21%
  • daiDai(DAI)$1.000.02%
  • litecoinLitecoin(LTC)$57.844.27%
  • CantonCanton(CC)$0.1112842.84%
  • USD1USD1(USD1)$1.000.03%
  • avalanche-2Avalanche(AVAX)$9.3315.61%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.391.05%
  • hedera-hashgraphHedera(HBAR)$0.0810224.29%
  • suiSui(SUI)$0.856.29%
  • Global DollarGlobal Dollar(USDG)$1.00-0.01%
  • shiba-inuShiba Inu(SHIB)$0.0000051.03%
  • BittensorBittensor(TAO)$267.917.66%
  • crypto-com-chainCronos(CRO)$0.0599440.29%
  • MemeCoreMemeCore(M)$1.30-0.59%
  • paypal-usdPayPal USD(PYUSD)$1.000.00%
  • tether-goldTether Gold(XAUT)$4,372.680.44%
  • okbOKB(OKB)$120.994.60%
  • Circle USYCCircle USYC(USYC)$1.140.00%
  • Ripple USDRipple USD(RLUSD)$1.00-0.02%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.08%
  • aaveAave(AAVE)$142.832.62%
  • mantleMantle(MNT)$0.647.57%
  • AsterAster(ASTER)$0.772.35%
  • OndoOndo(ONDO)$0.4254347.84%
  • EthenaEthena(ENA)$0.20084723.39%
  • Pump.funPump.fun(PUMP)$0.004144-3.24%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

LangChain’s Align Evals closes the evaluator trust gap with prompt-level calibration

July 30, 2025
in AI & Technology
Reading Time: 4 mins read
A A
LangChain’s Align Evals closes the evaluator trust gap with prompt-level calibration
ShareShareShareShareShare

Want smarter insights in your inbox? Sign up for our weekly newsletters to get only what matters to enterprise AI, data, and security leaders. Subscribe Now


As enterprises increasingly turn to AI models to ensure their applications function well and are reliable, the gaps between model-led evaluations and human evaluations have only become clearer. 

YOU MAY ALSO LIKE

Google Gemini Also Escaped Its Testing Environment And Hacked Three Companies

What Is AI Agent Memory? Short-Term, Long-Term, Episodic, and Semantic Memory Explained – Unite.AI

To combat this, LangChain added Align Evals to LangSmith, a way to bridge the gap between large language model-based evaluators and human preferences and reduce noise. Align Evals enables LangSmith users to create their own LLM-based evaluators and calibrate them to align more closely with company preferences. 

“But, one big challenge we hear consistently from teams is: ‘Our evaluation scores don’t match what we’d expect a human on our team to say.’ This mismatch leads to noisy comparisons and time wasted chasing false signals,” LangChain said in a blog post. 

LangChain is one of the few platforms to integrate LLM-as-a-judge, or model-led evaluations for other models, directly into the testing dashboard. 


The AI Impact Series Returns to San Francisco – August 5

The next phase of AI is here – are you ready? Join leaders from Block, GSK, and SAP for an exclusive look at how autonomous agents are reshaping enterprise workflows – from real-time decision-making to end-to-end automation.

Secure your spot now – space is limited: https://bit.ly/3GuuPLF


The company said that it based Align Evals on a paper by Amazon principal applied scientist Eugene Yan. In his paper, Yan laid out the framework for an app, also called AlignEval, that would automate parts of the evaluation process. 

Align Evals would allow enterprises and other builders to iterate on evaluation prompts, compare alignment scores from human evaluators and LLM-generated scores and to a baseline alignment score. 

LangChain said Align Evals “is the first step in helping you build better evaluators.” Over time, the company aims to integrate analytics to track performance and automate prompt optimization, generating prompt variations automatically. 

How to start 

Users will first identify evaluation criteria for their application. For example, chat apps generally require accuracy.

Next, users have to select the data they want for human review. These examples must demonstrate both good and bad aspects so that human evaluators can gain a holistic view of the application and assign a range of grades. Developers then have to manually assign scores for prompts or task goals that will serve as a benchmark. 

This is one of my favorite features that we’ve launched!

Creating LLM-as-a-Judge evaluators is hard – this hopefully makes that flow a bit easier

I believe in this flow so much I even recorded a video around it! https://t.co/FlPOJcko12 https://t.co/wAQpYZMeov

— Harrison Chase (@hwchase17) July 30, 2025

Developers then need to create an initial prompt for the model evaluator and iterate using the alignment results from the human graders. 

“For example, if your LLM consistently over-scores certain responses, try adding clearer negative criteria. Improving your evaluator score is meant to be an iterative process. Learn more about best practices on iterating on your prompt in our docs,” LangChain said.

Growing number of LLM evaluations

Increasingly, enterprises are turning to evaluation frameworks to assess the reliability, behavior, task alignment and auditability of AI systems, including applications and agents. Being able to point to a clear score of how models or agents perform provides organizations not just the confidence to deploy AI applications, but also makes it easier to compare other models. 

Companies like Salesforce and AWS began offering ways for customers to judge performance. Salesforce’s Agentforce 3 has a command center that shows agent performance. AWS provides both human and automated evaluation on the Amazon Bedrock platform, where users can choose the model to test their applications on, though these are not user-created model evaluators. OpenAI also offers model-based evaluation.

Meta’s Self-Taught Evaluator builds on the same LLM-as-a-judge concept that LangSmith uses, though Meta has yet to make it a feature for any of its application-building platforms. 

As more developers and businesses demand easier evaluation and more customized ways to assess performance, more platforms will begin to offer integrated methods for using models to evaluate other models, and many more will provide tailored options for enterprises. 

this is exactly what the mcp ecosystem needs – better evaluation tools for llm workflows. we’ve been seeing developers struggle with this in jenova ai, especially when they’re orchestrating complex multi-tool chains and need to validate outputs.

the align evals approach of…

— Aiden (@Aiden_Novaa) July 30, 2025

Daily insights on business use cases with VB Daily

If you want to impress your boss, VB Daily has you covered. We give you the inside scoop on what companies are doing with generative AI, from regulatory shifts to practical deployments, so you can share insights for maximum ROI.

Read our Privacy Policy

Thanks for subscribing. Check out more VB newsletters here.

An error occured.

Credit: Source link
ShareTweetSendSharePin

Related Posts

Google Gemini Also Escaped Its Testing Environment And Hacked Three Companies
AI & Technology

Google Gemini Also Escaped Its Testing Environment And Hacked Three Companies

September 19, 2026
What Is AI Agent Memory? Short-Term, Long-Term, Episodic, and Semantic Memory Explained – Unite.AI
AI & Technology

What Is AI Agent Memory? Short-Term, Long-Term, Episodic, and Semantic Memory Explained – Unite.AI

September 19, 2026
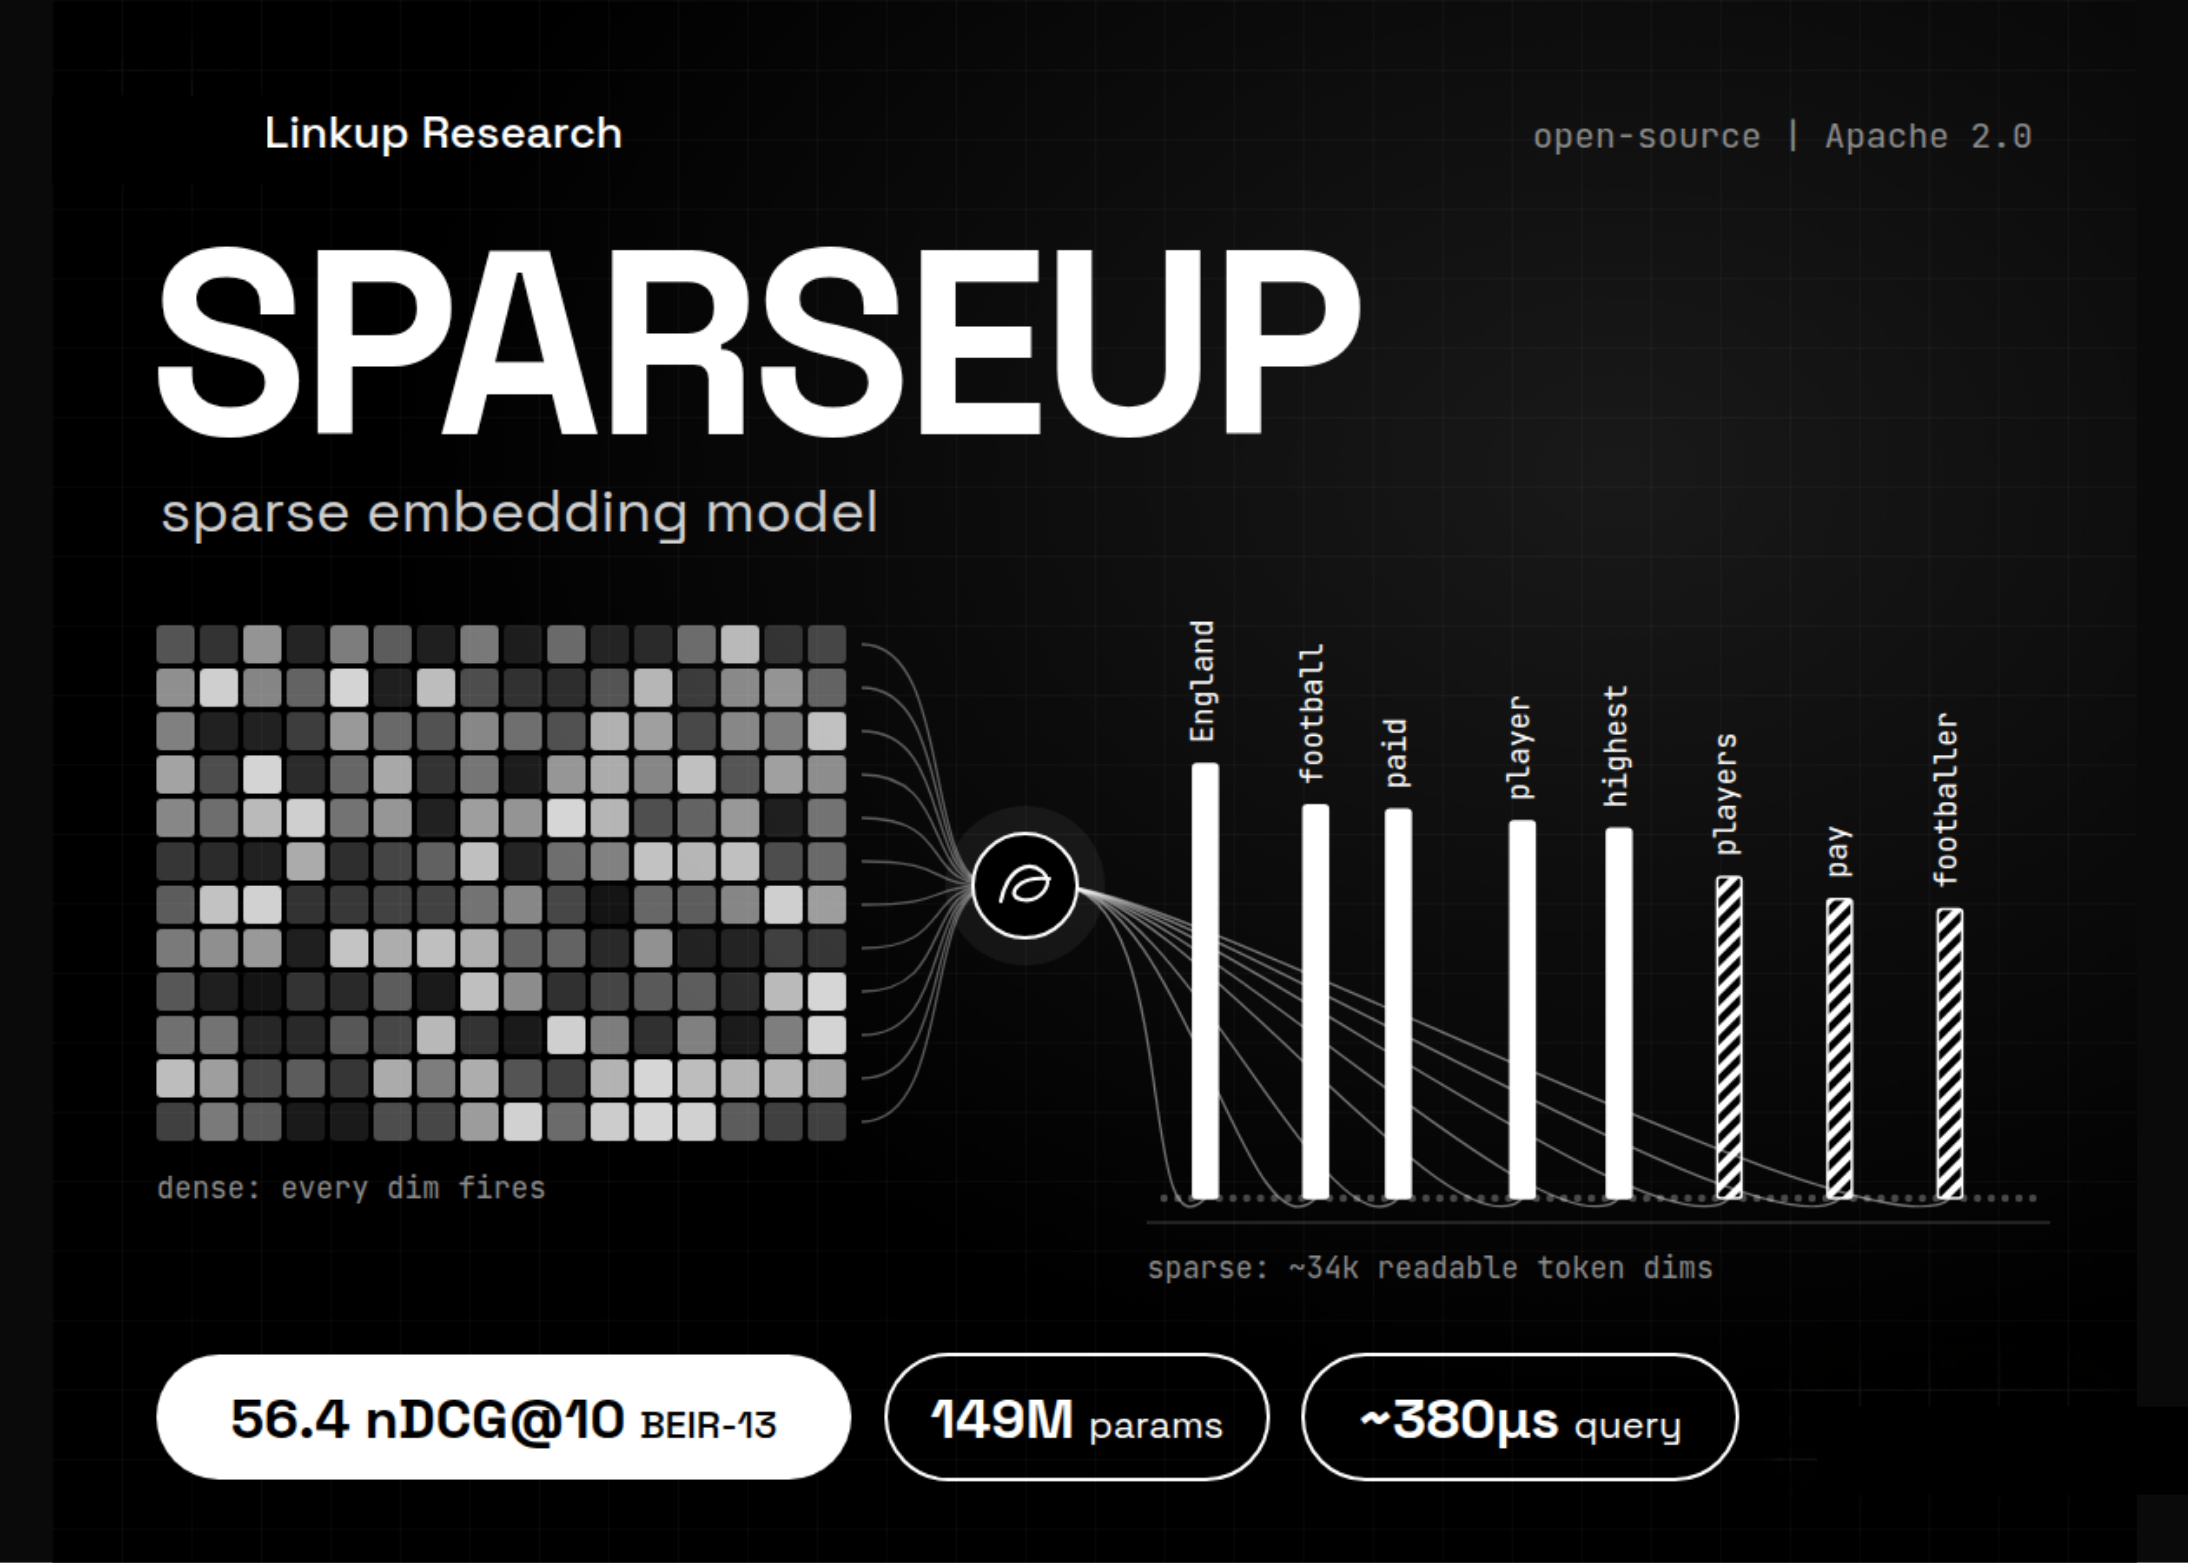
Linkup Research Releases SPARSEUP: A 149M-Parameter Open-Source Sparse Embedding Model
AI & Technology

Linkup Research Releases SPARSEUP: A 149M-Parameter Open-Source Sparse Embedding Model

September 19, 2026
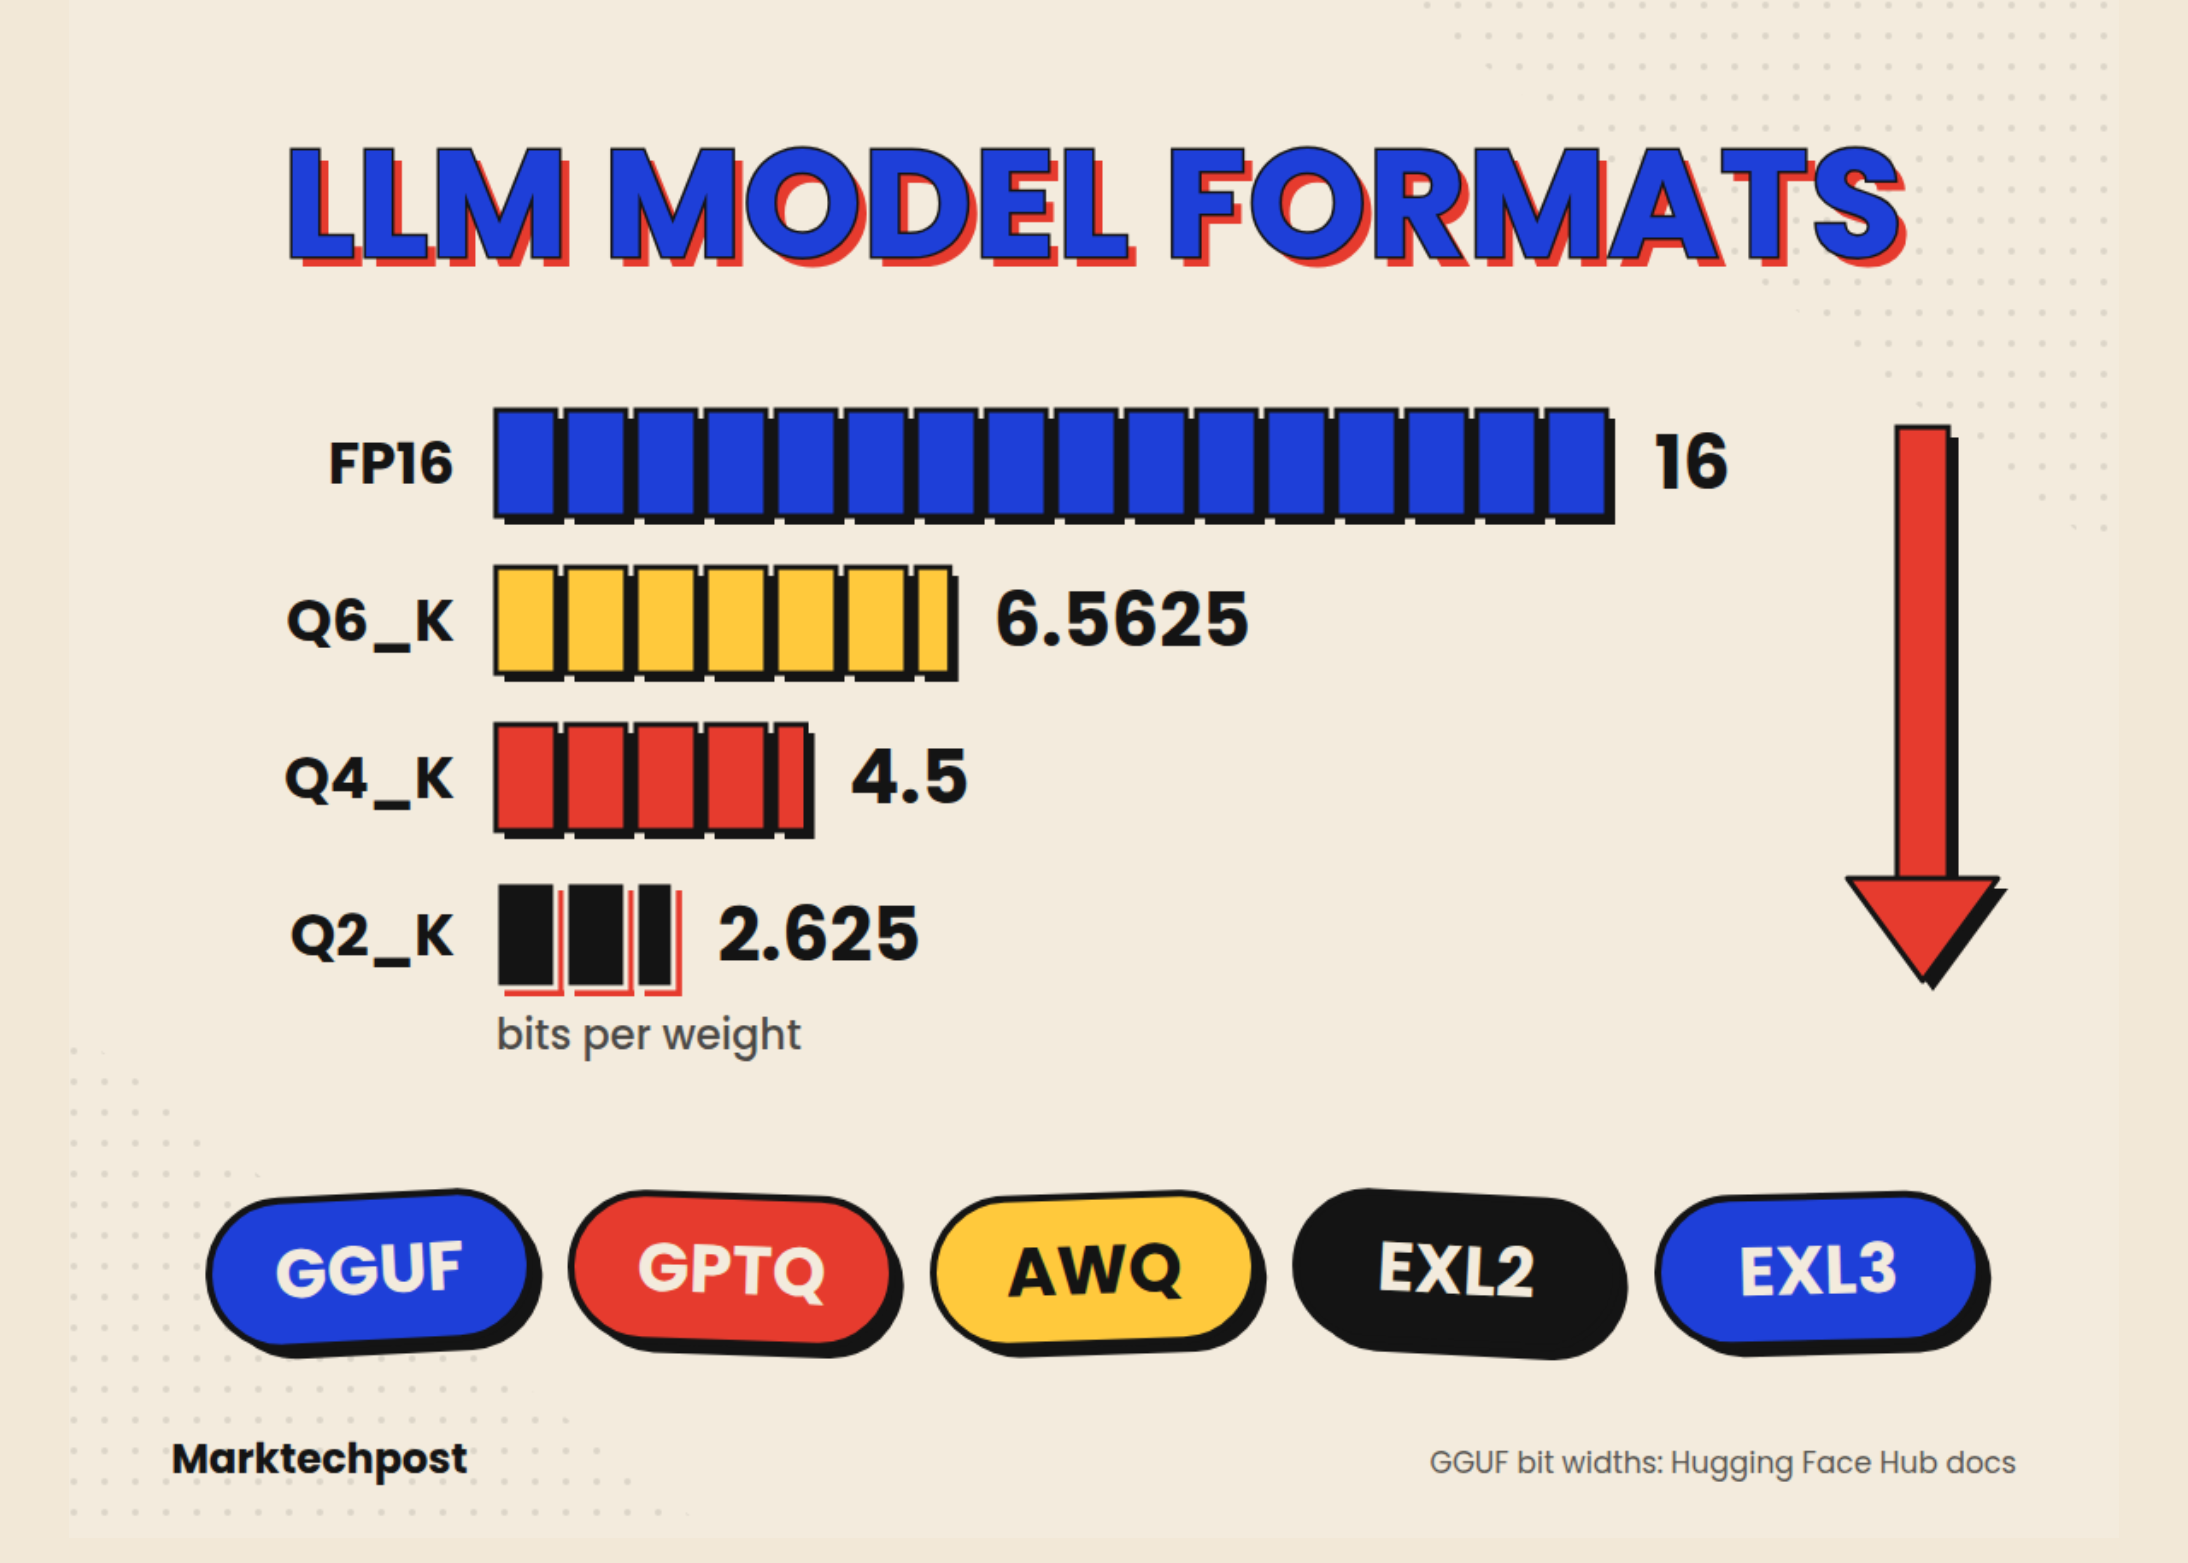
GGUF vs GPTQ vs AWQ vs EXL2: LLM Model Formats Explained (2026)
AI & Technology

GGUF vs GPTQ vs AWQ vs EXL2: LLM Model Formats Explained (2026)

September 19, 2026
Next Post
Trump says US will set 15% tariff on South Korean imports under new deal – Reuters

Trump says US will set 15% tariff on South Korean imports under new deal - Reuters

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
NBC Nightly News with Tom Llamas Full Episode – Sept. 10

NBC Nightly News with Tom Llamas Full Episode – Sept. 10

September 13, 2026
Kelsey Mitchell sets WNBA season scoring record, fêted by Fever – ESPN

Kelsey Mitchell sets WNBA season scoring record, fêted by Fever – ESPN

September 19, 2026
How the 9/11 Generation Is Passing Down Their Shared History | Sept. 11

How the 9/11 Generation Is Passing Down Their Shared History | Sept. 11

September 13, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!