Large Language Models (LLMs) have demonstrated exceptional capabilities across diverse applications, but their widespread adoption faces significant challenges. The primary concern stems from training datasets that contain varied, unfocused, and potentially harmful content, including malicious code and cyberattack-related information. This creates a critical need to align LLM outputs with specific user requirements while preventing misuse. Current approaches like Reinforcement Learning from Human Feedback (RLHF) attempt to address these issues by incorporating human preferences into model behavior. However, RLHF faces substantial limitations due to its high computational requirements, dependence on complex reward models, and the inherent instability of reinforcement learning algorithms. This situation necessitates more efficient and reliable methods to fine-tune LLMs while maintaining their performance and ensuring responsible AI development.
Various alignment methods have emerged to address the challenges of fine-tuning LLMs with human preferences. RLHF initially gained prominence by using a reward model trained on human preference data, combined with reinforcement learning algorithms like PPO to optimize model behavior. However, its complex implementation and resource-intensive nature led to the development of Direct Policy Optimization (DPO), which simplifies the process by eliminating the need for a reward model and using binary cross-entropy loss instead. Recent research has explored different divergence measures to control output diversity, particularly focusing on α-divergence as a way to balance between reverse KL and forward KL divergence. Also, researchers have investigated various approaches to enhance response diversity, including temperature-based sampling techniques, prompt manipulation, and objective function modifications. The importance of diversity has become increasingly relevant, especially in tasks where coverage – the ability to solve problems through multiple generated samples – is crucial, such as in mathematical and coding applications.
Researchers from The University of Tokyo and Preferred Networks, Inc. introduce H-DPO, a robust modification to the traditional DPO approach that addresses the limitations of mode-seeking behavior. The key innovation lies in controlling the entropy of the resulting policy distribution, which enables more effective capture of target distribution modes. Traditional reverse KL divergence minimization can sometimes fail to achieve proper mode-seeking fitting by preserving variance when fitting an unimodal distribution to a multimodal target. H-DPO addresses this by introducing a hyperparameter α that modifies the regularization term, allowing for deliberate entropy reduction when α < 1. This approach aligns with practical observations that LLMs often perform better with lower temperature values during evaluation. Unlike post-training temperature adjustments, H-DPO incorporates this distribution sharpening directly into the training objective, ensuring optimal alignment with the desired behavior while maintaining implementation simplicity.
The H-DPO methodology introduces a robust approach to entropy control in language model alignment by modifying the reverse KL divergence regularization term. The method decomposes reverse KL divergence into entropy and cross-entropy components, introducing a coefficient α that enables precise control over the distribution’s entropy. The objective function for H-DPO is formulated as JH-DPO, which combines the expected reward with the modified divergence term. When α equals 1, the function maintains standard DPO behavior, but setting α below 1 encourages entropy reduction. Through constrained optimization using Lagrange multipliers, the optimal policy is derived as a function of the reference policy and reward, with α controlling the sharpness of the distribution. The implementation requires minimal modification to the existing DPO framework, essentially involving the replacement of the coefficient β with αβ in the loss function, making it highly practical for real-world applications.
The experimental evaluation of H-DPO demonstrated significant improvements across multiple benchmarks compared to standard DPO. The method was tested on diverse tasks including grade school math problems (GSM8K), coding tasks (HumanEval), multiple-choice questions (MMLU-Pro), and instruction-following tasks (IFEval). By reducing α to values between 0.95 and 0.9, H-DPO achieved performance improvements across all tasks. The diversity metrics showed interesting trade-offs: lower α values resulted in reduced diversity at temperature 1, while higher α values increased diversity. However, the relationship between α and diversity proved more complex when considering temperature variations. On the GSM8K benchmark, H-DPO with α=0.8 achieved optimal coverage at the training temperature of 1, outperforming standard DPO’s best results at temperature 0.5. Importantly, on HumanEval, larger α values (α=1.1) showed superior performance for extensive sampling scenarios (k>100), indicating that response diversity played a crucial role in coding task performance.
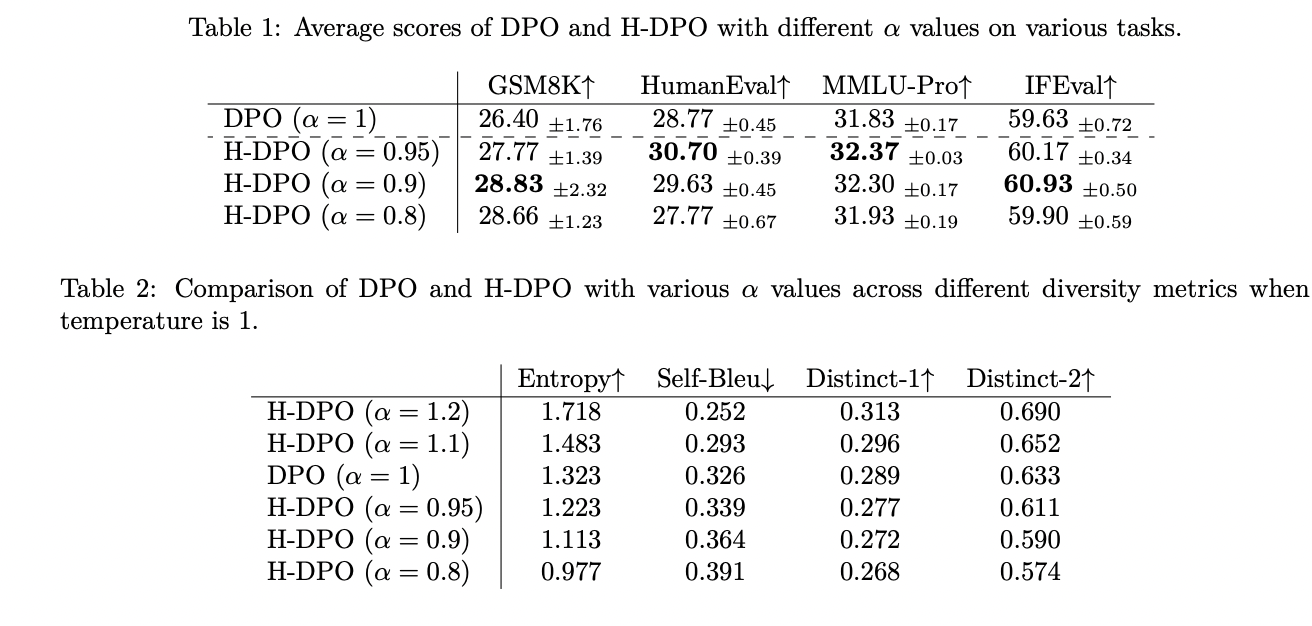
H-DPO represents a significant advancement in language model alignment, offering a simple yet effective modification to the standard DPO framework. Through its innovative entropy control mechanism via the hyperparameter α, the method achieves superior mode-seeking behavior and enables more precise control over output distribution. The experimental results across various tasks demonstrated improved accuracy and diversity in model outputs, particularly excelling in mathematical reasoning and coverage metrics. While the manual tuning of α remains a limitation, H-DPO’s straightforward implementation and impressive performance make it a valuable contribution to the field of language model alignment, paving the way for more effective and controllable AI systems.
Check out the Paper. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter and join our Telegram Channel and LinkedIn Group. If you like our work, you will love our newsletter.. Don’t Forget to join our 55k+ ML SubReddit.
[FREE AI WEBINAR] Implementing Intelligent Document Processing with GenAI in Financial Services and Real Estate Transactions– From Framework to Production

Asjad is an intern consultant at Marktechpost. He is persuing B.Tech in mechanical engineering at the Indian Institute of Technology, Kharagpur. Asjad is a Machine learning and deep learning enthusiast who is always researching the applications of machine learning in healthcare.
Credit: Source link