


















• bitcoinBitcoin(BTC)$80,638.006.22%
  • ethereumEthereum(ETH)$2,432.248.83%
  • tetherTether(USDT)$1.000.04%
  • binancecoinBNB(BNB)$716.754.76%
  • rippleXRP(XRP)$1.314.63%
  • usd-coinUSDC(USDC)$1.000.02%
  • solanaSolana(SOL)$96.696.83%
  • tronTRON(TRX)$0.319258-0.74%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.051.53%
  • zcashZcash(ZEC)$1,323.2713.10%
  • HyperliquidHyperliquid(HYPE)$84.262.90%
  • dogecoinDogecoin(DOGE)$0.0772746.09%
  • moneroMonero(XMR)$636.431.29%
  • USDSUSDS(USDS)$1.000.02%
  • whitebitWhiteBIT Coin(WBT)$78.066.93%
  • chainlinkChainlink(LINK)$11.527.65%
  • leo-tokenLEO Token(LEO)$9.350.51%
  • cardanoCardano(ADA)$0.1990677.98%
  • stellarStellar(XLM)$0.1687896.78%
  • bitcoin-cashBitcoin Cash(BCH)$281.955.58%
  • nearNEAR Protocol(NEAR)$4.069.00%
  • uniswapUniswap(UNI)$7.729.93%
  • daiDai(DAI)$1.000.03%
  • Ethena USDeEthena USDe(USDE)$1.000.06%
  • litecoinLitecoin(LTC)$56.407.36%
  • RainRain(RAIN)$0.005986-6.46%
  • CantonCanton(CC)$0.1015716.43%
  • avalanche-2Avalanche(AVAX)$8.845.86%
  • suiSui(SUI)$0.938.12%
  • USD1USD1(USD1)$1.000.06%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.182.40%
  • tether-goldTether Gold(XAUT)$4,111.894.76%
  • hedera-hashgraphHedera(HBAR)$0.0734677.95%
  • quant-networkQuant(QNT)$205.529.39%
  • shiba-inuShiba Inu(SHIB)$0.0000055.60%
  • Global DollarGlobal Dollar(USDG)$1.000.02%
  • BittensorBittensor(TAO)$237.528.20%
  • paypal-usdPayPal USD(PYUSD)$1.000.02%
  • crypto-com-chainCronos(CRO)$0.0522786.24%
  • Ripple USDRipple USD(RLUSD)$1.000.02%
  • EthenaEthena(ENA)$0.1831578.98%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.15-0.09%
  • okbOKB(OKB)$112.505.92%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • pepePepe(PEPE)$0.0000056.29%
  • aaveAave(AAVE)$132.876.98%
  • OndoOndo(ONDO)$0.4143629.42%
  • Pump.funPump.fun(PUMP)$0.0043696.21%
  • MemeCoreMemeCore(M)$0.841.69%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Google Proposes TUMIX: Multi-Agent Test-Time Scaling With Tool-Use Mixture

October 4, 2025
in AI & Technology
Reading Time: 9 mins read
A A
Google Proposes TUMIX: Multi-Agent Test-Time Scaling With Tool-Use Mixture
ShareShareShareShareShare

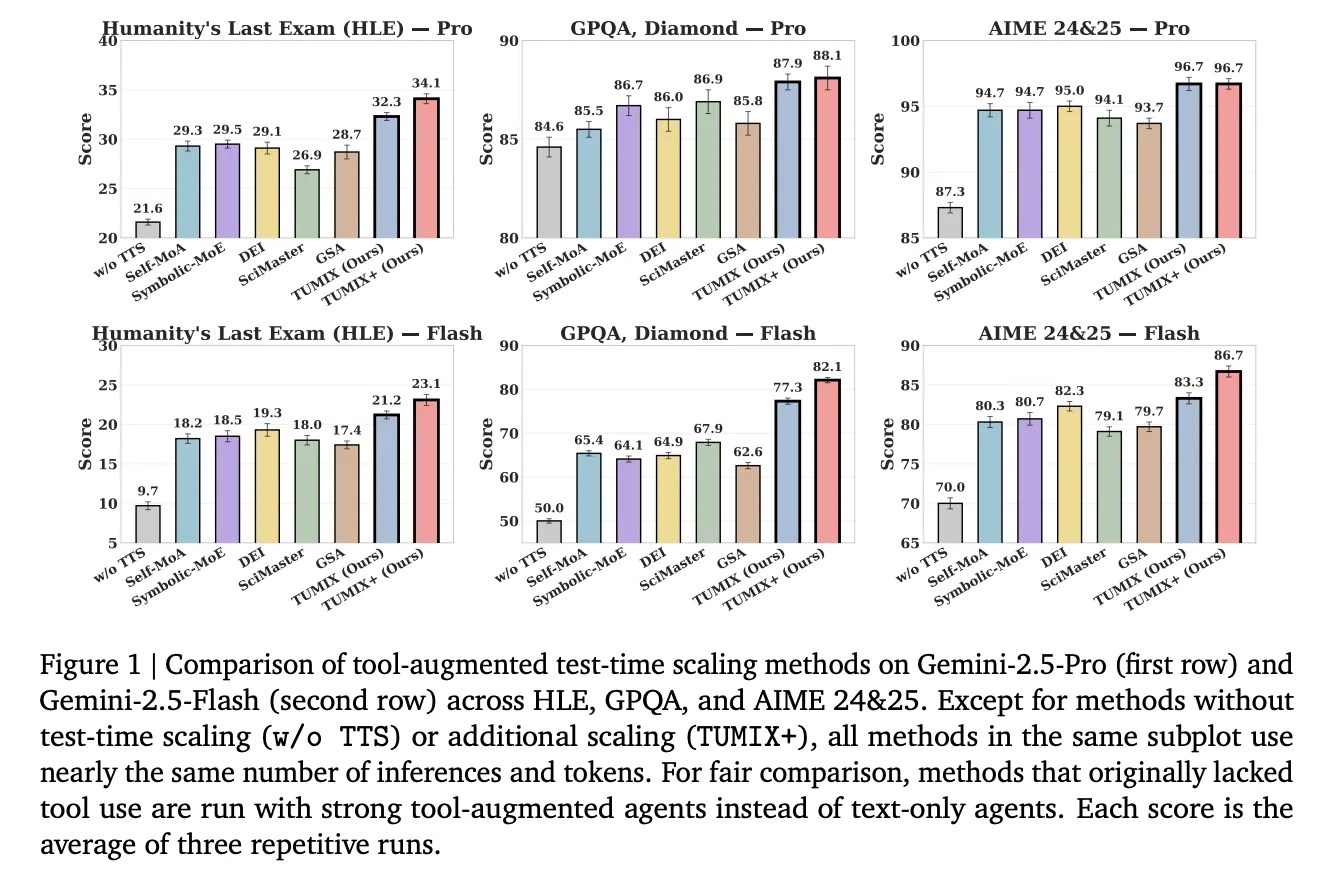
What if, instead of re-sampling one agent, you could push Gemini-2.5 Pro to 34.1% on HLE by mixing 12–15 tool-using agents that share notes and stop early? Google Cloud AI Research, with collaborators from MIT, Harvard, and Google DeepMind, introduced TUMIX (Tool-Use Mixture)—a test-time framework that ensembles heterogeneous agent styles (text-only, code, search, guided variants) and lets them share intermediate answers over a few refinement rounds, then stop early via an LLM-based judge. The result: higher accuracy at lower cost on hard reasoning benchmarks such as HLE, GPQA-Diamond, and AIME (2024/2025).
https://arxiv.org/pdf/2510.01279

So, What exactly is different new?

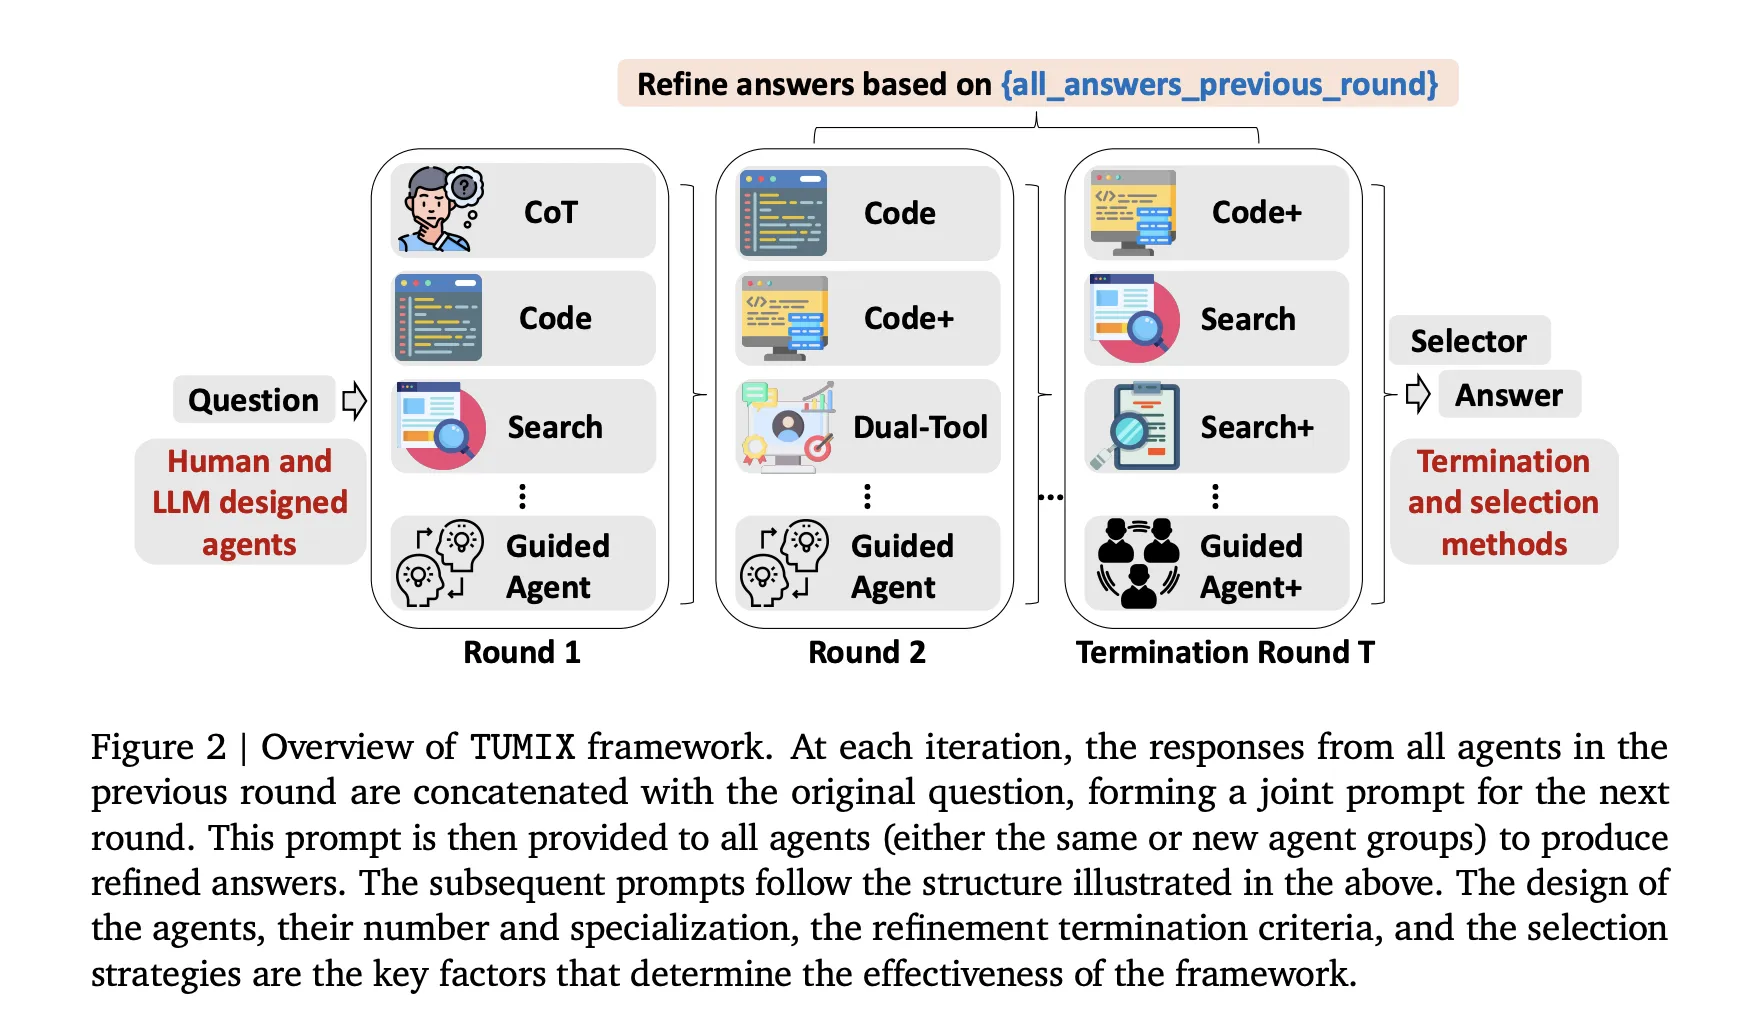
  • Mixture over modality, not just more samples: TUMIX runs ~15 agent styles spanning Chain-of-Thought (CoT), code execution, web search, dual-tool agents, and guided variants. Each round, every agent sees (a) the original question and (b) other agents’ previous answers, then proposes a refined answer. This message-passing raises average accuracy early while diversity gradually collapses—so stopping matters.
  • Adaptive early-termination: An LLM-as-Judge halts refinement once answers exhibit strong consensus (with a minimum round threshold). This preserves accuracy at ~49% of the inference cost vs. fixed-round refinement; token cost drops to ~46% because late rounds are token-heavier.
  • Auto-designed agents: Beyond human-crafted agents, TUMIX prompts the base LLM to generate new agent types; mixing these with the manual set yields an additional ~+1.2% average lift without extra cost. The empirical “sweet spot” is ~12–15 agent styles.
https://arxiv.org/pdf/2510.01279

How does it work?

TUMIX runs a group of heterogeneous agents—text-only Chain-of-Thought, code-executing, web-searching, and guided variants—in parallel, then iterates a small number of refinement rounds where each agent conditions on the original question plus the other agents’ prior rationales and answers (structured note-sharing). After each round, an LLM-based judge evaluates consensus/consistency to decide early termination; if confidence is insufficient, another round is triggered, otherwise the system finalizes via simple aggregation (e.g., majority vote or selector). This mixture-of-tool-use design trades brute-force re-sampling for diverse reasoning paths, improving coverage of correct candidates while controlling token/tool budgets; empirically, benefits saturate around 12–15 agent styles, and stopping early preserves diversity and lowers cost without sacrificing accuracy

YOU MAY ALSO LIKE

Cat Wu to Lead Product Management for OpenAI’s Core Products – Unite.AI

Snap Has More Than 30 Million Paid Subscribers Across Snapchat+ And Other Plans

Lets discuss the Results

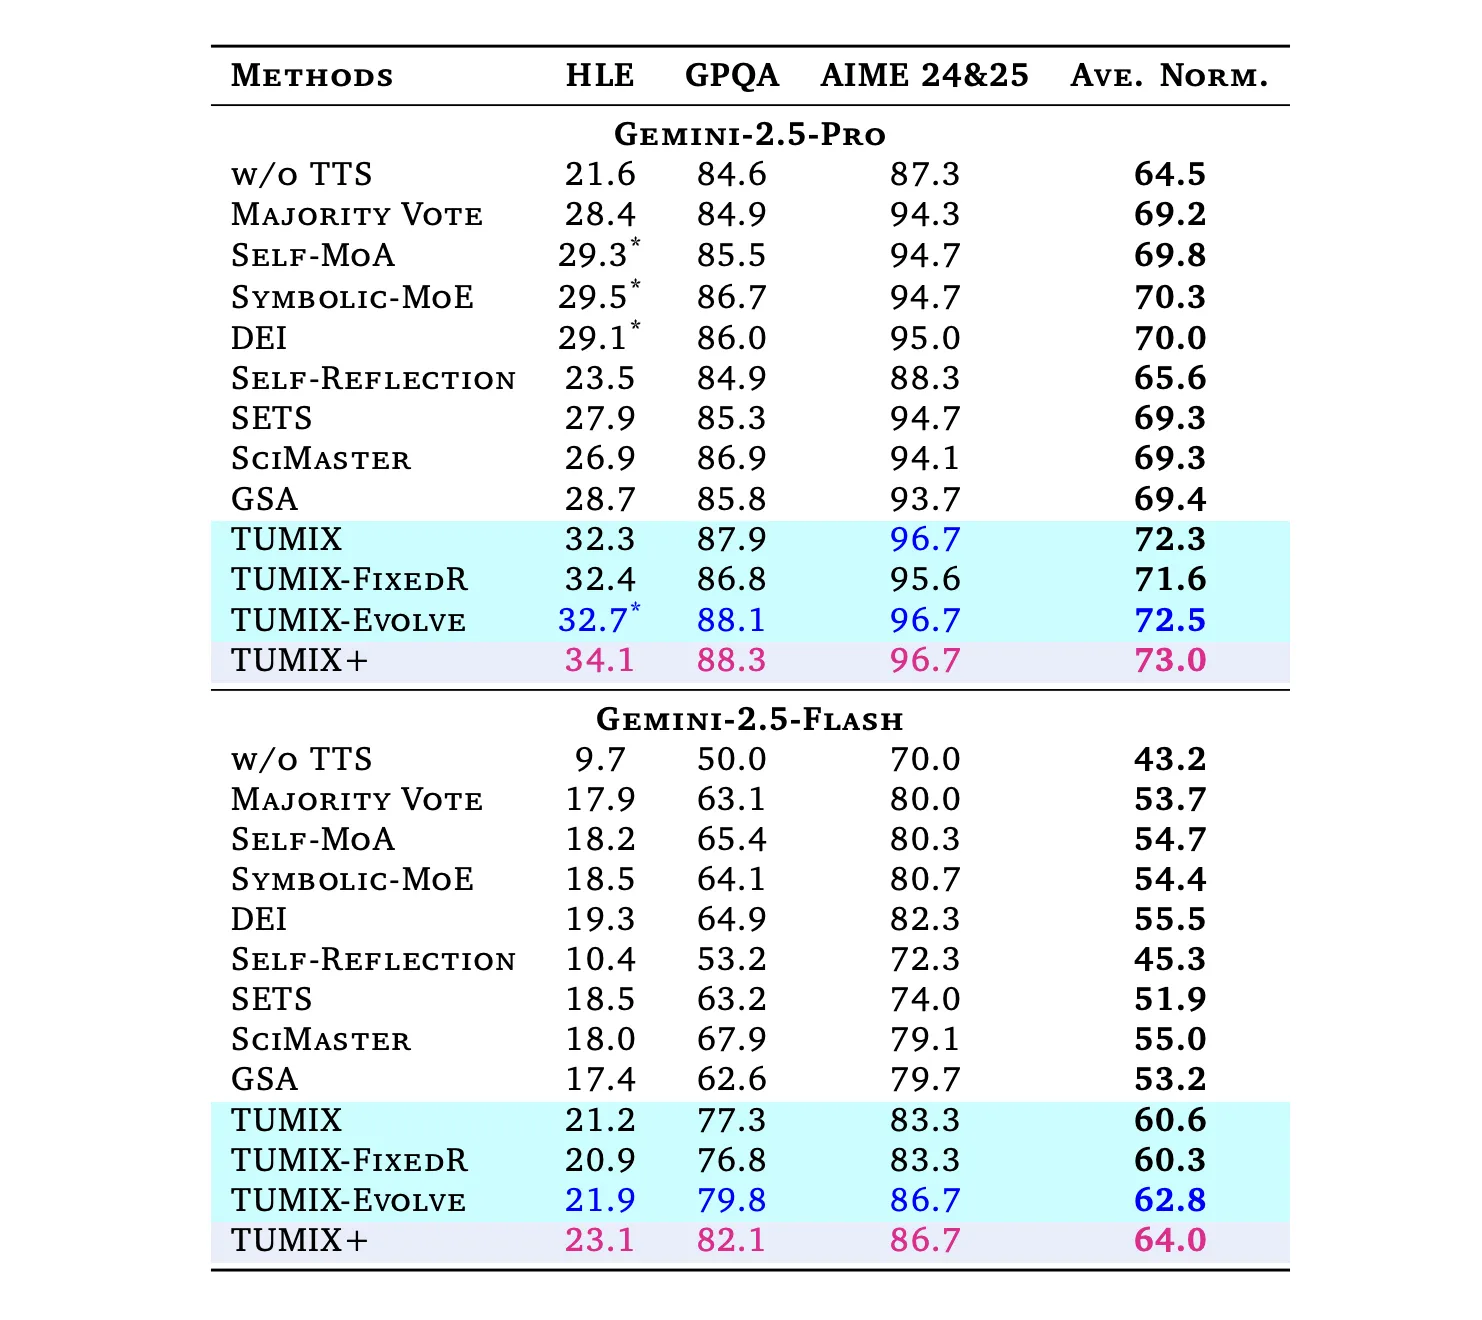
Under comparable inference budgets to strong tool-augmented baselines (Self-MoA, Symbolic-MoE, DEI, SciMaster, GSA), TUMIX yields the best average accuracy; a scaled variant (TUMIX+) pushes further with more compute:

  • HLE (Humanity’s Last Exam): Pro: 21.6% → 34.1% (TUMIX+); Flash: 9.7% → 23.1%.
    (HLE is a 2,500-question, difficult, multi-domain benchmark finalized in 2025.)
  • GPQA-Diamond: Pro: up to 88.3%; Flash: up to 82.1%. (GPQA-Diamond is the hardest 198-question subset authored by domain experts.)
  • AIME 2024/25: Pro: 96.7%; Flash: 86.7% with TUMIX(+) at test time.

Across tasks, TUMIX averages +3.55% over the best prior tool-augmented test-time scaling baseline at similar cost, and +7.8% / +17.4% over no-scaling for Pro/Flash, respectively.
https://arxiv.org/pdf/2510.01279

TUMIX is a great approach from Google because it frames test-time scaling as a search problem over heterogeneous tool policies rather than brute-force sampling. The parallel committee (text, code, search) improves candidate coverage, while the LLM-judge enables early-stop that preserves diversity and reduces token/tool spend—useful under latency budgets. The HLE gains (34.1% with Gemini-2.5 Pro) align with the benchmark’s finalized 2,500-question design, and the ~12–15 agent styles “sweet spot” indicates selection—not generation—is the limiting factor.


Check out the Paper. Feel free to check out our GitHub Page for Tutorials, Codes and Notebooks. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.

Asif Razzaq is the CEO of Marktechpost Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.

🙌 Follow MARKTECHPOST: Add us as a preferred source on Google.

Credit: Source link

ShareTweetSendSharePin

Related Posts

Cat Wu to Lead Product Management for OpenAI’s Core Products – Unite.AI
AI & Technology

Cat Wu to Lead Product Management for OpenAI’s Core Products – Unite.AI

November 5, 2026
Snap Has More Than 30 Million Paid Subscribers Across Snapchat+ And Other Plans
AI & Technology

Snap Has More Than 30 Million Paid Subscribers Across Snapchat+ And Other Plans

November 4, 2026
Atmospheric AI Secures M Seed for Procurement Modeling Push – Unite.AI
AI & Technology

Atmospheric AI Secures $10M Seed for Procurement Modeling Push – Unite.AI

November 4, 2026
Perplexity Adds Live Web Grounding to Its Decisions API – Unite.AI
AI & Technology

Perplexity Adds Live Web Grounding to Its Decisions API – Unite.AI

November 4, 2026
Next Post
Assata Shakur, Black Liberation Army figure and activist, dies at 78

Assata Shakur, Black Liberation Army figure and activist, dies at 78

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Binance says North Korean hackers conducted fake job interviews to hack engineer’s laptop

Binance says North Korean hackers conducted fake job interviews to hack engineer’s laptop

November 3, 2026
Packers' Christian Watson makes stunning 'TNF' return after hospital trip – USA Today

Packers' Christian Watson makes stunning 'TNF' return after hospital trip – USA Today

October 30, 2026
Christa Pike’s lawyer calls for commuted death sentence

Christa Pike’s lawyer calls for commuted death sentence

October 30, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!








