• bitcoinBitcoin(BTC)$83,928.00-2.89%
  • ethereumEthereum(ETH)$2,657.46-3.22%
  • tetherTether(USDT)$1.00-0.01%
  • binancecoinBNB(BNB)$763.75-3.25%
  • rippleXRP(XRP)$1.49-4.18%
  • usd-coinUSDC(USDC)$1.00-0.01%
  • solanaSolana(SOL)$114.14-2.77%
  • tronTRON(TRX)$0.338639-0.62%
  • zcashZcash(ZEC)$1,530.42-0.94%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.030.43%
  • HyperliquidHyperliquid(HYPE)$92.77-2.99%
  • dogecoinDogecoin(DOGE)$0.092191-7.27%
  • moneroMonero(XMR)$549.39-4.18%
  • whitebitWhiteBIT Coin(WBT)$84.26-2.81%
  • USDSUSDS(USDS)$1.00-0.02%
  • chainlinkChainlink(LINK)$12.23-5.89%
  • cardanoCardano(ADA)$0.238075-4.43%
  • RainRain(RAIN)$0.012446-7.08%
  • leo-tokenLEO Token(LEO)$8.97-0.01%
  • stellarStellar(XLM)$0.202990-4.95%
  • bitcoin-cashBitcoin Cash(BCH)$351.307.59%
  • uniswapUniswap(UNI)$9.12-0.87%
  • nearNEAR Protocol(NEAR)$4.25-3.91%
  • Ethena USDeEthena USDe(USDE)$1.00-0.01%
  • litecoinLitecoin(LTC)$60.25-2.94%
  • daiDai(DAI)$1.00-0.01%
  • avalanche-2Avalanche(AVAX)$10.25-7.44%
  • USD1USD1(USD1)$1.00-0.01%
  • CantonCanton(CC)$0.108053-4.36%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.41-2.28%
  • hedera-hashgraphHedera(HBAR)$0.090120-6.03%
  • suiSui(SUI)$0.96-4.26%
  • BittensorBittensor(TAO)$292.56-6.31%
  • shiba-inuShiba Inu(SHIB)$0.000006-6.36%
  • Global DollarGlobal Dollar(USDG)$1.000.00%
  • crypto-com-chainCronos(CRO)$0.061721-7.41%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.01%
  • MemeCoreMemeCore(M)$1.21-7.03%
  • tether-goldTether Gold(XAUT)$4,285.06-1.20%
  • BitwayBitway(BTW)$0.9815.58%
  • okbOKB(OKB)$118.34-3.15%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • Ripple USDRipple USD(RLUSD)$1.000.00%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.23%
  • aaveAave(AAVE)$139.57-2.46%
  • mantleMantle(MNT)$0.65-1.20%
  • EthenaEthena(ENA)$0.2088801.27%
  • OndoOndo(ONDO)$0.415667-3.16%
  • Pump.funPump.fun(PUMP)$0.004025-10.87%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

FocusLLM: A Scalable AI Framework for Efficient Long-Context Processing in Language Models

August 26, 2024
in AI & Technology
Reading Time: 4 mins read
A A
FocusLLM: A Scalable AI Framework for Efficient Long-Context Processing in Language Models
ShareShareShareShareShare

Empowering LLMs to handle long contexts effectively is essential for many applications, but conventional transformers require substantial resources for extended context lengths. Long contexts enhance tasks like document summarization and question answering. Yet, several challenges arise: transformers’ quadratic complexity increases training costs, LLMs need help with longer sequences even after fine-tuning, and obtaining high-quality long-text datasets is difficult. To mitigate these issues, methods like modifying attention mechanisms or token compression have been explored, but they often result in information loss, hindering precise tasks like verification and question answering.

Researchers from Tsinghua and Xiamen Universities introduced FocusLLM, a framework designed to extend the context length of decoder-only LLMs. FocusLLM divides long text into chunks and uses a parallel decoding mechanism to extract and integrate relevant information. This approach enhances training efficiency and versatility, allowing LLMs to handle texts up to 400K tokens with minimal training costs. FocusLLM outperforms other methods in tasks like question answering and long-text comprehension, demonstrating superior performance on Longbench and ∞-Bench benchmarks while maintaining low perplexity on extensive sequences.

YOU MAY ALSO LIKE

Logitech’s Yeti 2 Brings The 17-Year-Old USB Mic Into The Modern Age

Never Use ChatGPT For These Five Tasks

Recent advancements in long-context modeling have introduced various approaches to overcome transformer limitations. Length extrapolation methods, like positional interpolation, aim to adapt transformers to longer sequences but often struggle with distractions from noisy content. Other methods modify attention mechanisms or use compression to manage long texts but fail to utilize all tokens effectively. Memory-enhanced models improve long-context comprehension by integrating information into persistent memory or encoding and querying long texts in segments. However, these methods face limitations in memory length extrapolation and high computational costs, whereas FocusLLM achieves greater training efficiency and effectiveness on extremely long texts.

The methodology behind FocusLLM involves adapting the LLM architecture to handle extremely long text sequences. FocusLLM segments the input into chunks, each processed by an augmented decoder with additional trainable parameters. Local context is appended to each chunk, allowing for parallel decoding, where candidate tokens are generated simultaneously across chunks. This approach reduces computational complexity significantly, particularly with long sequences. FocusLLM’s training uses an auto-regressive loss, focusing on predicting the next token, and employs two loss functions—Continuation and Repetition loss—to improve the model’s ability to handle diverse chunk sizes and contexts.

The evaluation of FocusLLM highlights its strong performance in language modeling and downstream tasks, especially with long-context inputs. Trained efficiently on 8×A100 GPUs, FocusLLM surpasses LLaMA-2-7B and other fine-tuning-free methods, maintaining stable perplexity even with extended sequences. On downstream tasks using Longbench and ∞-Bench datasets, it outperformed models like StreamingLLM and Activation Beacon. FocusLLM’s design, featuring parallel decoding and efficient chunk processing, enables it to handle long sequences effectively without the computational burden of other models, making it a highly efficient solution for long-context tasks.

In conclusion, FocusLLM introduces a framework that significantly extends the context length of LLMs by utilizing a parallel decoding strategy. This approach divides long texts into manageable chunks, extracting essential information from each and integrating it into the context. FocusLLM performs superior downstream tasks while maintaining low perplexity, even with sequences up to 400K tokens. Its design allows for remarkable training efficiency, enabling long-context processing with minimal computational and memory costs. This framework offers a scalable solution for enhancing LLMs, making it a valuable tool for long-context applications.


Check out the Paper. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter and join our Telegram Channel and LinkedIn Group. If you like our work, you will love our newsletter..

Don’t Forget to join our 49k+ ML SubReddit

Find Upcoming AI Webinars here

Sana Hassan, a consulting intern at Marktechpost and dual-degree student at IIT Madras, is passionate about applying technology and AI to address real-world challenges. With a keen interest in solving practical problems, he brings a fresh perspective to the intersection of AI and real-life solutions.

🐝 Join the Fastest Growing AI Research Newsletter Read by Researchers from Google + NVIDIA + Meta + Stanford + MIT + Microsoft and many others…


Credit: Source link

ShareTweetSendSharePin

Related Posts

Logitech’s Yeti 2 Brings The 17-Year-Old USB Mic Into The Modern Age
AI & Technology

Logitech’s Yeti 2 Brings The 17-Year-Old USB Mic Into The Modern Age

September 23, 2026
Never Use ChatGPT For These Five Tasks
AI & Technology

Never Use ChatGPT For These Five Tasks

September 23, 2026
Apple Links Landmarks On Its Maps App To Hidden Histories Podcast Episodes
AI & Technology

Apple Links Landmarks On Its Maps App To Hidden Histories Podcast Episodes

September 23, 2026
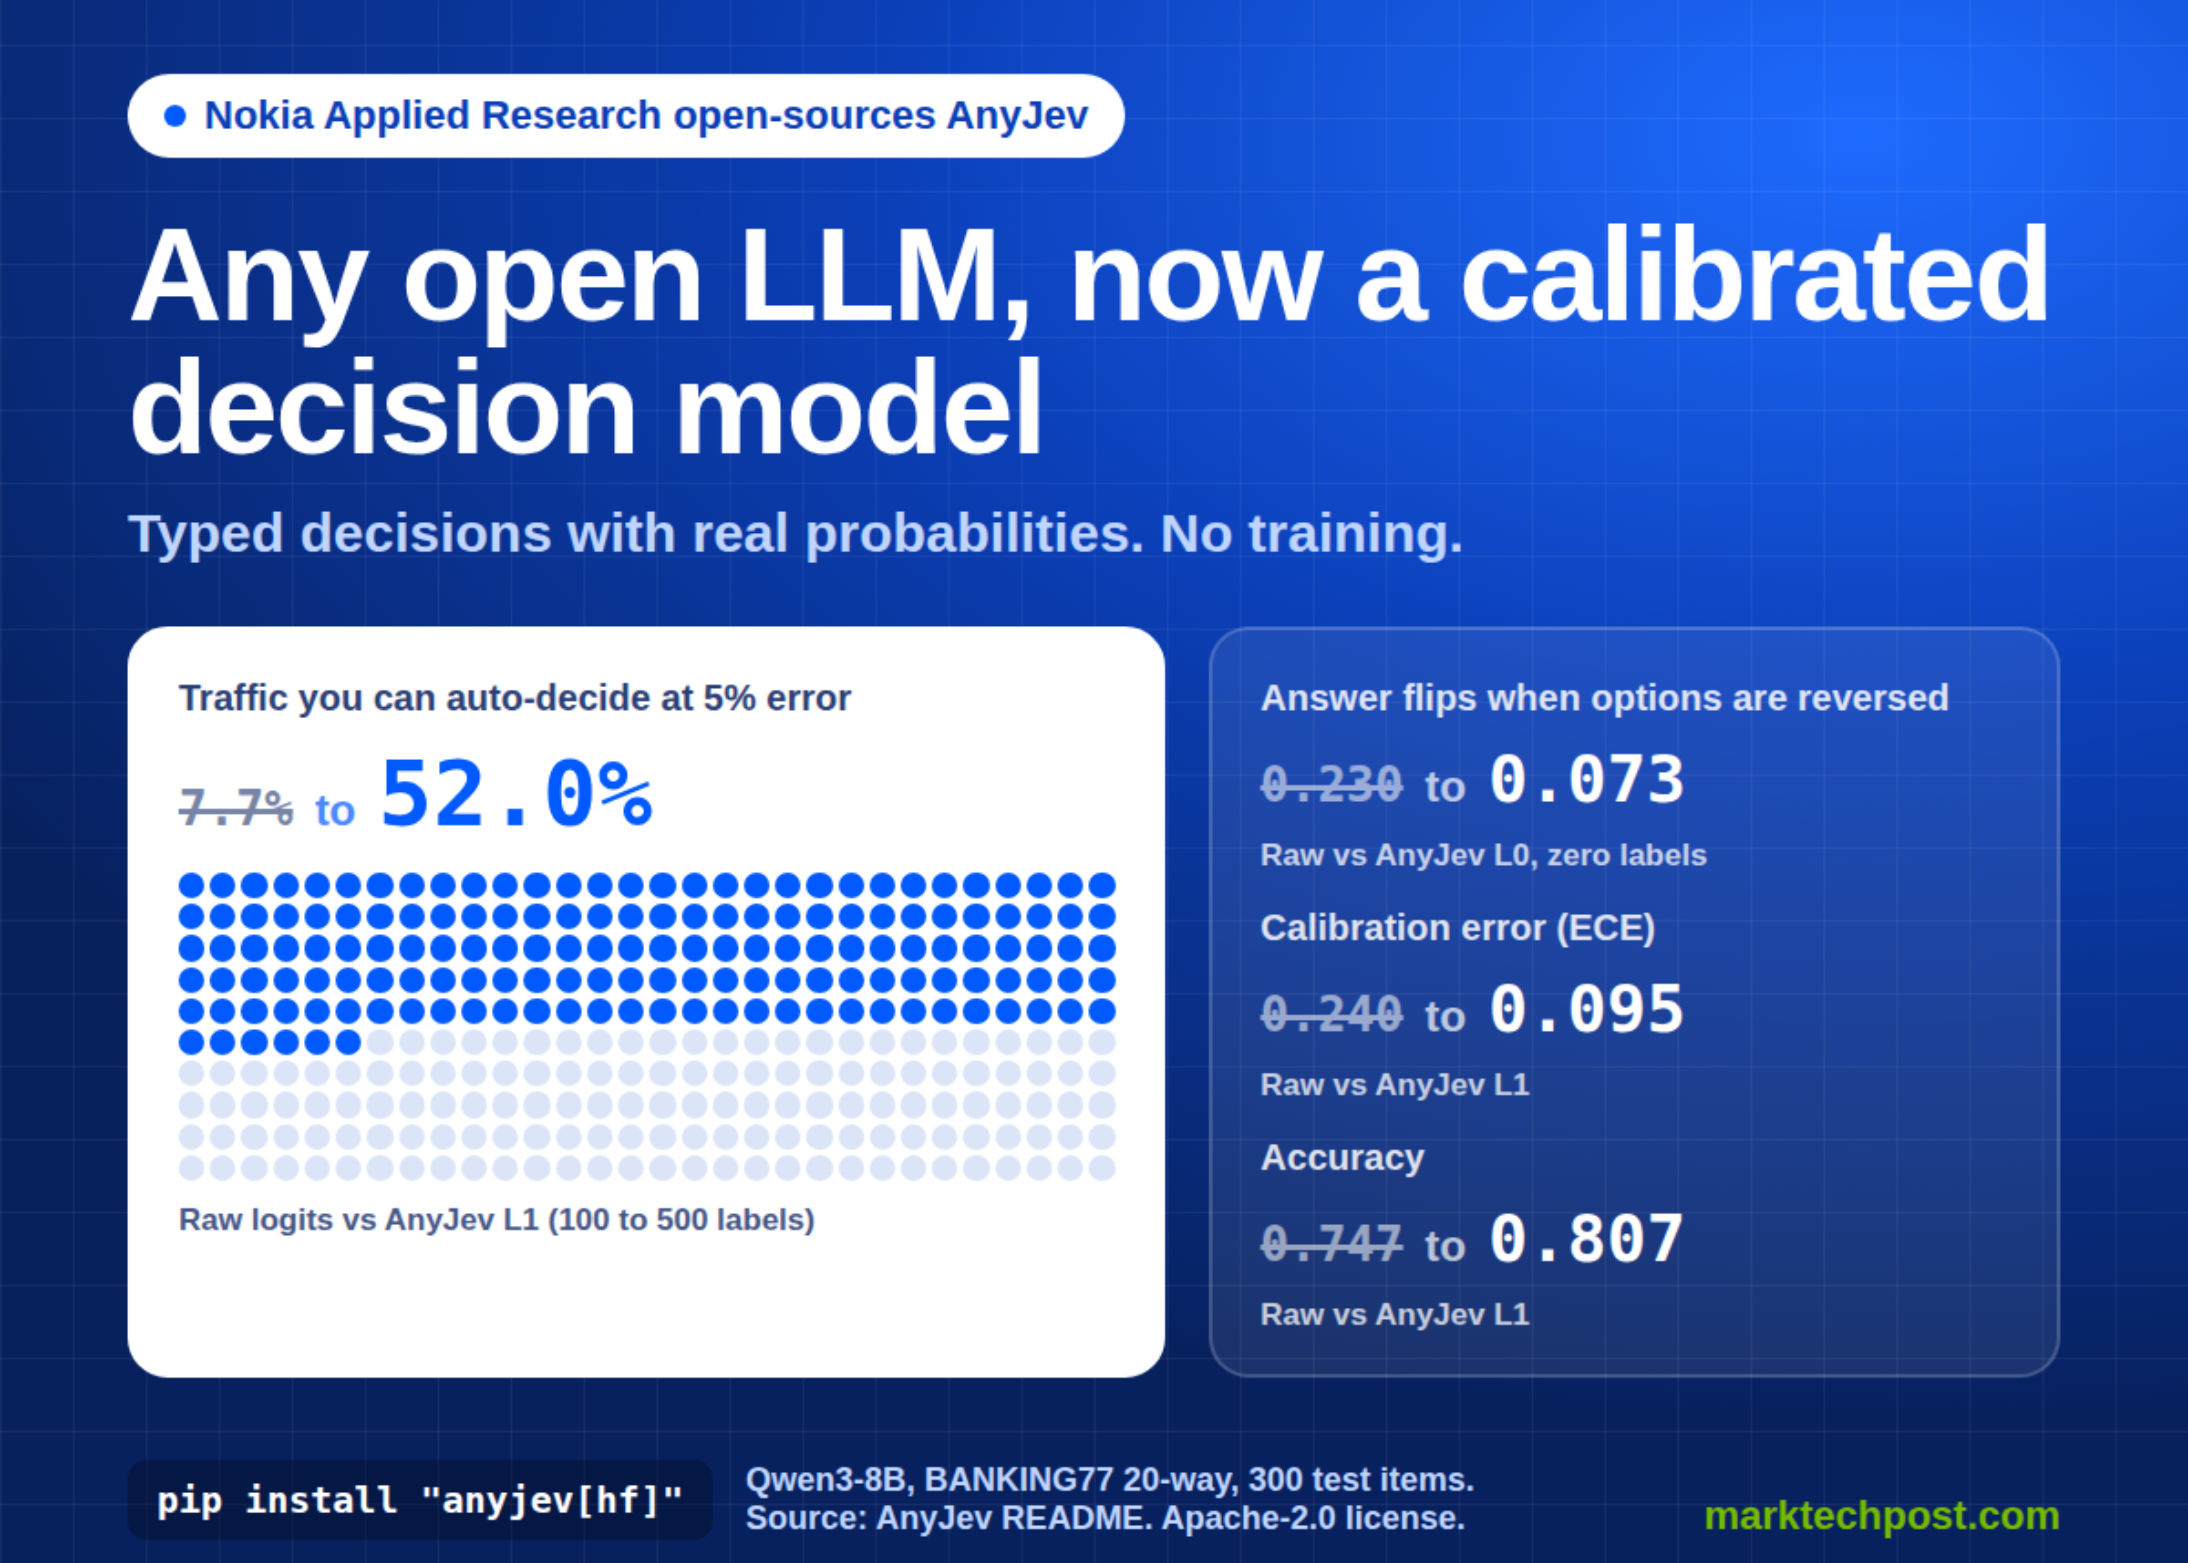
Nokia Open-Sources AnyJev: A Training-Free Layer That Turns Any Open LLM Into a Calibrated Decision Model
AI & Technology

Nokia Open-Sources AnyJev: A Training-Free Layer That Turns Any Open LLM Into a Calibrated Decision Model

September 23, 2026
Next Post
Snoop Dogg says he’s always loved the Olympics

Snoop Dogg says he's always loved the Olympics

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Judge responds to Clancy lawyer request to remove juror

Judge responds to Clancy lawyer request to remove juror

September 18, 2026
Trump Proposes Renaming Artificial Intelligence, Announces AI Force – Unite.AI

Trump Proposes Renaming Artificial Intelligence, Announces AI Force – Unite.AI

September 19, 2026
Trump says dozens of Americans missing after Nepal floods

Trump says dozens of Americans missing after Nepal floods

September 22, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!