• bitcoinBitcoin(BTC)$80,989.00-0.30%
  • ethereumEthereum(ETH)$2,622.69-0.24%
  • tetherTether(USDT)$1.00-0.01%
  • binancecoinBNB(BNB)$758.01-0.71%
  • rippleXRP(XRP)$1.40-0.06%
  • usd-coinUSDC(USDC)$1.00-0.01%
  • solanaSolana(SOL)$110.18-2.71%
  • tronTRON(TRX)$0.3396790.35%
  • zcashZcash(ZEC)$1,471.63-2.03%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.02-1.22%
  • HyperliquidHyperliquid(HYPE)$91.25-0.74%
  • dogecoinDogecoin(DOGE)$0.086970-1.51%
  • moneroMonero(XMR)$535.41-5.99%
  • whitebitWhiteBIT Coin(WBT)$82.65-0.78%
  • RainRain(RAIN)$0.0137882.07%
  • USDSUSDS(USDS)$1.00-0.03%
  • chainlinkChainlink(LINK)$12.31-0.62%
  • cardanoCardano(ADA)$0.2258400.36%
  • leo-tokenLEO Token(LEO)$8.90-0.09%
  • stellarStellar(XLM)$0.1941170.10%
  • uniswapUniswap(UNI)$8.47-5.79%
  • bitcoin-cashBitcoin Cash(BCH)$250.81-2.92%
  • Ethena USDeEthena USDe(USDE)$1.00-0.02%
  • nearNEAR Protocol(NEAR)$3.54-4.67%
  • daiDai(DAI)$1.00-0.02%
  • litecoinLitecoin(LTC)$56.94-0.09%
  • USD1USD1(USD1)$1.00-0.02%
  • CantonCanton(CC)$0.108714-2.02%
  • avalanche-2Avalanche(AVAX)$9.6416.86%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.38-0.21%
  • hedera-hashgraphHedera(HBAR)$0.0803801.67%
  • suiSui(SUI)$0.853.79%
  • MemeCoreMemeCore(M)$1.4811.58%
  • Global DollarGlobal Dollar(USDG)$1.00-0.01%
  • shiba-inuShiba Inu(SHIB)$0.000005-0.98%
  • BittensorBittensor(TAO)$261.544.91%
  • crypto-com-chainCronos(CRO)$0.058994-1.59%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.03%
  • tether-goldTether Gold(XAUT)$4,372.62-0.09%
  • Circle USYCCircle USYC(USYC)$1.140.00%
  • okbOKB(OKB)$117.120.23%
  • Ripple USDRipple USD(RLUSD)$1.00-0.01%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.14-0.41%
  • aaveAave(AAVE)$139.650.73%
  • AsterAster(ASTER)$0.76-0.48%
  • mantleMantle(MNT)$0.62-0.74%
  • EthenaEthena(ENA)$0.20038318.39%
  • OndoOndo(ONDO)$0.4126343.43%
  • Pump.funPump.fun(PUMP)$0.004144-5.69%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

EleutherAI Presents Language Model Evaluation Harness (lm-eval) for Reproducible and Rigorous NLP Assessments, Enhancing Language Model Evaluation

May 26, 2024
in AI & Technology
Reading Time: 6 mins read
A A
EleutherAI Presents Language Model Evaluation Harness (lm-eval) for Reproducible and Rigorous NLP Assessments, Enhancing Language Model Evaluation
ShareShareShareShareShare

Language models are fundamental to natural language processing (NLP), focusing on generating and comprehending human language. These models are integral to applications such as machine translation, text summarization, and conversational agents, where the aim is to develop technology capable of understanding and producing human-like text. Despite their significance, the effective evaluation of these models remains an open challenge within the NLP community.

Researchers often encounter methodological challenges while evaluating language models, such as models’ sensitivity to different evaluation setups, difficulties in making proper comparisons across methods, and the lack of reproducibility and transparency. These issues can hinder scientific progress and lead to biased or unreliable findings in language model research, potentially affecting the adoption of new methods and the direction of future research.

Existing evaluation methods for language models often rely on benchmark tasks and automated metrics such as BLEU and ROUGE. These metrics offer advantages like reproducibility and lower costs compared to manual human evaluations. However, they also have notable limitations. For instance, while automated metrics can measure the overlap between a generated response and a reference text, they may need to fully capture the nuances of human language or the correctness of the responses generated by the models. 

Researchers from EleutherAI and Stability AI, in collaboration with other institutions, introduced the Language Model Evaluation Harness (lm-eval), an open-source library designed to enhance the evaluation process. lm-eval aims to provide a standardized and flexible framework for evaluating language models. This tool facilitates reproducible and rigorous evaluations across various benchmarks and models, significantly improving the reliability and transparency of language model assessments.

The lm-eval tool integrates several key features to optimize the evaluation process. It allows for the modular implementation of evaluation tasks, enabling researchers to share and reproduce results more efficiently. The library supports multiple evaluation requests, such as conditional loglikelihoods, perplexities, and text generation, ensuring a comprehensive assessment of a model’s capabilities. For example, lm-eval can calculate the probability of given output strings based on provided inputs or measure the average loglikelihood of producing tokens in a dataset. These features make lm-eval a versatile tool for evaluating language models in different contexts.

Performance results from using lm-eval demonstrate its effectiveness in addressing common challenges in language model evaluation. The tool helps identify issues such as the dependence on minor implementation details, which can significantly impact the validity of evaluations. By providing a standardized framework, lm-eval ensures that researchers can perform evaluations consistently, regardless of the specific models or benchmarks used. This consistency is crucial for fair comparisons across different methods and models, ultimately leading to more reliable and accurate research outcomes.
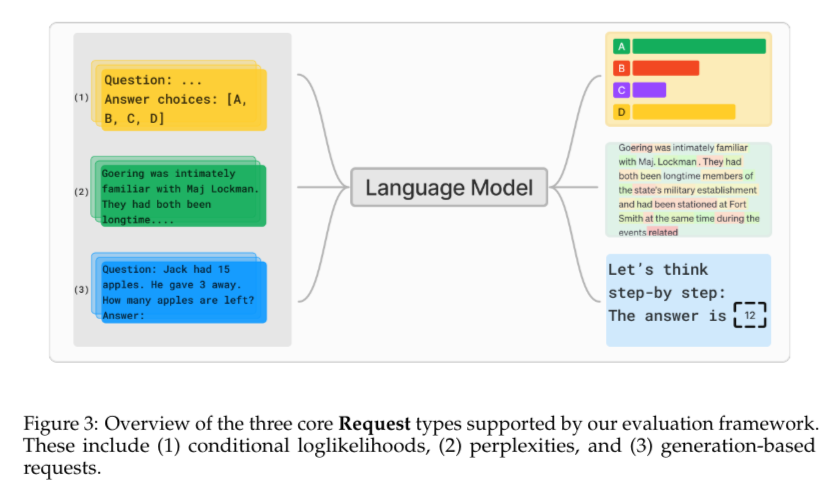
lm-eval includes features supporting qualitative analysis and statistical testing, which are essential for thorough model evaluations. The library allows for qualitative checks of evaluation scores and outputs, helping researchers identify and correct errors early in the evaluation process. It also reports standard errors for most supported metrics, enabling researchers to perform statistical significance testing and assess the reliability of their results. 

In conclusion, Key highlights of the research:

  • Researchers face significant challenges in evaluating LLMs, including issues with models’ sensitivity to evaluation setups, difficulties in making proper comparisons across methods, and a lack of reproducibility and transparency in results.
  • The research draws on three years of experience evaluating language models to provide guidance and lessons for researchers. It highlights common challenges and best practices to improve the rigor and communication of results in the language modeling community.
  • Lastly, it introduces lm-eval, an open-source library designed to enable independent, reproducible, and extensible evaluation of language models. It addresses the identified challenges and improves the overall evaluation process.

Check out the Paper. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter. Join our Telegram Channel, Discord Channel, and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our 42k+ ML SubReddit

YOU MAY ALSO LIKE

SpaceX Targets September 28 For Starship’s First Orbital Flight

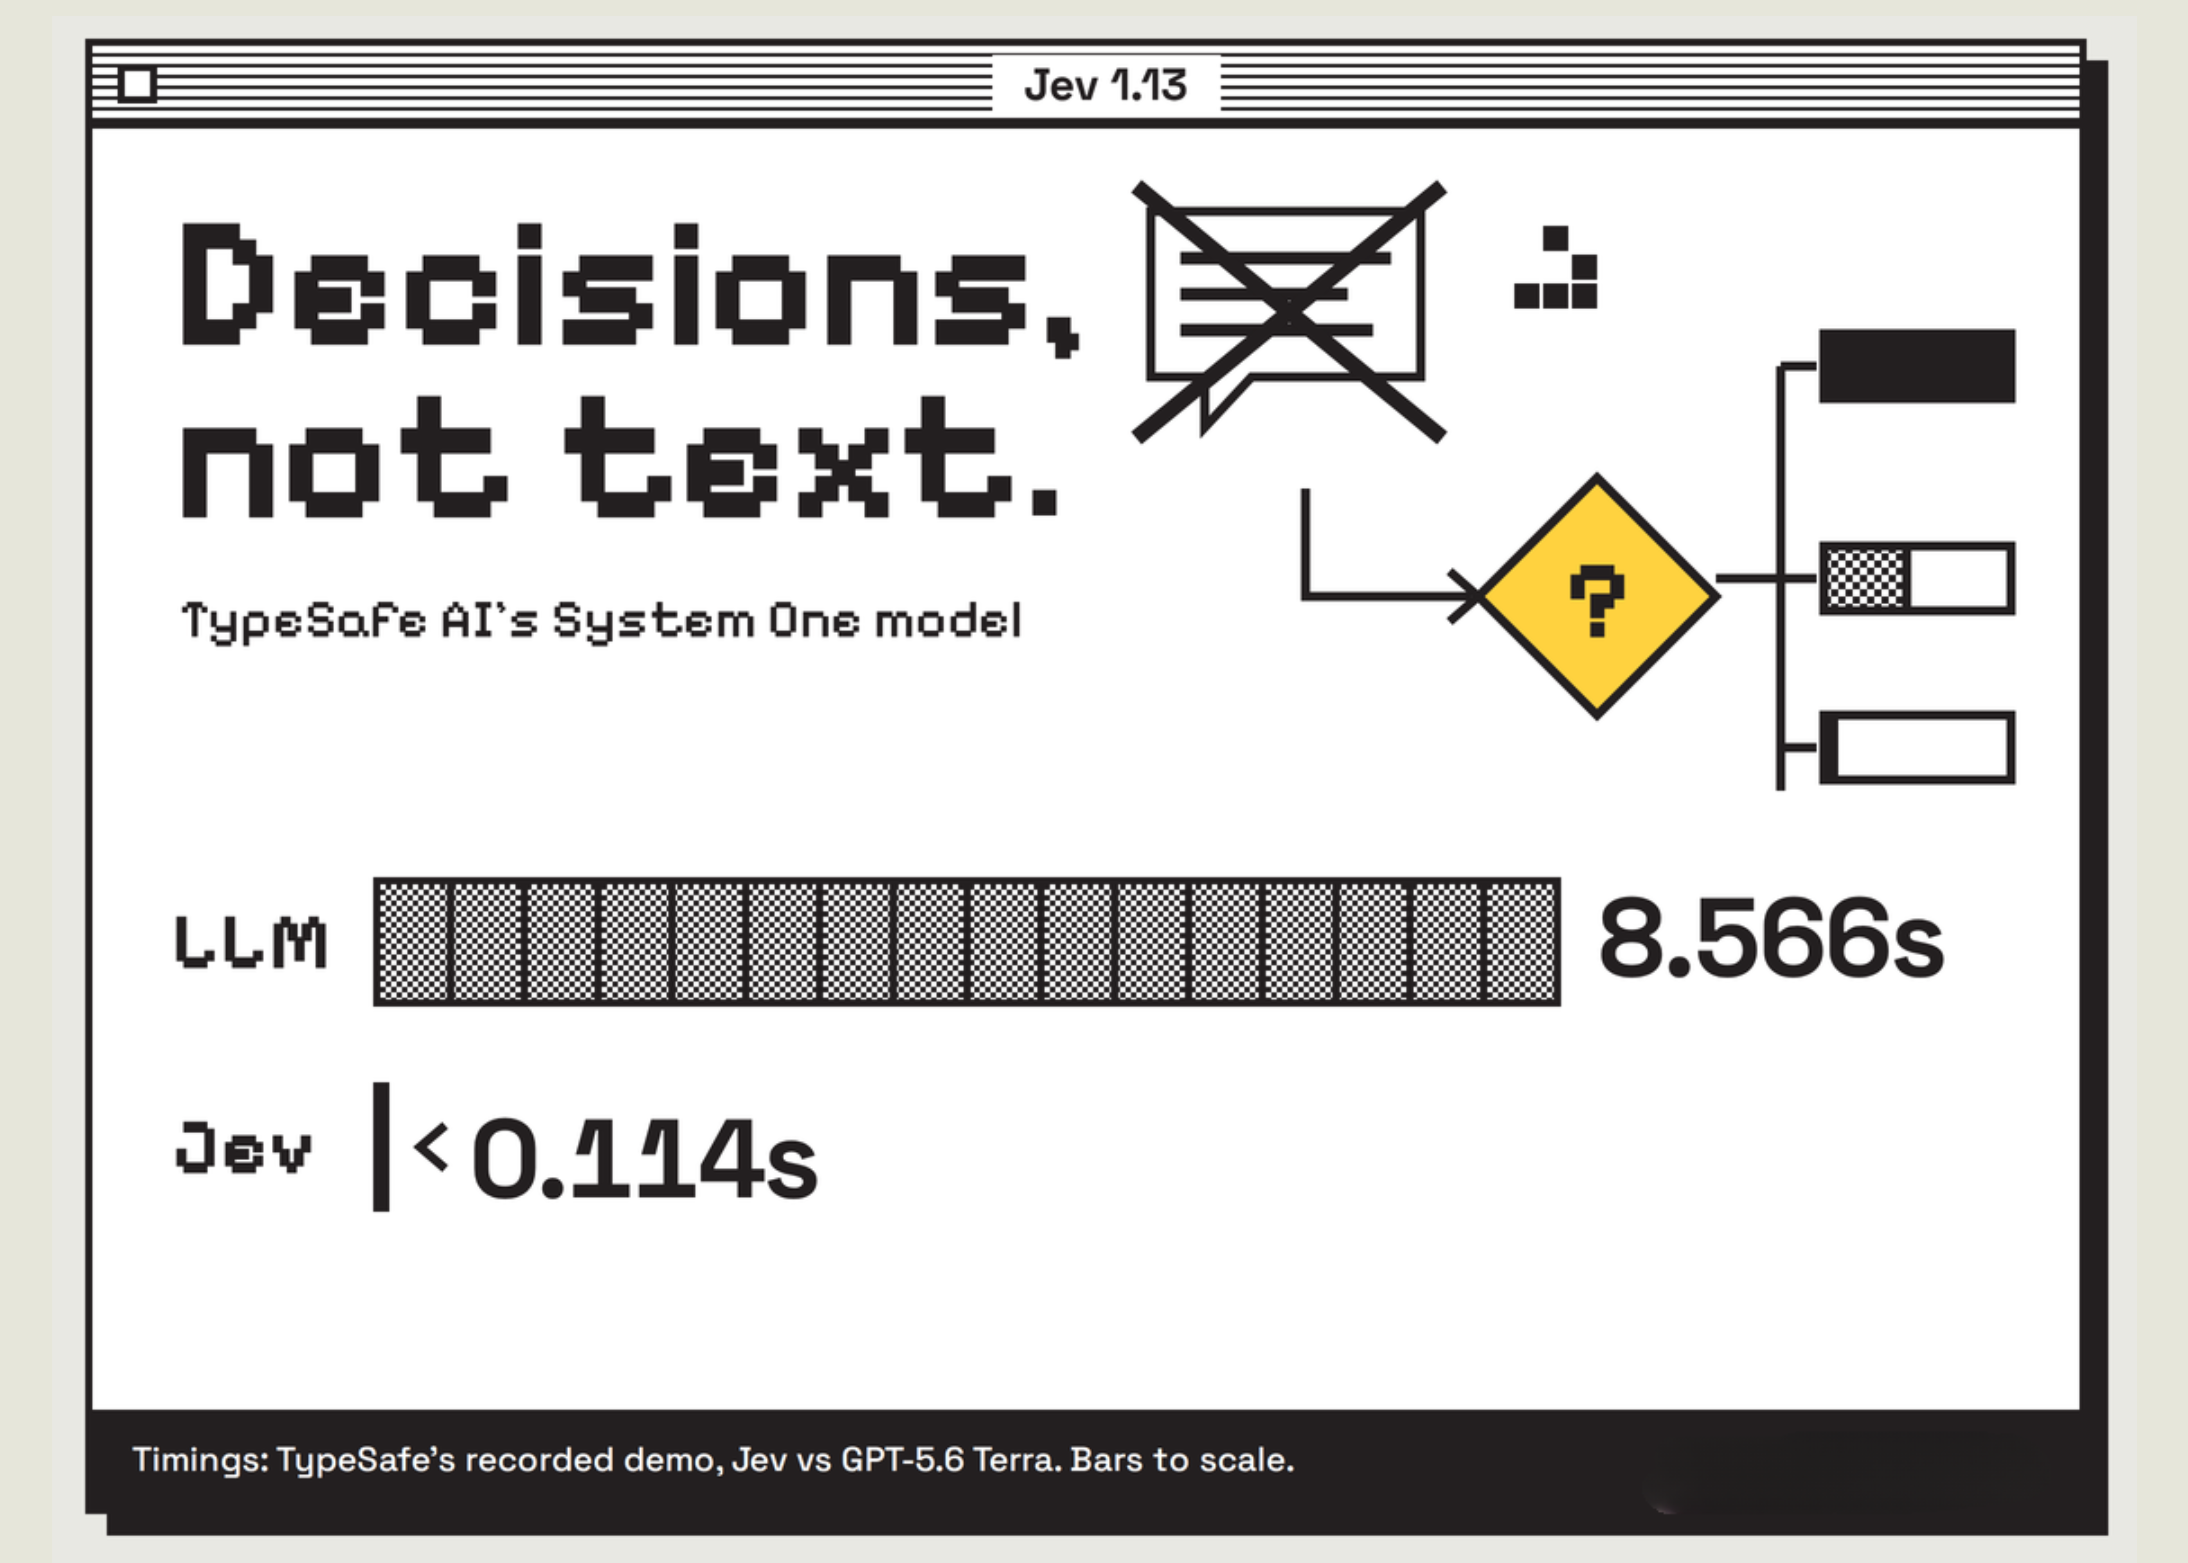
TypeSafe AI Releases Jev: A System One Model That Returns Typed, Calibrated Decisions Instead of Text

Asif Razzaq is the CEO of Marktechpost Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.


🐝 Join the Fastest Growing AI Research Newsletter Read by Researchers from Google + NVIDIA + Meta + Stanford + MIT + Microsoft and many others…


Credit: Source link

ShareTweetSendSharePin

Related Posts

SpaceX Targets September 28 For Starship’s First Orbital Flight
AI & Technology

SpaceX Targets September 28 For Starship’s First Orbital Flight

September 19, 2026
TypeSafe AI Releases Jev: A System One Model That Returns Typed, Calibrated Decisions Instead of Text
AI & Technology

TypeSafe AI Releases Jev: A System One Model That Returns Typed, Calibrated Decisions Instead of Text

September 19, 2026
Why Is Your iPad Not Charging (And How To Fix It)
AI & Technology

Why Is Your iPad Not Charging (And How To Fix It)

September 19, 2026
How To Block And Unblock A Number On Your Android Phone
AI & Technology

How To Block And Unblock A Number On Your Android Phone

September 19, 2026
Next Post
Mary Poppins songwriter Richard Sherman dies aged 95

Mary Poppins songwriter Richard Sherman dies aged 95

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Woman accused of photographing Lindsay Clancy jurors charged with witness intimidation

Woman accused of photographing Lindsay Clancy jurors charged with witness intimidation

September 19, 2026
How To Force Quit On Your Windows PC

How To Force Quit On Your Windows PC

September 14, 2026
Apple TV Cleaned Up At The Emmys With Eight Wins For Widow’s Bay And Pluribus

Apple TV Cleaned Up At The Emmys With Eight Wins For Widow’s Bay And Pluribus

September 15, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!