• bitcoinBitcoin(BTC)$78,502.002.34%
  • ethereumEthereum(ETH)$2,530.542.14%
  • tetherTether(USDT)$1.000.03%
  • binancecoinBNB(BNB)$721.060.64%
  • rippleXRP(XRP)$1.447.14%
  • usd-coinUSDC(USDC)$1.000.01%
  • solanaSolana(SOL)$102.822.98%
  • tronTRON(TRX)$0.338599-0.26%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.040.00%
  • zcashZcash(ZEC)$1,167.588.83%
  • HyperliquidHyperliquid(HYPE)$80.053.31%
  • dogecoinDogecoin(DOGE)$0.0840522.01%
  • RainRain(RAIN)$0.014307-5.69%
  • USDSUSDS(USDS)$1.000.01%
  • moneroMonero(XMR)$514.24-1.18%
  • whitebitWhiteBIT Coin(WBT)$81.252.16%
  • chainlinkChainlink(LINK)$11.563.43%
  • leo-tokenLEO Token(LEO)$9.00-0.47%
  • cardanoCardano(ADA)$0.2096113.16%
  • stellarStellar(XLM)$0.1935299.37%
  • Ethena USDeEthena USDe(USDE)$1.000.03%
  • daiDai(DAI)$1.000.00%
  • bitcoin-cashBitcoin Cash(BCH)$224.241.60%
  • USD1USD1(USD1)$1.000.01%
  • litecoinLitecoin(LTC)$53.34-0.60%
  • uniswapUniswap(UNI)$6.546.02%
  • CantonCanton(CC)$0.0976212.92%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.350.69%
  • hedera-hashgraphHedera(HBAR)$0.0776873.57%
  • avalanche-2Avalanche(AVAX)$7.624.34%
  • Global DollarGlobal Dollar(USDG)$1.000.02%
  • nearNEAR Protocol(NEAR)$2.508.02%
  • shiba-inuShiba Inu(SHIB)$0.0000052.47%
  • suiSui(SUI)$0.733.33%
  • crypto-com-chainCronos(CRO)$0.0595204.13%
  • paypal-usdPayPal USD(PYUSD)$1.000.03%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • tether-goldTether Gold(XAUT)$4,297.32-0.95%
  • BittensorBittensor(TAO)$233.130.28%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • MemeCoreMemeCore(M)$1.09-4.34%
  • okbOKB(OKB)$113.561.52%
  • Ripple USDRipple USD(RLUSD)$1.000.01%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.14-0.07%
  • aaveAave(AAVE)$128.773.24%
  • AsterAster(ASTER)$0.702.51%
  • mantleMantle(MNT)$0.573.15%
  • pax-goldPAX Gold(PAXG)$4,301.30-0.95%
  • World Liberty FinancialWorld Liberty Financial(WLFI)$0.0578202.07%
  • OndoOndo(ONDO)$0.3559153.65%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Do LLM Agents Have Regret? This Machine Learning Research from MIT and the University of Maryland Presents a Case Study on Online Learning and Games

March 28, 2024
in AI & Technology
Reading Time: 5 mins read
A A
Do LLM Agents Have Regret? This Machine Learning Research from MIT and the University of Maryland Presents a Case Study on Online Learning and Games
ShareShareShareShareShare

Large Language Models (LLMs) have been increasingly employed for (interactive) decision-making through the model development of LLM-based agents. LLMs have shown remarkable successes in embodied AI, natural science, and social science applications in recent years. LLMs have also exhibited remarkable potential in solving various games. These exciting empirical successes require rigorous examination and understanding through a theoretical lens of decision-making. However, the performance of LLM agents in decision-making has yet to be fully investigated through quantitative metrics, especially in the multi-agent setting when they interact with each other, a typical scenario in real-world LLM-agent applications.

Thus, it is natural to ask: Is it possible to examine and better understand LLMs’ online and strategic decision-making behaviors through the lens of regret?

The impressive capability of LLMs for reasoning has inspired an enhancing line of research on how LLM-based autonomous agents interact with the environment by taking actions repeatedly/sequentially based on the feedback they receive. Some significant promises have been shown from a planning perspective. In particular, for embodied AI applications, e.g., robotics, LLMs have achieved impressive performance when used as the controller for decision-making. However, the performance of decision-making has yet to be rigorously characterized via the regret metric in these works. Recently, some researchers have proposed a principled architecture for LLM-agent, with provable regret guarantees in stationary and stochastic decision-making environments, under the Bayesian adaptive Markov decision processes framework.

To better understand the limits of LLM agents in these interactive environments, researchers from MIT and the University of Maryland propose to study their interactions in benchmark decision-making settings in online learning and game theory through the performance metric of regret. They propose a unique unsupervised training loss of regret-loss, which, in contrast to the supervised pre-training loss, does not require the labels of (optimal) actions. Then, they established the statistical guarantee of generalization bound for regret-loss minimization, followed by the optimization guarantee that minimizing such a loss may automatically lead to known no-regret learning algorithms.

Researchers propose two frameworks to rigorously validate the no-regret behavior of algorithms over a finite T, which might be of independent interest: a Trend-checking framework and a Regression-based framework. In the Trend-checking framework, they defined  H0 and H1, which denote the null and alternative hypotheses, respectively. The notion of convergence is related to T → ∞ by definition, making it challenging to verify directly. As an alternative, they propose a more tractable hypothesis. They propose an alternative approach in a Regression-based framework by fitting the data with regression. In particular, one can use the data to fit a linear function.

In the experiments, They compare GPT-4 with well-known no-regret algorithms, FTRL with entropy regularization, and FTPL with Gaussian perturbations (with tuned parameters). These pre-trained LLMs can achieve no regret and often have smaller regrets than these baselines. While comparing the performance of pre-trained LLMs with that of the counterparts of FTRL with bandit feedback, e.g., EXP3 and the bandit-version of FTPL, where GPT-4 consistently achieves lower regret. Regret of GPT-3.5 Turbo/GPT-4 for repeated games of 3 different game sizes, where both statistical frameworks validate the sublinear regret. 

In conclusion, the researchers from MIT and the University of Maryland studied the online decision-making and strategic behaviors of LLMs quantitatively through the metric of regret. They examined and validated the no-regret behavior of several representative pre-trained LLMs in benchmark online learning and game settings. They then provide theoretical insights into the no-regret behavior by connecting pre-trained LLMs to the follow-the-perturbed-leader algorithm in online learning under certain assumptions. They also identified (simple) cases where pre-trained LLMs fail to be no-regret. They thus proposed a new unsupervised training loss, regret-loss, to provably promote the no-regret behavior of Transformers without the labels of (optimal) actions.


Check out the Paper. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter. Join our Telegram Channel, Discord Channel, and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our 39k+ ML SubReddit


YOU MAY ALSO LIKE

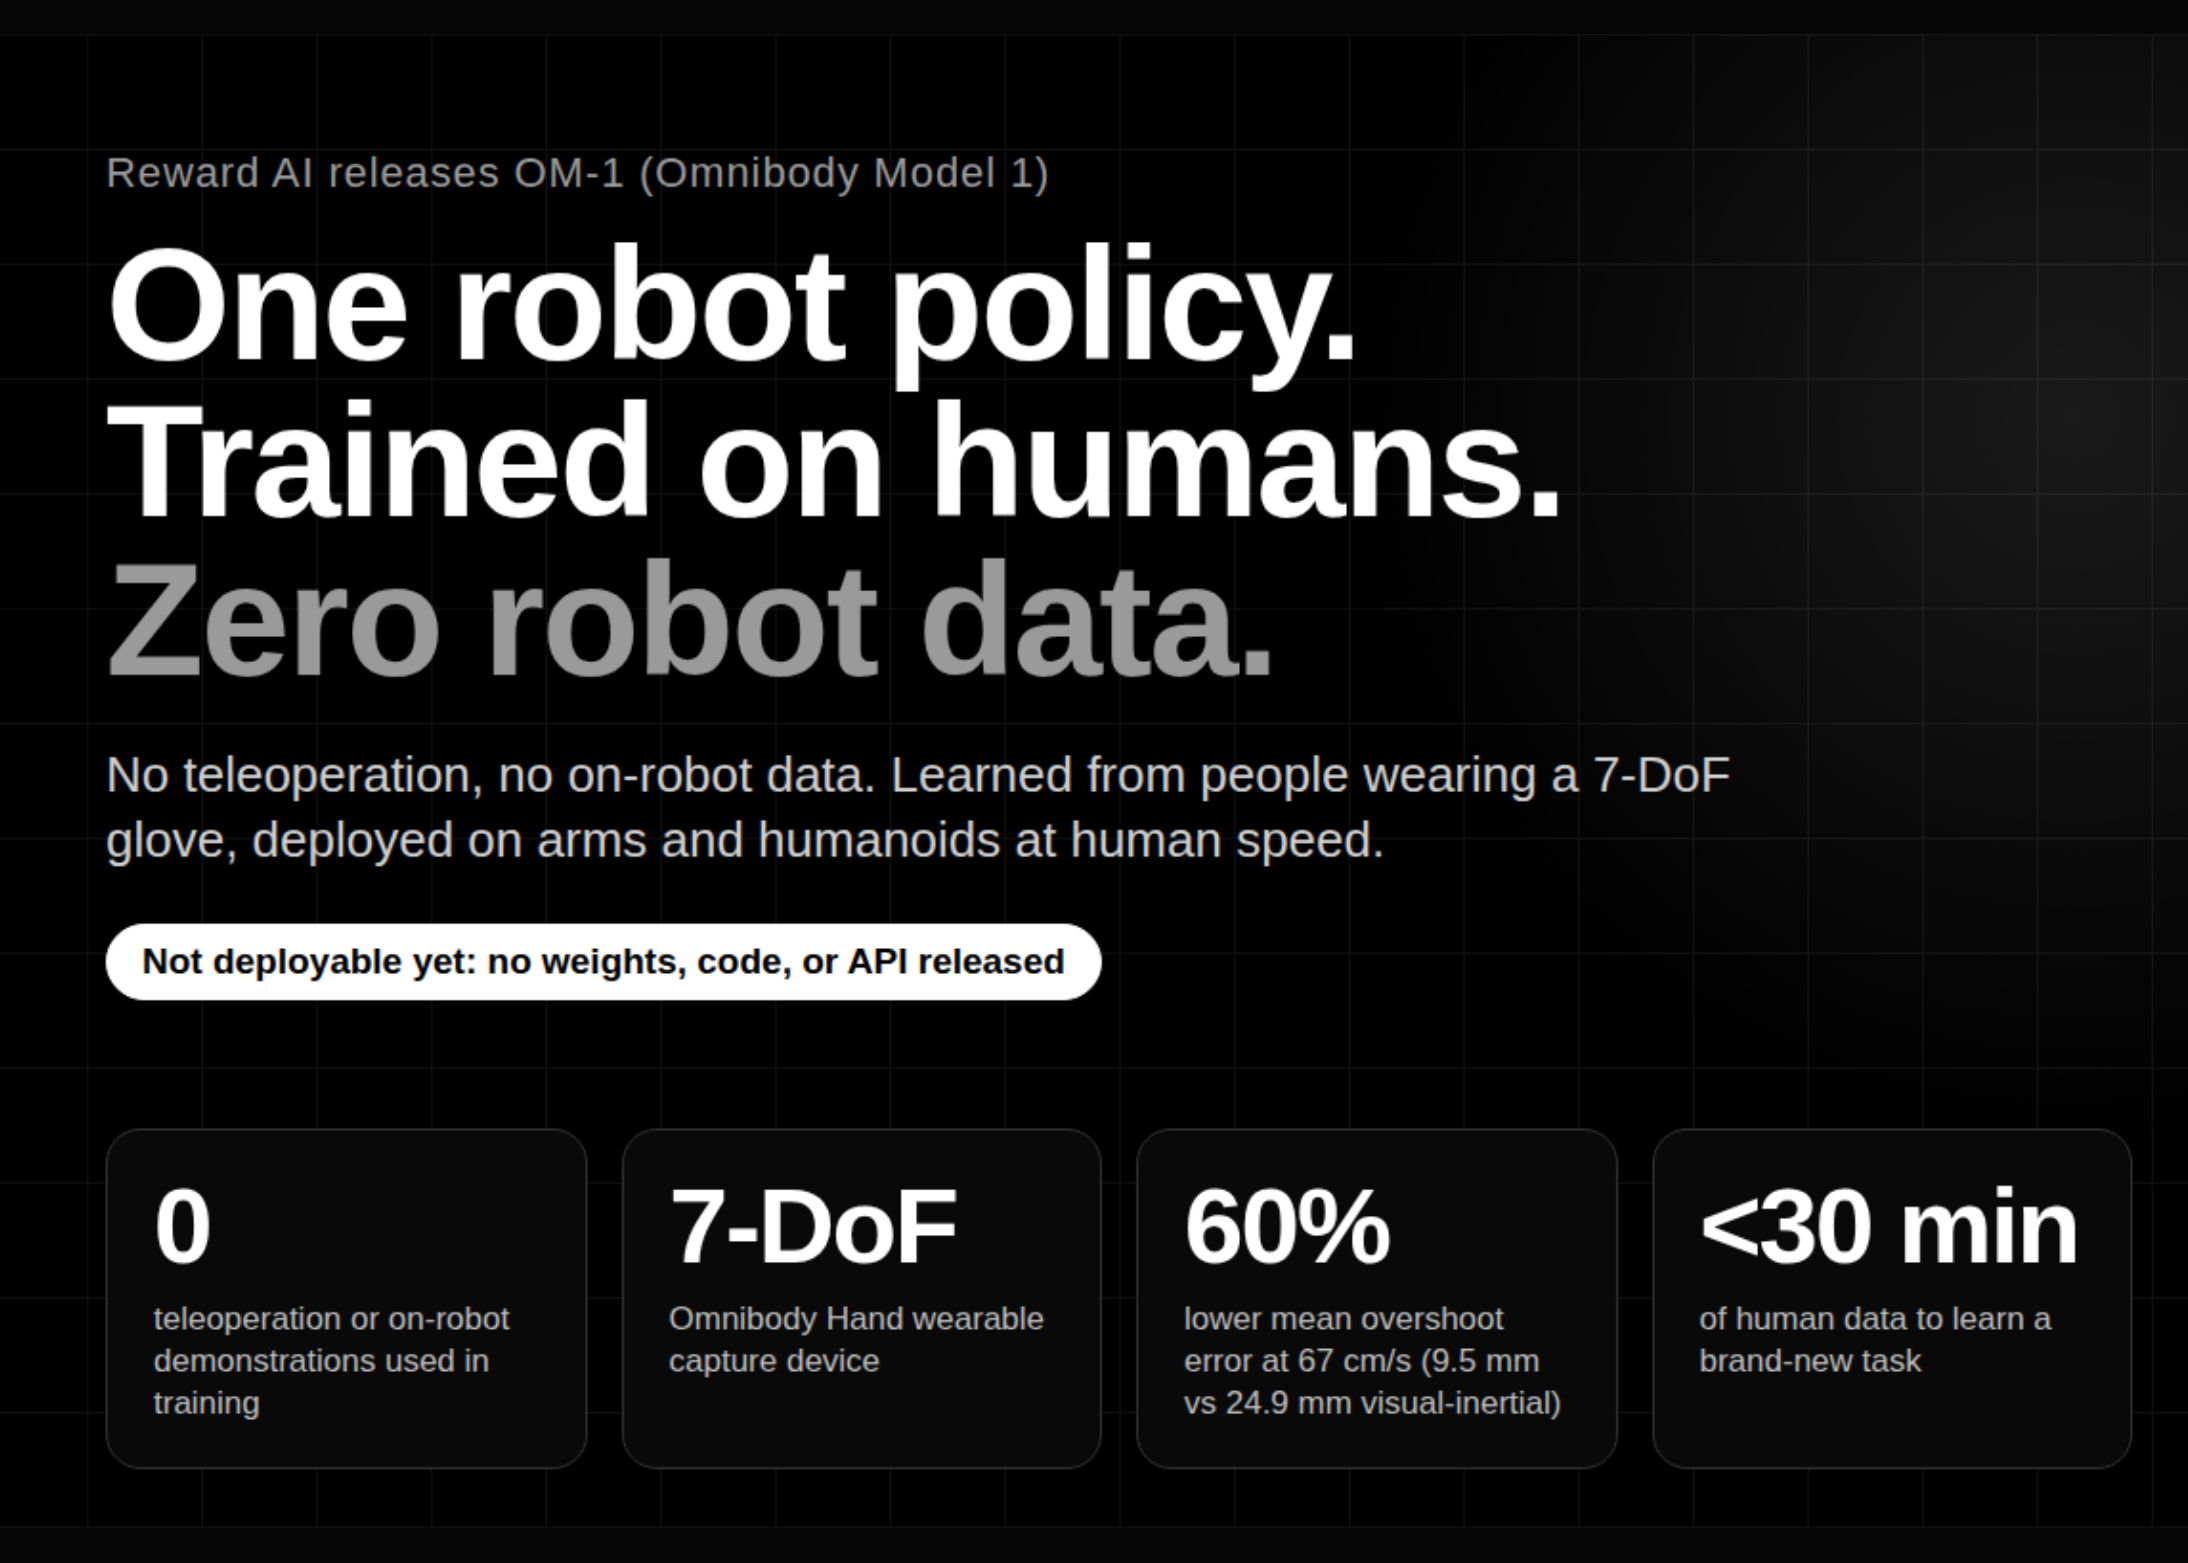
Reward AI Releases OM-1: A Robot Policy Trained on Human Demonstrations Only, With No Teleoperation or On-Robot Data

How To Force Quit On Your Windows PC

Asjad is an intern consultant at Marktechpost. He is persuing B.Tech in mechanical engineering at the Indian Institute of Technology, Kharagpur. Asjad is a Machine learning and deep learning enthusiast who is always researching the applications of machine learning in healthcare.


🐝 Join the Fastest Growing AI Research Newsletter Read by Researchers from Google + NVIDIA + Meta + Stanford + MIT + Microsoft and many others…


Credit: Source link

ShareTweetSendSharePin

Related Posts

Reward AI Releases OM-1: A Robot Policy Trained on Human Demonstrations Only, With No Teleoperation or On-Robot Data
AI & Technology

Reward AI Releases OM-1: A Robot Policy Trained on Human Demonstrations Only, With No Teleoperation or On-Robot Data

September 14, 2026
How To Force Quit On Your Windows PC
AI & Technology

How To Force Quit On Your Windows PC

September 14, 2026
NVIDIA Adds RTX PRO 5500 Blackwell GPU with 84 GB GDDR7 Memory – Unite.AI
AI & Technology

NVIDIA Adds RTX PRO 5500 Blackwell GPU with 84 GB GDDR7 Memory – Unite.AI

September 14, 2026
You Can Use Gemini To Help You Organize Your Files On Google Drive
AI & Technology

You Can Use Gemini To Help You Organize Your Files On Google Drive

September 14, 2026
Next Post
(Warning) SEC Lawsuit Against Coinbase…

(Warning) SEC Lawsuit Against Coinbase...

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
John Harbaugh: Giants' win over Cowboys in debut 'really special' – espn.com

John Harbaugh: Giants' win over Cowboys in debut 'really special' – espn.com

September 14, 2026
OpenAI CEO Sam Altman says he’s open to slowing AI as safety risks mount: report

OpenAI CEO Sam Altman says he’s open to slowing AI as safety risks mount: report

September 11, 2026
Teen rescued after days stranded in the waters off Alaska

Teen rescued after days stranded in the waters off Alaska

September 13, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!