• bitcoinBitcoin(BTC)$80,635.005.77%
  • ethereumEthereum(ETH)$2,429.358.30%
  • tetherTether(USDT)$1.000.04%
  • binancecoinBNB(BNB)$716.504.26%
  • rippleXRP(XRP)$1.314.41%
  • usd-coinUSDC(USDC)$1.000.02%
  • solanaSolana(SOL)$96.646.23%
  • tronTRON(TRX)$0.319247-0.72%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.051.54%
  • zcashZcash(ZEC)$1,320.2012.28%
  • HyperliquidHyperliquid(HYPE)$84.171.86%
  • dogecoinDogecoin(DOGE)$0.0772165.41%
  • moneroMonero(XMR)$636.811.60%
  • USDSUSDS(USDS)$1.000.02%
  • whitebitWhiteBIT Coin(WBT)$78.046.51%
  • chainlinkChainlink(LINK)$11.587.62%
  • leo-tokenLEO Token(LEO)$9.350.54%
  • cardanoCardano(ADA)$0.1986417.15%
  • stellarStellar(XLM)$0.1684636.15%
  • bitcoin-cashBitcoin Cash(BCH)$282.005.14%
  • nearNEAR Protocol(NEAR)$4.058.48%
  • uniswapUniswap(UNI)$7.749.36%
  • daiDai(DAI)$1.00-0.02%
  • Ethena USDeEthena USDe(USDE)$1.000.06%
  • litecoinLitecoin(LTC)$56.366.62%
  • RainRain(RAIN)$0.005978-6.74%
  • CantonCanton(CC)$0.1016866.04%
  • avalanche-2Avalanche(AVAX)$8.835.52%
  • suiSui(SUI)$0.947.71%
  • USD1USD1(USD1)$1.000.06%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.182.01%
  • tether-goldTether Gold(XAUT)$4,109.764.57%
  • hedera-hashgraphHedera(HBAR)$0.0733697.40%
  • quant-networkQuant(QNT)$204.848.66%
  • Global DollarGlobal Dollar(USDG)$1.000.02%
  • shiba-inuShiba Inu(SHIB)$0.0000055.04%
  • BittensorBittensor(TAO)$237.397.45%
  • paypal-usdPayPal USD(PYUSD)$1.000.02%
  • crypto-com-chainCronos(CRO)$0.0523825.94%
  • Ripple USDRipple USD(RLUSD)$1.000.02%
  • EthenaEthena(ENA)$0.1834958.64%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.07%
  • okbOKB(OKB)$112.325.36%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • pepePepe(PEPE)$0.0000055.67%
  • aaveAave(AAVE)$132.876.15%
  • OndoOndo(ONDO)$0.4147759.01%
  • Pump.funPump.fun(PUMP)$0.0043555.27%
  • MemeCoreMemeCore(M)$0.841.47%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

DeepSeek V3.2-Exp Cuts Long-Context Costs with DeepSeek Sparse Attention (DSA) While Maintaining Benchmark Parity

September 30, 2025
in AI & Technology
Reading Time: 8 mins read
A A
DeepSeek V3.2-Exp Cuts Long-Context Costs with DeepSeek Sparse Attention (DSA) While Maintaining Benchmark Parity
ShareShareShareShareShare

DeepSeek released DeepSeek-V3.2-Exp, an “intermediate” update to V3.1 that adds DeepSeek Sparse Attention (DSA)—a trainable sparsification path aimed at long-context efficiency. DeepSeek also reduced API prices by 50%+, consistent with the stated efficiency gains.

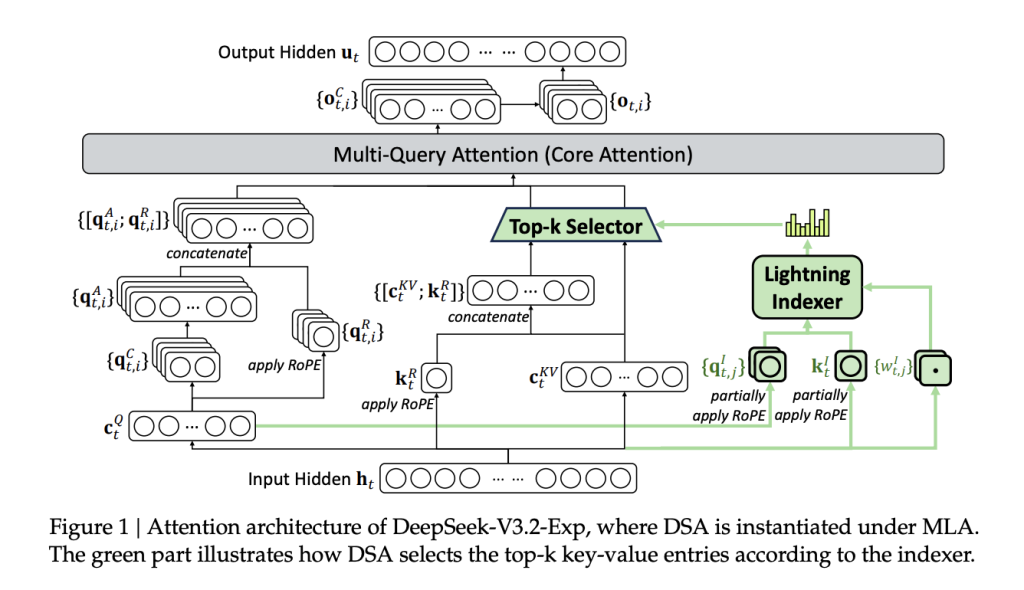
DeepSeek-V3.2-Exp keeps the V3/V3.1 stack (MoE + MLA) and inserts a two-stage attention path: (i) a lightweight “indexer” that scores context tokens; (ii) sparse attention over the selected subset.
YOU MAY ALSO LIKE

Cat Wu to Lead Product Management for OpenAI’s Core Products – Unite.AI

Snap Has More Than 30 Million Paid Subscribers Across Snapchat+ And Other Plans

https://github.com/deepseek-ai/DeepSeek-V3.2-Exp/blob/main/DeepSeek_V3_2.pdf

FP8 index → top-k selection → sparse core attention

DeepSeek Sparse Attention (DSA) splits the attention path into two compute tiers:

(1) Lightning indexer (FP8, few heads): For each query token
ℎ
𝑡
∈
𝑅
𝑑
h
t
​

∈R
d
, a lightweight scoring function computes index logits
𝐼
𝑡
,
𝑠
I
t,s
​

against preceding tokens
ℎ
𝑠
h
s
​

. It uses small indexer heads with a ReLU nonlinearity for throughput. Because this stage runs in FP8 and with few heads, its wall-time and FLOP cost are minor relative to dense attention.

(2) Fine-grained token selection (top-k): The system selects only the top-k=2048 key-value entries for each query and then performs standard attention only over that subset. This changes the dominant term from
𝑂
(
𝐿
2
)
O(L
2
) to
𝑂
(
𝐿
𝑘
)
O(Lk) with
𝑘
≪
𝐿
k≪L, while preserving the ability to attend to arbitrarily distant tokens when needed.

Training signal: The indexer is trained to imitate the dense model’s head-summed attention distribution via KL-divergence, first under a short dense warm-up (indexer learns targets while the main model is frozen), then during sparse training where gradients for the indexer remain separate from the main model’s language loss. Warm-up uses ~2.1B tokens; sparse stage uses ~943.7B tokens with top-k=2048, LR ~7.3e-6 for the main model.

Instantiation: DSA is implemented under MLA (Multi-head Latent Attention) in MQA mode for decoding so each latent KV entry is shared across query heads, aligning with the kernel-level requirement that KV entries be reused across queries for throughput.
https://github.com/deepseek-ai/DeepSeek-V3.2-Exp/blob/main/DeepSeek_V3_2.pdf

Lets Talk about it’s efficiency and accuracy

  • Costs vs. position (128k): DeepSeek provides per-million-token cost curves for prefill and decode on H800 clusters (reference price $2/GPU-hour). Decode costs fall substantially with DSA; prefill also benefits via a masked MHA simulation at short lengths. While the exact 83% figure circulating on social media maps to “~6× cheaper decode at 128k,” treat it as DeepSeek-reported until third-party replication lands.
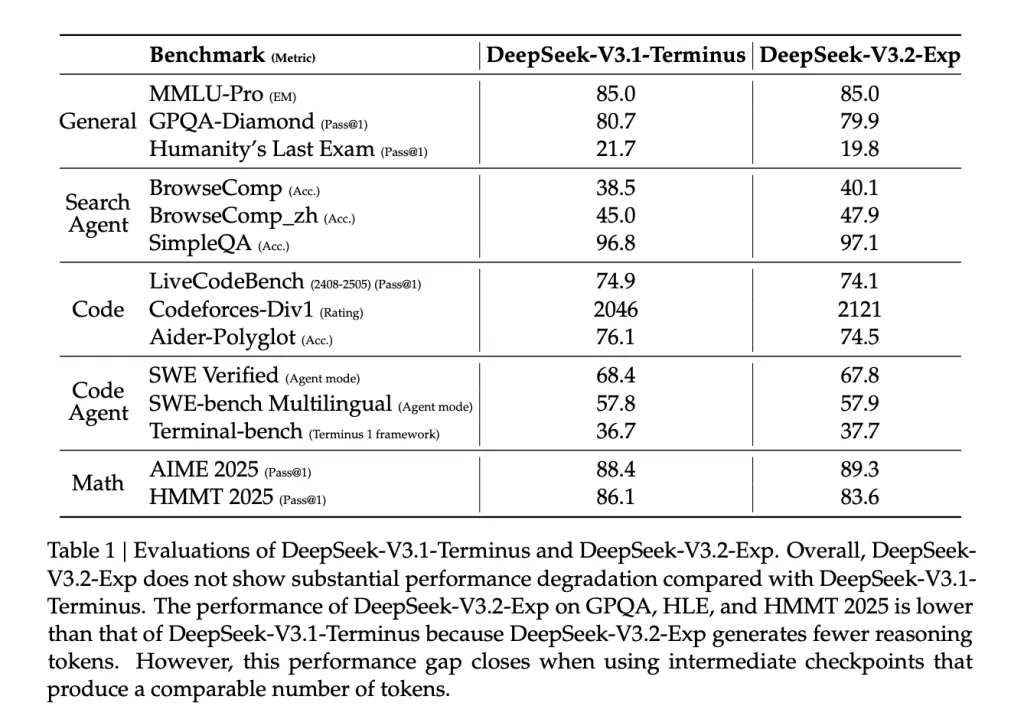
  • Benchmark parity: The released table shows MMLU-Pro = 85.0 (unchanged), small movement on GPQA/HLE/HMMT due to fewer reasoning tokens, and flat/positive movement on agentic/search tasks (e.g., BrowseComp 40.1 vs 38.5). The authors note the gaps close when using intermediate checkpoints that produce comparable token counts.
  • Operational signals: Day-0 support in SGLang and vLLM suggests the kernels and scheduler changes are production-aimed, not research-only. DeepSeek also references TileLang, DeepGEMM (indexer logits), and FlashMLA (sparse kernels) for open-source kernels.
  • Pricing: DeepSeek says API prices were cut by 50%+, consistent with model-card messaging about efficiency and Reuters/TechCrunch coverage that the release targets lower long-context inference economics.

Summary

DeepSeek V3.2-Exp shows that trainable sparsity (DSA) can hold benchmark parity while materially improving long-context economics: official docs commit to 50%+ API price cuts, with day-0 runtime support already available, and community threads claim larger decode-time gains at 128k that warrant independent replication under matched batching and cache policies. The near-term takeaway for teams is simple: treat V3.2-Exp as a drop-in A/B for RAG and long-document pipelines where O(L2)O(L^2)O(L2) attention dominates costs, and validate end-to-end throughput/quality on your stack.


FAQs

1) What exactly is DeepSeek V3.2-Exp?
V3.2-Exp is an experimental, intermediate update to V3.1-Terminus that introduces DeepSeek Sparse Attention (DSA) to improve long-context efficiency.

2) Is it truly open source, and under what license?
Yes. The repository and model weights are licensed under MIT, per the official Hugging Face model card (License section).

3) What is DeepSeek Sparse Attention (DSA) in practice?
DSA adds a lightweight indexing stage to score/select a small set of relevant tokens, then runs attention only over that subset—yielding “fine-grained sparse attention” and reported long-context training/inference efficiency gains while keeping output quality on par with V3.1.


Check out the GitHub Page and Hugging Face Model Card. Feel free to check out our GitHub Page for Tutorials, Codes and Notebooks. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter.

Asif Razzaq is the CEO of Marktechpost Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.

🔥[Recommended Read] NVIDIA AI Open-Sources ViPE (Video Pose Engine): A Powerful and Versatile 3D Video Annotation Tool for Spatial AI

Credit: Source link

ShareTweetSendSharePin

Related Posts

Cat Wu to Lead Product Management for OpenAI’s Core Products – Unite.AI
AI & Technology

Cat Wu to Lead Product Management for OpenAI’s Core Products – Unite.AI

November 5, 2026
Snap Has More Than 30 Million Paid Subscribers Across Snapchat+ And Other Plans
AI & Technology

Snap Has More Than 30 Million Paid Subscribers Across Snapchat+ And Other Plans

November 4, 2026
Atmospheric AI Secures M Seed for Procurement Modeling Push – Unite.AI
AI & Technology

Atmospheric AI Secures $10M Seed for Procurement Modeling Push – Unite.AI

November 4, 2026
Perplexity Adds Live Web Grounding to Its Decisions API – Unite.AI
AI & Technology

Perplexity Adds Live Web Grounding to Its Decisions API – Unite.AI

November 4, 2026
Next Post
Shoe Carnival: Short Sellers May Be Underestimating The Rebannering Story

Shoe Carnival: Short Sellers May Be Underestimating The Rebannering Story

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Bandwidth Inc. (BAND) Q3 2026 Earnings Call Transcript

Bandwidth Inc. (BAND) Q3 2026 Earnings Call Transcript

October 29, 2026
Russian strikes kill at least 21, wound 60 across Ukraine

Russian strikes kill at least 21, wound 60 across Ukraine

October 30, 2026
Six Mental Models to Tell Moats from Traps by Rob May – Unite.AI

Six Mental Models to Tell Moats from Traps by Rob May – Unite.AI

October 31, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!