• bitcoinBitcoin(BTC)$77,111.00-3.54%
  • ethereumEthereum(ETH)$2,222.75-4.04%
  • tetherTether(USDT)$1.000.01%
  • binancecoinBNB(BNB)$698.52-6.00%
  • rippleXRP(XRP)$1.24-3.73%
  • usd-coinUSDC(USDC)$1.000.01%
  • solanaSolana(SOL)$95.57-4.65%
  • tronTRON(TRX)$0.3344430.87%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.03-0.38%
  • HyperliquidHyperliquid(HYPE)$91.430.97%
  • zcashZcash(ZEC)$1,237.18-2.73%
  • dogecoinDogecoin(DOGE)$0.075531-4.26%
  • moneroMonero(XMR)$587.41-1.76%
  • USDSUSDS(USDS)$1.000.08%
  • whitebitWhiteBIT Coin(WBT)$73.91-3.71%
  • leo-tokenLEO Token(LEO)$9.42-0.51%
  • chainlinkChainlink(LINK)$11.05-4.64%
  • cardanoCardano(ADA)$0.192229-4.36%
  • stellarStellar(XLM)$0.166867-2.31%
  • bitcoin-cashBitcoin Cash(BCH)$285.652.61%
  • nearNEAR Protocol(NEAR)$4.25-4.12%
  • RainRain(RAIN)$0.006620-0.21%
  • daiDai(DAI)$1.000.05%
  • Ethena USDeEthena USDe(USDE)$1.00-0.06%
  • litecoinLitecoin(LTC)$55.36-4.19%
  • uniswapUniswap(UNI)$6.88-4.01%
  • USD1USD1(USD1)$1.00-0.10%
  • CantonCanton(CC)$0.096343-6.06%
  • avalanche-2Avalanche(AVAX)$8.25-6.01%
  • suiSui(SUI)$0.89-4.26%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.16-4.23%
  • hedera-hashgraphHedera(HBAR)$0.071886-3.15%
  • tether-goldTether Gold(XAUT)$3,922.25-2.53%
  • Global DollarGlobal Dollar(USDG)$1.000.04%
  • paypal-usdPayPal USD(PYUSD)$1.000.06%
  • shiba-inuShiba Inu(SHIB)$0.000005-2.75%
  • quant-networkQuant(QNT)$193.26-0.31%
  • BittensorBittensor(TAO)$231.75-7.63%
  • crypto-com-chainCronos(CRO)$0.051501-4.19%
  • Ripple USDRipple USD(RLUSD)$1.000.02%
  • EthenaEthena(ENA)$0.186745-8.63%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.04%
  • Circle USYCCircle USYC(USYC)$1.140.03%
  • okbOKB(OKB)$110.80-1.38%
  • MemeCoreMemeCore(M)$0.97-9.06%
  • pepePepe(PEPE)$0.0000056.31%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • aaveAave(AAVE)$125.02-5.50%
  • OndoOndo(ONDO)$0.390603-5.58%
  • BitwayBitway(BTW)$1.25-29.82%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Dataset Reset Policy Optimization (DR-PO): A Machine Learning Algorithm that Exploits a Generative Model’s Ability to Reset from Offline Data to Enhance RLHF from Preference-based Feedback

April 17, 2024
in AI & Technology
Reading Time: 5 mins read
A A
Dataset Reset Policy Optimization (DR-PO): A Machine Learning Algorithm that Exploits a Generative Model’s Ability to Reset from Offline Data to Enhance RLHF from Preference-based Feedback
ShareShareShareShareShare

Reinforcement Learning (RL) continuously evolves as researchers explore methods to refine algorithms that learn from human feedback. This domain of learning algorithms deals with challenges in defining and optimizing reward functions critical for training models to perform various tasks ranging from gaming to language processing.

A prevalent issue in this area is the inefficient use of pre-collected datasets of human preferences, often overlooked in the RL training processes. Traditionally, these models are trained from scratch, ignoring existing datasets’ rich, informative content. This disconnect leads to inefficiencies and a lack of utilization of valuable, pre-existing knowledge. Recent advancements have introduced innovative methods that effectively integrate offline data into the RL training process to address this inefficiency.

Researchers from Cornell University, Princeton University, and Microsoft Research introduced a new algorithm, the Dataset Reset Policy Optimization (DR-PO) method. This method ingeniously incorporates preexisting data into the model training rule and is distinguished by its ability to reset directly to specific states from an offline dataset during policy optimization. It contrasts with traditional methods that begin every training episode from a generic initial state.

The DR-PO method enhances offline data by allowing the model to ‘reset’ to specific, beneficial states already identified as useful in the offline data. This process reflects real-world conditions where scenarios are not always initiated from scratch but are often influenced by prior events or states. By leveraging this data, DR-PO improves the efficiency of the learning process and broadens the application scope of the trained models.

DR-PO employs a hybrid strategy that blends online and offline data streams. This method capitalizes on the informative nature of the offline dataset by resetting the policy optimizer to states previously identified as valuable by human labelers. The integration of this method has demonstrated promising improvements over traditional techniques, which often disregard the potential insights available in pre-collected data.

DR-PO has shown outstanding results in studies involving tasks like TL;DR summarization and the Anthropic Helpful Harmful dataset. DR-PO has outperformed established methods like Proximal Policy Optimization (PPO) and Direction Preference Optimization (DPO). In the TL;DR summarization task, DR-PO achieved a higher GPT4 win rate, enhancing the quality of generated summaries. In head-to-head comparisons, DR-PO’s approach to integrating resets and offline data has consistently demonstrated superior performance metrics.

In conclusion, DR-PO presents a significant breakthrough in RL. DR-PO overcomes traditional inefficiencies by integrating pre-collected, human-preferred data into the RL training process. This method enhances learning efficiency by utilizing resets to specific states identified in offline datasets. Empirical evidence demonstrates that DR-PO surpasses conventional approaches such as Proximal Policy Optimization and Direction Preference Optimization in real-world applications like TL;DR summarization, achieving superior GPT4 win rates. This innovative approach streamlines the training process and maximizes the utility of existing human feedback, setting a new benchmark in adapting offline data for model optimization.


Check out the Paper and Github. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter. Join our Telegram Channel, Discord Channel, and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our 40k+ ML SubReddit


Want to get in front of 1.5 Million AI Audience? Work with us here

YOU MAY ALSO LIKE

CXMT Q3 Revenue Rises 613% as DRAM Shortage Swings It to Profit – Unite.AI

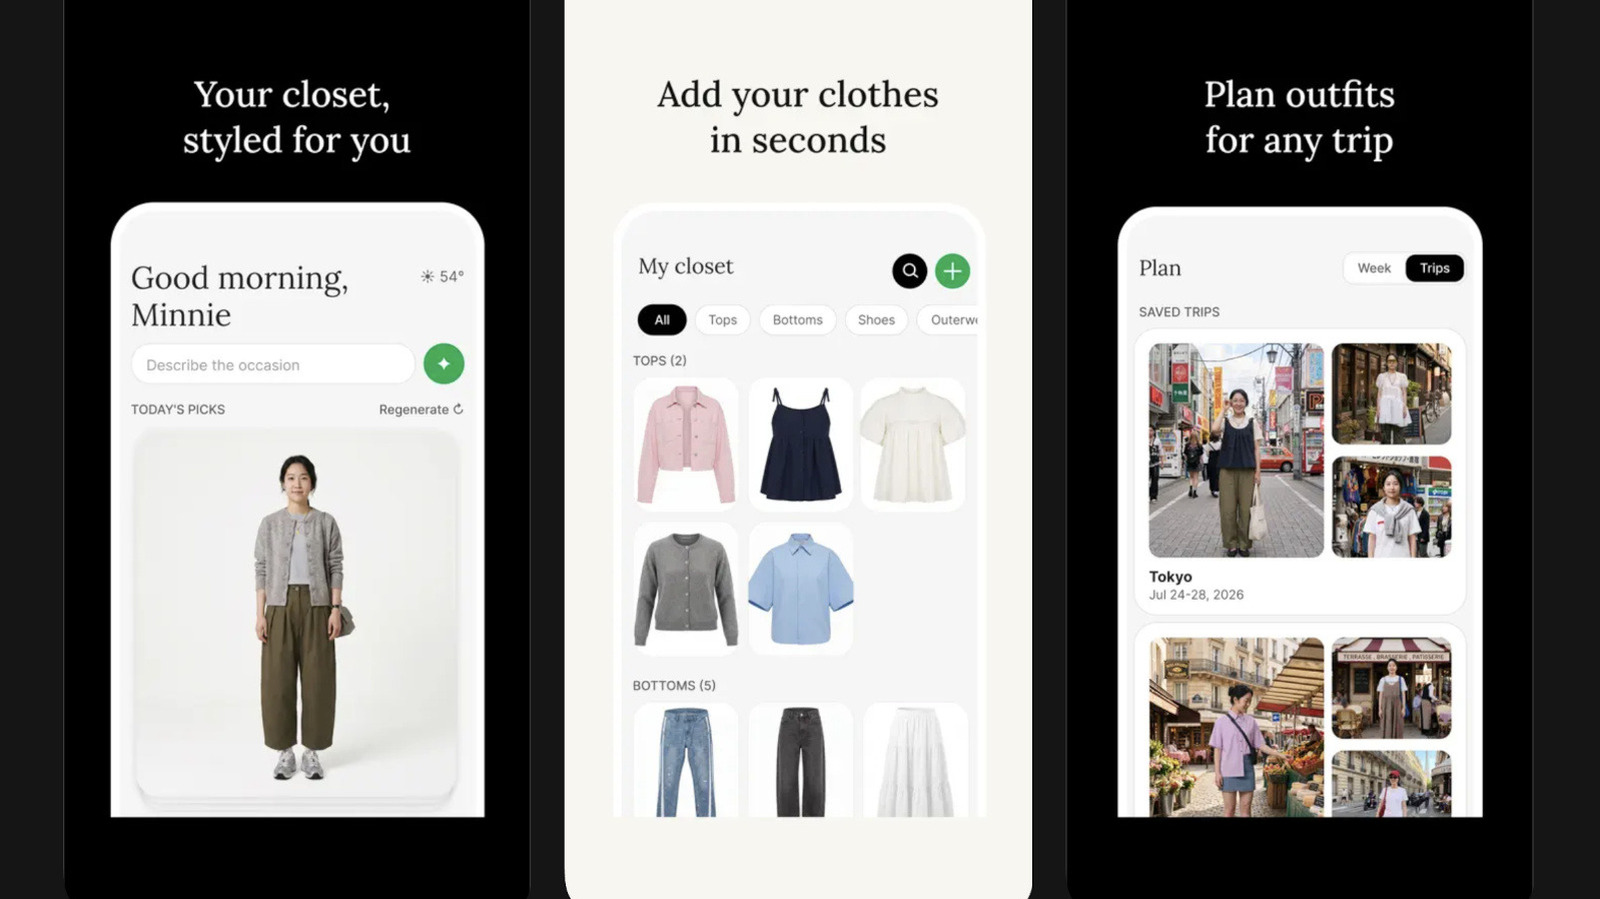
Meta Quietly Launches An AI Fashion App For Virtually Trying On Clothes

Hello, My name is Adnan Hassan. I am a consulting intern at Marktechpost and soon to be a management trainee at American Express. I am currently pursuing a dual degree at the Indian Institute of Technology, Kharagpur. I am passionate about technology and want to create new products that make a difference.


🐝 Join the Fastest Growing AI Research Newsletter Read by Researchers from Google + NVIDIA + Meta + Stanford + MIT + Microsoft and many others…


Credit: Source link

ShareTweetSendSharePin

Related Posts

CXMT Q3 Revenue Rises 613% as DRAM Shortage Swings It to Profit – Unite.AI
AI & Technology

CXMT Q3 Revenue Rises 613% as DRAM Shortage Swings It to Profit – Unite.AI

October 30, 2026
Meta Quietly Launches An AI Fashion App For Virtually Trying On Clothes
AI & Technology

Meta Quietly Launches An AI Fashion App For Virtually Trying On Clothes

October 30, 2026
Waymo And Toyota Will Soon Start Testing Their Robotaxis In Japan
AI & Technology

Waymo And Toyota Will Soon Start Testing Their Robotaxis In Japan

October 30, 2026
Cognizant Forms OpenAI Frontier Capability Group of 25,000+ Professionals – Unite.AI
AI & Technology

Cognizant Forms OpenAI Frontier Capability Group of 25,000+ Professionals – Unite.AI

October 30, 2026
Next Post
Arlington, VA: Emerging as a New Powerhouse in AI Innovation

Arlington, VA: Emerging as a New Powerhouse in AI Innovation

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
OpenAI Moves Toward a .25 Trillion Value

OpenAI Moves Toward a $1.25 Trillion Value

October 25, 2026
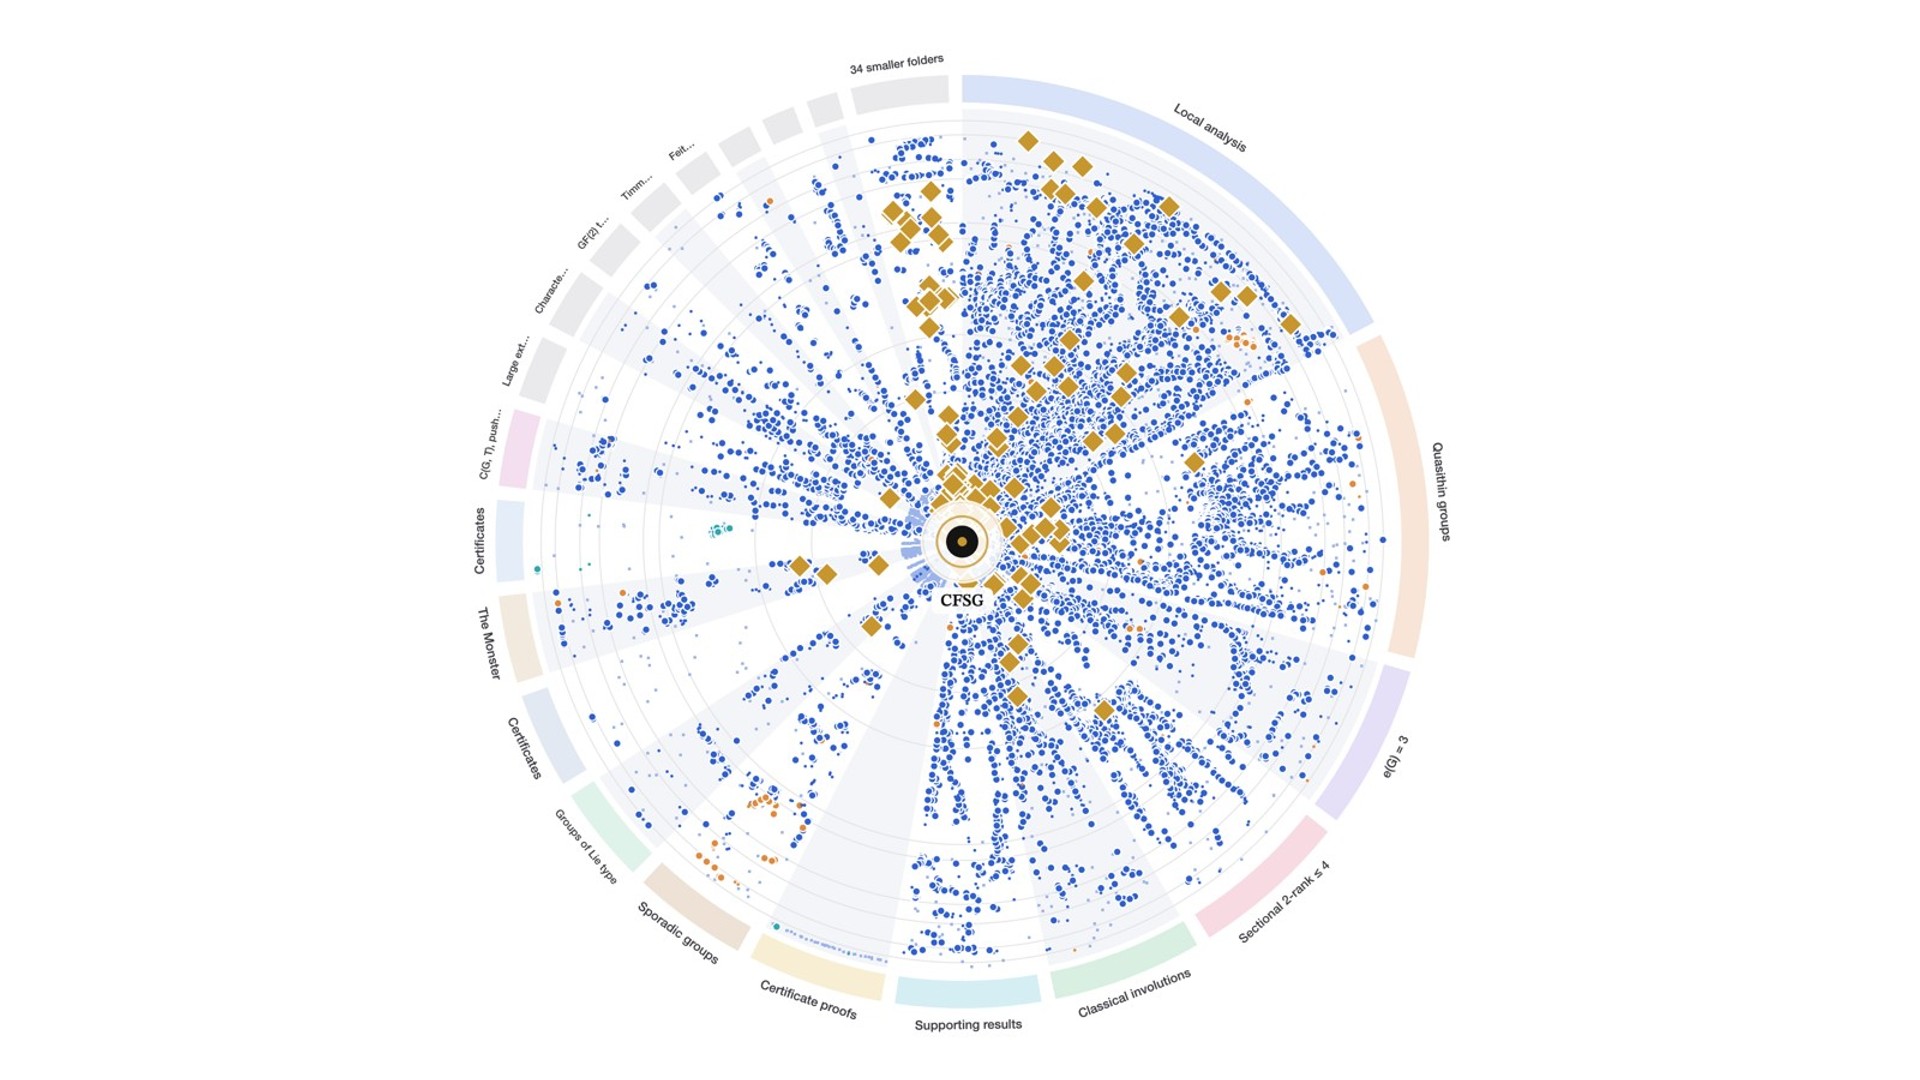
Axiom Math Releases 43.1M-Line Lean Proof of Group Classification – Unite.AI

Axiom Math Releases 43.1M-Line Lean Proof of Group Classification – Unite.AI

October 27, 2026
Storms leave hundreds of thousands without power

Storms leave hundreds of thousands without power

October 27, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!