• bitcoinBitcoin(BTC)$85,950.006.55%
  • ethereumEthereum(ETH)$2,742.676.11%
  • tetherTether(USDT)$1.000.01%
  • binancecoinBNB(BNB)$797.845.92%
  • rippleXRP(XRP)$1.508.92%
  • usd-coinUSDC(USDC)$1.000.01%
  • solanaSolana(SOL)$118.229.25%
  • tronTRON(TRX)$0.3449640.10%
  • zcashZcash(ZEC)$1,524.376.03%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.020.00%
  • HyperliquidHyperliquid(HYPE)$94.173.49%
  • dogecoinDogecoin(DOGE)$0.09468911.21%
  • moneroMonero(XMR)$576.226.66%
  • whitebitWhiteBIT Coin(WBT)$86.465.52%
  • RainRain(RAIN)$0.01411711.00%
  • chainlinkChainlink(LINK)$13.027.26%
  • USDSUSDS(USDS)$1.000.02%
  • cardanoCardano(ADA)$0.24441010.26%
  • leo-tokenLEO Token(LEO)$8.990.62%
  • stellarStellar(XLM)$0.21147810.33%
  • uniswapUniswap(UNI)$8.913.34%
  • nearNEAR Protocol(NEAR)$4.1312.47%
  • bitcoin-cashBitcoin Cash(BCH)$264.397.60%
  • avalanche-2Avalanche(AVAX)$11.192.85%
  • Ethena USDeEthena USDe(USDE)$1.000.02%
  • litecoinLitecoin(LTC)$62.7610.12%
  • daiDai(DAI)$1.000.01%
  • CantonCanton(CC)$0.1154639.03%
  • USD1USD1(USD1)$1.000.02%
  • suiSui(SUI)$1.0426.39%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.444.82%
  • hedera-hashgraphHedera(HBAR)$0.0914644.44%
  • shiba-inuShiba Inu(SHIB)$0.0000068.80%
  • MemeCoreMemeCore(M)$1.50-2.43%
  • Global DollarGlobal Dollar(USDG)$1.000.01%
  • BittensorBittensor(TAO)$285.3413.34%
  • crypto-com-chainCronos(CRO)$0.06424510.12%
  • paypal-usdPayPal USD(PYUSD)$1.000.02%
  • tether-goldTether Gold(XAUT)$4,341.46-0.63%
  • okbOKB(OKB)$123.096.04%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • BitwayBitway(BTW)$0.9024.94%
  • Ripple USDRipple USD(RLUSD)$1.000.00%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.00%
  • EthenaEthena(ENA)$0.22357011.96%
  • aaveAave(AAVE)$145.518.11%
  • OndoOndo(ONDO)$0.4484309.51%
  • mantleMantle(MNT)$0.647.28%
  • AsterAster(ASTER)$0.764.14%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Cutting Costs, Not Performance: Structured FeedForward Networks FFNs in Transformer-Based LLMs

July 1, 2024
in AI & Technology
Reading Time: 5 mins read
A A
Cutting Costs, Not Performance: Structured FeedForward Networks FFNs in Transformer-Based LLMs
ShareShareShareShareShare

Optimizing the efficiency of Feedforward Neural Networks (FFNs) within Transformer architectures is a significant challenge in AI. Large language models (LLMs) are highly resource-intensive, requiring substantial computational power and energy, which restricts their applicability and raises environmental concerns. Efficiently addressing this challenge is crucial for promoting sustainable AI practices and making advanced AI technologies more accessible by reducing operational costs.

Current methods to enhance FFN efficiency typically involve low-rank approximations and structured matrices. Approaches such as LowRank and BlockDense decompositions have been proposed to reduce parameters and FLOPs. However, these methods often face limitations in practical scenarios. For instance, low-rank approximations can suffer from poor optimization dynamics due to increased symmetries leading to saddle points, and structured matrices can result in suboptimal training dynamics and reduced efficiency in online decoding due to poor parallelism on GPUs. These limitations make the existing methods less suitable for real-time applications and large-scale deployments.

YOU MAY ALSO LIKE

A Laptop That Works Better With Your Android Phone

How AI Modernizes Lending Alongside Legacy Banking Systems Without a Teardown – Unite.AI

A team of researchers from Google DeepMind and EPFL propose a hybrid structure combining low-rank and block-diagonal matrices with a technique termed ‘self-guided training.’ This new method aims to mitigate the optimization issues by introducing a dense matrix during the initial training phase, which is gradually phased out, allowing the structured matrices to take over. This approach ensures better training stability and faster convergence. The hybrid method not only addresses computational efficiency but also ensures that optimization dynamics are smooth, reducing the occurrence of loss spikes and instability and thus representing a significant advancement over existing methods.

The research employs structured linear parameterization, where the FFN layers are approximated using combinations of low-rank and block-diagonal matrices. The key innovation is the ‘self-guided training’ method, where the dense matrix aids in the early training stages, progressively transitioning to efficient structured forms. The training utilizes the RefinedWeb dataset, which includes 600B tokens, and employs advanced GPU optimizations like mixed precision training, Flash Attention, and rotary embeddings. Hyperparameters such as learning rates and dropout rates are meticulously tuned to ensure optimal performance. The proposed models are tested at scales ranging from 110M to 1.3B parameters, demonstrating scalability and robustness.

The innovative method significantly enhances training and inference efficiency. The structured FFN models achieved a 1.35× speed-up in training and a 2.5× faster FFN at inference with only a slight increase in perplexity. The ‘self-guided training’ technique resulted in a 0.4 reduction in perplexity on a 1.3B parameter model with consistent training FLOPs. The approach demonstrated improved performance metrics, including lower perplexity and higher throughput, validating its efficacy and superiority over traditional FFNs.
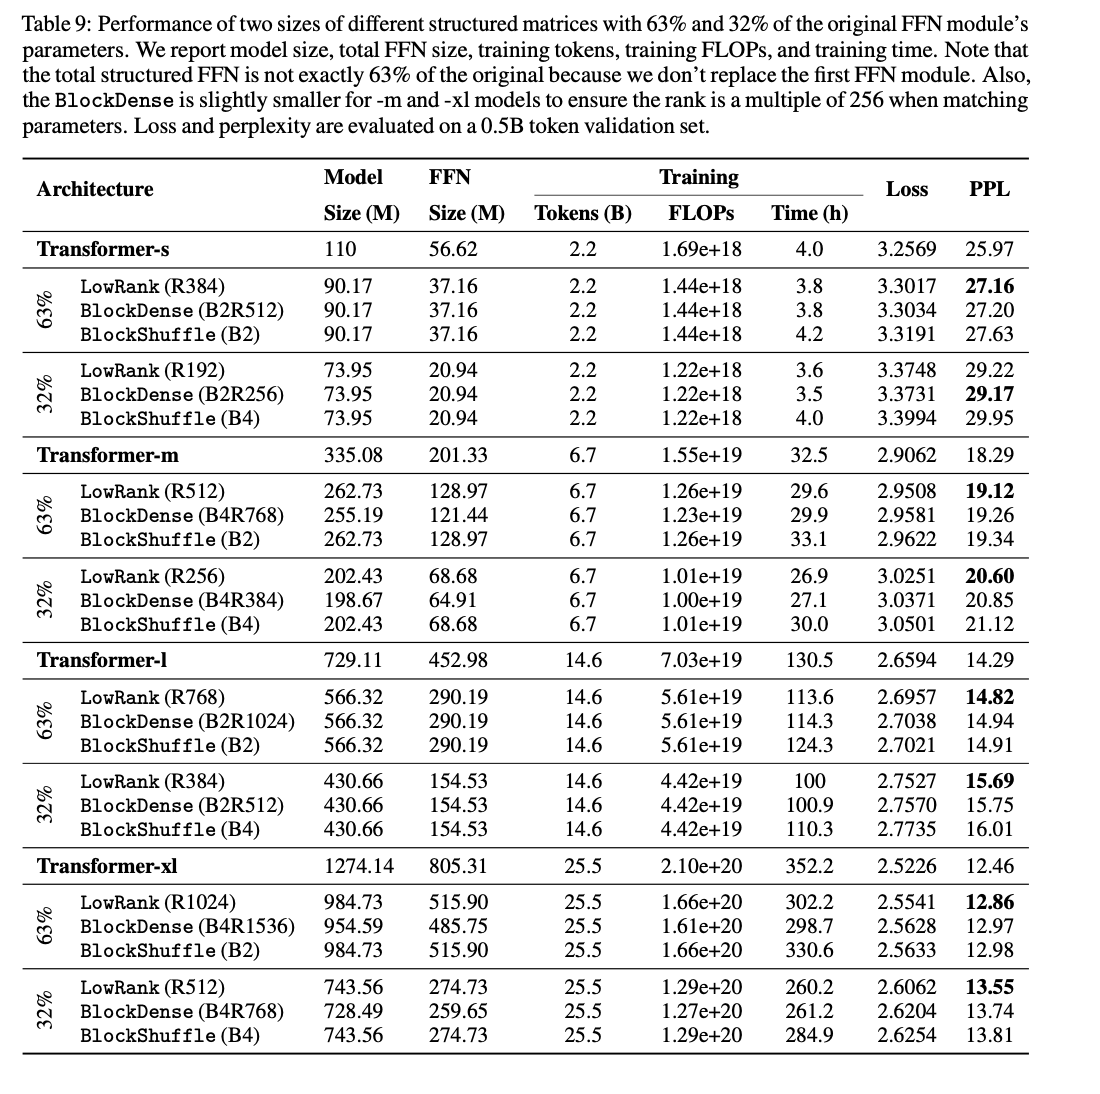
In conclusion, this research presents a significant contribution to optimizing large language models by introducing a hybrid structured FFN approach combined with self-guided training. This innovation addresses critical limitations of existing methods, resulting in improved training efficiency and model performance. The findings suggest that this advancement could propel AI research forward by making large-scale models more computationally efficient and accessible, thereby promoting sustainable and democratized AI development.


Check out the Paper. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter. 

Join our Telegram Channel and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our 45k+ ML SubReddit

Aswin AK is a consulting intern at MarkTechPost. He is pursuing his Dual Degree at the Indian Institute of Technology, Kharagpur. He is passionate about data science and machine learning, bringing a strong academic background and hands-on experience in solving real-life cross-domain challenges.

🐝 Join the Fastest Growing AI Research Newsletter Read by Researchers from Google + NVIDIA + Meta + Stanford + MIT + Microsoft and many others…


Credit: Source link

ShareTweetSendSharePin

Related Posts

A Laptop That Works Better With Your Android Phone
AI & Technology

A Laptop That Works Better With Your Android Phone

September 21, 2026
How AI Modernizes Lending Alongside Legacy Banking Systems Without a Teardown – Unite.AI
AI & Technology

How AI Modernizes Lending Alongside Legacy Banking Systems Without a Teardown – Unite.AI

September 21, 2026
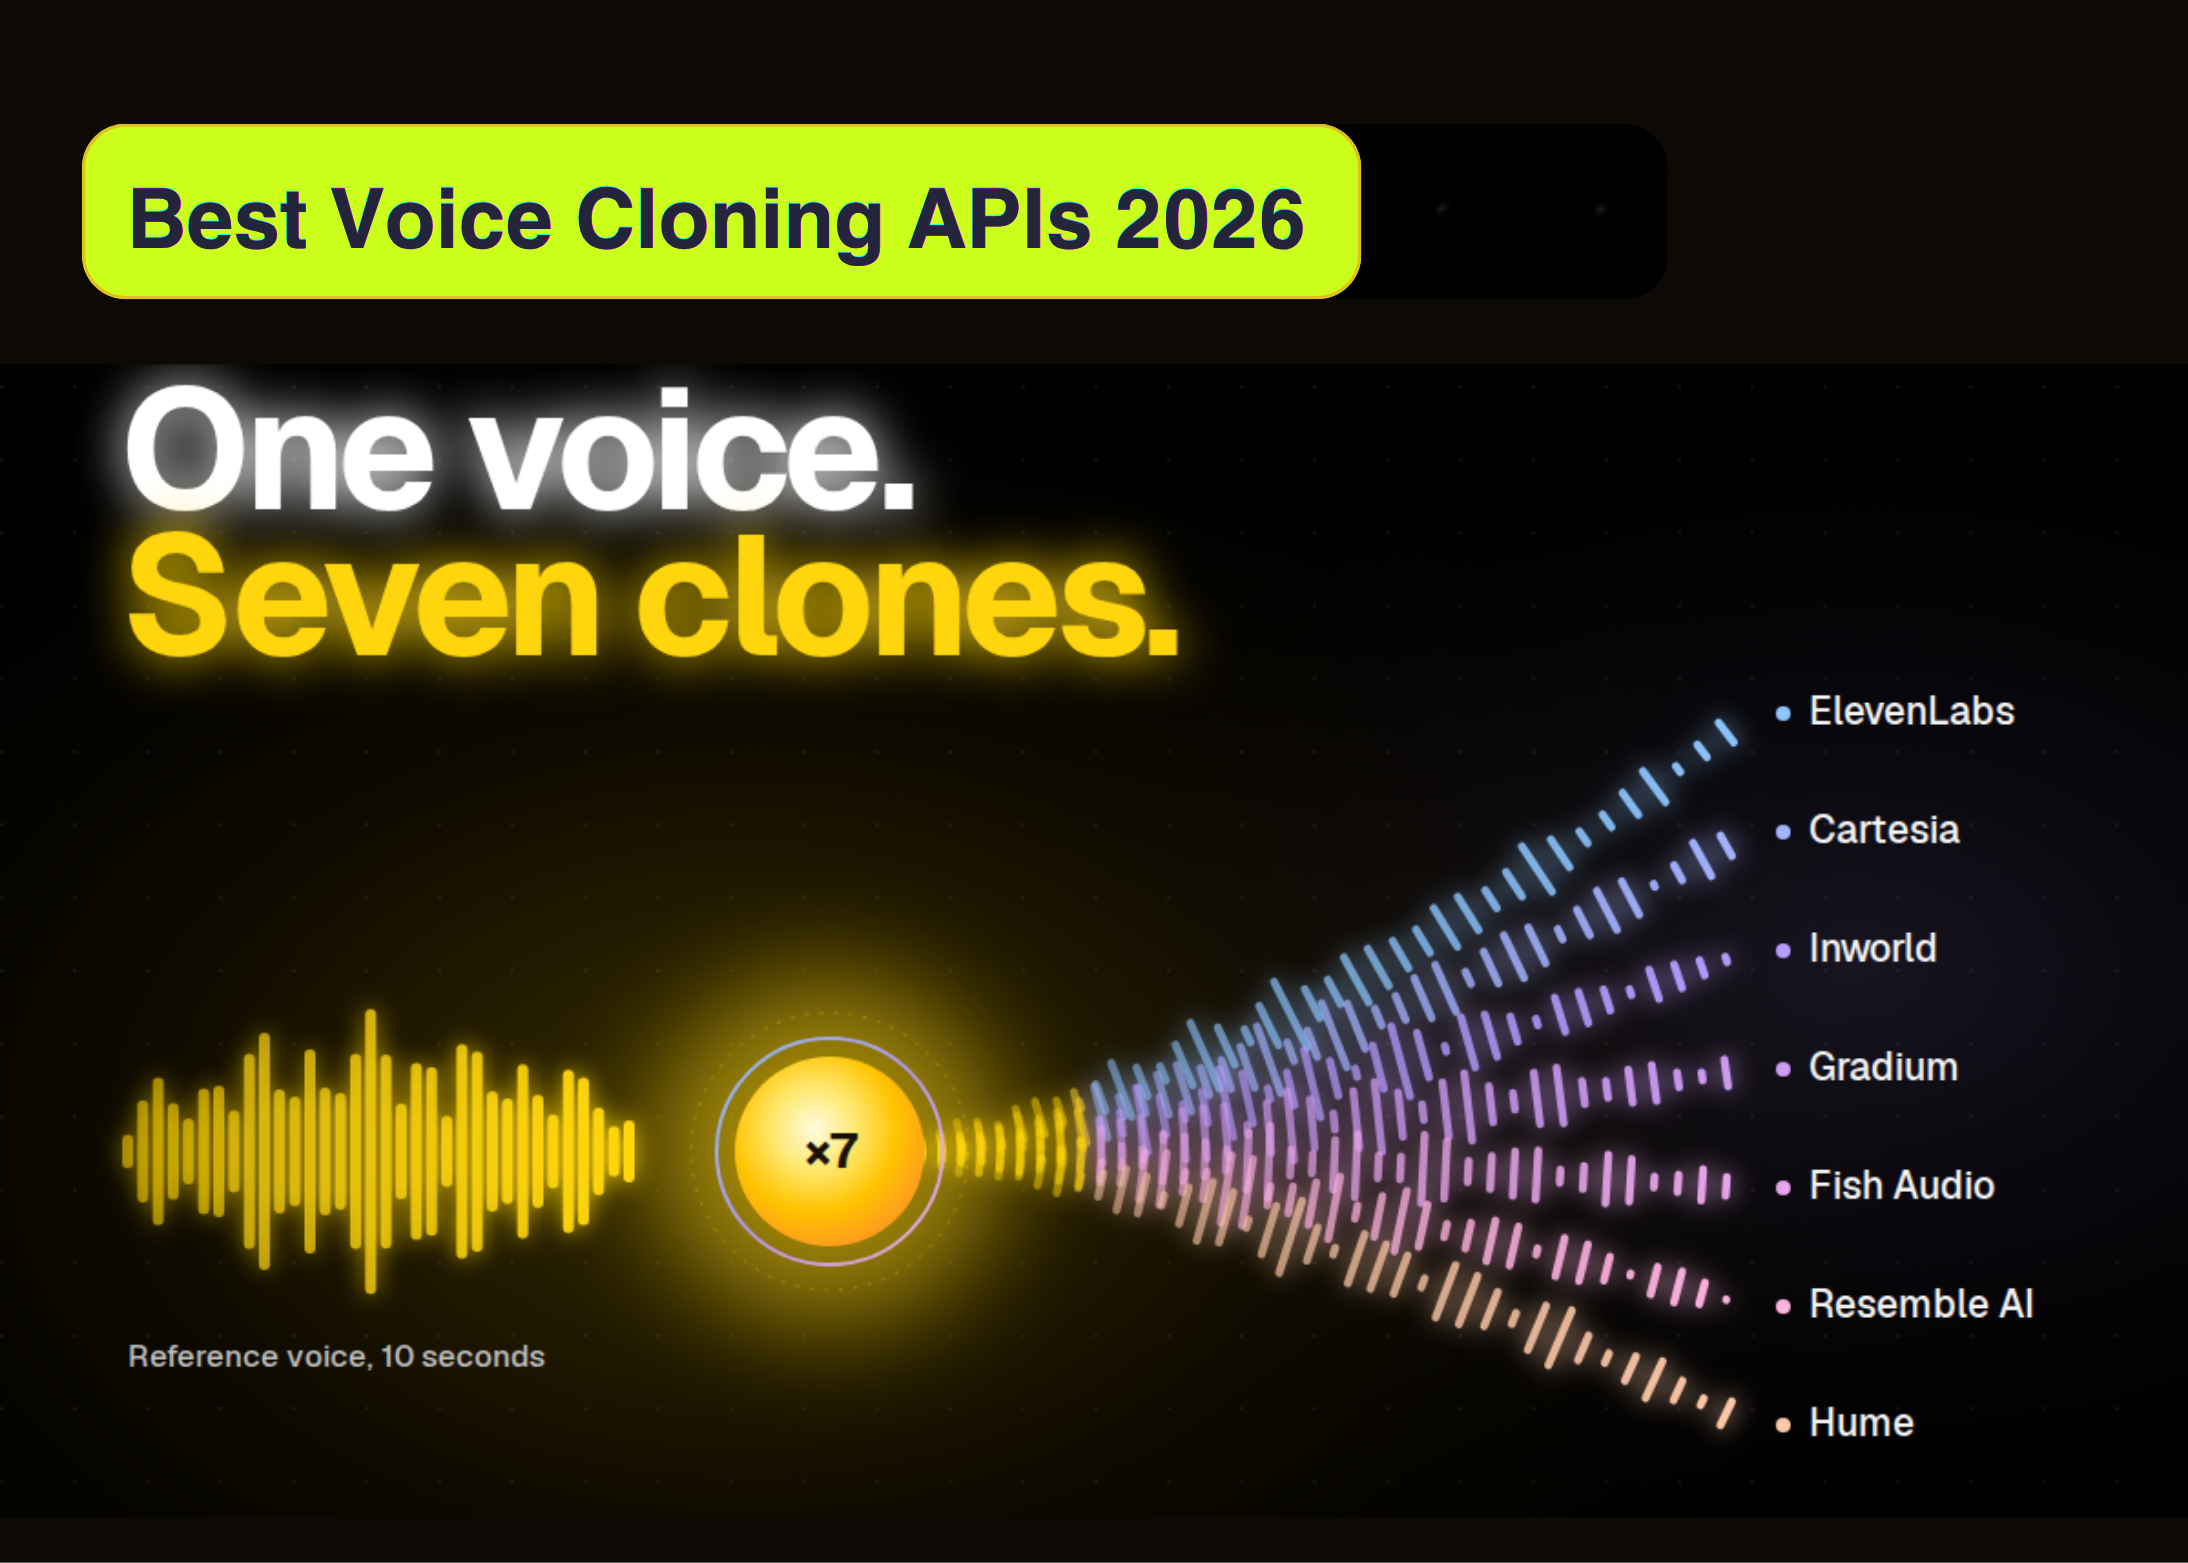
Best Voice Cloning APIs in 2026: Speaker Similarity, Consent Checks, and Price per 1M Characters
AI & Technology

Best Voice Cloning APIs in 2026: Speaker Similarity, Consent Checks, and Price per 1M Characters

September 21, 2026
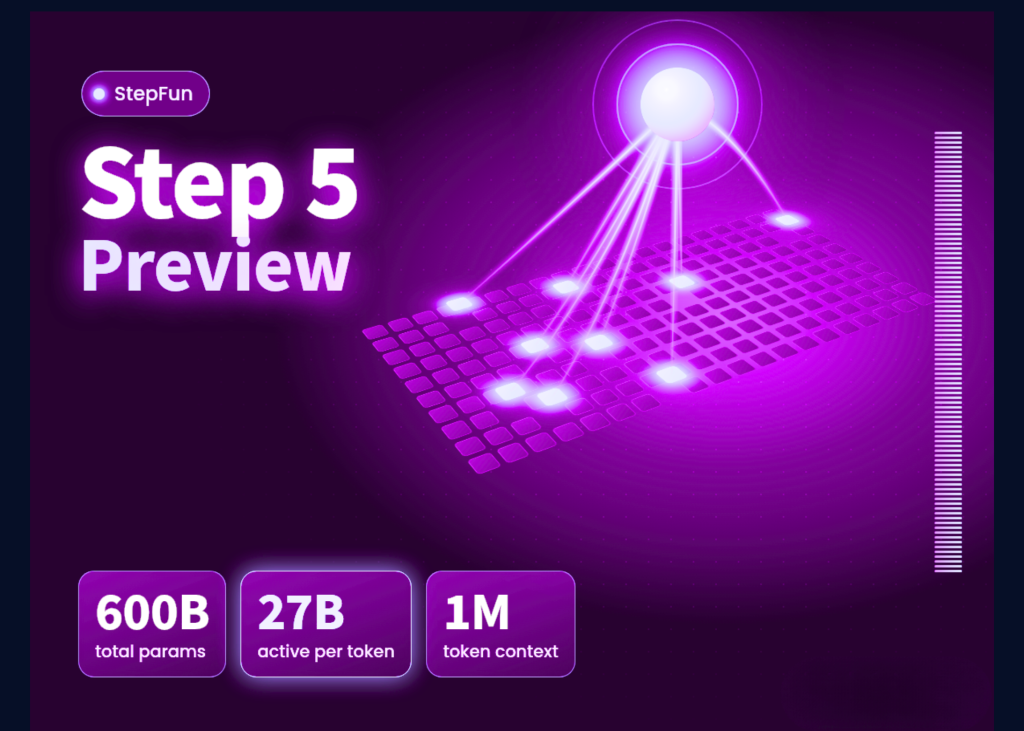
StepFun Launches Step 5 Preview: A 600B-Total, 27B-Active MoE Model With 1M Context for Long-Horizon Agentic Work
AI & Technology

StepFun Launches Step 5 Preview: A 600B-Total, 27B-Active MoE Model With 1M Context for Long-Horizon Agentic Work

September 21, 2026
Next Post
Runway Gen-3: Game-Changer or Overhyped?

Runway Gen-3: Game-Changer or Overhyped?

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
1984 track champ preps South LA bakery for 2028 Olympics

1984 track champ preps South LA bakery for 2028 Olympics

September 15, 2026
ICE agents detain more than 100 people in Memphis

ICE agents detain more than 100 people in Memphis

September 20, 2026
Decades-Old Anonymized Medical Data May Cause AI Misdiagnoses Now – Unite.AI

Decades-Old Anonymized Medical Data May Cause AI Misdiagnoses Now – Unite.AI

September 18, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!