• bitcoinBitcoin(BTC)$74,898.000.42%
  • ethereumEthereum(ETH)$2,121.92-0.38%
  • tetherTether(USDT)$1.00-0.01%
  • binancecoinBNB(BNB)$688.810.69%
  • usd-coinUSDC(USDC)$1.00-0.01%
  • rippleXRP(XRP)$1.09-2.46%
  • solanaSolana(SOL)$86.24-0.58%
  • tronTRON(TRX)$0.316598-0.92%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.050.00%
  • zcashZcash(ZEC)$1,168.77-4.25%
  • HyperliquidHyperliquid(HYPE)$75.090.27%
  • moneroMonero(XMR)$592.66-1.60%
  • dogecoinDogecoin(DOGE)$0.0697600.68%
  • USDSUSDS(USDS)$1.00-0.01%
  • whitebitWhiteBIT Coin(WBT)$72.170.14%
  • leo-tokenLEO Token(LEO)$9.310.54%
  • chainlinkChainlink(LINK)$10.642.57%
  • cardanoCardano(ADA)$0.1770661.03%
  • stellarStellar(XLM)$0.1469890.82%
  • Ethena USDeEthena USDe(USDE)$1.00-0.02%
  • bitcoin-cashBitcoin Cash(BCH)$238.01-1.19%
  • nearNEAR Protocol(NEAR)$3.642.63%
  • daiDai(DAI)$1.000.00%
  • uniswapUniswap(UNI)$7.043.89%
  • litecoinLitecoin(LTC)$51.321.99%
  • avalanche-2Avalanche(AVAX)$8.648.60%
  • CantonCanton(CC)$0.0918041.02%
  • suiSui(SUI)$0.842.18%
  • tether-goldTether Gold(XAUT)$4,115.841.97%
  • USD1USD1(USD1)$1.000.01%
  • RainRain(RAIN)$0.004541-10.24%
  • hedera-hashgraphHedera(HBAR)$0.0669052.01%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.020.65%
  • quant-networkQuant(QNT)$194.730.68%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.01%
  • Global DollarGlobal Dollar(USDG)$1.00-0.01%
  • Ripple USDRipple USD(RLUSD)$1.00-0.01%
  • shiba-inuShiba Inu(SHIB)$0.0000041.66%
  • BittensorBittensor(TAO)$222.352.63%
  • crypto-com-chainCronos(CRO)$0.0479431.55%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.15-0.34%
  • pepePepe(PEPE)$0.0000053.55%
  • Circle USYCCircle USYC(USYC)$1.140.00%
  • EthenaEthena(ENA)$0.1536473.60%
  • aaveAave(AAVE)$131.463.75%
  • okbOKB(OKB)$96.29-2.91%
  • Spiko Amundi Overnight Swap Fund (EUR)Spiko Amundi Overnight Swap Fund (EUR)(EURSAFO)$1.140.77%
  • pax-goldPAX Gold(PAXG)$4,120.932.13%
  • Falcon USDFalcon USD(USDF)$0.99-0.08%
  • OndoOndo(ONDO)$0.3716495.50%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

CS-Bench: A Bilingual (Chinese-English) Benchmark Dedicated to Evaluating the Performance of LLMs in Computer Science

June 21, 2024
in AI & Technology
Reading Time: 4 mins read
A A
CS-Bench: A Bilingual (Chinese-English) Benchmark Dedicated to Evaluating the Performance of LLMs in Computer Science
ShareShareShareShareShare

The domain of artificial intelligence has been significantly shaped by the emergence of large language models (LLMs), showing vast potential across various fields. However, enabling LLMs to effectively utilize computer science knowledge and serve humanity more efficiently remains a key challenge. Despite existing studies covering multiple fields, including computer science, there’s a lack of comprehensive evaluation specifically focused on LLMs’ performance in computer science. This gap overlooks the importance of thoroughly assessing the field and guiding LLM development to advance their capabilities in computer science.

Recent research has explored LLMs’ potential in various industries and scientific fields. However, studies on LLMs in computer science fall into two main categories: broad evaluation benchmarks where computer science constitutes only a small fraction, and explorations of specific LLM applications within computer science. Neither approach provides a comprehensive evaluation of LLMs’ foundational knowledge and reasoning abilities in the field. While individual capabilities like mathematics, coding, and logical reasoning have been well-studied, research on their integrated application and interrelationships remains sparse.

YOU MAY ALSO LIKE

YouTube Will Once Again Be Part Of Billboard Chart Calculations In 2027

ByteDance Seed Introduces Seedream 5.5 for Multi-Round Image Editing – Unite.AI

Researchers from Beijing University of Posts and Telecommunications propose CS-Bench, the first benchmark dedicated to evaluating LLMs’ performance in computer science. CS-Bench features high-quality, diverse task forms, varying capacities, and bilingual evaluation. It comprises approximately 5,000 carefully curated test items spanning 26 sections across 4 key computer science domains. The benchmark includes multiple-choice, assertion, fill-in-the-blank, and open-ended questions to better simulate real-world scenarios and assess LLMs’ robustness to different task formats. CS-Bench evaluates both knowledge-type and reasoning-type questions, supporting bilingual evaluation in Chinese and English.

CS-Bench covers four key domains: Data Structure and Algorithm (DSA), Computer Organization (CO), Computer Network(CN), and Operating System(OS). It includes 26 fine-grained subfields and diverse task forms to enrich assessment dimensions and simulate real-world scenarios. The data for CS-Bench comes from various sources, including publicly available online channels, adapted blog articles, and authorized teaching materials. The data processing involves a team of computer science graduates who parse questions and answers, label question types, and ensure quality through thorough manual checks. The benchmark supports bilingual assessment with a total of 4,838 samples across various task formats.

Evaluation results show that overall scores of models range from 39.86% to 72.29%. GPT-4 and GPT-4o represent the highest standard on CS-Bench, being the only models exceeding 70% proficiency. Open-source models like Qwen1.5-110B and Llama3-70B have surpassed previously strong closed-source models. Newer models demonstrate significant improvements compared to earlier versions. All models perform worse on reasoning compared to knowledge scores, indicating that reasoning poses a greater challenge. LLMs generally perform best in Data Structure and Algorithm and worst in Operating Systems. Stronger models demonstrate a better ability to use knowledge for reasoning and show more robustness across different task formats.
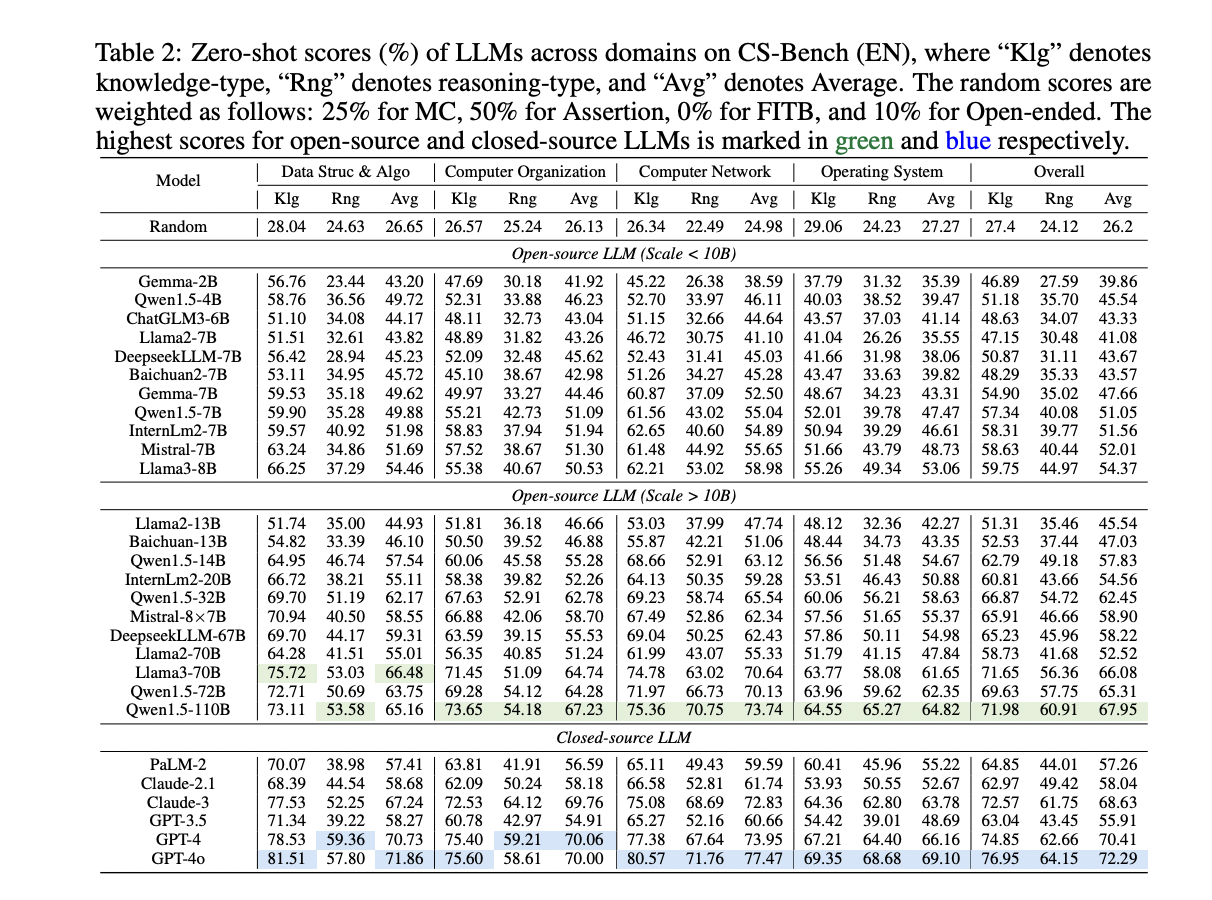
This study introduces CS-Bench to provide valuable insights into LLMs’ performance in computer science. Even top-performing models like GPT-4o have significant room for improvement. The benchmark highlights the close interconnections between computer science, mathematics, and coding abilities in LLMs. These findings offer directions for enhancing LLMs in the field and provide valuable insights into their cross-abilities and applications, paving the way for future advancements in AI and computer science.


Check out the Paper and GitHub. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter. 

Join our Telegram Channel and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our 45k+ ML SubReddit

Asjad is an intern consultant at Marktechpost. He is persuing B.Tech in mechanical engineering at the Indian Institute of Technology, Kharagpur. Asjad is a Machine learning and deep learning enthusiast who is always researching the applications of machine learning in healthcare.

🐝 Join the Fastest Growing AI Research Newsletter Read by Researchers from Google + NVIDIA + Meta + Stanford + MIT + Microsoft and many others…


Credit: Source link

ShareTweetSendSharePin

Related Posts

YouTube Will Once Again Be Part Of Billboard Chart Calculations In 2027
AI & Technology

YouTube Will Once Again Be Part Of Billboard Chart Calculations In 2027

November 9, 2026
ByteDance Seed Introduces Seedream 5.5 for Multi-Round Image Editing – Unite.AI
AI & Technology

ByteDance Seed Introduces Seedream 5.5 for Multi-Round Image Editing – Unite.AI

November 9, 2026
How To Use Your iPhone To Take The Best Picture Of The Moon
AI & Technology

How To Use Your iPhone To Take The Best Picture Of The Moon

November 9, 2026
Vanta Signs Deal to Acquire AI Security Firm Pillar Security – Unite.AI
AI & Technology

Vanta Signs Deal to Acquire AI Security Firm Pillar Security – Unite.AI

November 9, 2026
Next Post
“I Never Said That” (Dave Ramsey Myths)

“I Never Said That” (Dave Ramsey Myths)

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
U.S. on verge of losing measles elimination status as number of cases grows

U.S. on verge of losing measles elimination status as number of cases grows

November 8, 2026
Kohl's: Retailer Downgraded To Neutral Ahead Of Q3 Results, Awaiting Improved Earnings

Kohl's: Retailer Downgraded To Neutral Ahead Of Q3 Results, Awaiting Improved Earnings

November 7, 2026
NVIDIA Board Opens Review After Reported Foreign Intelligence Effort – Unite.AI

NVIDIA Board Opens Review After Reported Foreign Intelligence Effort – Unite.AI

November 8, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!