• bitcoinBitcoin(BTC)$80,071.00-1.60%
  • ethereumEthereum(ETH)$2,317.55-2.06%
  • tetherTether(USDT)$1.000.01%
  • binancecoinBNB(BNB)$746.31-0.99%
  • rippleXRP(XRP)$1.29-2.95%
  • usd-coinUSDC(USDC)$1.000.01%
  • solanaSolana(SOL)$100.20-2.59%
  • tronTRON(TRX)$0.331079-0.25%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.030.09%
  • zcashZcash(ZEC)$1,252.21-4.91%
  • HyperliquidHyperliquid(HYPE)$79.20-3.61%
  • dogecoinDogecoin(DOGE)$0.078087-2.83%
  • moneroMonero(XMR)$597.05-1.44%
  • USDSUSDS(USDS)$1.000.00%
  • whitebitWhiteBIT Coin(WBT)$76.87-1.65%
  • chainlinkChainlink(LINK)$11.49-2.99%
  • leo-tokenLEO Token(LEO)$9.450.83%
  • cardanoCardano(ADA)$0.199566-3.85%
  • stellarStellar(XLM)$0.168808-1.75%
  • nearNEAR Protocol(NEAR)$4.36-7.33%
  • bitcoin-cashBitcoin Cash(BCH)$279.20-7.91%
  • RainRain(RAIN)$0.006918-1.88%
  • daiDai(DAI)$1.000.00%
  • Ethena USDeEthena USDe(USDE)$1.000.01%
  • litecoinLitecoin(LTC)$57.35-0.79%
  • uniswapUniswap(UNI)$7.04-1.91%
  • USD1USD1(USD1)$1.000.00%
  • avalanche-2Avalanche(AVAX)$8.71-3.45%
  • CantonCanton(CC)$0.096740-6.62%
  • suiSui(SUI)$0.92-2.87%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.21-2.68%
  • hedera-hashgraphHedera(HBAR)$0.073869-3.46%
  • tether-goldTether Gold(XAUT)$4,025.05-0.45%
  • Global DollarGlobal Dollar(USDG)$1.000.00%
  • paypal-usdPayPal USD(PYUSD)$1.000.00%
  • BittensorBittensor(TAO)$248.95-3.09%
  • shiba-inuShiba Inu(SHIB)$0.000005-2.39%
  • BitwayBitway(BTW)$1.866.43%
  • quant-networkQuant(QNT)$192.46-4.32%
  • crypto-com-chainCronos(CRO)$0.053198-1.66%
  • EthenaEthena(ENA)$0.197333-4.67%
  • Ripple USDRipple USD(RLUSD)$1.00-0.01%
  • MemeCoreMemeCore(M)$1.05-5.45%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.01%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • okbOKB(OKB)$110.990.43%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • pepePepe(PEPE)$0.000005-1.05%
  • aaveAave(AAVE)$131.01-3.33%
  • OndoOndo(ONDO)$0.409440-2.70%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Consistency Large Language Models (CLLMs): A New Family of LLMs Specialized for the Jacobi Decoding Method for Latency Reduction

May 17, 2024
in AI & Technology
Reading Time: 5 mins read
A A
Consistency Large Language Models (CLLMs): A New Family of LLMs Specialized for the Jacobi Decoding Method for Latency Reduction
ShareShareShareShareShare

Large language models (LLMs), including GPT-4, LLaMA, and PaLM are pushing the boundaries of artificial intelligence. The inference latency of LLMs plays an important role because of LLMs integration in various applications, ensuring a positive user experience and high service quality. However, the LLM service operates within an AR paradigm, generating one token at a time because the attention mechanism relies on previous token states to generate the next token. To produce a longer response, a forward pass is executed using LLMs equivalent to the number of tokens generated, leading to high latency.

The efficient LLM Inference method is divided into two streams, a method that needs additional training and another that does not need it. Researchers explored this method due to the high AR inference cost for LLMs, mostly focused on increasing the AR decoding process. Another existing method is LLM Distillation, where the Knowledge distillation (KD) technique is used to create small models and replace the functionality of larger ones. However, traditional KD methods are not effective for LLMs. So, KD is used for autoregressive LLMs to minimize the reverse KL divergence between student and teacher models through student-driven decoding.   

Researchers from Shanghai Jiao University and the University of California proposed Consistency Large Language Models (CLLMs), a new family of LLMs specialized for the Jacobi decoding method for latency reduction. CLLM was compared with traditional methods such as speculative decoding and Medusa for adjusting auxiliary model components and didn’t use extra memory for this task, unlike others. When CLLMs are trained on ∼ 1M tokens for LLaMA-7B, it becomes 3.4 times faster on the Spider dataset showing that the cost of fine-tuning is moderate for this method. Two main factors for this speed-up are fast forwarding and stationary tokens. 

In fast forwarding, correct predictions are done in a single forward pass for multiple consecutive tokens whereas, stationary tokens show correct prediction with no change through subsequent iterations despite being preceded by inaccurate tokens. In target LLMs and CLLMs, when fast-forwarded and stationary counts are compared across all four datasets (in Table 3), there is an improvement of 2.0x to 6.8x in both token counts. Also, for both the token counts, such improvement in domain-specific datasets is better than in open-domain datasets profiled on MT-bench. This helps distinctive collocations and easy syntactical structures like blank space, newline tokens, and repetitive special characters in specialized domains like coding.

Researchers carried out experiments to evaluate the performance and inference speedup of CLLMs across multiple tasks such as comparing the stat-of-the-art (SOTA) baselines on the three domain-specific tasks and the open-domain profiled on MT-bench. CLLMs show outstanding performance on various benchmarks, e.g. they can achieve 2.4× to 3.4× speedup using Jacobi decoding with nearly no loss in accuracy on domain-specific benchmarks like GSM8K, CodeSearchNet Python, and Spider. CLLMs can achieve  2.4× speedup on ShareGPT with SOTA performance, with a 6.4 score on the open-domain benchmark MT-bench.
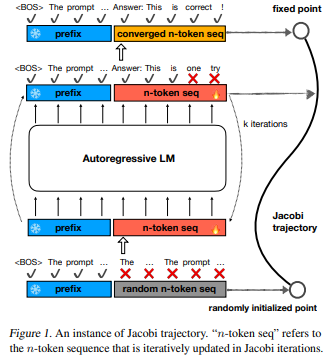
In conclusion, researchers introduced CLLMs, a new family of LLMs that excel in efficient parallel decoding and are designed in a way that they can improve the efficiency of Jacobi decoding. Additional architecture designs or managing two different models in a single system are complex and complexity is reduced with the help of CLLMs because this method is directly adapted from a target pre-trained LLM. Besides, fast-forwarded and stationary token counts are compared across four datasets, showing an enhancement of 2.0x to 6.8x In target LLMs and CLLMs. 


Check out the Paper and Project. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter. Join our Telegram Channel, Discord Channel, and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our 42k+ ML SubReddit

YOU MAY ALSO LIKE

Hackers Leaked Details Of More Than 41,000 Homeland Security Personnel

Infini-AI-Lab Releases Hermit, an Open-Source Harness Adapter Framework for AI Agents

Sajjad Ansari is a final year undergraduate from IIT Kharagpur. As a Tech enthusiast, he delves into the practical applications of AI with a focus on understanding the impact of AI technologies and their real-world implications. He aims to articulate complex AI concepts in a clear and accessible manner.


🐝 Join the Fastest Growing AI Research Newsletter Read by Researchers from Google + NVIDIA + Meta + Stanford + MIT + Microsoft and many others…


Credit: Source link

ShareTweetSendSharePin

Related Posts

Hackers Leaked Details Of More Than 41,000 Homeland Security Personnel
AI & Technology

Hackers Leaked Details Of More Than 41,000 Homeland Security Personnel

October 29, 2026
Infini-AI-Lab Releases Hermit, an Open-Source Harness Adapter Framework for AI Agents
AI & Technology

Infini-AI-Lab Releases Hermit, an Open-Source Harness Adapter Framework for AI Agents

October 29, 2026
NVIDIA Releases Nemotron 3.5 Transcribe: An Open 30B MoE Model for 40-Language Transcription with ~4B Active Parameters
AI & Technology

NVIDIA Releases Nemotron 3.5 Transcribe: An Open 30B MoE Model for 40-Language Transcription with ~4B Active Parameters

October 29, 2026
FCC Chair Wants To Let Prisons Jam Illegal Cellphones
AI & Technology

FCC Chair Wants To Let Prisons Jam Illegal Cellphones

October 28, 2026
Next Post
Sumitomo Mitsui: Multiple Positives (NYSE:SMFG)

Sumitomo Mitsui: Multiple Positives (NYSE:SMFG)

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Betterware: Tupperware Looks Better, But Jafra Looks Worse

Betterware: Tupperware Looks Better, But Jafra Looks Worse

October 24, 2026
Student protests in Albania lead to clashes with police

Student protests in Albania lead to clashes with police

October 25, 2026
Brad Raffensperger chats election security in Georgia ahead of midterms

Brad Raffensperger chats election security in Georgia ahead of midterms

October 27, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!