• bitcoinBitcoin(BTC)$84,270.00-2.38%
  • ethereumEthereum(ETH)$2,669.99-3.14%
  • tetherTether(USDT)$1.00-0.01%
  • binancecoinBNB(BNB)$765.69-2.69%
  • rippleXRP(XRP)$1.49-6.10%
  • usd-coinUSDC(USDC)$1.00-0.01%
  • solanaSolana(SOL)$114.08-3.52%
  • tronTRON(TRX)$0.340102-0.50%
  • zcashZcash(ZEC)$1,506.760.28%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.03-1.30%
  • HyperliquidHyperliquid(HYPE)$92.98-3.43%
  • dogecoinDogecoin(DOGE)$0.092002-8.45%
  • moneroMonero(XMR)$549.82-2.47%
  • whitebitWhiteBIT Coin(WBT)$84.48-2.60%
  • USDSUSDS(USDS)$1.00-0.02%
  • chainlinkChainlink(LINK)$12.23-5.91%
  • cardanoCardano(ADA)$0.236855-6.44%
  • RainRain(RAIN)$0.012247-6.73%
  • leo-tokenLEO Token(LEO)$9.010.31%
  • stellarStellar(XLM)$0.201170-6.85%
  • bitcoin-cashBitcoin Cash(BCH)$340.03-1.46%
  • nearNEAR Protocol(NEAR)$4.341.18%
  • uniswapUniswap(UNI)$9.16-2.53%
  • Ethena USDeEthena USDe(USDE)$1.00-0.01%
  • litecoinLitecoin(LTC)$60.84-3.26%
  • daiDai(DAI)$1.00-0.01%
  • avalanche-2Avalanche(AVAX)$10.28-6.33%
  • USD1USD1(USD1)$1.000.00%
  • CantonCanton(CC)$0.108785-4.59%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.41-2.89%
  • hedera-hashgraphHedera(HBAR)$0.089829-10.03%
  • suiSui(SUI)$0.96-5.33%
  • shiba-inuShiba Inu(SHIB)$0.000006-8.11%
  • BittensorBittensor(TAO)$286.93-7.52%
  • Global DollarGlobal Dollar(USDG)$1.000.01%
  • crypto-com-chainCronos(CRO)$0.061085-8.55%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.01%
  • MemeCoreMemeCore(M)$1.21-7.75%
  • BitwayBitway(BTW)$1.0116.07%
  • tether-goldTether Gold(XAUT)$4,286.11-1.65%
  • okbOKB(OKB)$117.76-3.89%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • Ripple USDRipple USD(RLUSD)$1.00-0.01%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.02%
  • mantleMantle(MNT)$0.65-2.15%
  • aaveAave(AAVE)$138.37-4.23%
  • EthenaEthena(ENA)$0.205855-1.20%
  • OndoOndo(ONDO)$0.410876-6.22%
  • polkadotPolkadot(DOT)$1.10-7.82%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

ByteDance Research Releases DAPO: A Fully Open-Sourced LLM Reinforcement Learning System at Scale

March 18, 2025
in AI & Technology
Reading Time: 7 mins read
A A
ByteDance Research Releases DAPO: A Fully Open-Sourced LLM Reinforcement Learning System at Scale
ShareShareShareShareShare

Reinforcement learning (RL) has become central to advancing Large Language Models (LLMs), empowering them with improved reasoning capabilities necessary for complex tasks. However, the research community faces considerable challenges in reproducing state-of-the-art RL techniques due to incomplete disclosure of key training details by major industry players. This opacity has limited the progress of broader scientific efforts and collaborative research.

Researchers from ByteDance, Tsinghua University, and the University of Hong Kong recently introduced DAPO (Dynamic Sampling Policy Optimization), an open-source large-scale reinforcement learning system designed for enhancing the reasoning abilities of Large Language Models. The DAPO system seeks to bridge the gap in reproducibility by openly sharing all algorithmic details, training procedures, and datasets. Built upon the verl framework, DAPO includes training codes and a thoroughly prepared dataset called DAPO-Math-17K, specifically designed for mathematical reasoning tasks.

YOU MAY ALSO LIKE

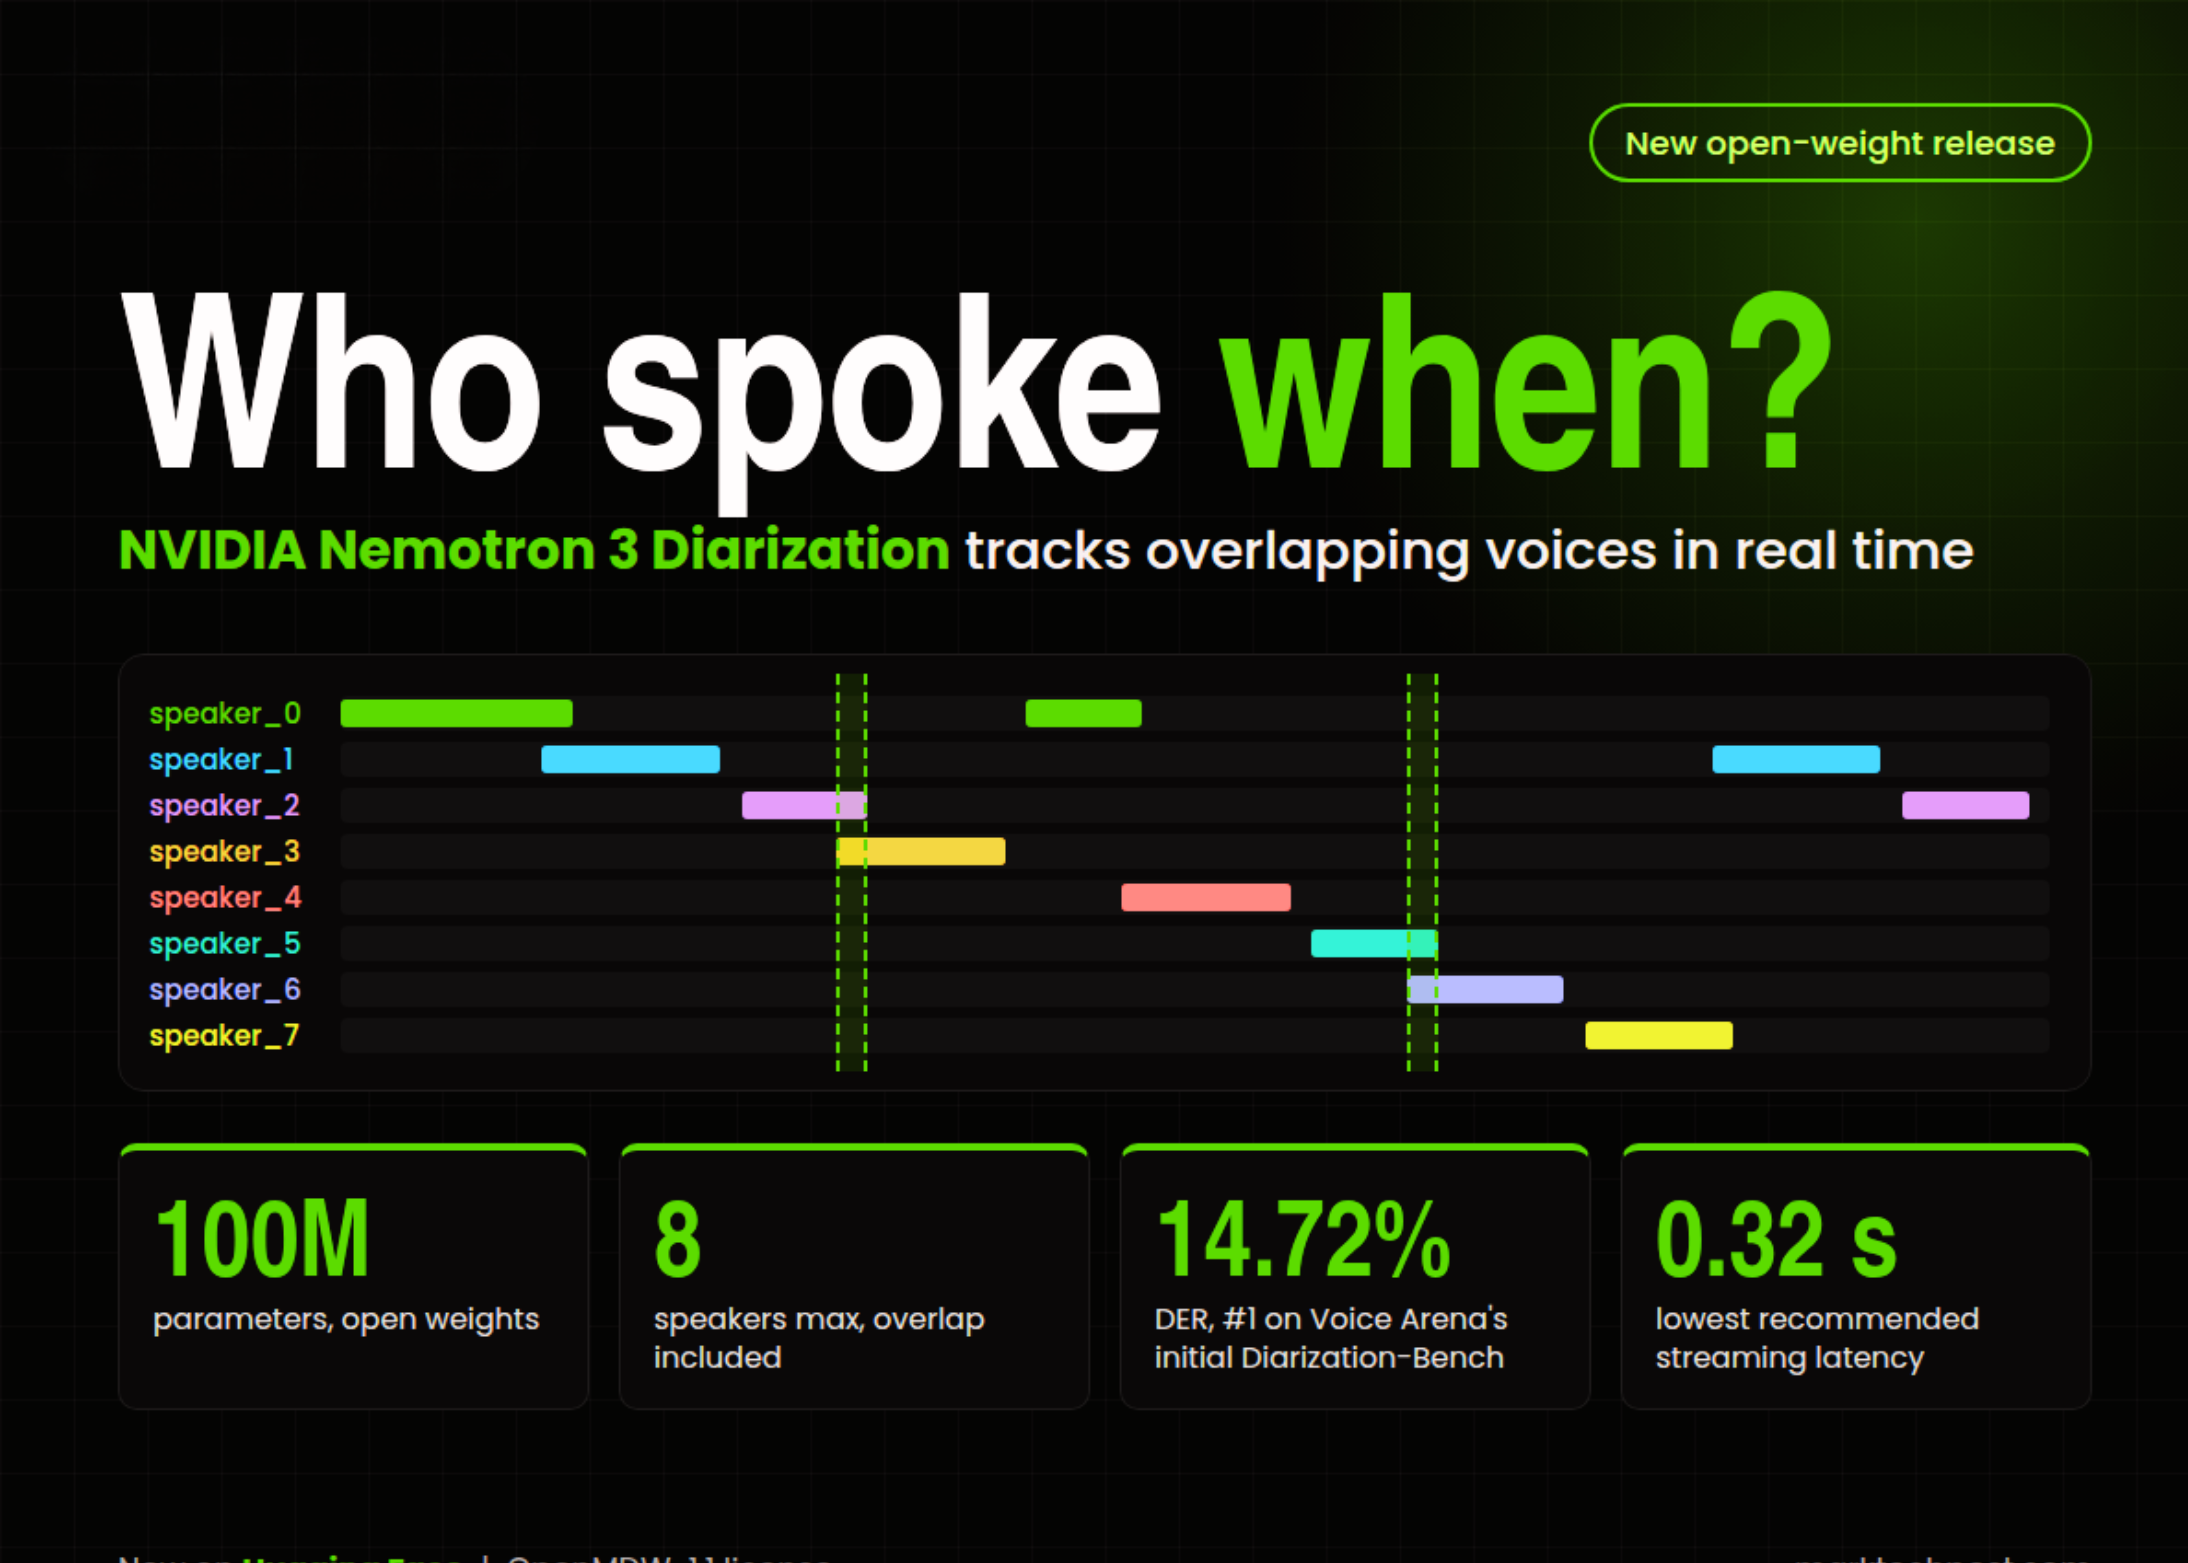
NVIDIA Releases Nemotron 3 Diarization: A 100M-Parameter Open-Weight Model That Tracks 8 Speakers in Real Time

Disney+ And Hulu Are Getting Even More Expensive (Again)

DAPO’s technical foundation includes four core innovations aimed at resolving key challenges in reinforcement learning. The first, “Clip-Higher,” addresses the issue of entropy collapse, a situation where models prematurely settle into limited exploration patterns. By carefully managing the clipping ratio in policy updates, this technique encourages greater diversity in model outputs. “Dynamic Sampling” counters inefficiencies in training by dynamically filtering samples based on their usefulness, thus ensuring a more consistent gradient signal. The “Token-level Policy Gradient Loss” offers a refined loss calculation method, emphasizing token-level rather than sample-level adjustments to better accommodate varying lengths of reasoning sequences. Lastly, “Overlong Reward Shaping” introduces a controlled penalty for excessively long responses, gently guiding models toward concise and efficient reasoning.

In practical experimentation, DAPO has demonstrated significant improvements. Evaluations on the American Invitational Mathematics Examination (AIME) 2024 benchmark show that DAPO-trained models achieved a score of 50 points using the Qwen2.5-32B base model, improving on previous methods such as DeepSeek-R1-Zero-Qwen-32B, which achieved 47 points. Notably, DAPO attained this improvement with approximately half the training steps, underscoring the efficiency of the proposed methods. A systematic analysis revealed incremental enhancements from each introduced technique, moving from a baseline of 30 points (using GRPO alone) up to 50 points with the full DAPO methodology.

Beyond quantitative results, DAPO’s training dynamics provided insights into the model’s evolving reasoning patterns. Initially, the models showed little reflective behavior, often proceeding linearly through tasks without reconsideration of previous steps. However, with ongoing training, the models progressively exhibited more reflective behaviors, demonstrating a form of iterative self-review. This shift highlights the capability of reinforcement learning not only to enhance existing reasoning pathways but also to cultivate entirely new cognitive strategies over time.

In conclusion, the open-sourcing of DAPO represents a meaningful contribution to the reinforcement learning community, removing barriers previously created by inaccessible methodologies. By clearly documenting and providing comprehensive access to the system’s techniques, dataset, and code, this collaborative initiative invites further research and innovation. The combined efforts of ByteDance, Tsinghua University, and the University of Hong Kong showcase the potential of transparent and cooperative research to advance the collective understanding and practical capabilities of large-scale reinforcement learning systems.


Check out the Paper and Project Page. All credit for this research goes to the researchers of this project. Also, feel free to follow us on Twitter and don’t forget to join our 80k+ ML SubReddit.


Asif Razzaq is the CEO of Marktechpost Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.

Credit: Source link

ShareTweetSendSharePin

Related Posts

NVIDIA Releases Nemotron 3 Diarization: A 100M-Parameter Open-Weight Model That Tracks 8 Speakers in Real Time
AI & Technology

NVIDIA Releases Nemotron 3 Diarization: A 100M-Parameter Open-Weight Model That Tracks 8 Speakers in Real Time

September 23, 2026
Disney+ And Hulu Are Getting Even More Expensive (Again)
AI & Technology

Disney+ And Hulu Are Getting Even More Expensive (Again)

September 23, 2026
Logitech’s Yeti 2 Brings The 17-Year-Old USB Mic Into The Modern Age
AI & Technology

Logitech’s Yeti 2 Brings The 17-Year-Old USB Mic Into The Modern Age

September 23, 2026
Never Use ChatGPT For These Five Tasks
AI & Technology

Never Use ChatGPT For These Five Tasks

September 23, 2026
Next Post
Zoom to Add Agentic Capabilities

Zoom to Add Agentic Capabilities

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Live Updates: Mamdani and Trump Discuss Immigration and Affordability at Gracie Mansion – The New York Times

Live Updates: Mamdani and Trump Discuss Immigration and Affordability at Gracie Mansion – The New York Times

September 21, 2026
My Brother And I Don’t Speak – Should I Help His Kids?

My Brother And I Don’t Speak – Should I Help His Kids?

September 19, 2026
Clancy’s lawyer says he would be ready for a retrial ‘next week’

Clancy’s lawyer says he would be ready for a retrial ‘next week’

September 19, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!