
We begin this tutorial to demonstrate how to harness TPOT to automate and optimize machine learning pipelines practically. By working directly in Google Colab, we ensure the setup is lightweight, reproducible, and accessible. We walk through loading data, defining a custom scorer, tailoring the search space with advanced models like XGBoost, and setting up a cross-validation strategy. As we proceed, we explore how evolutionary algorithms in TPOT search for high-performing pipelines, providing us transparency through Pareto fronts and checkpoints. Check out the FULL CODES here.
!pip -q install tpot==0.12.2 xgboost==2.0.3 scikit-learn==1.4.2 graphviz==0.20.3


import os, json, math, time, random, numpy as np, pandas as pd
from sklearn.datasets import load_breast_cancer
from sklearn.model_selection import train_test_split, StratifiedKFold
from sklearn.preprocessing import StandardScaler
from sklearn.metrics import make_scorer, f1_score, classification_report, confusion_matrix
from sklearn.pipeline import Pipeline
from tpot import TPOTClassifier
from sklearn.linear_model import LogisticRegression
from sklearn.naive_bayes import GaussianNB
from sklearn.tree import DecisionTreeClassifier
from sklearn.ensemble import RandomForestClassifier, ExtraTreesClassifier, GradientBoostingClassifier
from xgboost import XGBClassifier


SEED = 7
random.seed(SEED); np.random.seed(SEED); os.environ["PYTHONHASHSEED"]=str(SEED)
We begin by installing the libraries and importing all the essential modules that support data handling, model building, and pipeline optimization. We set a fixed random seed to ensure our results remain reproducible every time we run the notebook. Check out the FULL CODES here.
X, y = load_breast_cancer(return_X_y=True, as_frame=True)
X_tr, X_te, y_tr, y_te = train_test_split(X, y, test_size=0.3, stratify=y, random_state=SEED)


scaler = StandardScaler().fit(X_tr)
X_tr_s, X_te_s = scaler.transform(X_tr), scaler.transform(X_te)


def f1_cost_sensitive(y_true, y_pred):
   return f1_score(y_true, y_pred, average="binary", pos_label=1)
cost_f1 = make_scorer(f1_cost_sensitive, greater_is_better=True)
Here, we load the breast cancer dataset and split it into training and testing sets while preserving class balance. We standardize the features for stability and then define a custom F1-based scorer, allowing us to evaluate pipelines with a focus on effectively capturing positive cases. Check out the FULL CODES here.
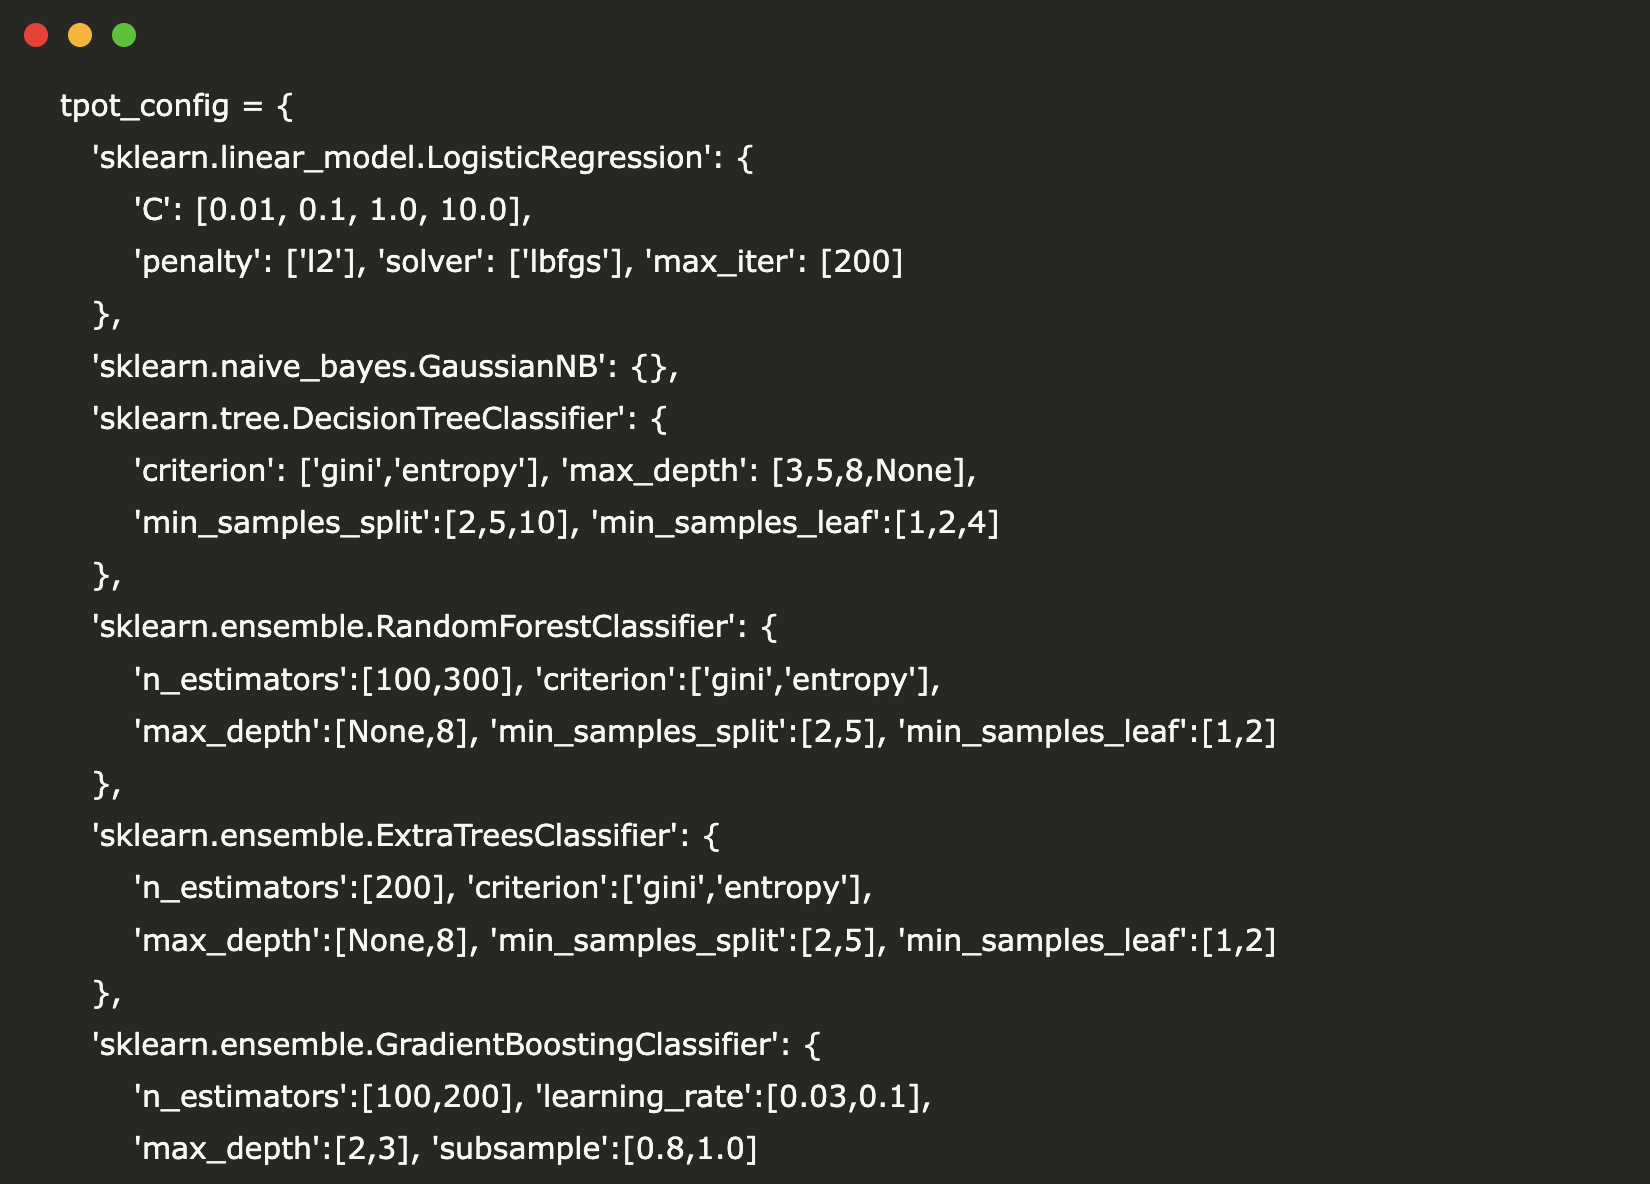
tpot_config = {
   'sklearn.linear_model.LogisticRegression': {
       'C': [0.01, 0.1, 1.0, 10.0],
       'penalty': ['l2'], 'solver': ['lbfgs'], 'max_iter': [200]
   },
   'sklearn.naive_bayes.GaussianNB': {},
   'sklearn.tree.DecisionTreeClassifier': {
       'criterion': ['gini','entropy'], 'max_depth': [3,5,8,None],
       'min_samples_split':[2,5,10], 'min_samples_leaf':[1,2,4]
   },
   'sklearn.ensemble.RandomForestClassifier': {
       'n_estimators':[100,300], 'criterion':['gini','entropy'],
       'max_depth':[None,8], 'min_samples_split':[2,5], 'min_samples_leaf':[1,2]
   },
   'sklearn.ensemble.ExtraTreesClassifier': {
       'n_estimators':[200], 'criterion':['gini','entropy'],
       'max_depth':[None,8], 'min_samples_split':[2,5], 'min_samples_leaf':[1,2]
   },
   'sklearn.ensemble.GradientBoostingClassifier': {
       'n_estimators':[100,200], 'learning_rate':[0.03,0.1],
       'max_depth':[2,3], 'subsample':[0.8,1.0]
   },
   'xgboost.XGBClassifier': {
       'n_estimators':[200,400], 'max_depth':[3,5], 'learning_rate':[0.05,0.1],
       'subsample':[0.8,1.0], 'colsample_bytree':[0.8,1.0],
       'reg_lambda':[1.0,2.0], 'min_child_weight':[1,3],
       'n_jobs':[0], 'tree_method':['hist'], 'eval_metric':['logloss'],
       'gamma':[0,1]
   }
}


cv = StratifiedKFold(n_splits=5, shuffle=True, random_state=SEED)
We define a custom TPOT configuration that combines linear models, tree-based learners, ensembles, and XGBoost, utilizing carefully chosen hyperparameters. We also established a stratified 5-fold cross-validation strategy, ensuring that every candidate pipeline is tested fairly across balanced splits of the dataset. Check out the FULL CODES here.
t0 = time.time()
tpot = TPOTClassifier(
   generations=5,
   population_size=40,
   offspring_size=40,
   scoring=cost_f1,
   cv=cv,
   subsample=0.8,
   n_jobs=-1,
   config_dict=tpot_config,
   verbosity=2,
   random_state=SEED,
   max_time_mins=10,
   early_stop=3,
   periodic_checkpoint_folder="tpot_ckpt",
   warm_start=False
)
tpot.fit(X_tr_s, y_tr)
print(f"\n⏱️ First search took {time.time()-t0:.1f}s")


def pareto_table(tpot_obj, k=5):
   rows=[]
   for ind, meta in tpot_obj.pareto_front_fitted_pipelines_.items():
       rows.append({
           "pipeline": ind, "cv_score": meta['internal_cv_score'],
           "size": len(str(meta['pipeline'])),
       })
   df = pd.DataFrame(rows).sort_values("cv_score", ascending=False).head(k)
   return df.reset_index(drop=True)


pareto_df = pareto_table(tpot, k=5)
print("\nTop Pareto pipelines (cv):\n", pareto_df)


def eval_pipeline(pipeline, X_te, y_te, name):
   y_hat = pipeline.predict(X_te)
   f1 = f1_score(y_te, y_hat)
   print(f"\n[{name}] F1(test) = {f1:.4f}")
   print(classification_report(y_te, y_hat, digits=3))


print("\nEvaluating top pipelines on test:")
for i, (ind, meta) in enumerate(sorted(
       tpot.pareto_front_fitted_pipelines_.items(),
       key=lambda kv: kv[1]['internal_cv_score'], reverse=True)[:3], 1):
   eval_pipeline(meta['pipeline'], X_te_s, y_te, name=f"Pareto#{i}")
We launch an evolutionary search with TPOT, cap the runtime for practicality, and checkpoint progress, allowing us to reproducibly hunt for strong pipelines. We then inspect the Pareto front to identify the top trade-offs, convert it into a compact table, and select leaders based on the cross-validation score. Finally, we evaluate the best candidates on the held-out test set to confirm real-world performance with F1 and a full classification report. Check out the FULL CODES here.
print("\n🔁 Warm-start for extra refinement...")
t1 = time.time()
tpot2 = TPOTClassifier(
   generations=3, population_size=40, offspring_size=40,
   scoring=cost_f1, cv=cv, subsample=0.8, n_jobs=-1,
   config_dict=tpot_config, verbosity=2, random_state=SEED,
   warm_start=True, periodic_checkpoint_folder="tpot_ckpt"
)
try:
   tpot2._population = tpot._population
   tpot2._pareto_front = tpot._pareto_front
except Exception:
   pass
tpot2.fit(X_tr_s, y_tr)
print(f"⏱️ Warm-start extra search took {time.time()-t1:.1f}s")


best_model = tpot2.fitted_pipeline_ if hasattr(tpot2, "fitted_pipeline_") else tpot.fitted_pipeline_
eval_pipeline(best_model, X_te_s, y_te, name="BestAfterWarmStart")


export_path = "tpot_best_pipeline.py"
(tpot2 if hasattr(tpot2, "fitted_pipeline_") else tpot).export(export_path)
print(f"\n📦 Exported best pipeline to: {export_path}")


from importlib import util as _util
spec = _util.spec_from_file_location("tpot_best", export_path)
tbest = _util.module_from_spec(spec); spec.loader.exec_module(tbest)
reloaded_clf = tbest.exported_pipeline_
pipe = Pipeline([("scaler", scaler), ("model", reloaded_clf)])
pipe.fit(X_tr, y_tr)
eval_pipeline(pipe, X_te, y_te, name="ReloadedExportedPipeline")


report = {
   "dataset": "sklearn breast_cancer",
   "train_size": int(X_tr.shape[0]), "test_size": int(X_te.shape[0]),
   "cv": "StratifiedKFold(5)",
   "scorer": "custom F1 (binary)",
   "search": {"gen_1": 5, "gen_2_warm": 3, "pop": 40, "subsample": 0.8},
   "exported_pipeline_first_120_chars": str(reloaded_clf)[:120]+"...",
}
print("\n🧾 Model Card:\n", json.dumps(report, indent=2))
We continue the search with a warm start, reusing the learned warm start to refine candidates and select the best performer on our test set. We export the winning pipeline, reload it alongside our scaler to mimic deployment, and verify its results. Finally, we generate a compact model card to document the dataset, search settings, and the summary of the exported pipeline for reproducibility.
In conclusion, we see how TPOT allows us to move beyond trial-and-error model selection and instead rely on automated, reproducible, and explainable optimization. We export the best pipeline, validate it on unseen data, and even reload it for deployment-style use, confirming that the workflow is not just experimental but production-ready. By combining reproducibility, flexibility, and interpretability, we end with a robust framework that we can confidently apply to more complex datasets and real-world problems.
Check out the FULL CODES here. Feel free to check out our GitHub Page for Tutorials, Codes and Notebooks. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter.
Asif Razzaq is the CEO of Marktechpost Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.
Credit: Source link