
• bitcoinBitcoin(BTC)$80,638.006.22%
  • ethereumEthereum(ETH)$2,432.248.83%
  • tetherTether(USDT)$1.000.04%
  • binancecoinBNB(BNB)$716.754.76%
  • rippleXRP(XRP)$1.314.63%
  • usd-coinUSDC(USDC)$1.000.02%
  • solanaSolana(SOL)$96.696.83%
  • tronTRON(TRX)$0.319258-0.74%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.051.53%
  • zcashZcash(ZEC)$1,323.2713.10%
  • HyperliquidHyperliquid(HYPE)$84.262.90%
  • dogecoinDogecoin(DOGE)$0.0772746.09%
  • moneroMonero(XMR)$636.431.29%
  • USDSUSDS(USDS)$1.000.02%
  • whitebitWhiteBIT Coin(WBT)$78.066.93%
  • chainlinkChainlink(LINK)$11.527.65%
  • leo-tokenLEO Token(LEO)$9.350.51%
  • cardanoCardano(ADA)$0.1990677.98%
  • stellarStellar(XLM)$0.1687896.78%
  • bitcoin-cashBitcoin Cash(BCH)$281.955.58%
  • nearNEAR Protocol(NEAR)$4.069.00%
  • uniswapUniswap(UNI)$7.729.93%
  • daiDai(DAI)$1.000.03%
  • Ethena USDeEthena USDe(USDE)$1.000.06%
  • litecoinLitecoin(LTC)$56.407.36%
  • RainRain(RAIN)$0.005986-6.46%
  • CantonCanton(CC)$0.1015716.43%
  • avalanche-2Avalanche(AVAX)$8.845.86%
  • suiSui(SUI)$0.938.12%
  • USD1USD1(USD1)$1.000.06%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.182.40%
  • tether-goldTether Gold(XAUT)$4,111.894.76%
  • hedera-hashgraphHedera(HBAR)$0.0734677.95%
  • quant-networkQuant(QNT)$205.529.39%
  • shiba-inuShiba Inu(SHIB)$0.0000055.60%
  • Global DollarGlobal Dollar(USDG)$1.000.02%
  • BittensorBittensor(TAO)$237.528.20%
  • paypal-usdPayPal USD(PYUSD)$1.000.02%
  • crypto-com-chainCronos(CRO)$0.0522786.24%
  • Ripple USDRipple USD(RLUSD)$1.000.02%
  • EthenaEthena(ENA)$0.1831578.98%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.15-0.09%
  • okbOKB(OKB)$112.505.92%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • pepePepe(PEPE)$0.0000056.29%
  • aaveAave(AAVE)$132.876.98%
  • OndoOndo(ONDO)$0.4143629.42%
  • Pump.funPump.fun(PUMP)$0.0043696.21%
  • MemeCoreMemeCore(M)$0.841.69%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Alibaba Qwen Team Just Released FP8 Builds of Qwen3-Next-80B-A3B (Instruct & Thinking), Bringing 80B/3B-Active Hybrid-MoE to Commodity GPUs

September 22, 2025
in AI & Technology
Reading Time: 8 mins read
A A
Alibaba Qwen Team Just Released FP8 Builds of Qwen3-Next-80B-A3B (Instruct & Thinking), Bringing 80B/3B-Active Hybrid-MoE to Commodity GPUs
ShareShareShareShareShare

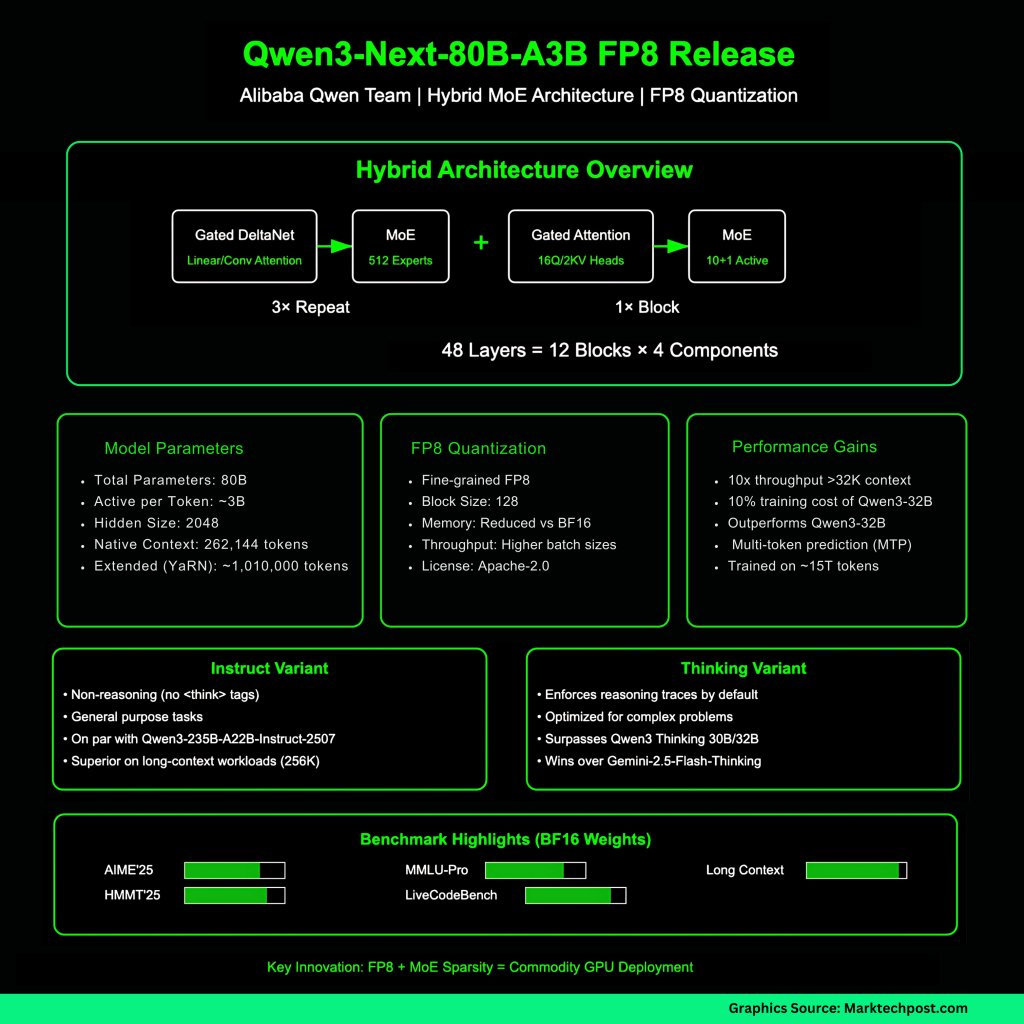
Alibaba’s Qwen team has just released FP8-quantized checkpoints for its new Qwen3-Next-80B-A3B models in two post-training variants—Instruct and Thinking—aimed at high-throughput inference with ultra-long context and MoE efficiency. The FP8 repos mirror the BF16 releases but package “fine-grained FP8” weights (block size 128) and deployment notes for sglang and vLLM nightly builds. Benchmarks in the cards remain those of the original BF16 models; FP8 is provided “for convenience and performance,” not as a separate evaluation run.

What’s in the A3B stack

Qwen3-Next-80B-A3B is a hybrid architecture combining Gated DeltaNet (a linear/conv-style attention surrogate) with Gated Attention, interleaved with an ultra-sparse Mixture-of-Experts (MoE). The 80B total parameter budget activates ~3B params per token via 512 experts (10 routed + 1 shared). The layout is specified as 48 layers arranged into 12 blocks: 3×(Gated DeltaNet → MoE) followed by 1×(Gated Attention → MoE). Native context is 262,144 tokens, validated up to ~1,010,000 tokens using RoPE scaling (YaRN). Hidden size is 2048; attention uses 16 Q heads and 2 KV heads at head dim 256; DeltaNet uses 32 V and 16 QK linear heads at head dim 128.

YOU MAY ALSO LIKE

Cat Wu to Lead Product Management for OpenAI’s Core Products – Unite.AI

Snap Has More Than 30 Million Paid Subscribers Across Snapchat+ And Other Plans

Qwen team reports the 80B-A3B base model outperforms Qwen3-32B on downstream tasks at ~10% of its training cost and delivers ~10× inference throughput beyond 32K context—driven by low activation in MoE and multi-token prediction (MTP). The Instruct variant is non-reasoning (no <think> tags), whereas the Thinking variant enforces reasoning traces by default and is optimized for complex problems.
FP8 releases: what actually changed

The FP8 model cards state the quantization is “fine-grained fp8” with block size 128. Deployment differs slightly from BF16: both sglang and vLLM require current main/nightly builds, with example commands provided for 256K context and optional MTP. The Thinking FP8 card also recommends a reasoning parser flag (e.g., --reasoning-parser deepseek-r1 in sglang, deepseek_r1 in vLLM). These releases retain Apache-2.0 licensing.

Benchmarks (reported on BF16 weights)

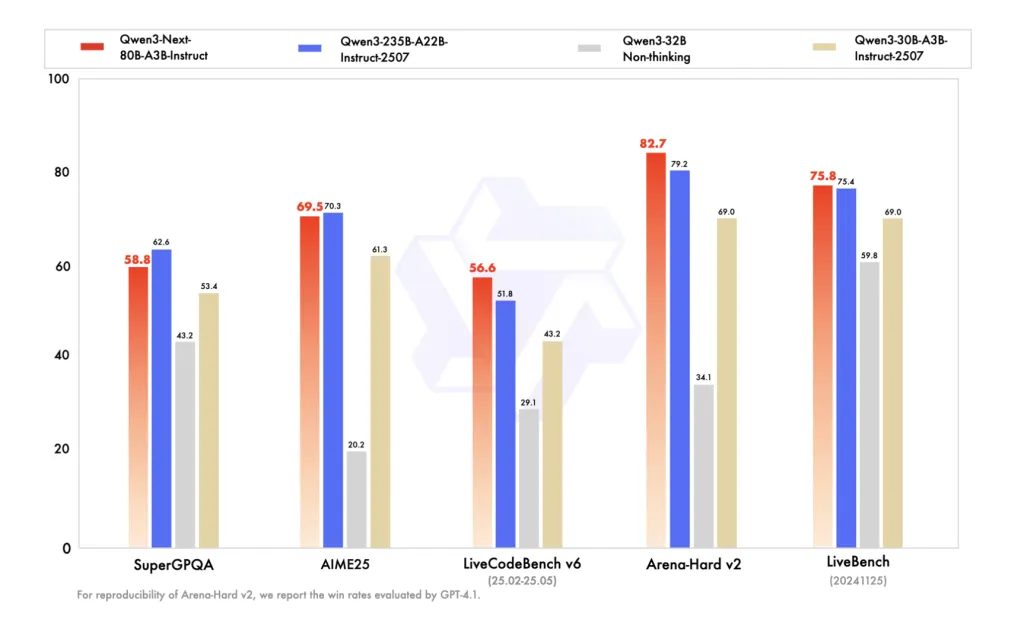
The Instruct FP8 card reproduces Qwen’s BF16 comparison table, putting Qwen3-Next-80B-A3B-Instruct on par with Qwen3-235B-A22B-Instruct-2507 on several knowledge/reasoning/coding benchmarks, and ahead on long-context workloads (up to 256K). The Thinking FP8 card lists AIME’25, HMMT’25, MMLU-Pro/Redux, and LiveCodeBench v6, where Qwen3-Next-80B-A3B-Thinking surpasses earlier Qwen3 Thinking releases (30B A3B-2507, 32B) and claims wins over Gemini-2.5-Flash-Thinking on multiple benchmarks.
Training and post-training signals

The series is trained on ~15T tokens before post-training. Qwen highlights stability additions (zero-centered, weight-decayed layer norm, etc.) and uses GSPO in RL post-training for the Thinking model to handle the hybrid attention + high-sparsity MoE combination. MTP is used to speed inference and improve pretraining signal.

Why FP8 matters?

On modern accelerators, FP8 activations/weights reduce memory bandwidth pressure and resident footprint versus BF16, allowing larger batch sizes or longer sequences at similar latency. Because A3B routes only ~3B parameters per token, the combination of FP8 + MoE sparsity compounds throughput gains in long-context regimes, particularly when paired with speculative decoding via MTP as exposed in the serving flags. That said, quantization interacts with routing and attention variants; real-world acceptance rates for speculative decoding and end-task accuracy can vary with engine and kernel implementations—hence Qwen’s guidance to use current sglang/vLLM and to tune speculative settings.

Summary

Qwen’s FP8 releases make the 80B/3B-active A3B stack practical to serve at 256K context on mainstream engines, preserving the hybrid-MoE design and MTP path for high throughput. The model cards keep benchmarks from BF16, so teams should validate FP8 accuracy and latency on their own stacks, especially with reasoning parsers and speculative settings. Net outcome: lower memory bandwidth and improved concurrency without architectural regressions, positioned for long-context production workloads.


Check out the Qwen3-Next-80B-A3B models in two post-training variants—Instruct and Thinking. Feel free to check out our GitHub Page for Tutorials, Codes and Notebooks. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter.

Asif Razzaq is the CEO of Marktechpost Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.

🔥[Recommended Read] NVIDIA AI Open-Sources ViPE (Video Pose Engine): A Powerful and Versatile 3D Video Annotation Tool for Spatial AI

Credit: Source link

ShareTweetSendSharePin

Related Posts

Cat Wu to Lead Product Management for OpenAI’s Core Products – Unite.AI
AI & Technology

Cat Wu to Lead Product Management for OpenAI’s Core Products – Unite.AI

November 5, 2026
Snap Has More Than 30 Million Paid Subscribers Across Snapchat+ And Other Plans
AI & Technology

Snap Has More Than 30 Million Paid Subscribers Across Snapchat+ And Other Plans

November 4, 2026
Atmospheric AI Secures M Seed for Procurement Modeling Push – Unite.AI
AI & Technology

Atmospheric AI Secures $10M Seed for Procurement Modeling Push – Unite.AI

November 4, 2026
Perplexity Adds Live Web Grounding to Its Decisions API – Unite.AI
AI & Technology

Perplexity Adds Live Web Grounding to Its Decisions API – Unite.AI

November 4, 2026
Next Post
Congress works to end the ‘wounded veterans tax’

Congress works to end the 'wounded veterans tax'

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Cornell Students Call On President to Resign; Inside Israel and Gaza for Oct. 7 Anniversary – Oct. 6

Cornell Students Call On President to Resign; Inside Israel and Gaza for Oct. 7 Anniversary – Oct. 6

October 30, 2026
Project Suncatcher’s Orbiting TPU Delivers Its First AI-Generated Haiku – Unite.AI

Project Suncatcher’s Orbiting TPU Delivers Its First AI-Generated Haiku – Unite.AI

October 30, 2026
Traversal Raises 0M Series B at B Valuation to Expand AI SRE – Unite.AI

Traversal Raises $120M Series B at $1B Valuation to Expand AI SRE – Unite.AI

November 3, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!