• bitcoinBitcoin(BTC)$77,462.000.51%
  • ethereumEthereum(ETH)$2,247.531.32%
  • tetherTether(USDT)$1.000.07%
  • binancecoinBNB(BNB)$708.251.91%
  • rippleXRP(XRP)$1.262.94%
  • usd-coinUSDC(USDC)$1.000.07%
  • solanaSolana(SOL)$96.692.14%
  • tronTRON(TRX)$0.322897-10.16%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.03-0.25%
  • zcashZcash(ZEC)$1,279.273.57%
  • HyperliquidHyperliquid(HYPE)$89.44-1.95%
  • dogecoinDogecoin(DOGE)$0.0762042.61%
  • moneroMonero(XMR)$594.66-4.26%
  • USDSUSDS(USDS)$1.000.44%
  • chainlinkChainlink(LINK)$11.6610.75%
  • whitebitWhiteBIT Coin(WBT)$74.370.75%
  • leo-tokenLEO Token(LEO)$9.42-0.25%
  • cardanoCardano(ADA)$0.1962624.95%
  • stellarStellar(XLM)$0.1700625.47%
  • bitcoin-cashBitcoin Cash(BCH)$295.068.90%
  • nearNEAR Protocol(NEAR)$4.358.54%
  • daiDai(DAI)$1.000.05%
  • Ethena USDeEthena USDe(USDE)$1.000.11%
  • RainRain(RAIN)$0.006289-3.84%
  • uniswapUniswap(UNI)$7.1410.18%
  • litecoinLitecoin(LTC)$55.732.54%
  • CantonCanton(CC)$0.0986136.46%
  • USD1USD1(USD1)$1.000.10%
  • avalanche-2Avalanche(AVAX)$8.604.70%
  • suiSui(SUI)$0.916.52%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.182.27%
  • hedera-hashgraphHedera(HBAR)$0.0729796.03%
  • tether-goldTether Gold(XAUT)$3,880.27-2.91%
  • Global DollarGlobal Dollar(USDG)$1.000.04%
  • paypal-usdPayPal USD(PYUSD)$1.000.34%
  • shiba-inuShiba Inu(SHIB)$0.0000054.97%
  • quant-networkQuant(QNT)$192.336.67%
  • BittensorBittensor(TAO)$238.753.94%
  • crypto-com-chainCronos(CRO)$0.0519392.63%
  • EthenaEthena(ENA)$0.1904189.66%
  • Ripple USDRipple USD(RLUSD)$1.000.11%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.15-0.06%
  • Circle USYCCircle USYC(USYC)$1.140.03%
  • okbOKB(OKB)$111.631.99%
  • MemeCoreMemeCore(M)$0.95-5.64%
  • pepePepe(PEPE)$0.0000058.40%
  • OndoOndo(ONDO)$0.41957912.39%
  • aaveAave(AAVE)$131.3110.47%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Pump.funPump.fun(PUMP)$0.0041737.49%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Advancing Medical Reasoning with Reinforcement Learning from Verifiable Rewards (RLVR): Insights from MED-RLVR

March 30, 2025
in AI & Technology
Reading Time: 4 mins read
A A
Advancing Medical Reasoning with Reinforcement Learning from Verifiable Rewards (RLVR): Insights from MED-RLVR
ShareShareShareShareShare

Reinforcement Learning from Verifiable Rewards (RLVR) has recently emerged as a promising method for enhancing reasoning abilities in language models without direct supervision. This approach has shown notable success in mathematics and coding, where reasoning naturally aligns with structured problem-solving. While studies have demonstrated that RLVR alone can lead to self-evolved reasoning, research has largely been limited to these technical fields. Efforts to extend RLVR have explored synthetic datasets, such as those involving sequential tasks and object counting, indicating potential but also highlighting the challenges of adapting this method to different domains.

Expanding RLVR to broader areas remains an open challenge, particularly in tasks like multiple-choice question answering (MCQA), which provides structured, verifiable labels across diverse subjects, including medicine. However, unlike math and coding, which involve complex reasoning with an open-ended answer space, MCQA tasks typically have predefined answer choices, making it uncertain whether RLVR’s benefits translate effectively. This limitation is especially relevant in medical reasoning tasks, where models must navigate intricate clinical knowledge to produce accurate responses, an area that has proven difficult for existing AI systems.

YOU MAY ALSO LIKE

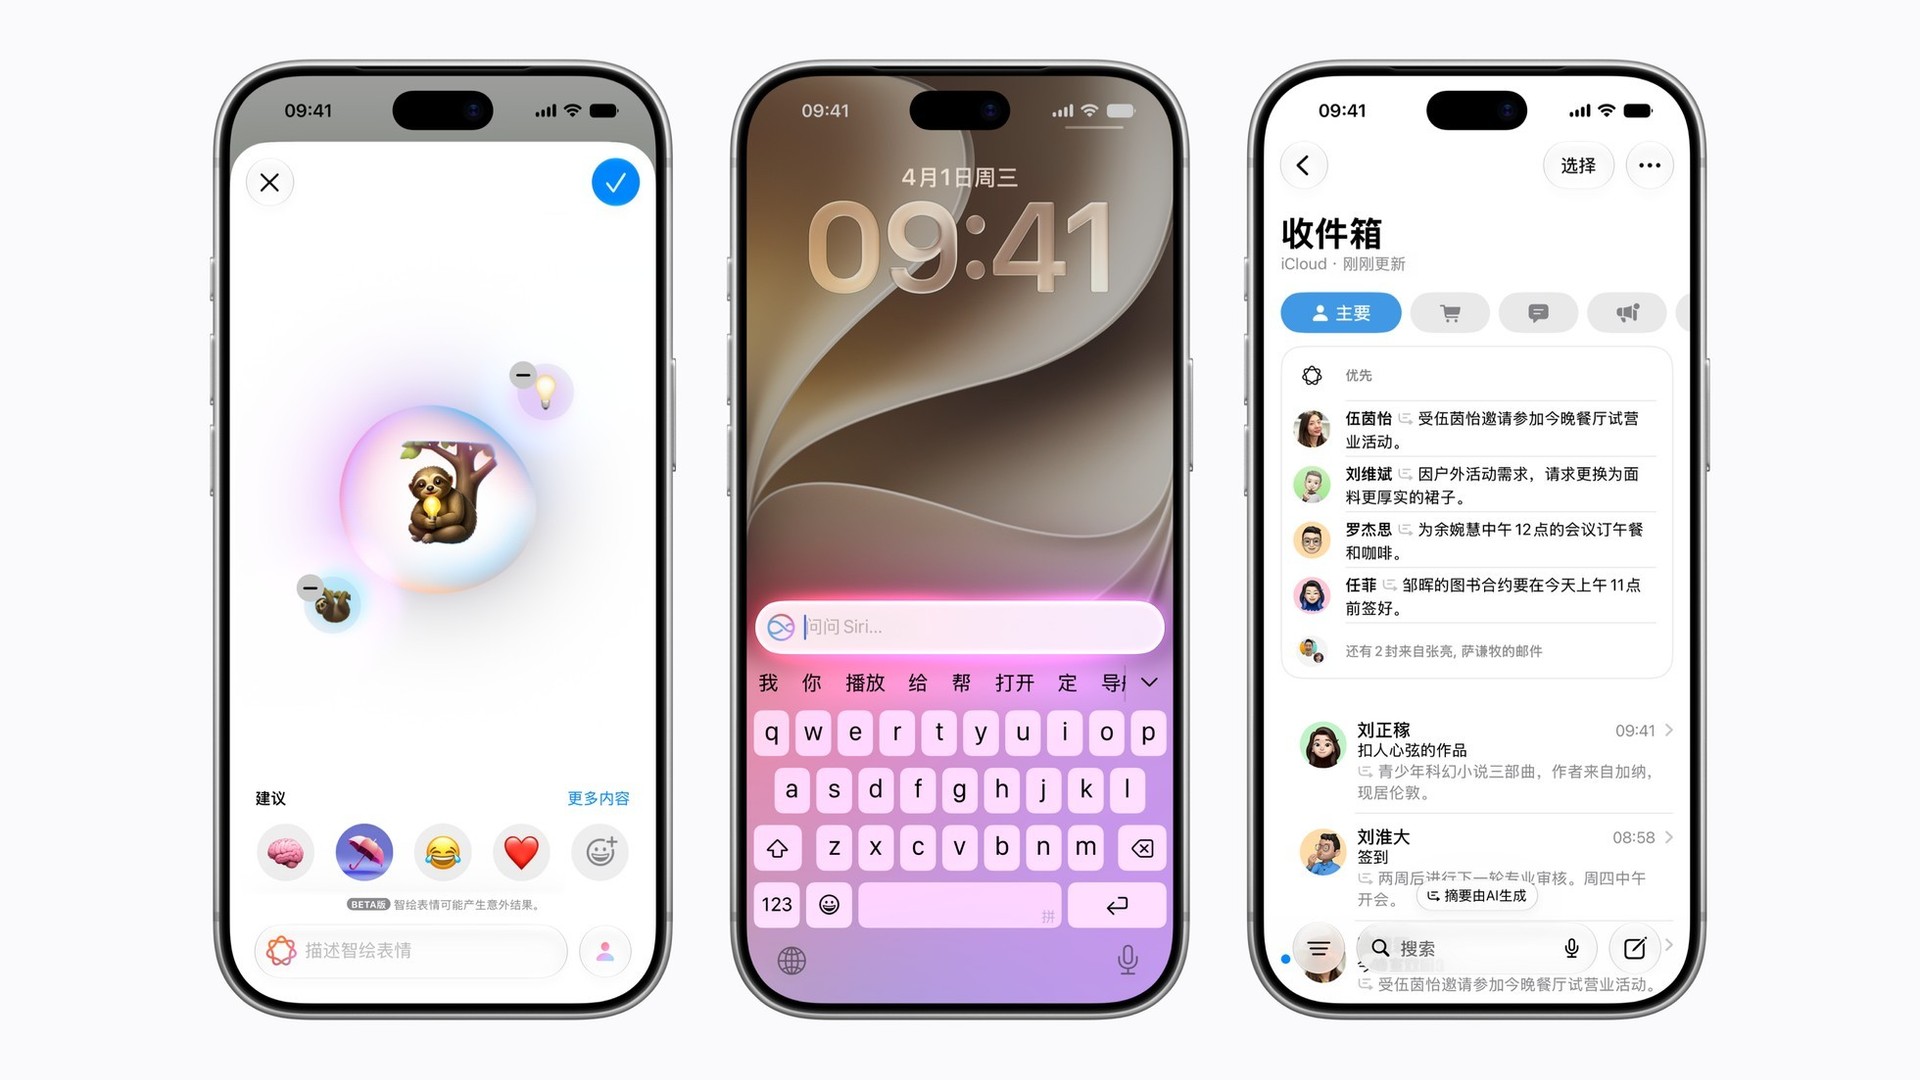
Apple Brings First Apple Intelligence Features to China in iOS 27.3 – Unite.AI

Powerlattice Raises $86M in Equity Offering, SEC Filing Shows – Unite.AI

Researchers from Microsoft Research investigate whether medical reasoning can emerge through RLVR. They introduce MED-RLVR, leveraging medical MCQA data to assess RLVR’s effectiveness in the medical domain. Their findings show that RLVR extends beyond math and coding, achieving performance comparable to supervised fine-tuning (SFT) in in-distribution tasks while significantly improving out-of-distribution generalization by eight percentage points. Analyzing training dynamics, they observe that reasoning capabilities emerge in a 3B-parameter base model without explicit supervision, highlighting RLVR’s potential for advancing reasoning in knowledge-intensive fields like medicine.

RL optimizes decision-making by training an agent to maximize rewards through interactions with an environment. It has been effectively applied to language models to align outputs with human preferences and, more recently, to elicit reasoning without explicit supervision. This study employs Proximal Policy Optimization (PPO) to train a policy model, incorporating a clipped objective function to stabilize training. Using a rule-based reward function, MED-RLVR assigns rewards based on output correctness and format validity. Without additional supervision, the model demonstrates emergent medical reasoning, similar to mathematical reasoning in prior RLVR studies, highlighting RLVR’s potential beyond structured domains.

The MedQA-USMLE dataset, which includes multi-choice medical exam questions, is used to train MED-RLVR. Unlike the standard four-option version, this dataset presents a greater challenge by offering more answer choices. Training is based on the Qwen2.5-3B model using OpenRLHF for reinforcement learning. Compared to SFT, MED-RLVR demonstrates superior generalization, particularly on the MMLU-Pro-Health dataset. Analysis reveals six stages of reasoning evolution: format failures, verbose outputs, reward hacking, and reintegrated reasoning. Unlike math or coding tasks, no self-validation behaviors (“aha-moments”) were observed, suggesting potential improvements through penalizing short reasoning chains or fine-tuning with longer CoTs.

In conclusion, the study focuses on MCQA in medicine, providing a controlled setting for evaluation. However, MCQA does not fully capture the complexity of real-world tasks like open-text answering, report generation, or medical dialogues. Additionally, the unimodal approach limits the model’s ability to integrate multimodal data, which is crucial for diagnostic applications. Future work should address these limitations. MED-RLVR, based on reinforcement learning with verifiable rewards, matches SFT on in-distribution tasks and improves out-of-distribution generalization. While medical reasoning emerges without explicit supervision, challenges like reward hacking persist, highlighting the need for further exploration of complex reasoning and multimodal integration.


Check out the Paper. All credit for this research goes to the researchers of this project. Also, feel free to follow us on Twitter and don’t forget to join our 85k+ ML SubReddit.

Sana Hassan, a consulting intern at Marktechpost and dual-degree student at IIT Madras, is passionate about applying technology and AI to address real-world challenges. With a keen interest in solving practical problems, he brings a fresh perspective to the intersection of AI and real-life solutions.

Credit: Source link

ShareTweetSendSharePin

Related Posts

Apple Brings First Apple Intelligence Features to China in iOS 27.3 – Unite.AI
AI & Technology

Apple Brings First Apple Intelligence Features to China in iOS 27.3 – Unite.AI

October 30, 2026
Powerlattice Raises M in Equity Offering, SEC Filing Shows – Unite.AI
AI & Technology

Powerlattice Raises $86M in Equity Offering, SEC Filing Shows – Unite.AI

October 30, 2026
Meta Settles Another Social Media Addiction Case Just Before Trial
AI & Technology

Meta Settles Another Social Media Addiction Case Just Before Trial

October 30, 2026
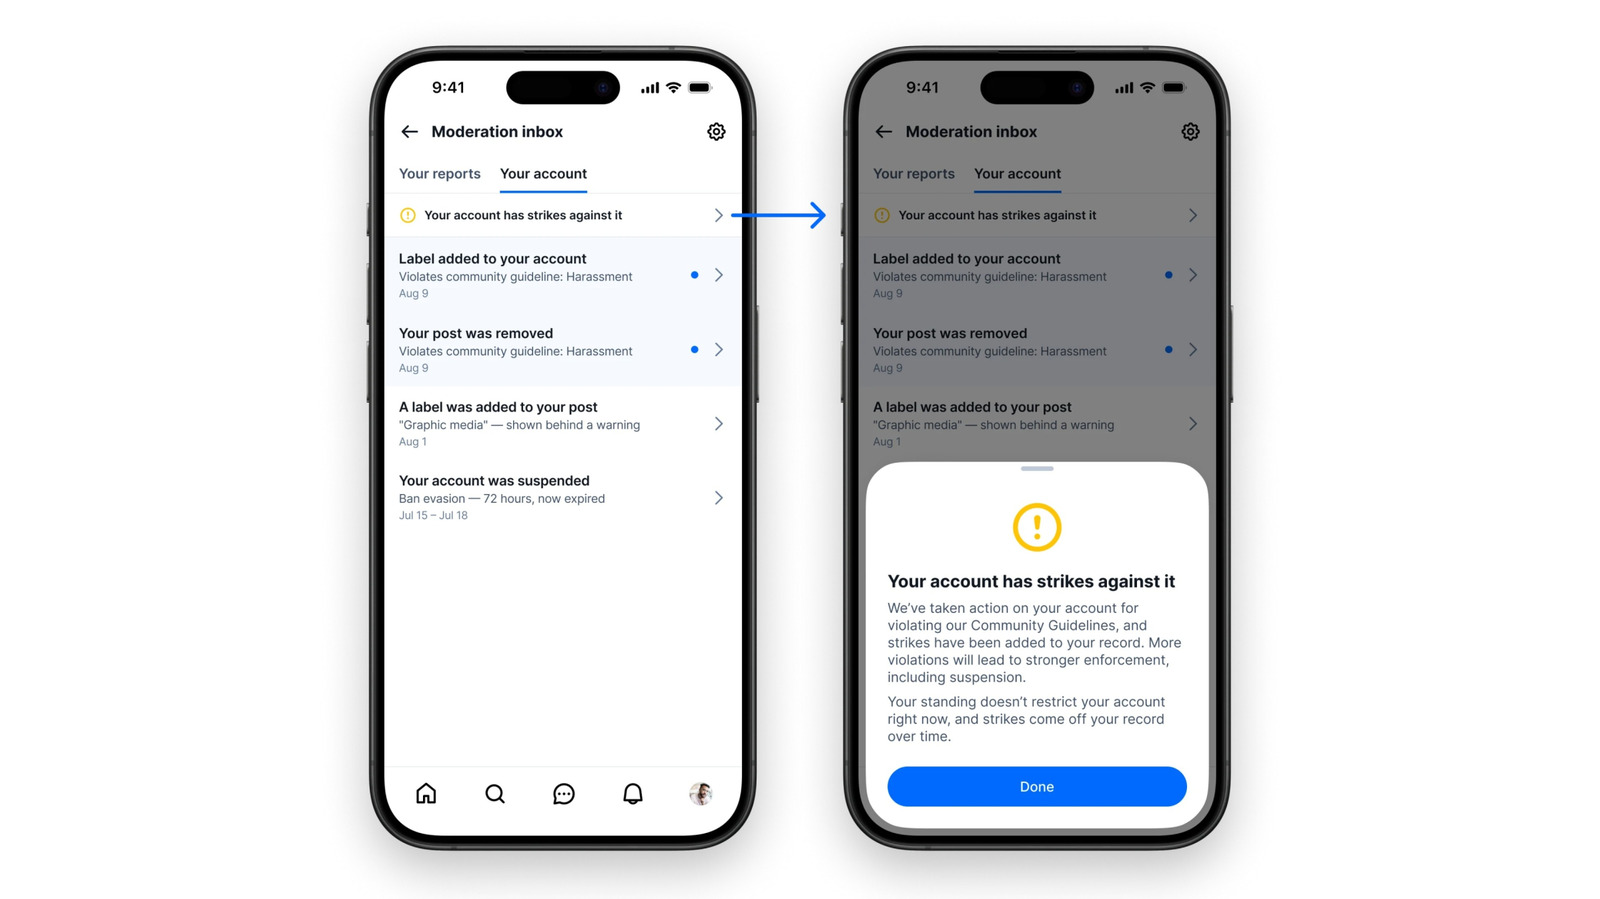
Bluesky Now Has A Dedicated ‘Moderation Inbox’
AI & Technology

Bluesky Now Has A Dedicated ‘Moderation Inbox’

October 30, 2026
Next Post
Tencent AI Researchers Introduce Hunyuan-T1: A Mamba-Powered Ultra-Large Language Model Redefining Deep Reasoning, Contextual Efficiency, and Human-Centric Reinforcement Learning

Tencent AI Researchers Introduce Hunyuan-T1: A Mamba-Powered Ultra-Large Language Model Redefining Deep Reasoning, Contextual Efficiency, and Human-Centric Reinforcement Learning

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Brewers ride 8-run fifth to Game 3 rout of Rays, take 3-0 World Series lead – ESPN

Brewers ride 8-run fifth to Game 3 rout of Rays, take 3-0 World Series lead – ESPN

October 27, 2026
Univ. of Chicago students react after woman says she was sexually assaulted at fraternity house 

Univ. of Chicago students react after woman says she was sexually assaulted at fraternity house 

October 25, 2026
Battleground House candidate: Democrats ‘have to be for something’ to win in November

Battleground House candidate: Democrats ‘have to be for something’ to win in November

October 24, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!