• bitcoinBitcoin(BTC)$76,693.00-4.60%
  • ethereumEthereum(ETH)$2,215.38-4.91%
  • tetherTether(USDT)$1.00-0.01%
  • binancecoinBNB(BNB)$693.59-6.76%
  • rippleXRP(XRP)$1.23-4.94%
  • usd-coinUSDC(USDC)$1.000.00%
  • solanaSolana(SOL)$94.40-6.38%
  • tronTRON(TRX)$0.3344850.92%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.03-0.32%
  • HyperliquidHyperliquid(HYPE)$90.71-0.49%
  • zcashZcash(ZEC)$1,221.95-4.65%
  • dogecoinDogecoin(DOGE)$0.074928-5.53%
  • moneroMonero(XMR)$582.63-2.72%
  • USDSUSDS(USDS)$1.000.05%
  • whitebitWhiteBIT Coin(WBT)$73.52-4.72%
  • leo-tokenLEO Token(LEO)$9.41-0.65%
  • chainlinkChainlink(LINK)$10.93-6.46%
  • cardanoCardano(ADA)$0.190035-6.01%
  • stellarStellar(XLM)$0.165739-3.26%
  • bitcoin-cashBitcoin Cash(BCH)$283.431.27%
  • nearNEAR Protocol(NEAR)$4.25-4.56%
  • RainRain(RAIN)$0.006474-0.54%
  • daiDai(DAI)$1.000.00%
  • Ethena USDeEthena USDe(USDE)$1.00-0.09%
  • litecoinLitecoin(LTC)$54.90-5.30%
  • uniswapUniswap(UNI)$6.81-5.94%
  • USD1USD1(USD1)$1.00-0.13%
  • CantonCanton(CC)$0.095078-7.02%
  • avalanche-2Avalanche(AVAX)$8.21-7.29%
  • suiSui(SUI)$0.88-6.23%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.15-5.43%
  • tether-goldTether Gold(XAUT)$3,900.20-3.00%
  • hedera-hashgraphHedera(HBAR)$0.070948-4.36%
  • Global DollarGlobal Dollar(USDG)$1.000.02%
  • paypal-usdPayPal USD(PYUSD)$1.000.04%
  • quant-networkQuant(QNT)$191.55-1.87%
  • shiba-inuShiba Inu(SHIB)$0.000005-4.80%
  • BittensorBittensor(TAO)$230.25-9.30%
  • crypto-com-chainCronos(CRO)$0.050982-5.25%
  • Ripple USDRipple USD(RLUSD)$1.000.01%
  • EthenaEthena(ENA)$0.185365-10.95%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.15-0.06%
  • Circle USYCCircle USYC(USYC)$1.140.03%
  • okbOKB(OKB)$110.06-2.18%
  • MemeCoreMemeCore(M)$0.97-10.05%
  • pepePepe(PEPE)$0.0000054.49%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • aaveAave(AAVE)$123.48-7.55%
  • OndoOndo(ONDO)$0.387773-7.25%
  • Falcon USDFalcon USD(USDF)$0.99-0.39%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

A Concurrent Programming Framework for Quantitative Analysis of Efficiency Issues When Serving Multiple Long-Context Requests Under Limited GPU High-Bandwidth Memory (HBM) Regime

July 5, 2024
in AI & Technology
Reading Time: 4 mins read
A A
A Concurrent Programming Framework for Quantitative Analysis of Efficiency Issues When Serving Multiple Long-Context Requests Under Limited GPU High-Bandwidth Memory (HBM) Regime
ShareShareShareShareShare

Large language models (LLMs) have gained significant capabilities, reaching GPT-4 level performance. However, deploying these models for applications requiring extensive context, such as repository-level coding and hour-long video understanding, poses substantial challenges. These tasks demand input contexts ranging from 100K to 10M tokens, a significant leap from the standard 4K token limit. Researchers are grappling with an ambitious goal: How can the deployment of 1M context production-level transformers be made as cost-effective as their 4K counterparts? The primary obstacle in serving long-context transformers is the size of the KV cache. For instance, a 30+B parameter model with 100K context requires a staggering 22.8GB of KV cache, compared to just 0.91GB for 4K context, highlighting the exponential increase in memory requirements as context length grows.

To overcome the challenges of deploying long-context transformers, the University of Edinburgh researcher has developed a concurrent programming framework for quantitative analysis of efficiency issues when serving multiple long-context requests under limited GPU high-bandwidth memory (HBM). This framework focuses on a 34B GPT-3.5 level model with a 50K context on an A100 NVLink GPU as a representative example. The analysis reveals four key deployment challenges stemming from the large KV cache: extended prefilling time and memory usage for long inputs, restricted concurrent user capacity due to HBM occupation, increased decoding latency from frequent KV cache access, and significant context switching latency when swapping KV cache between HBM and DDR memory. This comprehensive framework enables researchers to evaluate existing solutions and explore potential combinations for developing end-to-end systems that can efficiently handle long-context language models.

YOU MAY ALSO LIKE

CXMT Q3 Revenue Rises 613% as DRAM Shortage Swings It to Profit – Unite.AI

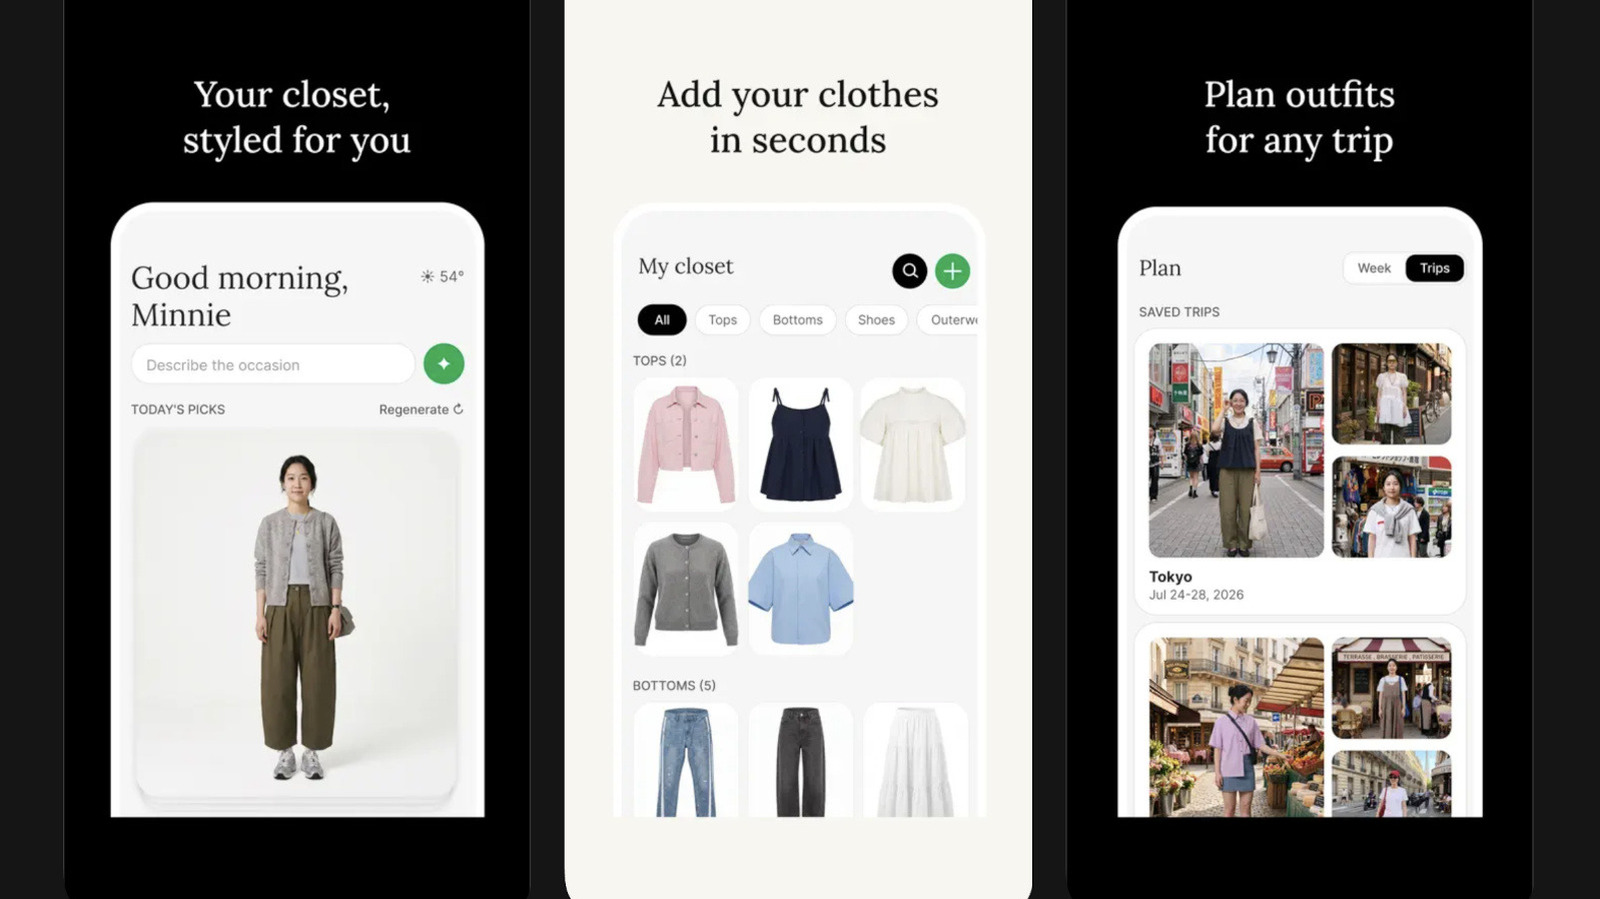
Meta Quietly Launches An AI Fashion App For Virtually Trying On Clothes

The study focuses on compressing the KV cache across four dimensions: layer, head, token, and hidden. Researchers hypothesize that some tasks may not require full-depth computation for the layer dimension, allowing for layer skipping during prefilling. This approach could potentially reduce the KV cache to just one layer, achieving a 1/60 compression ratio. In the head dimension, studies suggest that certain heads specialize in retrieval and long-context capabilities. By retaining only these crucial heads and pruning others, significant compression can be achieved. For instance, some research indicates that as few as 20 out of 1024 heads might be sufficient for retrieval tasks.

The token dimension compression is based on the hypothesis that if a token’s information can be inferred from its context, it can be compressed by dropping or merging it with neighboring tokens. However, this dimension appears less compressible than layers or heads, with most works showing less than 50% compression ratio. The hidden dimension, already small at 128, has seen limited exploration beyond quantization techniques. Researchers suggest that applying dimension reduction techniques like LoRA to the KV cache might yield further improvements. The framework also considers the relative cost between prefilling and decoding, noting that as models grow larger and context lengths increase, the cost shifts from decoding to prefilling, emphasizing the need for optimizing both aspects for efficient long-context deployment.

The research presents a comprehensive analysis of challenges in deploying long-context transformers, aiming to make 1M context serving as cost-effective as 4K. This goal would democratize advanced AI applications like video understanding and generative agents. The study introduces a concurrent programming framework that breaks down user interaction throughput into four key metrics: concurrency, prefilling, decoding, and context switching. By examining how various factors impact these metrics and reviewing existing optimization efforts, the research highlights significant opportunities for integrating current approaches to developing robust end-to-end long-context serving systems. This work lays the groundwork for full-stack optimization of long-context inference.


Check out the Paper. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter. 

Join our Telegram Channel and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our 46k+ ML SubReddit

Asjad is an intern consultant at Marktechpost. He is persuing B.Tech in mechanical engineering at the Indian Institute of Technology, Kharagpur. Asjad is a Machine learning and deep learning enthusiast who is always researching the applications of machine learning in healthcare.

🐝 Join the Fastest Growing AI Research Newsletter Read by Researchers from Google + NVIDIA + Meta + Stanford + MIT + Microsoft and many others…


Credit: Source link

ShareTweetSendSharePin

Related Posts

CXMT Q3 Revenue Rises 613% as DRAM Shortage Swings It to Profit – Unite.AI
AI & Technology

CXMT Q3 Revenue Rises 613% as DRAM Shortage Swings It to Profit – Unite.AI

October 30, 2026
Meta Quietly Launches An AI Fashion App For Virtually Trying On Clothes
AI & Technology

Meta Quietly Launches An AI Fashion App For Virtually Trying On Clothes

October 30, 2026
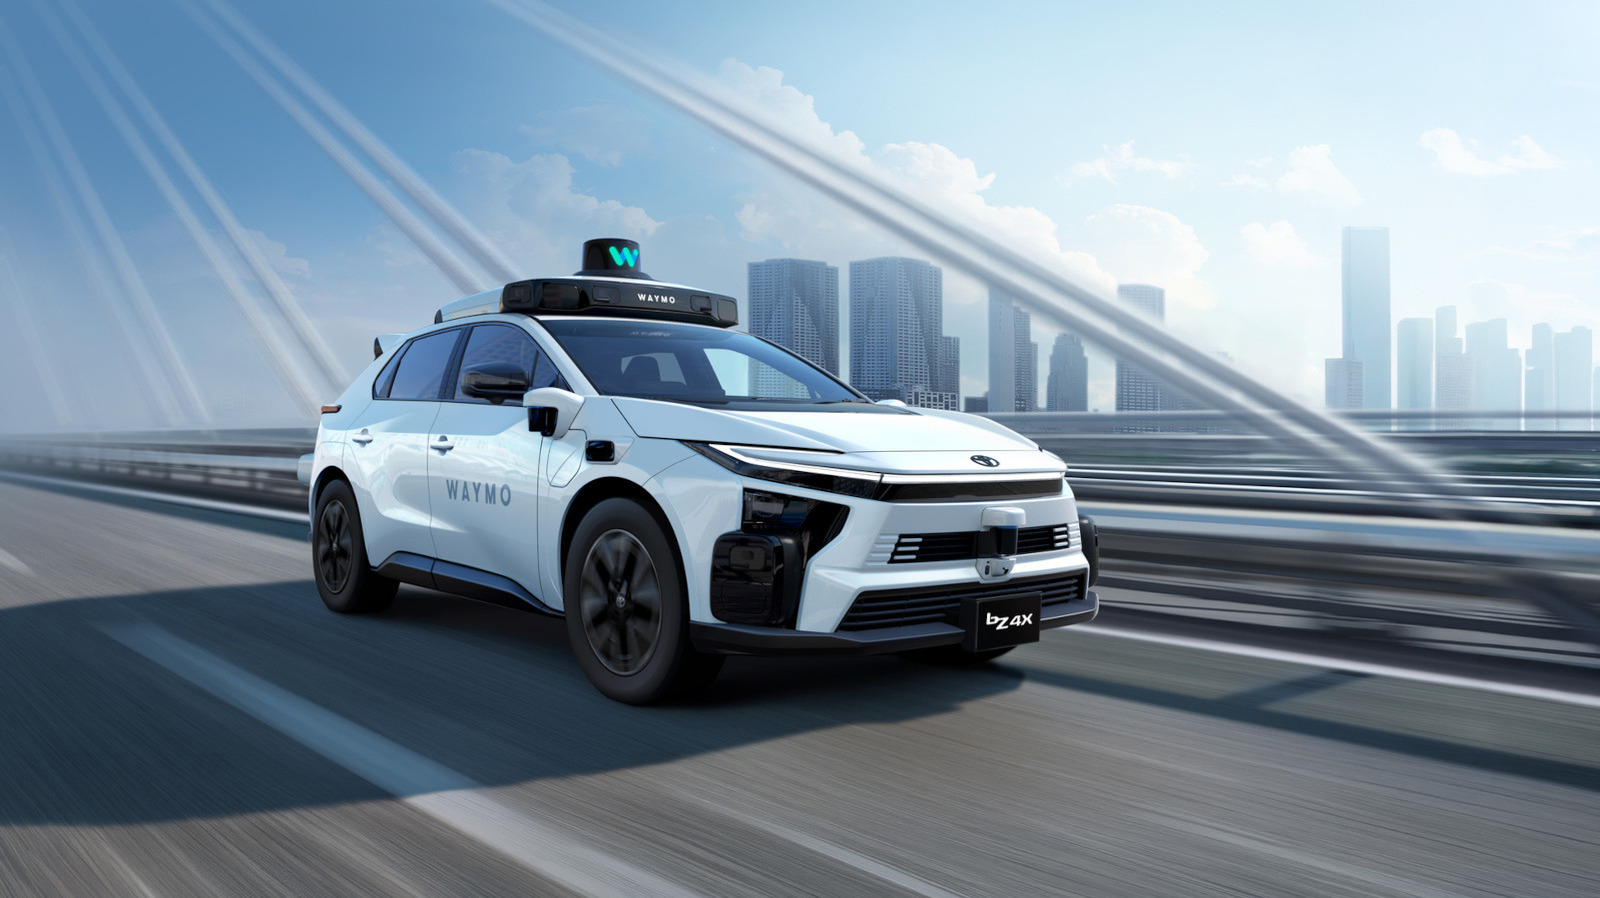
Waymo And Toyota Will Soon Start Testing Their Robotaxis In Japan
AI & Technology

Waymo And Toyota Will Soon Start Testing Their Robotaxis In Japan

October 30, 2026
Cognizant Forms OpenAI Frontier Capability Group of 25,000+ Professionals – Unite.AI
AI & Technology

Cognizant Forms OpenAI Frontier Capability Group of 25,000+ Professionals – Unite.AI

October 30, 2026
Next Post
Biden and Trump argued back argued which one is America’s all-time worst president.

Biden and Trump argued back argued which one is America’s all-time worst president.

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Video of Kelly Clarkson at Brooklyn store released

Video of Kelly Clarkson at Brooklyn store released

October 25, 2026
Vicor: Don't Get Off This Ride

Vicor: Don't Get Off This Ride

October 25, 2026
Good news: Town brings homecoming parade to doorstep of 6-year-old battling cancer

Good news: Town brings homecoming parade to doorstep of 6-year-old battling cancer

October 23, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!