• bitcoinBitcoin(BTC)$84,508.000.49%
  • ethereumEthereum(ETH)$2,688.95-0.08%
  • tetherTether(USDT)$1.000.00%
  • binancecoinBNB(BNB)$773.820.02%
  • rippleXRP(XRP)$1.52-1.93%
  • usd-coinUSDC(USDC)$1.000.00%
  • solanaSolana(SOL)$121.830.22%
  • tronTRON(TRX)$0.333784-0.79%
  • zcashZcash(ZEC)$1,582.771.75%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.063.39%
  • HyperliquidHyperliquid(HYPE)$91.29-1.14%
  • dogecoinDogecoin(DOGE)$0.096894-1.37%
  • chainlinkChainlink(LINK)$14.12-1.38%
  • moneroMonero(XMR)$544.96-1.62%
  • whitebitWhiteBIT Coin(WBT)$84.290.40%
  • USDSUSDS(USDS)$1.00-0.01%
  • cardanoCardano(ADA)$0.254135-1.73%
  • RainRain(RAIN)$0.012561-0.38%
  • leo-tokenLEO Token(LEO)$9.030.78%
  • stellarStellar(XLM)$0.215880-2.00%
  • nearNEAR Protocol(NEAR)$5.207.95%
  • bitcoin-cashBitcoin Cash(BCH)$333.30-1.05%
  • uniswapUniswap(UNI)$9.650.14%
  • litecoinLitecoin(LTC)$71.17-2.49%
  • CantonCanton(CC)$0.133640-4.58%
  • suiSui(SUI)$1.245.41%
  • Ethena USDeEthena USDe(USDE)$1.000.02%
  • avalanche-2Avalanche(AVAX)$10.94-0.49%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.6712.06%
  • daiDai(DAI)$1.000.00%
  • USD1USD1(USD1)$1.00-0.02%
  • hedera-hashgraphHedera(HBAR)$0.093396-1.65%
  • BittensorBittensor(TAO)$323.09-3.16%
  • shiba-inuShiba Inu(SHIB)$0.000006-2.02%
  • crypto-com-chainCronos(CRO)$0.0672101.91%
  • Global DollarGlobal Dollar(USDG)$1.00-0.01%
  • BitwayBitway(BTW)$1.1810.10%
  • paypal-usdPayPal USD(PYUSD)$1.000.00%
  • EthenaEthena(ENA)$0.274196-0.10%
  • quant-networkQuant(QNT)$185.2257.48%
  • tether-goldTether Gold(XAUT)$4,280.770.05%
  • MemeCoreMemeCore(M)$1.17-3.90%
  • OndoOndo(ONDO)$0.55-0.15%
  • okbOKB(OKB)$121.29-0.18%
  • Ripple USDRipple USD(RLUSD)$1.000.00%
  • Circle USYCCircle USYC(USYC)$1.140.00%
  • aaveAave(AAVE)$154.36-0.70%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Pump.funPump.fun(PUMP)$0.00490910.31%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.02%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Google DeepMind Finds a Fundamental Bug in RAG: Embedding Limits Break Retrieval at Scale

September 4, 2025
in AI & Technology
Reading Time: 9 mins read
A A
Google DeepMind Finds a Fundamental Bug in RAG: Embedding Limits Break Retrieval at Scale
ShareShareShareShareShare

Retrieval-Augmented Generation (RAG) systems generally rely on dense embedding models that map queries and documents into fixed-dimensional vector spaces. While this approach has become the default for many AI applications, a recent research from Google DeepMind team explains a fundamental architectural limitation that cannot be solved by larger models or better training alone.

What Is the Theoretical Limit of Embedding Dimensions?

At the core of the issue is the representational capacity of fixed-size embeddings. An embedding of dimension d cannot represent all possible combinations of relevant documents once the database grows beyond a critical size. This follows from results in communication complexity and sign-rank theory.

YOU MAY ALSO LIKE

How To Improve Your Router’s Security In 10 Minutes

Humanoid Robots Are Getting Even Creepier (This One Can Cry On Command)

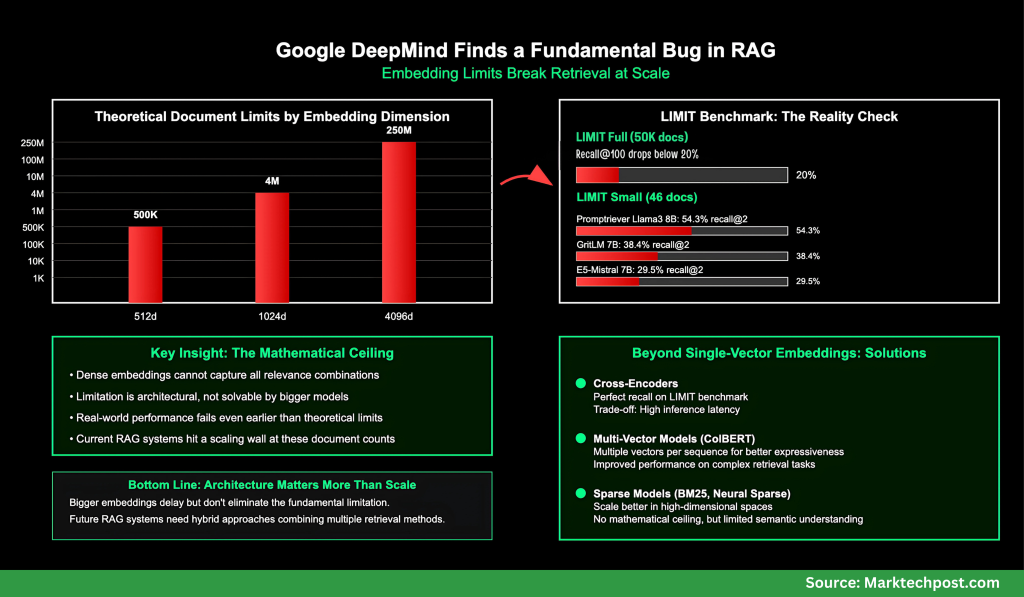
  • For embeddings of size 512, retrieval breaks down around 500K documents.
  • For 1024 dimensions, the limit extends to about 4 million documents.
  • For 4096 dimensions, the theoretical ceiling is 250 million documents.

These values are best-case estimates derived under free embedding optimization, where vectors are directly optimized against test labels. Real-world language-constrained embeddings fail even earlier.
https://arxiv.org/pdf/2508.21038

How Does the LIMIT Benchmark Expose This Problem?

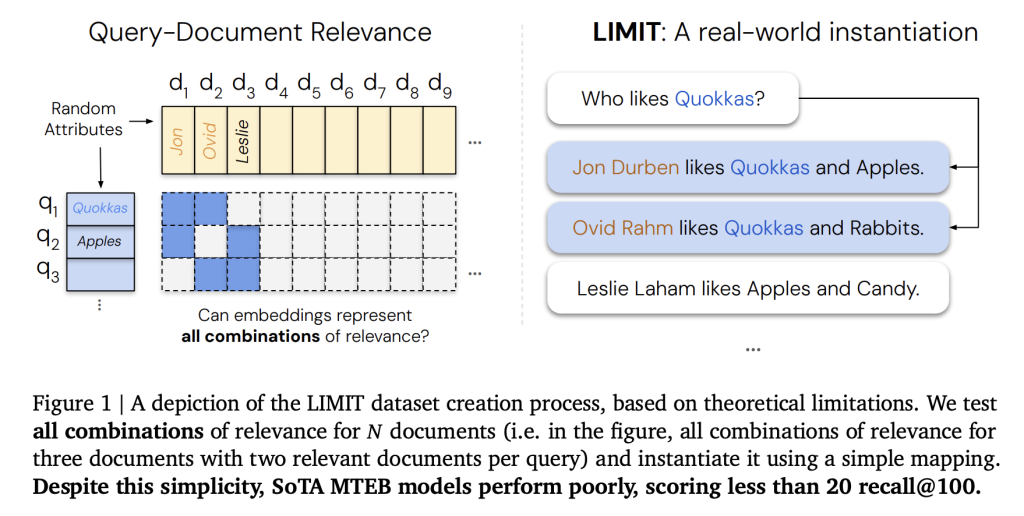
To test this limitation empirically, Google DeepMind Team introduced LIMIT (Limitations of Embeddings in Information Retrieval), a benchmark dataset specifically designed to stress-test embedders. LIMIT has two configurations:

  • LIMIT full (50K documents): In this large-scale setup, even strong embedders collapse, with recall@100 often falling below 20%.
  • LIMIT small (46 documents): Despite the simplicity of this toy-sized setup, models still fail to solve the task. Performance varies widely but remains far from reliable:
    • Promptriever Llama3 8B: 54.3% recall@2 (4096d)
    • GritLM 7B: 38.4% recall@2 (4096d)
    • E5-Mistral 7B: 29.5% recall@2 (4096d)
    • Gemini Embed: 33.7% recall@2 (3072d)

Even with just 46 documents, no embedder reaches full recall, highlighting that the limitation is not dataset size alone but the single-vector embedding architecture itself.

In contrast, BM25, a classical sparse lexical model, does not suffer from this ceiling. Sparse models operate in effectively unbounded dimensional spaces, allowing them to capture combinations that dense embeddings cannot.
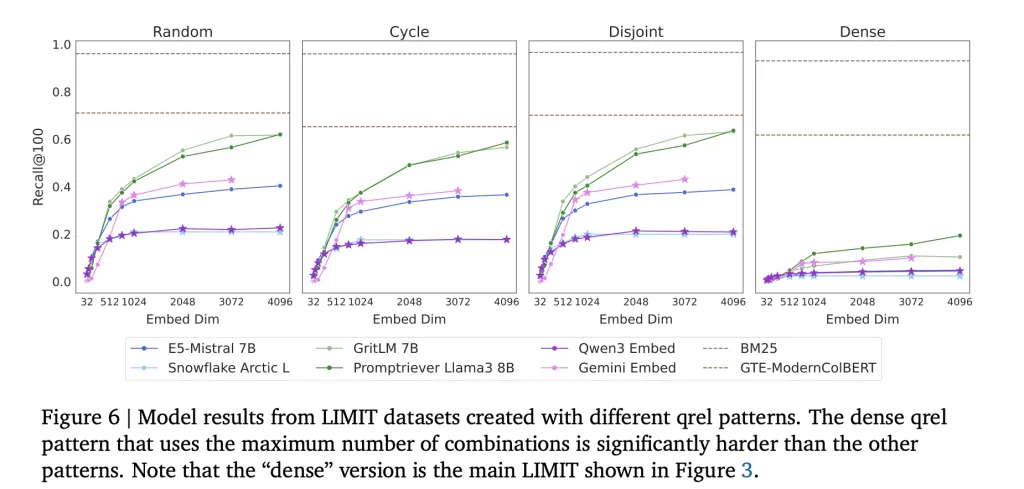
https://arxiv.org/pdf/2508.21038

Why Does This Matter for RAG?

CCurrent RAG implementations typically assume that embeddings can scale indefinitely with more data. The Google DeepMind research team explains how this assumption is incorrect: embedding size inherently constrains retrieval capacity. This affects:

  • Enterprise search engines handling millions of documents.
  • Agentic systems that rely on complex logical queries.
  • Instruction-following retrieval tasks, where queries define relevance dynamically.

Even advanced benchmarks like MTEB fail to capture these limitations because they test only a narrow part/section of query-document combinations.

What Are the Alternatives to Single-Vector Embeddings?

The research team suggested that scalable retrieval will require moving beyond single-vector embeddings:

  • Cross-Encoders: Achieve perfect recall on LIMIT by directly scoring query-document pairs, but at the cost of high inference latency.
  • Multi-Vector Models (e.g., ColBERT): Offer more expressive retrieval by assigning multiple vectors per sequence, improving performance on LIMIT tasks.
  • Sparse Models (BM25, TF-IDF, neural sparse retrievers): Scale better in high-dimensional search but lack semantic generalization.

The key insight is that architectural innovation is required, not simply larger embedders.
What is the Key Takeaway?

The research team’s analysis shows that dense embeddings, despite their success, are bound by a mathematical limit: they cannot capture all possible relevance combinations once corpus sizes exceed limits tied to embedding dimensionality. The LIMIT benchmark demonstrates this failure concretely:

  • On LIMIT full (50K docs): recall@100 drops below 20%.
  • On LIMIT small (46 docs): even the best models max out at ~54% recall@2.

Classical techniques like BM25, or newer architectures such as multi-vector retrievers and cross-encoders, remain essential for building reliable retrieval engines at scale.


Check out the PAPER here. Feel free to check out our GitHub Page for Tutorials, Codes and Notebooks. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter.


Asif Razzaq is the CEO of Marktechpost Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.

Credit: Source link

ShareTweetSendSharePin

Related Posts

How To Improve Your Router’s Security In 10 Minutes
AI & Technology

How To Improve Your Router’s Security In 10 Minutes

September 27, 2026
Humanoid Robots Are Getting Even Creepier (This One Can Cry On Command)
AI & Technology

Humanoid Robots Are Getting Even Creepier (This One Can Cry On Command)

September 27, 2026
AI Coding Agents for Enterprise: IP Indemnity, Data Residency and 500-Seat Cost Compared
AI & Technology

AI Coding Agents for Enterprise: IP Indemnity, Data Residency and 500-Seat Cost Compared

September 27, 2026
A Coding Guide to Google Research’s MSEB: Writing Sound Encoders to the Benchmark Contract and Scoring Them Across Classification, Clustering, Retrieval and Segmentation
AI & Technology

A Coding Guide to Google Research’s MSEB: Writing Sound Encoders to the Benchmark Contract and Scoring Them Across Classification, Clustering, Retrieval and Segmentation

September 27, 2026
Next Post
L.A. educators worry about how ICE raids may impact students

L.A. educators worry about how ICE raids may impact students

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Attorneys trade quarters while making closing arguments

Attorneys trade quarters while making closing arguments

September 22, 2026
Chase Sapphire Preferred® Card Review

Chase Sapphire Preferred® Card Review

September 20, 2026
Topaz Energy: Operator-Funded Reserve Renewal Supports The Premium

Topaz Energy: Operator-Funded Reserve Renewal Supports The Premium

September 26, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!