Multimodal AI agents are designed to process and integrate various data types, such as images, text, and videos, to perform tasks in digital and physical environments. They are used in robotics, virtual assistants, and user interface automation, where they need to understand and act based on complex multimodal inputs. These systems aim to bridge verbal and spatial intelligence by leveraging deep learning techniques, enabling interactions across multiple domains.
AI systems often specialize in vision-language understanding or robotic manipulation but struggle to combine these capabilities into a single model. Many AI models are designed for domain-specific tasks, such as UI navigation in digital environments or physical manipulation in robotics, limiting their generalization across different applications. The challenge lies in developing a unified model to understand and act across multiple modalities, ensuring effective decision-making in structured and unstructured environments.
Existing Vision-Language-Action (VLA) models attempt to address multimodal tasks by pretraining on large datasets of vision-language pairs followed by action trajectory data. However, these models typically lack adaptability across different environments. Examples include Pix2Act and WebGUM, which excel in UI navigation, and OpenVLA and RT-2, which are optimized for robotic manipulation. These models often require separate training processes and fail to generalize across both digital and physical environments. Also, conventional multimodal models struggle with integrating spatial and temporal intelligence, limiting their ability to perform complex tasks autonomously.
Researchers from Microsoft Research, the University of Maryland, the University of Wisconsin-Madison KAIST, and the University of Washington introduced Magma, a foundation model designed to unify multimodal understanding with action execution, enabling AI agents to function seamlessly in digital and physical environments. Magma is designed to overcome the shortcomings of existing VLA models by incorporating a robust training methodology that integrates multimodal understanding, action grounding, and planning. Magma is trained using a diverse dataset comprising 39 million samples, including images, videos, and robotic action trajectories. It incorporates two novel techniques,
- Set-of-Mark (SoM): SoM enables the model to label actionable visual objects, such as buttons in UI environments
- Trace-of-Mark (ToM): ToM allows it to track object movements over time and plan future actions accordingly
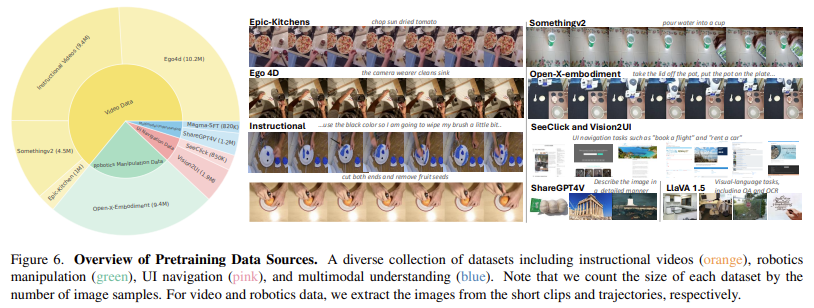
Magma employs a combination of deep learning architectures and large-scale pretraining to optimize its performance across multiple domains. The model uses a ConvNeXt-XXL vision backbone to process images and videos, while an LLaMA-3-8B language model handles textual inputs. This architecture enables Magma to integrate vision-language understanding with action execution seamlessly. It is trained on a curated dataset that includes UI navigation tasks from SeeClick and Vision2UI, robotic manipulation datasets from Open-X-Embodiment, and instructional videos from sources like Ego4D, Something-Something V2, and Epic-Kitchen. By leveraging SoM and ToM, Magma can effectively learn action grounding from UI screenshots and robotics data while enhancing its ability to predict future actions based on observed visual sequences. During training, the model processes up to 2.7 million UI screenshots, 970,000 robotic trajectories, and over 25 million video samples to ensure robust multimodal learning.
In zero-shot UI navigation tasks, Magma achieved an element selection accuracy of 57.2%, outperforming models like GPT-4V-OmniParser and SeeClick. In robotic manipulation tasks, Magma attained a success rate of 52.3% in Google Robot tasks and 35.4% in Bridge simulations, significantly surpassing OpenVLA, which only achieved 31.7% and 15.9% in the same benchmarks. The model also performed exceptionally well in multimodal understanding tasks, reaching 80.0% accuracy in VQA v2, 66.5% in TextVQA, and 87.4% in POPE evaluations. Magma also demonstrated strong spatial reasoning capabilities, scoring 74.8% on the BLINK dataset and 80.1% on the Visual Spatial Reasoning (VSR) benchmark. In video question-answering tasks, Magma achieved an accuracy of 88.6% on IntentQA and 72.9% on NextQA, further highlighting its ability to process temporal information effectively.
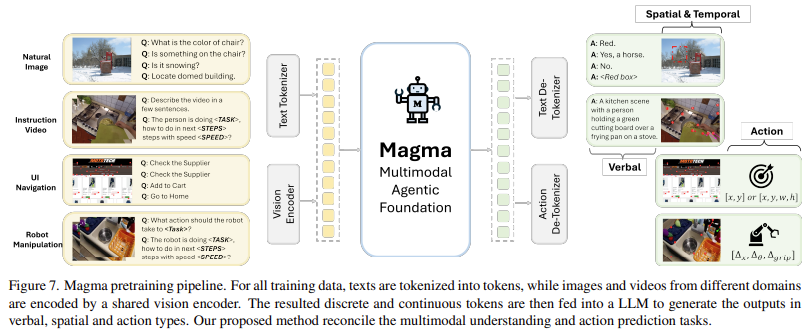
Several Key Takeaways emerge from the Research on Magma:
- Magma was trained on 39 million multimodal samples, including 2.7 million UI screenshots, 970,000 robotic trajectories, and 25 million video samples.
- The model combines vision, language, and action in a unified framework, overcoming the limitations of domain-specific AI models.
- SoM enables accurate labeling of clickable objects, while ToM allows tracking object movement over time, improving long-term planning capabilities.
- Magma achieved a 57.2% accuracy rate in element selection in UI tasks, a 52.3% success rate in robotic manipulation, and an 80.0% accuracy rate in VQA tasks.
- Magma outperformed existing AI models by over 19.6% in spatial reasoning benchmarks and improved by 28% over previous models in video-based reasoning.
- Magma demonstrated superior generalization across multiple tasks without requiring additional fine-tuning, making it a highly adaptable AI agent.
- Magma’s capabilities can enhance decision-making and execution in robotics, autonomous systems, UI automation, digital assistants, and industrial AI.
Check out the Paper and Project Page. All credit for this research goes to the researchers of this project. Also, feel free to follow us on Twitter and don’t forget to join our 75k+ ML SubReddit.
🚨 Recommended Read- LG AI Research Releases NEXUS: An Advanced System Integrating Agent AI System and Data Compliance Standards to Address Legal Concerns in AI Datasets

Asif Razzaq is the CEO of Marktechpost Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.
Credit: Source link