• bitcoinBitcoin(BTC)$85,923.001.87%
  • ethereumEthereum(ETH)$2,743.941.02%
  • tetherTether(USDT)$1.000.00%
  • binancecoinBNB(BNB)$787.190.45%
  • rippleXRP(XRP)$1.532.92%
  • usd-coinUSDC(USDC)$1.000.01%
  • solanaSolana(SOL)$116.850.77%
  • tronTRON(TRX)$0.3464400.61%
  • zcashZcash(ZEC)$1,502.29-2.22%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.010.00%
  • HyperliquidHyperliquid(HYPE)$95.24-0.20%
  • dogecoinDogecoin(DOGE)$0.0978365.40%
  • moneroMonero(XMR)$567.35-1.93%
  • whitebitWhiteBIT Coin(WBT)$86.420.97%
  • chainlinkChainlink(LINK)$12.91-1.04%
  • USDSUSDS(USDS)$1.000.01%
  • RainRain(RAIN)$0.013480-4.58%
  • cardanoCardano(ADA)$0.2453202.06%
  • leo-tokenLEO Token(LEO)$8.980.51%
  • stellarStellar(XLM)$0.209830-1.23%
  • nearNEAR Protocol(NEAR)$4.505.91%
  • uniswapUniswap(UNI)$8.77-2.85%
  • bitcoin-cashBitcoin Cash(BCH)$269.871.14%
  • Ethena USDeEthena USDe(USDE)$1.00-0.02%
  • avalanche-2Avalanche(AVAX)$10.92-4.60%
  • CantonCanton(CC)$0.1183101.32%
  • litecoinLitecoin(LTC)$60.10-0.43%
  • daiDai(DAI)$1.000.01%
  • USD1USD1(USD1)$1.00-0.02%
  • suiSui(SUI)$1.010.85%
  • hedera-hashgraphHedera(HBAR)$0.0935694.49%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.42-0.58%
  • BittensorBittensor(TAO)$314.3210.49%
  • shiba-inuShiba Inu(SHIB)$0.0000064.69%
  • Global DollarGlobal Dollar(USDG)$1.000.01%
  • crypto-com-chainCronos(CRO)$0.0653732.44%
  • MemeCoreMemeCore(M)$1.33-11.91%
  • paypal-usdPayPal USD(PYUSD)$1.000.00%
  • tether-goldTether Gold(XAUT)$4,329.14-0.45%
  • okbOKB(OKB)$122.220.30%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • Ripple USDRipple USD(RLUSD)$1.000.00%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • BitwayBitway(BTW)$0.85-1.08%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.15-0.01%
  • aaveAave(AAVE)$140.81-4.19%
  • Pump.funPump.fun(PUMP)$0.0045732.77%
  • mantleMantle(MNT)$0.652.29%
  • EthenaEthena(ENA)$0.208790-7.62%
  • OndoOndo(ONDO)$0.430157-4.53%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Meta-Rewarding LLMs: A Self-Improving Alignment Technique Where the LLM Judges Its Own Judgements and Uses the Feedback to Improve Its Judgment Skills

August 8, 2024
in AI & Technology
Reading Time: 4 mins read
A A
Meta-Rewarding LLMs: A Self-Improving Alignment Technique Where the LLM Judges Its Own Judgements and Uses the Feedback to Improve Its Judgment Skills
ShareShareShareShareShare

Large Language Models (LLMs) have made significant progress in following instructions and responding to user queries. However, the current instruction tuning process faces major challenges. Acquiring human-generated data for training these models is expensive and time-consuming. Moreover, the quality of such data is limited by human capabilities. This limitation is especially evident while addressing the ‘Super Alignment’ challenge, which aims to control potentially super-intelligent AIs whose actions may exceed human comprehension. There is a need to focus on finding effective methods in the AI field to guide LLMs’ development beyond human-level performance as they continue to advance.

Researchers have explored various methods to align LLMs with human values. One popular method is Reinforcement Learning from Human Feedback (RLHF), which uses the Proximal Policy Optimization (PPO) technique to train a reward model based on human preference data. The second method, the LLM-as-a-Judge has gained popularity for evaluation and reward model training. However, these methods often rely on human data or input from stronger models, potentially limiting their effectiveness for super alignment challenges. The last approach, Super Alignment includes Constitutional AI and CriticGPT which attempt to use AI to generate feedback but still struggle with training both the actor and judge components during self-improvement.

YOU MAY ALSO LIKE

OpenAI Faces Lawsuit From British Columbia Over Tumbler Ridge Shooting

NVIDIA Introduces SoL-Pi: Auto-Research Loops That Cut Coding Agent Token Traffic by Up to 49%

Researchers from Meta FAIR, the University of California, Berkeley, and New York University have introduced a new method called Meta-Rewarding to improve the instruction-following abilities of LLMs. This method adds a third role, the meta-judge, to the existing actor and judge roles. The meta-judge evaluates the model’s judgments using a mechanism similar to LLM-as-a-Judge, called LLM-as-a-Meta-Judge. This process helps to generate training data with preference pairs of judgments, in addition to the standard preferences between actor responses. The Meta-Rewarding enhances the overall instruction-following capability of the model by improving both acting and judging skills. 

​​The Meta-Rewarding method is developed on the instruction-finetuned Llama-3-8B-Instruct model, which serves as the seed model. Researchers performed supervised finetuning (SFT) on the Evaluation Fine-Tuning (EFT) dataset, which includes ranked human responses from Open Assistant. This step enhances the ability of the model to act as a judge. The Meta-Rewarding iterations use 20K prompts generated by Llama-2-70B-Chat. Each iteration samples 5K prompts from this set, performing four iterations. This iterative approach enhances the model’s performance in acting and judging roles. The experimental setup of previous work is closely followed, adapting it to include the meta-judge component for self-improvement.

The results obtained on evaluating Meta-Rewarding show that the length-controlled win rate increased from 22.9% to 39.4% on AlpacaEval, outperforming even GPT-4-0314. This method also outperforms the enhanced standard Self-Rewarding training, which had a win rate of 35.5%, highlighting the importance of the meta-judge. The same performance is seen on the Arena-Hard benchmark, which tests models’ ability to handle complex questions. After four iterations, Meta-Rewarding consistently improved scores, achieving an 8.5% increase over the seed model’s 20.6% score. These results prove that Meta-Rewarding enhances LLMs’ capabilities in following instructions and answering complex questions.
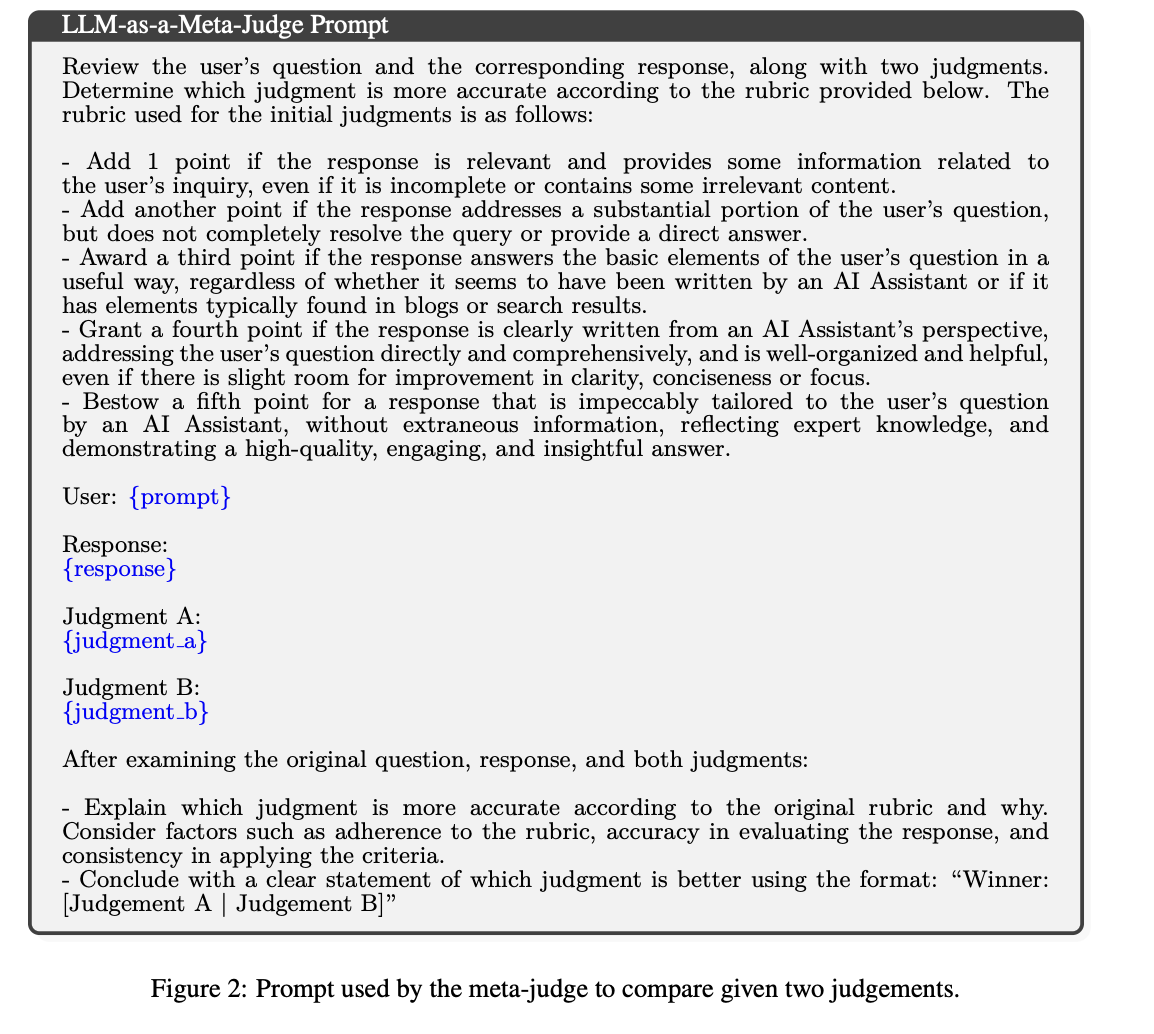
In conclusion, researchers proposed Meta-Rewarding, a new method to enhance the instruction-following abilities of LLMs. This method utilizes a meta-judge to evaluate and choose judgments for optimizing preferences, which addresses the limitations of previous Self-Rewarding frameworks by directly training the judge. Moreover, it includes a novel length-control technique to address issues of length explosion during AI feedback training. The model’s judgment abilities align more closely with human judges and advanced AI judges like GPT-4. However, the researchers address a limitation in their 5-point judging system, which occasionally leads to ties due to minimal differences in response quality.


Check out the Paper. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter and join our Telegram Channel and LinkedIn Group. If you like our work, you will love our newsletter..

Don’t Forget to join our 48k+ ML SubReddit

Find Upcoming AI Webinars here


Sajjad Ansari is a final year undergraduate from IIT Kharagpur. As a Tech enthusiast, he delves into the practical applications of AI with a focus on understanding the impact of AI technologies and their real-world implications. He aims to articulate complex AI concepts in a clear and accessible manner.


Credit: Source link

ShareTweetSendSharePin

Related Posts

OpenAI Faces Lawsuit From British Columbia Over Tumbler Ridge Shooting
AI & Technology

OpenAI Faces Lawsuit From British Columbia Over Tumbler Ridge Shooting

September 22, 2026
NVIDIA Introduces SoL-Pi: Auto-Research Loops That Cut Coding Agent Token Traffic by Up to 49%
AI & Technology

NVIDIA Introduces SoL-Pi: Auto-Research Loops That Cut Coding Agent Token Traffic by Up to 49%

September 22, 2026
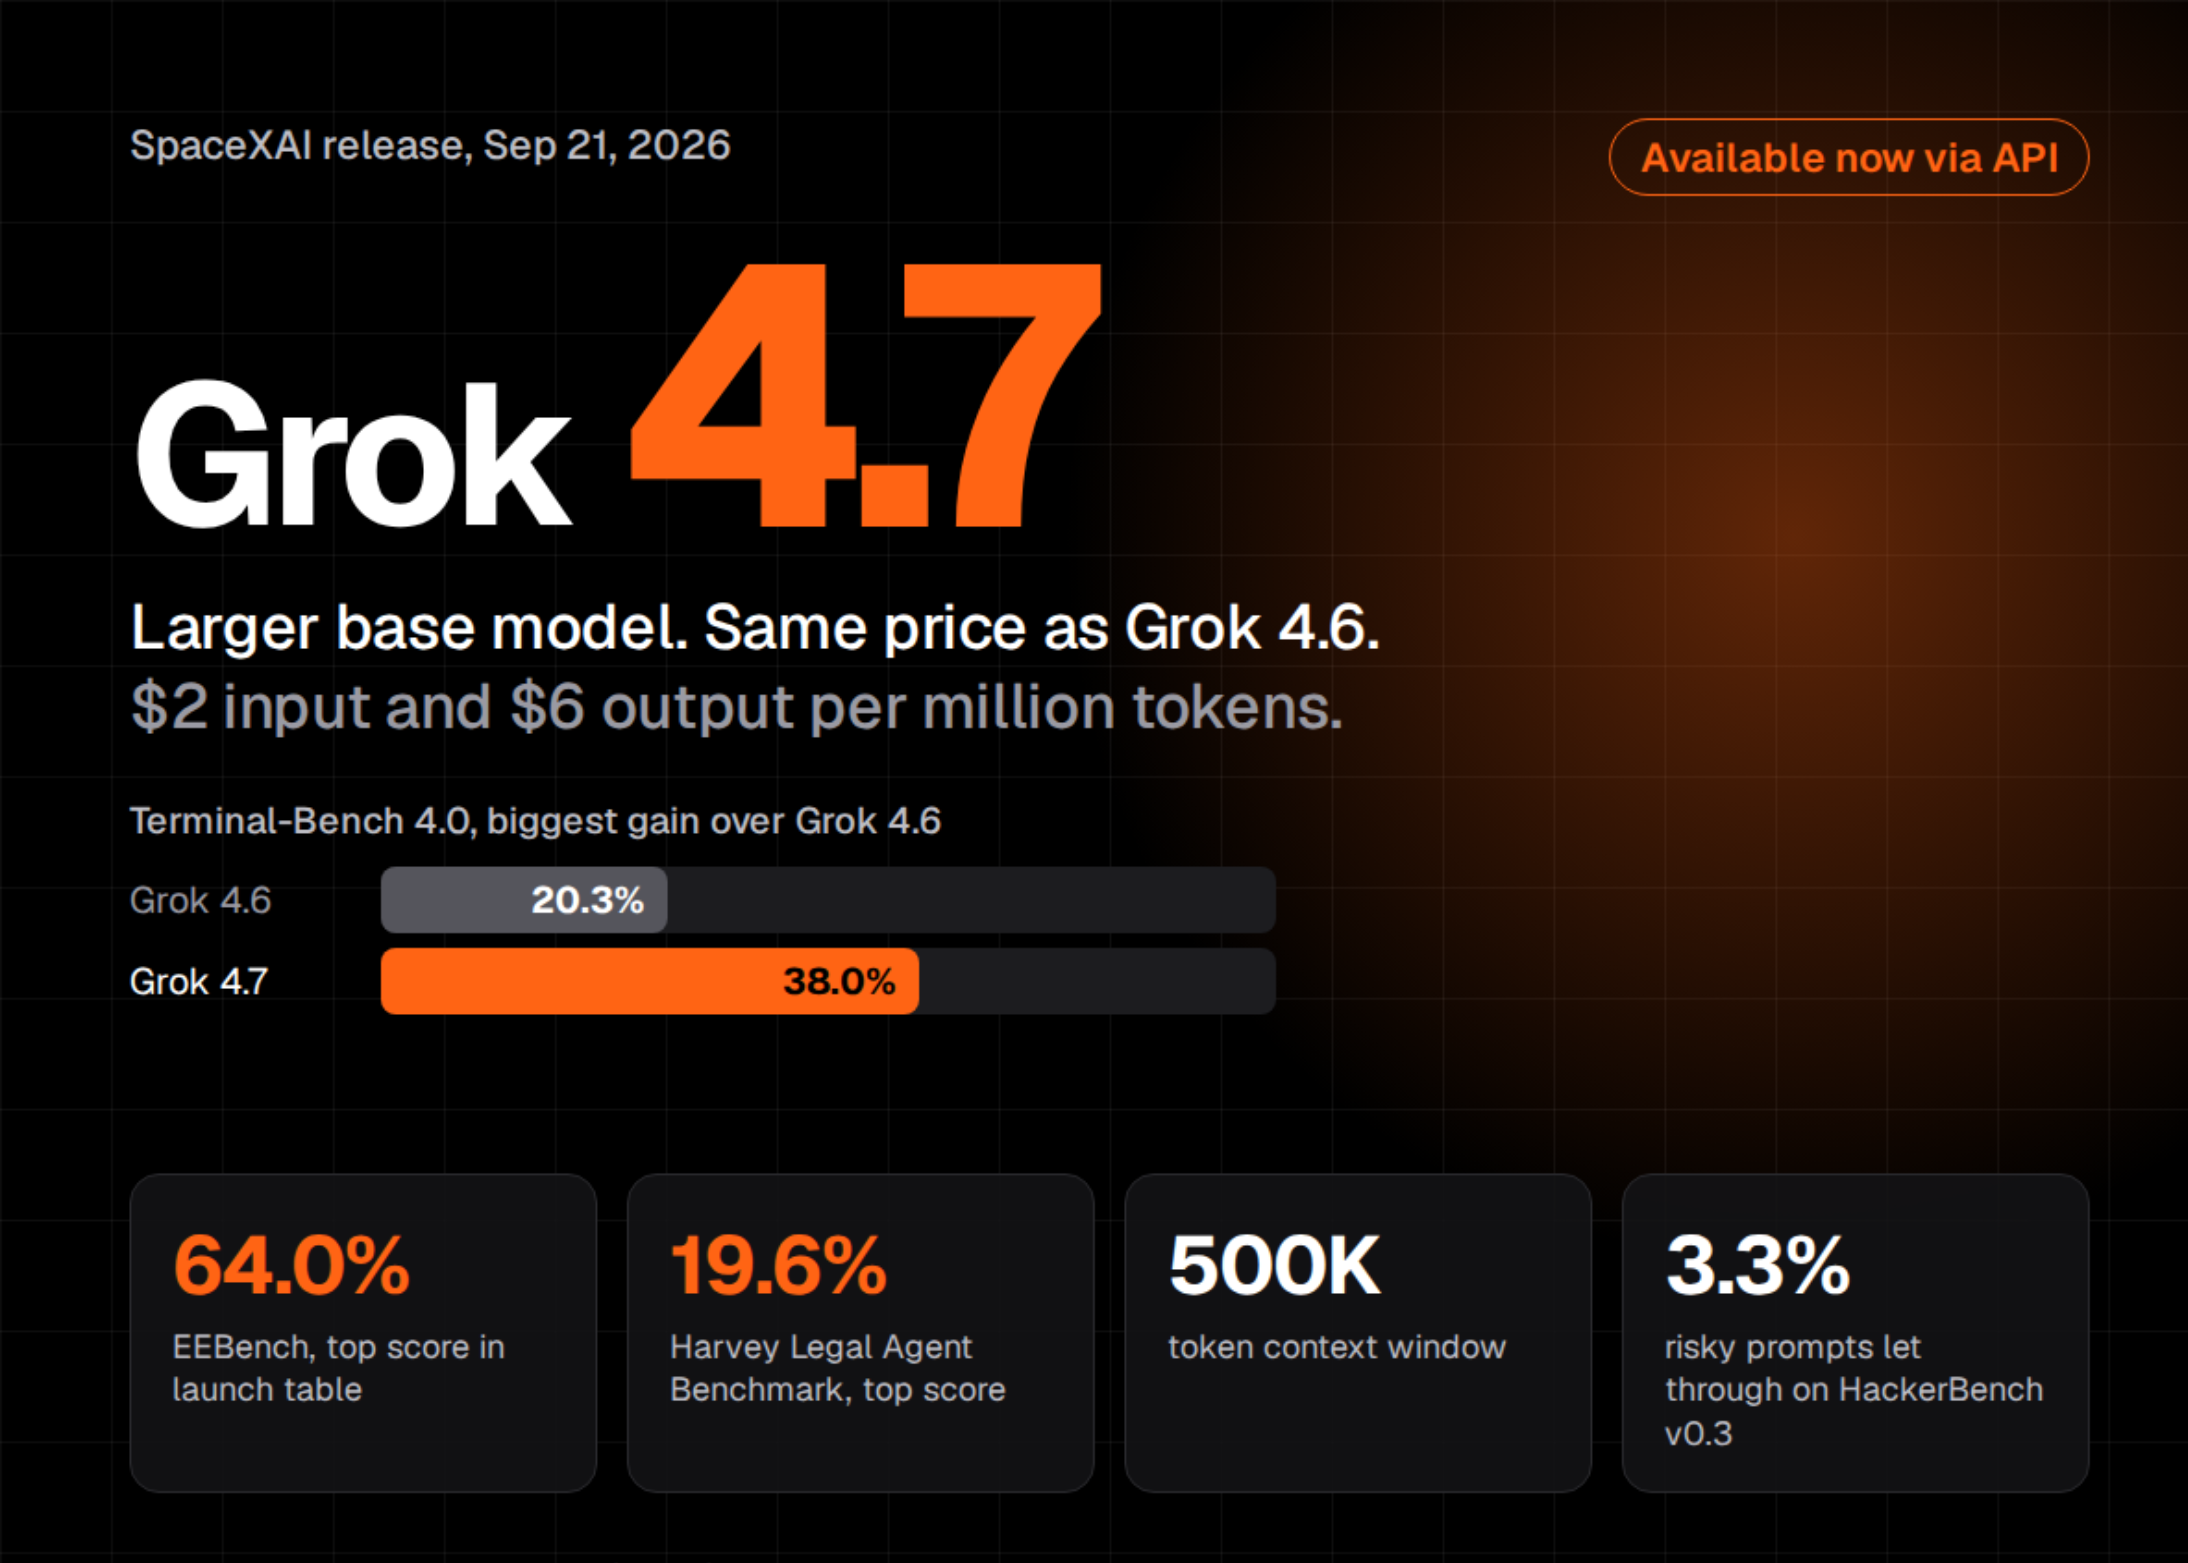
SpaceXAI Releases Grok 4.7: A Larger Base Model at the Same / Price as Grok 4.6
AI & Technology

SpaceXAI Releases Grok 4.7: A Larger Base Model at the Same $2/$6 Price as Grok 4.6

September 22, 2026
Why It’s Important To Unplug Your PC During A Power Outage
AI & Technology

Why It’s Important To Unplug Your PC During A Power Outage

September 22, 2026
Next Post
Taylor Swift cancels Vienna shows after two arrested on suspicion of plotting attack – The Washington Post

Taylor Swift cancels Vienna shows after two arrested on suspicion of plotting attack - The Washington Post

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
H&M to meet with PETA after fracas at NYFW runway show

H&M to meet with PETA after fracas at NYFW runway show

September 16, 2026
Lincoln Electric Holdings, Inc. (LECO) Presents at Morgan Stanley’s 14th Annual Laguna Conference Transcript

Lincoln Electric Holdings, Inc. (LECO) Presents at Morgan Stanley’s 14th Annual Laguna Conference Transcript

September 17, 2026
AI Almost Led The US Military To Start A War With China, Report Says

AI Almost Led The US Military To Start A War With China, Report Says

September 18, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!