• bitcoinBitcoin(BTC)$85,871.001.96%
  • ethereumEthereum(ETH)$2,738.721.28%
  • tetherTether(USDT)$1.000.00%
  • binancecoinBNB(BNB)$785.860.50%
  • rippleXRP(XRP)$1.544.19%
  • usd-coinUSDC(USDC)$1.000.01%
  • solanaSolana(SOL)$116.971.37%
  • tronTRON(TRX)$0.3484721.24%
  • zcashZcash(ZEC)$1,496.31-1.17%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.010.00%
  • HyperliquidHyperliquid(HYPE)$94.92-0.95%
  • dogecoinDogecoin(DOGE)$0.0985226.82%
  • moneroMonero(XMR)$566.81-3.14%
  • whitebitWhiteBIT Coin(WBT)$86.330.99%
  • chainlinkChainlink(LINK)$12.92-0.09%
  • RainRain(RAIN)$0.013538-3.89%
  • USDSUSDS(USDS)$1.00-0.01%
  • cardanoCardano(ADA)$0.2483464.06%
  • leo-tokenLEO Token(LEO)$8.980.41%
  • stellarStellar(XLM)$0.2121462.35%
  • nearNEAR Protocol(NEAR)$4.534.49%
  • uniswapUniswap(UNI)$8.78-4.50%
  • bitcoin-cashBitcoin Cash(BCH)$267.622.39%
  • Ethena USDeEthena USDe(USDE)$1.00-0.02%
  • avalanche-2Avalanche(AVAX)$10.88-3.05%
  • litecoinLitecoin(LTC)$60.411.36%
  • CantonCanton(CC)$0.1172180.66%
  • daiDai(DAI)$1.000.01%
  • USD1USD1(USD1)$1.00-0.01%
  • hedera-hashgraphHedera(HBAR)$0.0955417.65%
  • suiSui(SUI)$1.020.98%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.430.70%
  • BittensorBittensor(TAO)$318.1713.55%
  • shiba-inuShiba Inu(SHIB)$0.0000065.71%
  • crypto-com-chainCronos(CRO)$0.0660614.76%
  • Global DollarGlobal Dollar(USDG)$1.000.01%
  • MemeCoreMemeCore(M)$1.34-12.98%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.01%
  • tether-goldTether Gold(XAUT)$4,319.11-0.74%
  • okbOKB(OKB)$123.021.48%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • Ripple USDRipple USD(RLUSD)$1.000.00%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.60%
  • BitwayBitway(BTW)$0.82-0.25%
  • aaveAave(AAVE)$141.38-4.18%
  • mantleMantle(MNT)$0.652.92%
  • EthenaEthena(ENA)$0.210704-4.88%
  • Pump.funPump.fun(PUMP)$0.0045281.63%
  • OndoOndo(ONDO)$0.433744-1.63%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

A Concurrent Programming Framework for Quantitative Analysis of Efficiency Issues When Serving Multiple Long-Context Requests Under Limited GPU High-Bandwidth Memory (HBM) Regime

July 5, 2024
in AI & Technology
Reading Time: 4 mins read
A A
A Concurrent Programming Framework for Quantitative Analysis of Efficiency Issues When Serving Multiple Long-Context Requests Under Limited GPU High-Bandwidth Memory (HBM) Regime
ShareShareShareShareShare

Large language models (LLMs) have gained significant capabilities, reaching GPT-4 level performance. However, deploying these models for applications requiring extensive context, such as repository-level coding and hour-long video understanding, poses substantial challenges. These tasks demand input contexts ranging from 100K to 10M tokens, a significant leap from the standard 4K token limit. Researchers are grappling with an ambitious goal: How can the deployment of 1M context production-level transformers be made as cost-effective as their 4K counterparts? The primary obstacle in serving long-context transformers is the size of the KV cache. For instance, a 30+B parameter model with 100K context requires a staggering 22.8GB of KV cache, compared to just 0.91GB for 4K context, highlighting the exponential increase in memory requirements as context length grows.

To overcome the challenges of deploying long-context transformers, the University of Edinburgh researcher has developed a concurrent programming framework for quantitative analysis of efficiency issues when serving multiple long-context requests under limited GPU high-bandwidth memory (HBM). This framework focuses on a 34B GPT-3.5 level model with a 50K context on an A100 NVLink GPU as a representative example. The analysis reveals four key deployment challenges stemming from the large KV cache: extended prefilling time and memory usage for long inputs, restricted concurrent user capacity due to HBM occupation, increased decoding latency from frequent KV cache access, and significant context switching latency when swapping KV cache between HBM and DDR memory. This comprehensive framework enables researchers to evaluate existing solutions and explore potential combinations for developing end-to-end systems that can efficiently handle long-context language models.

YOU MAY ALSO LIKE

OpenAI Faces Lawsuit From British Columbia Over Tumbler Ridge Shooting

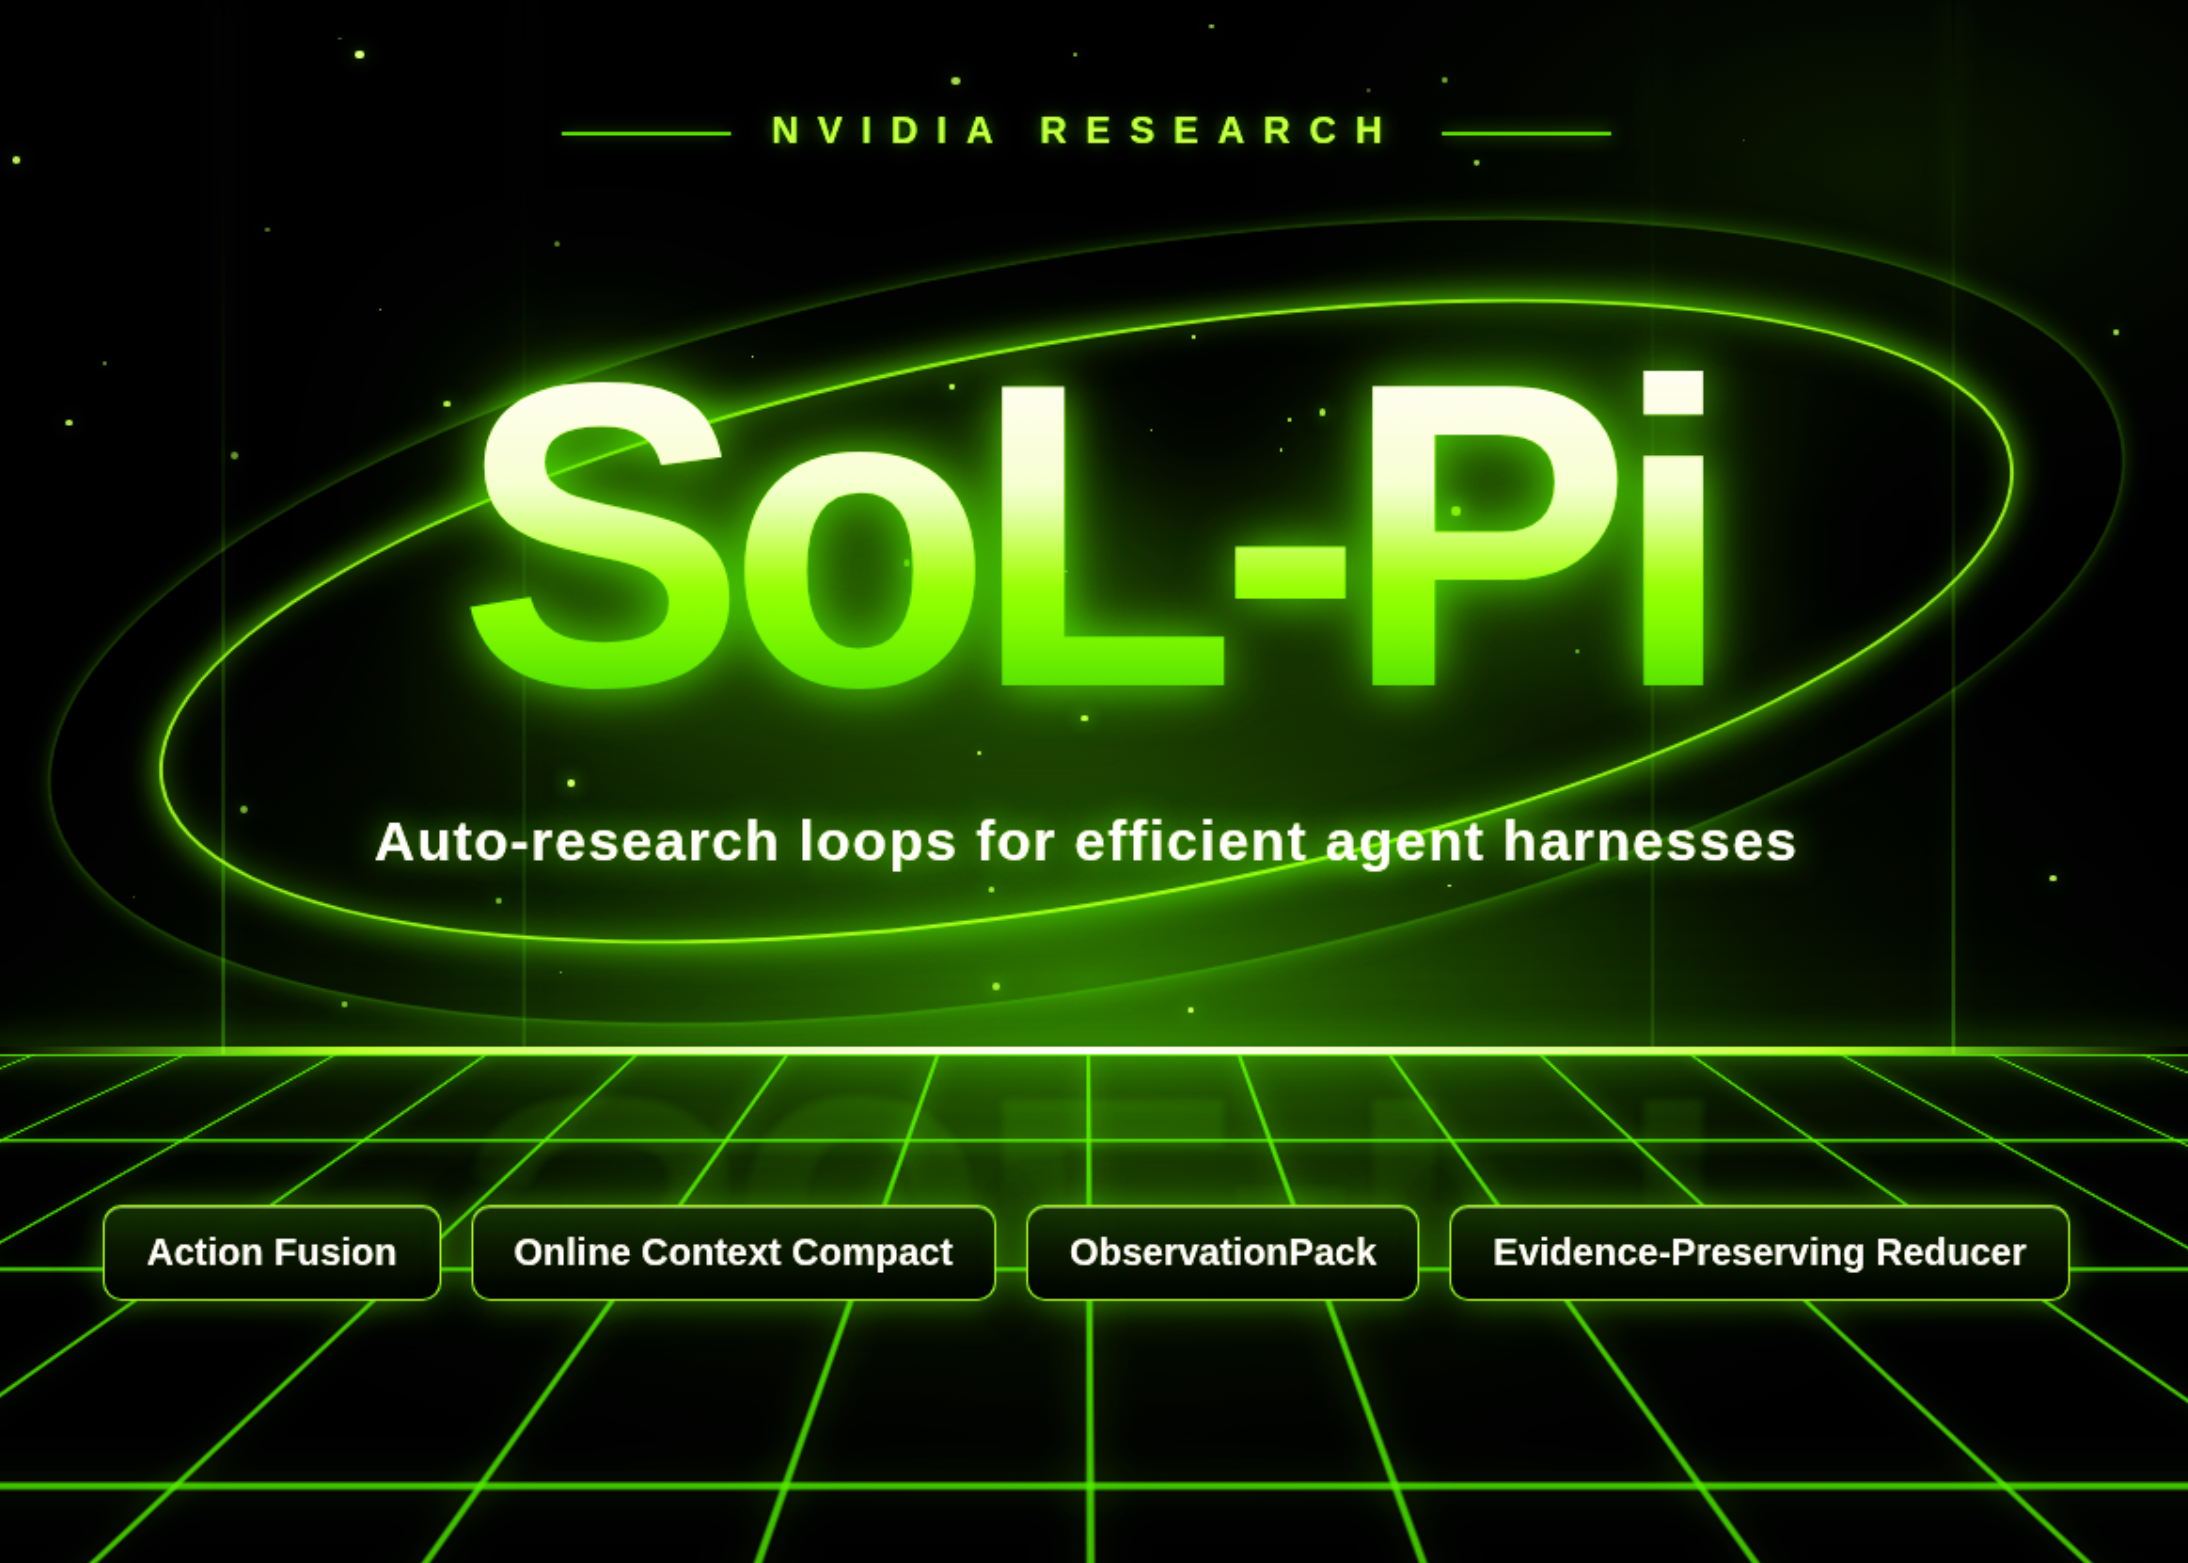
NVIDIA Introduces SoL-Pi: Auto-Research Loops That Cut Coding Agent Token Traffic by Up to 49%

The study focuses on compressing the KV cache across four dimensions: layer, head, token, and hidden. Researchers hypothesize that some tasks may not require full-depth computation for the layer dimension, allowing for layer skipping during prefilling. This approach could potentially reduce the KV cache to just one layer, achieving a 1/60 compression ratio. In the head dimension, studies suggest that certain heads specialize in retrieval and long-context capabilities. By retaining only these crucial heads and pruning others, significant compression can be achieved. For instance, some research indicates that as few as 20 out of 1024 heads might be sufficient for retrieval tasks.

The token dimension compression is based on the hypothesis that if a token’s information can be inferred from its context, it can be compressed by dropping or merging it with neighboring tokens. However, this dimension appears less compressible than layers or heads, with most works showing less than 50% compression ratio. The hidden dimension, already small at 128, has seen limited exploration beyond quantization techniques. Researchers suggest that applying dimension reduction techniques like LoRA to the KV cache might yield further improvements. The framework also considers the relative cost between prefilling and decoding, noting that as models grow larger and context lengths increase, the cost shifts from decoding to prefilling, emphasizing the need for optimizing both aspects for efficient long-context deployment.

The research presents a comprehensive analysis of challenges in deploying long-context transformers, aiming to make 1M context serving as cost-effective as 4K. This goal would democratize advanced AI applications like video understanding and generative agents. The study introduces a concurrent programming framework that breaks down user interaction throughput into four key metrics: concurrency, prefilling, decoding, and context switching. By examining how various factors impact these metrics and reviewing existing optimization efforts, the research highlights significant opportunities for integrating current approaches to developing robust end-to-end long-context serving systems. This work lays the groundwork for full-stack optimization of long-context inference.


Check out the Paper. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter. 

Join our Telegram Channel and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our 46k+ ML SubReddit


Asjad is an intern consultant at Marktechpost. He is persuing B.Tech in mechanical engineering at the Indian Institute of Technology, Kharagpur. Asjad is a Machine learning and deep learning enthusiast who is always researching the applications of machine learning in healthcare.

🐝 Join the Fastest Growing AI Research Newsletter Read by Researchers from Google + NVIDIA + Meta + Stanford + MIT + Microsoft and many others…


Credit: Source link

ShareTweetSendSharePin

Related Posts

OpenAI Faces Lawsuit From British Columbia Over Tumbler Ridge Shooting
AI & Technology

OpenAI Faces Lawsuit From British Columbia Over Tumbler Ridge Shooting

September 22, 2026
NVIDIA Introduces SoL-Pi: Auto-Research Loops That Cut Coding Agent Token Traffic by Up to 49%
AI & Technology

NVIDIA Introduces SoL-Pi: Auto-Research Loops That Cut Coding Agent Token Traffic by Up to 49%

September 22, 2026
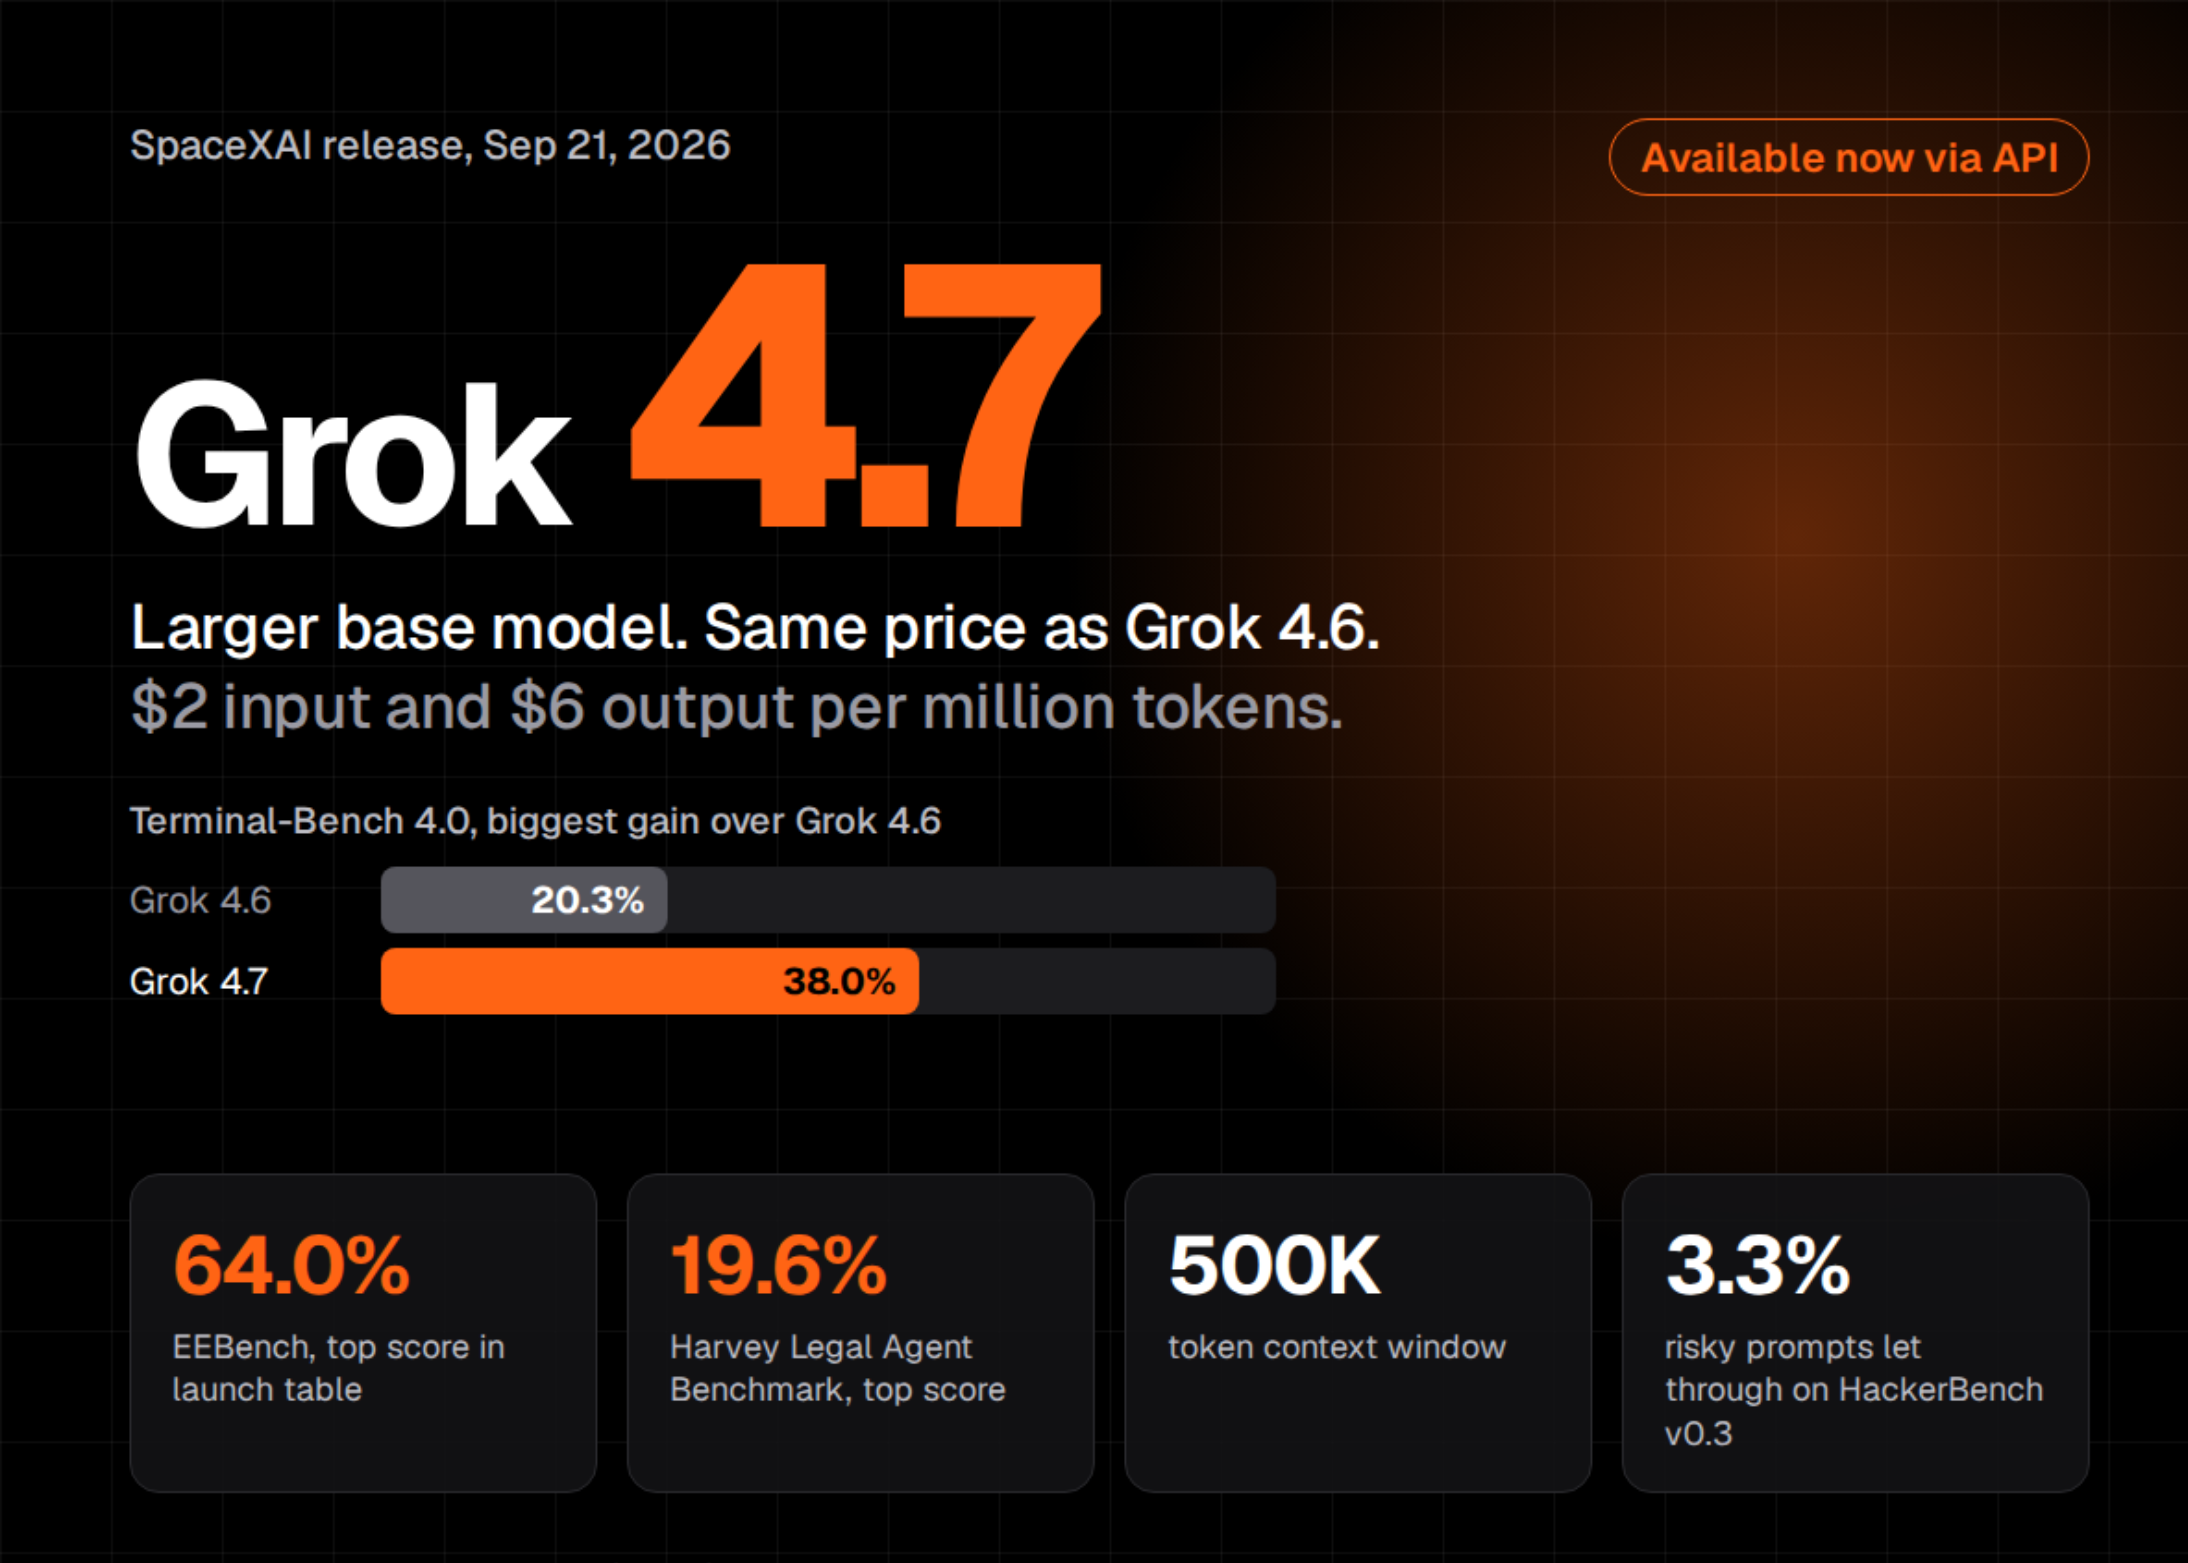
SpaceXAI Releases Grok 4.7: A Larger Base Model at the Same / Price as Grok 4.6
AI & Technology

SpaceXAI Releases Grok 4.7: A Larger Base Model at the Same $2/$6 Price as Grok 4.6

September 22, 2026
Why It’s Important To Unplug Your PC During A Power Outage
AI & Technology

Why It’s Important To Unplug Your PC During A Power Outage

September 22, 2026
Next Post
Biden and Trump argued back argued which one is America’s all-time worst president.

Biden and Trump argued back argued which one is America’s all-time worst president.

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Wall Street hangout San Pietro that became a post-9/11 destination is open again after major revamp

Wall Street hangout San Pietro that became a post-9/11 destination is open again after major revamp

September 18, 2026
John Hancock Multimanager 2040 Lifetime Portfolio Q2 2026 Commentary (JLIAX)

John Hancock Multimanager 2040 Lifetime Portfolio Q2 2026 Commentary (JLIAX)

September 16, 2026
Millions under severe weather threat over Labor Day weekend

Millions under severe weather threat over Labor Day weekend

September 17, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!