• bitcoinBitcoin(BTC)$81,767.001.16%
  • ethereumEthereum(ETH)$2,649.272.23%
  • tetherTether(USDT)$1.000.00%
  • binancecoinBNB(BNB)$768.131.38%
  • rippleXRP(XRP)$1.434.23%
  • usd-coinUSDC(USDC)$1.000.00%
  • solanaSolana(SOL)$111.970.28%
  • tronTRON(TRX)$0.3390990.19%
  • zcashZcash(ZEC)$1,504.844.51%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.030.44%
  • HyperliquidHyperliquid(HYPE)$93.212.47%
  • dogecoinDogecoin(DOGE)$0.0898622.73%
  • moneroMonero(XMR)$568.661.11%
  • whitebitWhiteBIT Coin(WBT)$83.410.58%
  • RainRain(RAIN)$0.0139824.61%
  • USDSUSDS(USDS)$1.00-0.04%
  • chainlinkChainlink(LINK)$12.603.90%
  • cardanoCardano(ADA)$0.2299035.37%
  • leo-tokenLEO Token(LEO)$8.930.61%
  • stellarStellar(XLM)$0.1999694.20%
  • uniswapUniswap(UNI)$8.83-0.80%
  • bitcoin-cashBitcoin Cash(BCH)$256.542.94%
  • Ethena USDeEthena USDe(USDE)$1.00-0.01%
  • nearNEAR Protocol(NEAR)$3.61-1.97%
  • daiDai(DAI)$1.000.00%
  • litecoinLitecoin(LTC)$57.983.63%
  • CantonCanton(CC)$0.1124012.92%
  • USD1USD1(USD1)$1.000.00%
  • avalanche-2Avalanche(AVAX)$9.7120.45%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.401.72%
  • hedera-hashgraphHedera(HBAR)$0.0817994.58%
  • suiSui(SUI)$0.867.47%
  • MemeCoreMemeCore(M)$1.5113.09%
  • shiba-inuShiba Inu(SHIB)$0.0000063.08%
  • Global DollarGlobal Dollar(USDG)$1.000.00%
  • BittensorBittensor(TAO)$269.929.29%
  • crypto-com-chainCronos(CRO)$0.0601702.15%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.03%
  • tether-goldTether Gold(XAUT)$4,374.23-0.22%
  • okbOKB(OKB)$119.473.70%
  • Circle USYCCircle USYC(USYC)$1.140.00%
  • Ripple USDRipple USD(RLUSD)$1.00-0.01%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.14-0.26%
  • aaveAave(AAVE)$143.404.15%
  • OndoOndo(ONDO)$0.43753910.49%
  • mantleMantle(MNT)$0.634.44%
  • AsterAster(ASTER)$0.762.69%
  • EthenaEthena(ENA)$0.20418424.55%
  • Pump.funPump.fun(PUMP)$0.004166-2.48%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Solving the ‘Lost-in-the-Middle’ Problem in Large Language Models: A Breakthrough in Attention Calibration

June 27, 2024
in AI & Technology
Reading Time: 4 mins read
A A
Solving the ‘Lost-in-the-Middle’ Problem in Large Language Models: A Breakthrough in Attention Calibration
ShareShareShareShareShare

Despite the significant advancement in large language models (LLMs), LLMs often need help with long contexts, especially where information is spread across the complete text. LLMs can now handle long stretches of text as input, but they still face the “lost in the middle” problem. The ability of LLMs to accurately find and use information within that context weakens as the relevant information gets further away from the beginning or end. In other words, they tend to focus on the information at the beginning and end, neglecting what’s sandwiched in between.

Researchers from the University of Washington, MIT, Google Cloud AI Research, and Google collaborated to address the “lost-in-the-middle” issue. Despite being trained to handle large input contexts, LLMs exhibit an inherent attention bias that results in higher attention to tokens at the beginning and end of the input. This leads to reduced accuracy when critical information is situated in the middle. The study aims to mitigate the positional bias by allowing the model to attend to contexts based on their relevance, regardless of their position within the input sequence.

YOU MAY ALSO LIKE

How To Block And Unblock A Number On Your Android Phone

Google Gemini Also Escaped Its Testing Environment And Hacked Three Companies

Current methods to tackle the lost-in-the-middle problem often involve re-ranking the relevance of documents and repositioning the most pertinent ones at the beginning or end of the input sequence. However, these methods usually require additional supervision or fine-tuning and do not fundamentally address the LLMs’ ability to utilize mid-sequence information effectively. To overcome this limitation, the researchers propose a novel calibration mechanism called “found-in-the-middle.” 

The researchers first establish that the lost-in-the-middle issue is linked to a U-shaped attention bias. The inherent bias persists even when the order of documents is randomized. To verify their hypothesis, the authors intervene by adjusting the attention distribution to reflect relevance rather than position. They quantify this positional bias by measuring changes in attention as they vary the position of a fixed context within the input prompt.

The proposed “found-in-the-middle” mechanism disentangles positional bias from the attention scores, enabling a more accurate reflection of the documents’ relevance. This calibration involves estimating the bias and adjusting attention scores accordingly. Experiments demonstrate that the calibrated attention significantly improves the model’s ability to locate relevant information within long contexts, leading to better performance in retrieval-augmented generation (RAG) tasks. 

The researchers operationalize this calibration mechanism to improve overall RAG performance. The attention calibration method consistently outperforms uncalibrated models across various tasks and models, including those with different context window lengths. The approach yields improvements of up to 15 percentage points on the NaturalQuestions dataset. Additionally, combining attention calibration with existing reordering methods further enhances model performance, demonstrating the effectiveness and complementarity of the proposed solution.

In conclusion, the proposed mechanism effectively identifies and addresses the lost-in-the-middle phenomenon by linking it to intrinsic positional attention bias in LLMs. The found-in-the-middle mechanism successfully mitigates this bias, enabling the models to attend to relevant contexts more faithfully and significantly improving performance in long-context utilization tasks. This advancement opens new ways for enhancing LLM attention mechanisms and their application in various user-facing applications.


Check out the Paper. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter. 

Join our Telegram Channel and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our 45k+ ML SubReddit


🚀 Create, edit, and augment tabular data with the first compound AI system, Gretel Navigator, now generally available! [Advertisement]


Pragati Jhunjhunwala is a consulting intern at MarktechPost. She is currently pursuing her B.Tech from the Indian Institute of Technology(IIT), Kharagpur. She is a tech enthusiast and has a keen interest in the scope of software and data science applications. She is always reading about the developments in different field of AI and ML.

[Announcing Gretel Navigator] Create, edit, and augment tabular data with the first compound AI system trusted by EY, Databricks, Google, and Microsoft


Credit: Source link

ShareTweetSendSharePin

Related Posts

How To Block And Unblock A Number On Your Android Phone
AI & Technology

How To Block And Unblock A Number On Your Android Phone

September 19, 2026
Google Gemini Also Escaped Its Testing Environment And Hacked Three Companies
AI & Technology

Google Gemini Also Escaped Its Testing Environment And Hacked Three Companies

September 19, 2026
What Is AI Agent Memory? Short-Term, Long-Term, Episodic, and Semantic Memory Explained – Unite.AI
AI & Technology

What Is AI Agent Memory? Short-Term, Long-Term, Episodic, and Semantic Memory Explained – Unite.AI

September 19, 2026
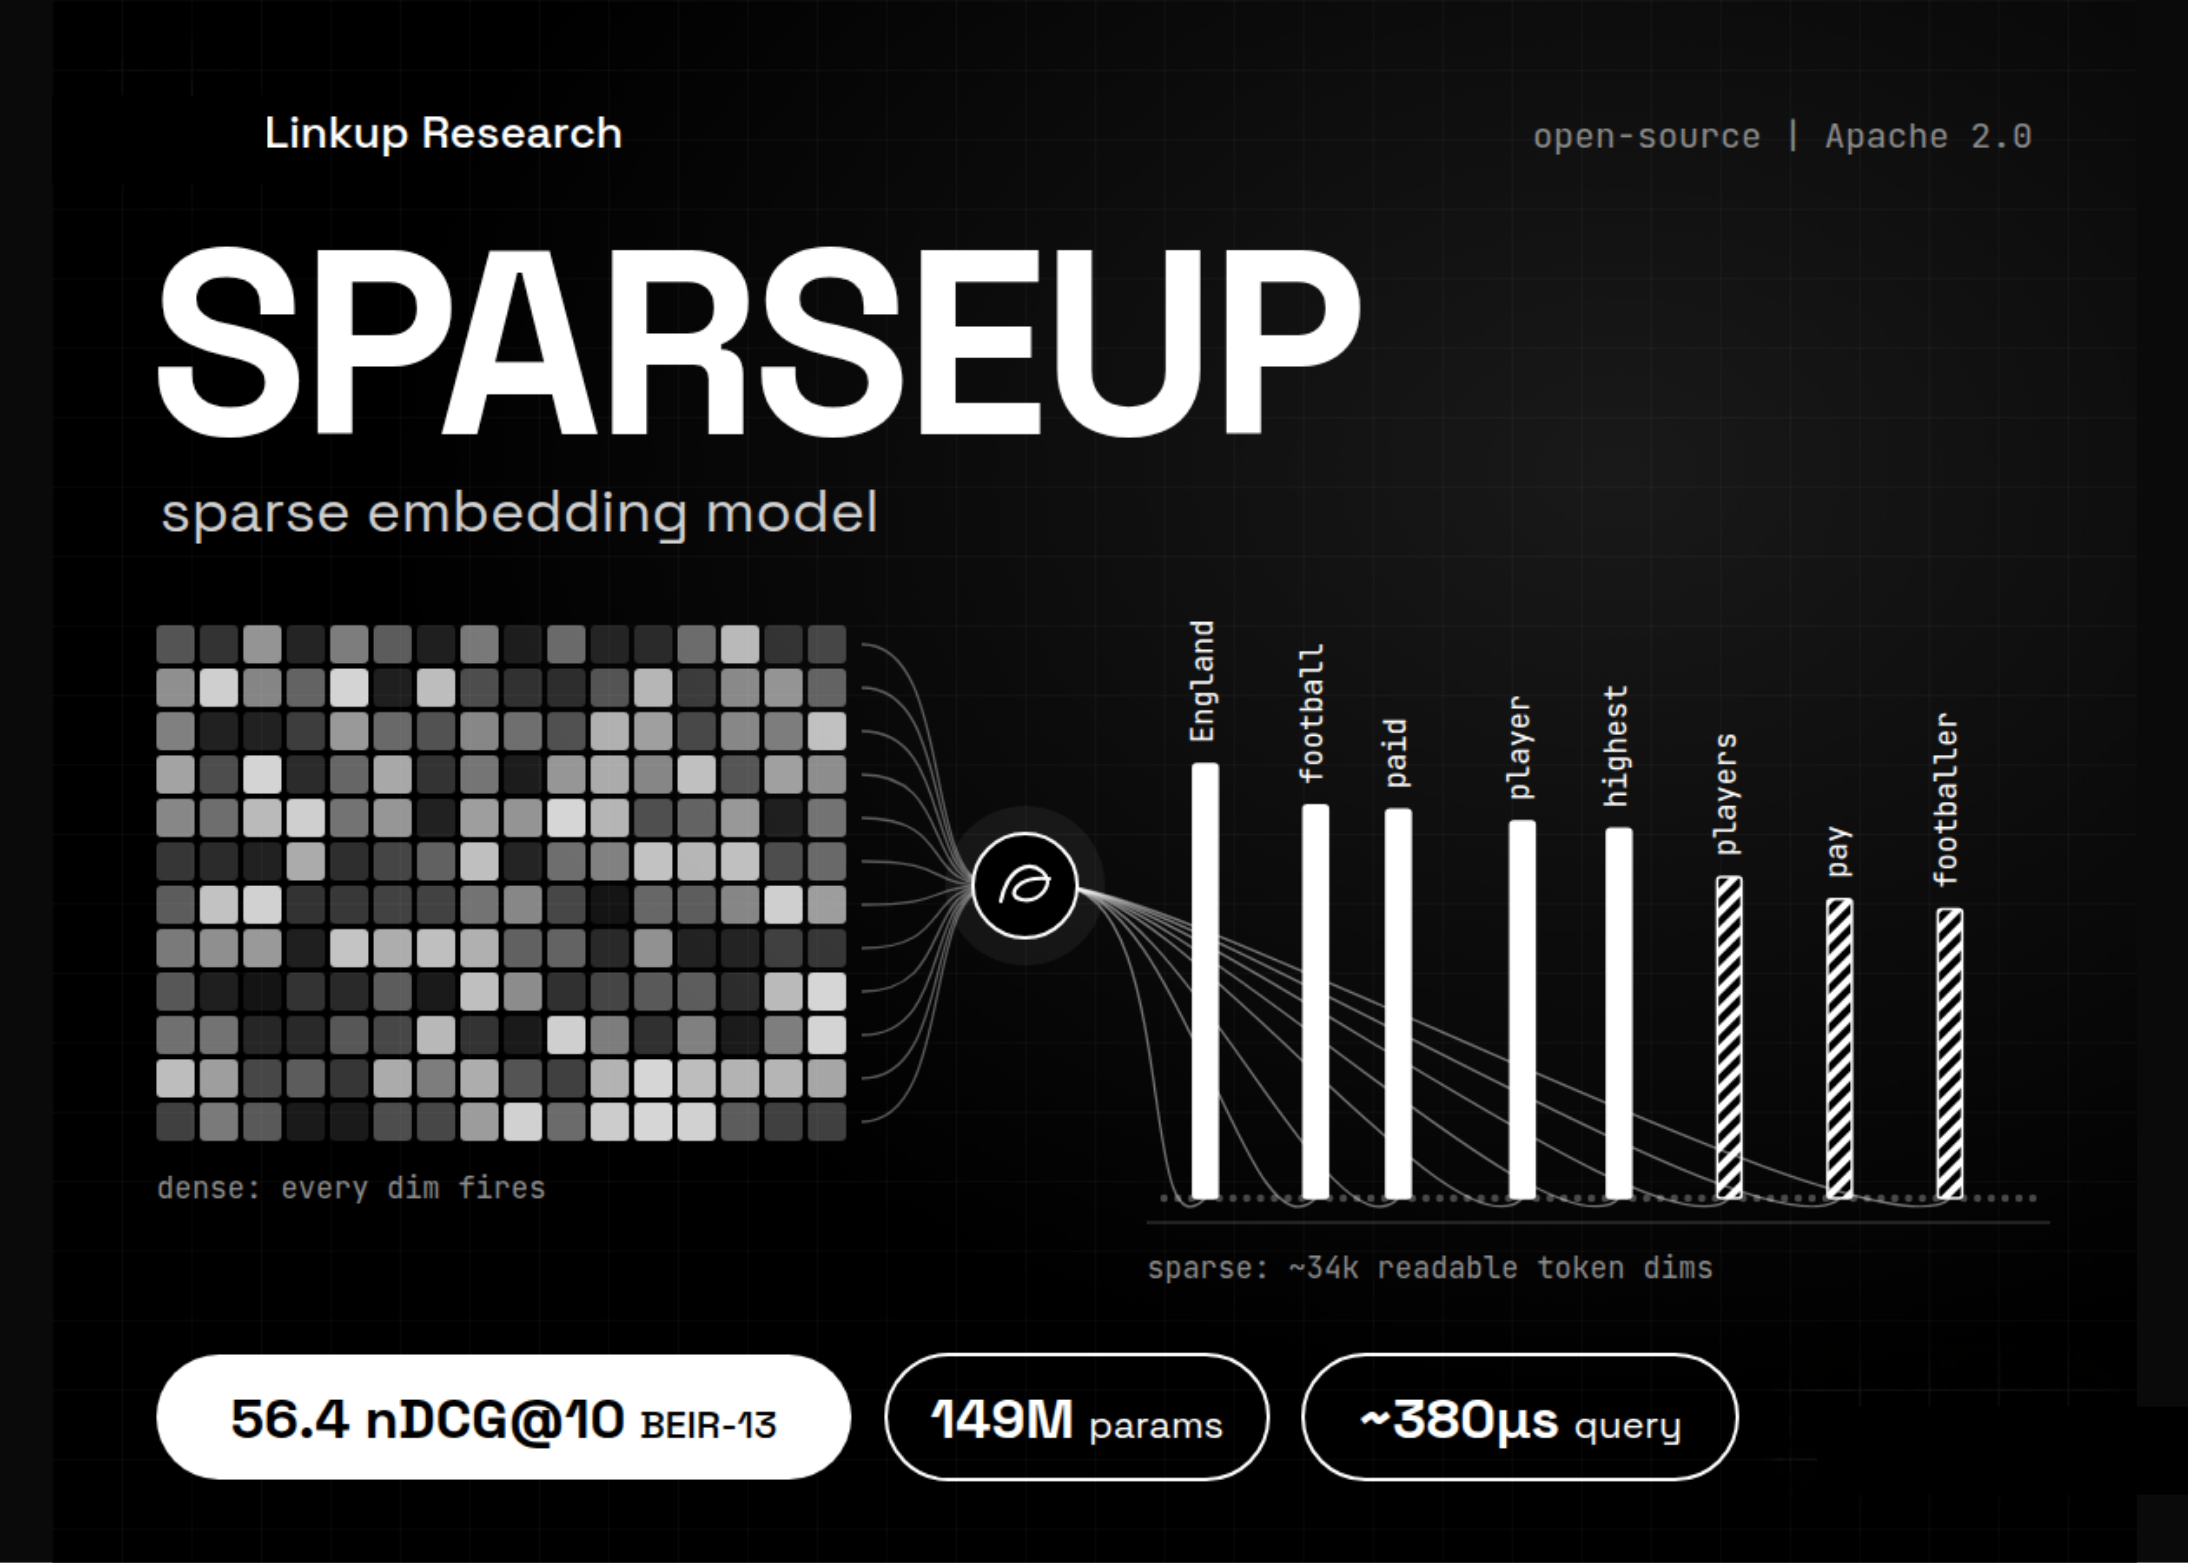
Linkup Research Releases SPARSEUP: A 149M-Parameter Open-Source Sparse Embedding Model
AI & Technology

Linkup Research Releases SPARSEUP: A 149M-Parameter Open-Source Sparse Embedding Model

September 19, 2026
Next Post
Chipotle’s stock split is the largest in history…

Chipotle's stock split is the largest in history...

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Wall St set to open higher as easing oil prices boost Fed hike relief – reuters.com

Wall St set to open higher as easing oil prices boost Fed hike relief – reuters.com

September 17, 2026
Man saves child from running into traffic in Mexico

Man saves child from running into traffic in Mexico

September 16, 2026
Dashcam video shows arrest after police pursuit

Dashcam video shows arrest after police pursuit

September 18, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!