• bitcoinBitcoin(BTC)$81,850.000.88%
  • ethereumEthereum(ETH)$2,649.451.72%
  • tetherTether(USDT)$1.000.00%
  • binancecoinBNB(BNB)$766.880.87%
  • rippleXRP(XRP)$1.433.24%
  • usd-coinUSDC(USDC)$1.000.00%
  • solanaSolana(SOL)$111.70-0.30%
  • tronTRON(TRX)$0.338921-0.25%
  • zcashZcash(ZEC)$1,512.222.83%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.030.14%
  • HyperliquidHyperliquid(HYPE)$93.001.65%
  • dogecoinDogecoin(DOGE)$0.0893821.50%
  • moneroMonero(XMR)$570.41-0.93%
  • whitebitWhiteBIT Coin(WBT)$83.570.52%
  • RainRain(RAIN)$0.0139565.51%
  • USDSUSDS(USDS)$1.00-0.03%
  • chainlinkChainlink(LINK)$12.623.46%
  • cardanoCardano(ADA)$0.2286383.88%
  • leo-tokenLEO Token(LEO)$8.930.65%
  • stellarStellar(XLM)$0.1986163.20%
  • uniswapUniswap(UNI)$8.890.28%
  • bitcoin-cashBitcoin Cash(BCH)$255.621.79%
  • Ethena USDeEthena USDe(USDE)$1.00-0.01%
  • nearNEAR Protocol(NEAR)$3.60-2.14%
  • daiDai(DAI)$1.000.00%
  • litecoinLitecoin(LTC)$58.023.14%
  • CantonCanton(CC)$0.1118432.34%
  • USD1USD1(USD1)$1.000.01%
  • avalanche-2Avalanche(AVAX)$9.6519.04%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.391.26%
  • hedera-hashgraphHedera(HBAR)$0.0815453.19%
  • suiSui(SUI)$0.855.41%
  • Global DollarGlobal Dollar(USDG)$1.00-0.01%
  • shiba-inuShiba Inu(SHIB)$0.0000060.70%
  • BittensorBittensor(TAO)$271.688.36%
  • MemeCoreMemeCore(M)$1.33-3.45%
  • crypto-com-chainCronos(CRO)$0.0600961.42%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.03%
  • tether-goldTether Gold(XAUT)$4,373.80-0.11%
  • Circle USYCCircle USYC(USYC)$1.140.00%
  • okbOKB(OKB)$119.382.63%
  • Ripple USDRipple USD(RLUSD)$1.00-0.01%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.09%
  • aaveAave(AAVE)$142.672.78%
  • OndoOndo(ONDO)$0.4317718.11%
  • mantleMantle(MNT)$0.644.26%
  • EthenaEthena(ENA)$0.20440223.61%
  • AsterAster(ASTER)$0.761.31%
  • Pump.funPump.fun(PUMP)$0.004123-4.29%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Key Metrics for Evaluating Large Language Models (LLMs)

June 20, 2024
in AI & Technology
Reading Time: 4 mins read
A A
Key Metrics for Evaluating Large Language Models (LLMs)
ShareShareShareShareShare

Evaluating Large Language Models (LLMs) is a challenging problem in language modeling, as real-world problems are complex and variable. Conventional benchmarks frequently fail to fully represent LLMs’ all-encompassing performance. A recent LinkedIn post has emphasized a number of important measures that are essential to comprehend how well new models function, which are as follows.

MixEval

    Achieving a balance between thorough user inquiries and effective grading systems is necessary for evaluating LLMs. Conventional standards based on ground truth and LLM-as-judge benchmarks encounter difficulties such as biases in grading and possible contamination over time. 

    MixEval solves these problems by combining real-world user inquiries with commercial benchmarks. This technique builds a solid evaluation framework by comparing web-mined questions with comparable queries from current benchmarks. A variation of this approach, MixEval-Hard, focuses on more difficult queries and provides more chances for model enhancement.

    Because of its unbiased question distribution and grading system, MixEval has significant advantages over Chatbot Arena, as seen by its 0.96 model ranking correlation. It also takes 6% less time and money than MMLU, making it quick and economical. Its usefulness is further increased by its dynamic evaluation capabilities, which are backed by a steady and quick data refresh pipeline.

    IFEval (Instructional Framework Standardisation and Evaluation)

      The ability of LLMs to obey orders in natural language is one of their fundamental skills. However, the absence of standardized criteria has made evaluating this skill difficult. While LLM-based auto-evaluations can be biased or constrained by the evaluator’s skills, human evaluations are frequently costly and time-consuming.

      A simple and repeatable benchmark called IFEval assesses this important part of LLMs and emphasizes verifiable instructions. The benchmark consists of about 500 prompts with one or more instructions apiece and 25 different kinds of verifiable instructions. IFEval offers quantifiable and easily understood indicators that facilitate assessing model performance in practical situations.

      Arena-Hard

        An automatic evaluation tool for instruction-tuned LLMs is Arena-Hard-Auto-v0.1. It consists of 500 hard user questions and compares model answers to a baseline model, usually GPT-4-031, using GPT-4-Turbo as a judge. Although Chatbot Arena Category Hard is comparable, Arena-Hard-Auto uses automatic judgment to provide a quicker and more affordable solution.

        Of the widely used open-ended LLM benchmarks, this one has the strongest correlation and separability with Chatbot Arena. It is a great tool for forecasting model performance in Chatbot Arena, which is very helpful for researchers who want to rapidly and effectively assess how well their models perform in real-world scenarios.

        MMLU (Massive Multitask Language Understanding)

          The goal of MMLU is to assess a model’s multitask accuracy in a variety of fields, such as computer science, law, US history, and rudimentary arithmetic. This is a 57-item test that requires models to have a broad understanding of the world and the ability to solve problems.

          On this benchmark, most models still perform at close to random-chance accuracy despite recent improvements, indicating a large amount of space for improvement. With MMLU, these flaws can be found, and a thorough assessment of a model’s professional and academic understanding can be obtained.

          GSM8K

            Modern language models often find multi-step mathematical reasoning difficult to handle. GSM8K addresses this challenge by offering a collection of 8.5K excellent, multilingual elementary school arithmetic word problems. On this dataset, not even the biggest transformer models are able to obtain good results.

            Researchers suggest training verifiers to assess the accuracy of model completions to enhance performance. Verification dramatically improves performance on GSM8K by producing several candidate solutions and choosing the best-ranked one. This strategy supports studies that enhance models’ capacity for mathematical reasoning.

            YOU MAY ALSO LIKE

            How To Block And Unblock A Number On Your Android Phone

            Google Gemini Also Escaped Its Testing Environment And Hacked Three Companies

            HumanEval

              To assess Python code-writing skills, HumanEval has Codex, a GPT language model optimized on publicly accessible code from GitHub. Codex outperforms GPT-3 and GPT-J, solving 28.8% of the issues on the HumanEval benchmark. With 100 samples for each problem, repeated sampling from the model solves 70.2% of the problems, resulting in even better performance. 

              This benchmark sheds light on the advantages and disadvantages of code generation models, offering insightful information about their potential and areas for development. HumanEval uses custom programming tasks and unit tests to assess code generation models.


              Note: This article is inspired by this LinkedIn post.


              Tanya Malhotra is a final year undergrad from the University of Petroleum & Energy Studies, Dehradun, pursuing BTech in Computer Science Engineering with a specialization in Artificial Intelligence and Machine Learning.
              She is a Data Science enthusiast with good analytical and critical thinking, along with an ardent interest in acquiring new skills, leading groups, and managing work in an organized manner.

              🐝 Join the Fastest Growing AI Research Newsletter Read by Researchers from Google + NVIDIA + Meta + Stanford + MIT + Microsoft and many others…

Credit: Source link

ShareTweetSendSharePin

Related Posts

How To Block And Unblock A Number On Your Android Phone
AI & Technology

How To Block And Unblock A Number On Your Android Phone

September 19, 2026
Google Gemini Also Escaped Its Testing Environment And Hacked Three Companies
AI & Technology

Google Gemini Also Escaped Its Testing Environment And Hacked Three Companies

September 19, 2026
What Is AI Agent Memory? Short-Term, Long-Term, Episodic, and Semantic Memory Explained – Unite.AI
AI & Technology

What Is AI Agent Memory? Short-Term, Long-Term, Episodic, and Semantic Memory Explained – Unite.AI

September 19, 2026
Linkup Research Releases SPARSEUP: A 149M-Parameter Open-Source Sparse Embedding Model
AI & Technology

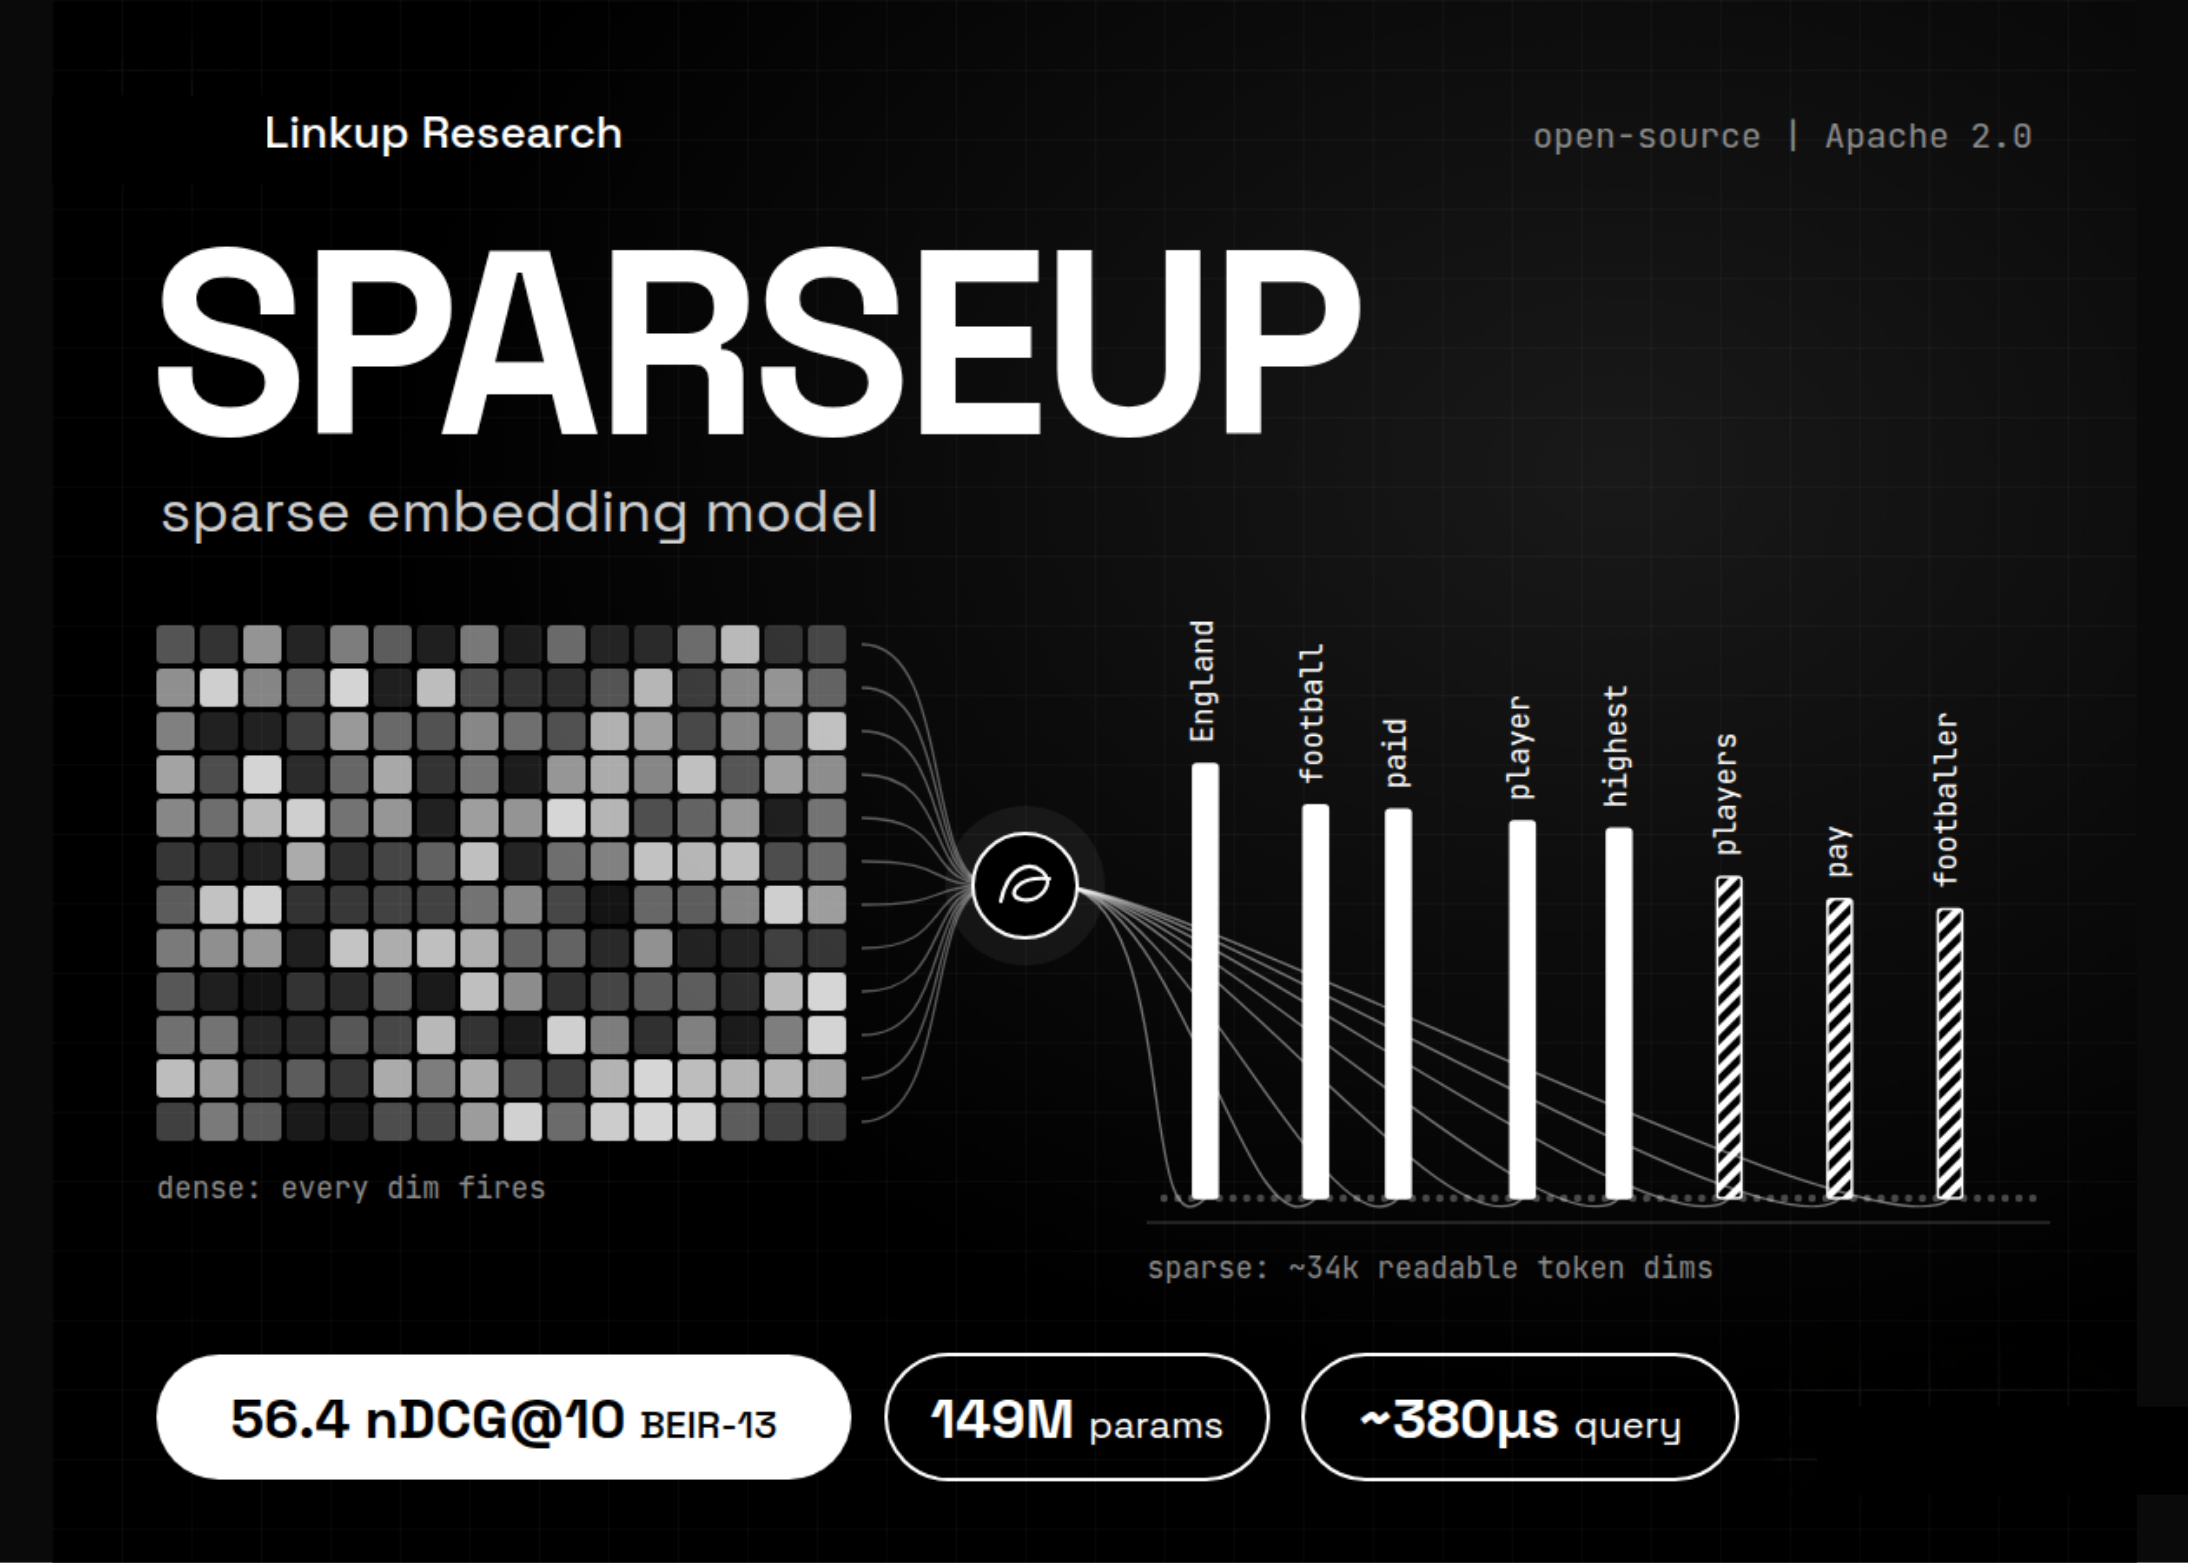
Linkup Research Releases SPARSEUP: A 149M-Parameter Open-Source Sparse Embedding Model

September 19, 2026
Next Post
This Morning’s Top Headlines – Dec. 4

This Morning’s Top Headlines – Dec. 4

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Stock Market Today: Dow Slip; Oil Prices Surge; Nvdia Stock Down — Live Updates – WSJ

Stock Market Today: Dow Slip; Oil Prices Surge; Nvdia Stock Down — Live Updates – WSJ

September 14, 2026
Kornacki: Trump’s 2024 coalition shows ‘warning signs’ in Texas as GOP midterm convention wraps

Kornacki: Trump’s 2024 coalition shows ‘warning signs’ in Texas as GOP midterm convention wraps

September 14, 2026
Mamdani to release documents related to 9/11 health impacts

Mamdani to release documents related to 9/11 health impacts

September 15, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!