• bitcoinBitcoin(BTC)$81,726.001.03%
  • ethereumEthereum(ETH)$2,650.582.09%
  • tetherTether(USDT)$1.000.00%
  • binancecoinBNB(BNB)$767.791.27%
  • rippleXRP(XRP)$1.444.12%
  • usd-coinUSDC(USDC)$1.000.00%
  • solanaSolana(SOL)$112.160.17%
  • tronTRON(TRX)$0.3392950.21%
  • zcashZcash(ZEC)$1,493.813.26%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.030.45%
  • HyperliquidHyperliquid(HYPE)$93.142.19%
  • dogecoinDogecoin(DOGE)$0.0908473.70%
  • moneroMonero(XMR)$567.73-0.19%
  • RainRain(RAIN)$0.0139894.16%
  • whitebitWhiteBIT Coin(WBT)$83.390.49%
  • USDSUSDS(USDS)$1.00-0.03%
  • chainlinkChainlink(LINK)$12.623.99%
  • cardanoCardano(ADA)$0.2305035.37%
  • leo-tokenLEO Token(LEO)$8.930.72%
  • stellarStellar(XLM)$0.2000974.05%
  • uniswapUniswap(UNI)$8.81-0.15%
  • bitcoin-cashBitcoin Cash(BCH)$256.323.01%
  • Ethena USDeEthena USDe(USDE)$1.000.00%
  • nearNEAR Protocol(NEAR)$3.62-2.56%
  • daiDai(DAI)$1.00-0.01%
  • litecoinLitecoin(LTC)$57.953.40%
  • CantonCanton(CC)$0.1127303.43%
  • USD1USD1(USD1)$1.000.01%
  • avalanche-2Avalanche(AVAX)$9.7620.90%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.391.45%
  • hedera-hashgraphHedera(HBAR)$0.0820794.85%
  • suiSui(SUI)$0.878.26%
  • MemeCoreMemeCore(M)$1.4911.71%
  • shiba-inuShiba Inu(SHIB)$0.0000064.02%
  • Global DollarGlobal Dollar(USDG)$1.00-0.01%
  • BittensorBittensor(TAO)$268.708.20%
  • crypto-com-chainCronos(CRO)$0.0602612.10%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.02%
  • tether-goldTether Gold(XAUT)$4,374.47-0.23%
  • Circle USYCCircle USYC(USYC)$1.140.00%
  • okbOKB(OKB)$119.433.45%
  • Ripple USDRipple USD(RLUSD)$1.00-0.01%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.03%
  • aaveAave(AAVE)$143.413.85%
  • OndoOndo(ONDO)$0.4371649.92%
  • mantleMantle(MNT)$0.634.41%
  • AsterAster(ASTER)$0.772.50%
  • EthenaEthena(ENA)$0.20356924.04%
  • Pump.funPump.fun(PUMP)$0.004188-2.09%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

This AI Paper from China Proposes a Novel dReLU-based Sparsification Method that Increases Model Sparsity to 90% while Maintaining Performance, Achieving a 2-5× Speedup in Inference

June 15, 2024
in AI & Technology
Reading Time: 5 mins read
A A
This AI Paper from China Proposes a Novel dReLU-based Sparsification Method that Increases Model Sparsity to 90% while Maintaining Performance, Achieving a 2-5× Speedup in Inference
ShareShareShareShareShare

Large Language Models (LLMs) have made substantial progress in the field of Natural Language Processing (NLP). By scaling up the number of model parameters, LLMs show higher performance in tasks such as code generation and question answering. However, most modern LLMs, like Mistral, Gemma, and Llama, are dense models, which means that during inference, they use every parameter. Even while this dense architecture is strong, it requires a lot of processing power, which makes it difficult to create AI that is both affordable and widely available.

Conditional computation has been studied as a solution to increase efficiency. By only turning on some of the model’s neurons in response to the input, this technique cuts down on pointless calculations. Conditional computation can be implemented using two primary methods. The Mixture-of-Experts (MoE) strategy is the first method. By predefining constraints on the model’s structure prior to training, such as determining the number of experts to activate for a particular input, MoE introduces conditional computation. This expert routing technique increases efficiency by selectively activating specific model components without raising computing complexity. 

The second method uses activation functions such as ReLU’s intrinsic sparsity. For non-positive inputs, ReLU inherently produces zero, resulting in many dormant neurons that provide nothing to the computation. This inherent sparsity can improve inference efficiency. 

Many LLMs, like activation functions like GELU and Swish, do not encourage as much sparsity and are more difficult to accelerate using conditional computation despite their efficiency advantages. ReLUfication, a technique that substitutes ReLU for the original activation function during pretraining, has been presented as a solution to this problem. However, performance may suffer, and this approach frequently falls short of achieving the appropriate degrees of sparsity.

There are two primary reasons for the inadequacies of current ReLUfication techniques. First, substituting ReGLU for SwiGLU alone only slightly improves sparsity, indicating the necessity for more significant architectural adjustments. Second, the model’s skills may not fully recover due to the small amount and limited variety of pretraining data.

In a recent study, a team of researchers from China has suggested dReLU, a new activation function that tackles the inefficiencies of negative activations in the GLU component, as a solution to these problems. The tests on small-scale LLMs pretrained with dReLU in addition to SwiGLU have demonstrated that models with dReLU perform on par with SwiGLU models, with sparsity levels approaching 90%. The team has improved the ReLUfication process by gathering heterogeneous pretraining data from other sources, such as code, web, and mathematical datasets.

The team has also performed a sparsity analysis on MoE-based LLMs and discovered that the experts’ feed-forward networks show sparse activation that is comparable to dense LLMs. This observation suggests that combining MoE approaches with ReLU-induced sparsity may yield additional efficiency advantages.

The researchers have created TurboSparse-Mistral-47B and TurboSparse-Mixtral-47B by applying this method to the Mistral-7B and Mixtral-47B models to validate the methodology. The rigorous tests have shown that the performance of these improved models is not only comparable to that of their original versions but frequently better. The TurboSparse-Mixtral-47B model enhanced sparsity from 75% to 97% while greatly reducing processing requirements during inference, and the TurboSparse-Mistral-7B model achieved an average FFN sparsity of 90% while improving capabilities.

Merging these models with PowerInfer demonstrated an average 2.83× acceleration in the generation tasks, verifying the effectiveness of the suggested approach in augmenting both productivity and performance.

The team has summarized their primary contributions as follows.

  1. dReLU function has been introduced, which enhances activation sparsity. Only 150B tokens, or less than 1% of the usual pretraining tokens (about 15T tokens) have been used in this technique.
  1. The release of TurboSparse-Mistral7B and TurboSparse-Mixtral-47B models has been announced. These sparsely activated models demonstrate superior performance compared to their original, dense versions.
  1. Evaluation has revealed that a 2-5× speedup can be achieved with these models for practical inference. With TurboSparse-Mixtral-47B, up to 10 tokens can be accomplished without the need for a GPU.

Check out the Paper and Models. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter. 

Join our Telegram Channel and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our 44k+ ML SubReddit


YOU MAY ALSO LIKE

How To Block And Unblock A Number On Your Android Phone

Google Gemini Also Escaped Its Testing Environment And Hacked Three Companies

Tanya Malhotra is a final year undergrad from the University of Petroleum & Energy Studies, Dehradun, pursuing BTech in Computer Science Engineering with a specialization in Artificial Intelligence and Machine Learning.
She is a Data Science enthusiast with good analytical and critical thinking, along with an ardent interest in acquiring new skills, leading groups, and managing work in an organized manner.


🐝 Join the Fastest Growing AI Research Newsletter Read by Researchers from Google + NVIDIA + Meta + Stanford + MIT + Microsoft and many others…


Credit: Source link

ShareTweetSendSharePin

Related Posts

How To Block And Unblock A Number On Your Android Phone
AI & Technology

How To Block And Unblock A Number On Your Android Phone

September 19, 2026
Google Gemini Also Escaped Its Testing Environment And Hacked Three Companies
AI & Technology

Google Gemini Also Escaped Its Testing Environment And Hacked Three Companies

September 19, 2026
What Is AI Agent Memory? Short-Term, Long-Term, Episodic, and Semantic Memory Explained – Unite.AI
AI & Technology

What Is AI Agent Memory? Short-Term, Long-Term, Episodic, and Semantic Memory Explained – Unite.AI

September 19, 2026
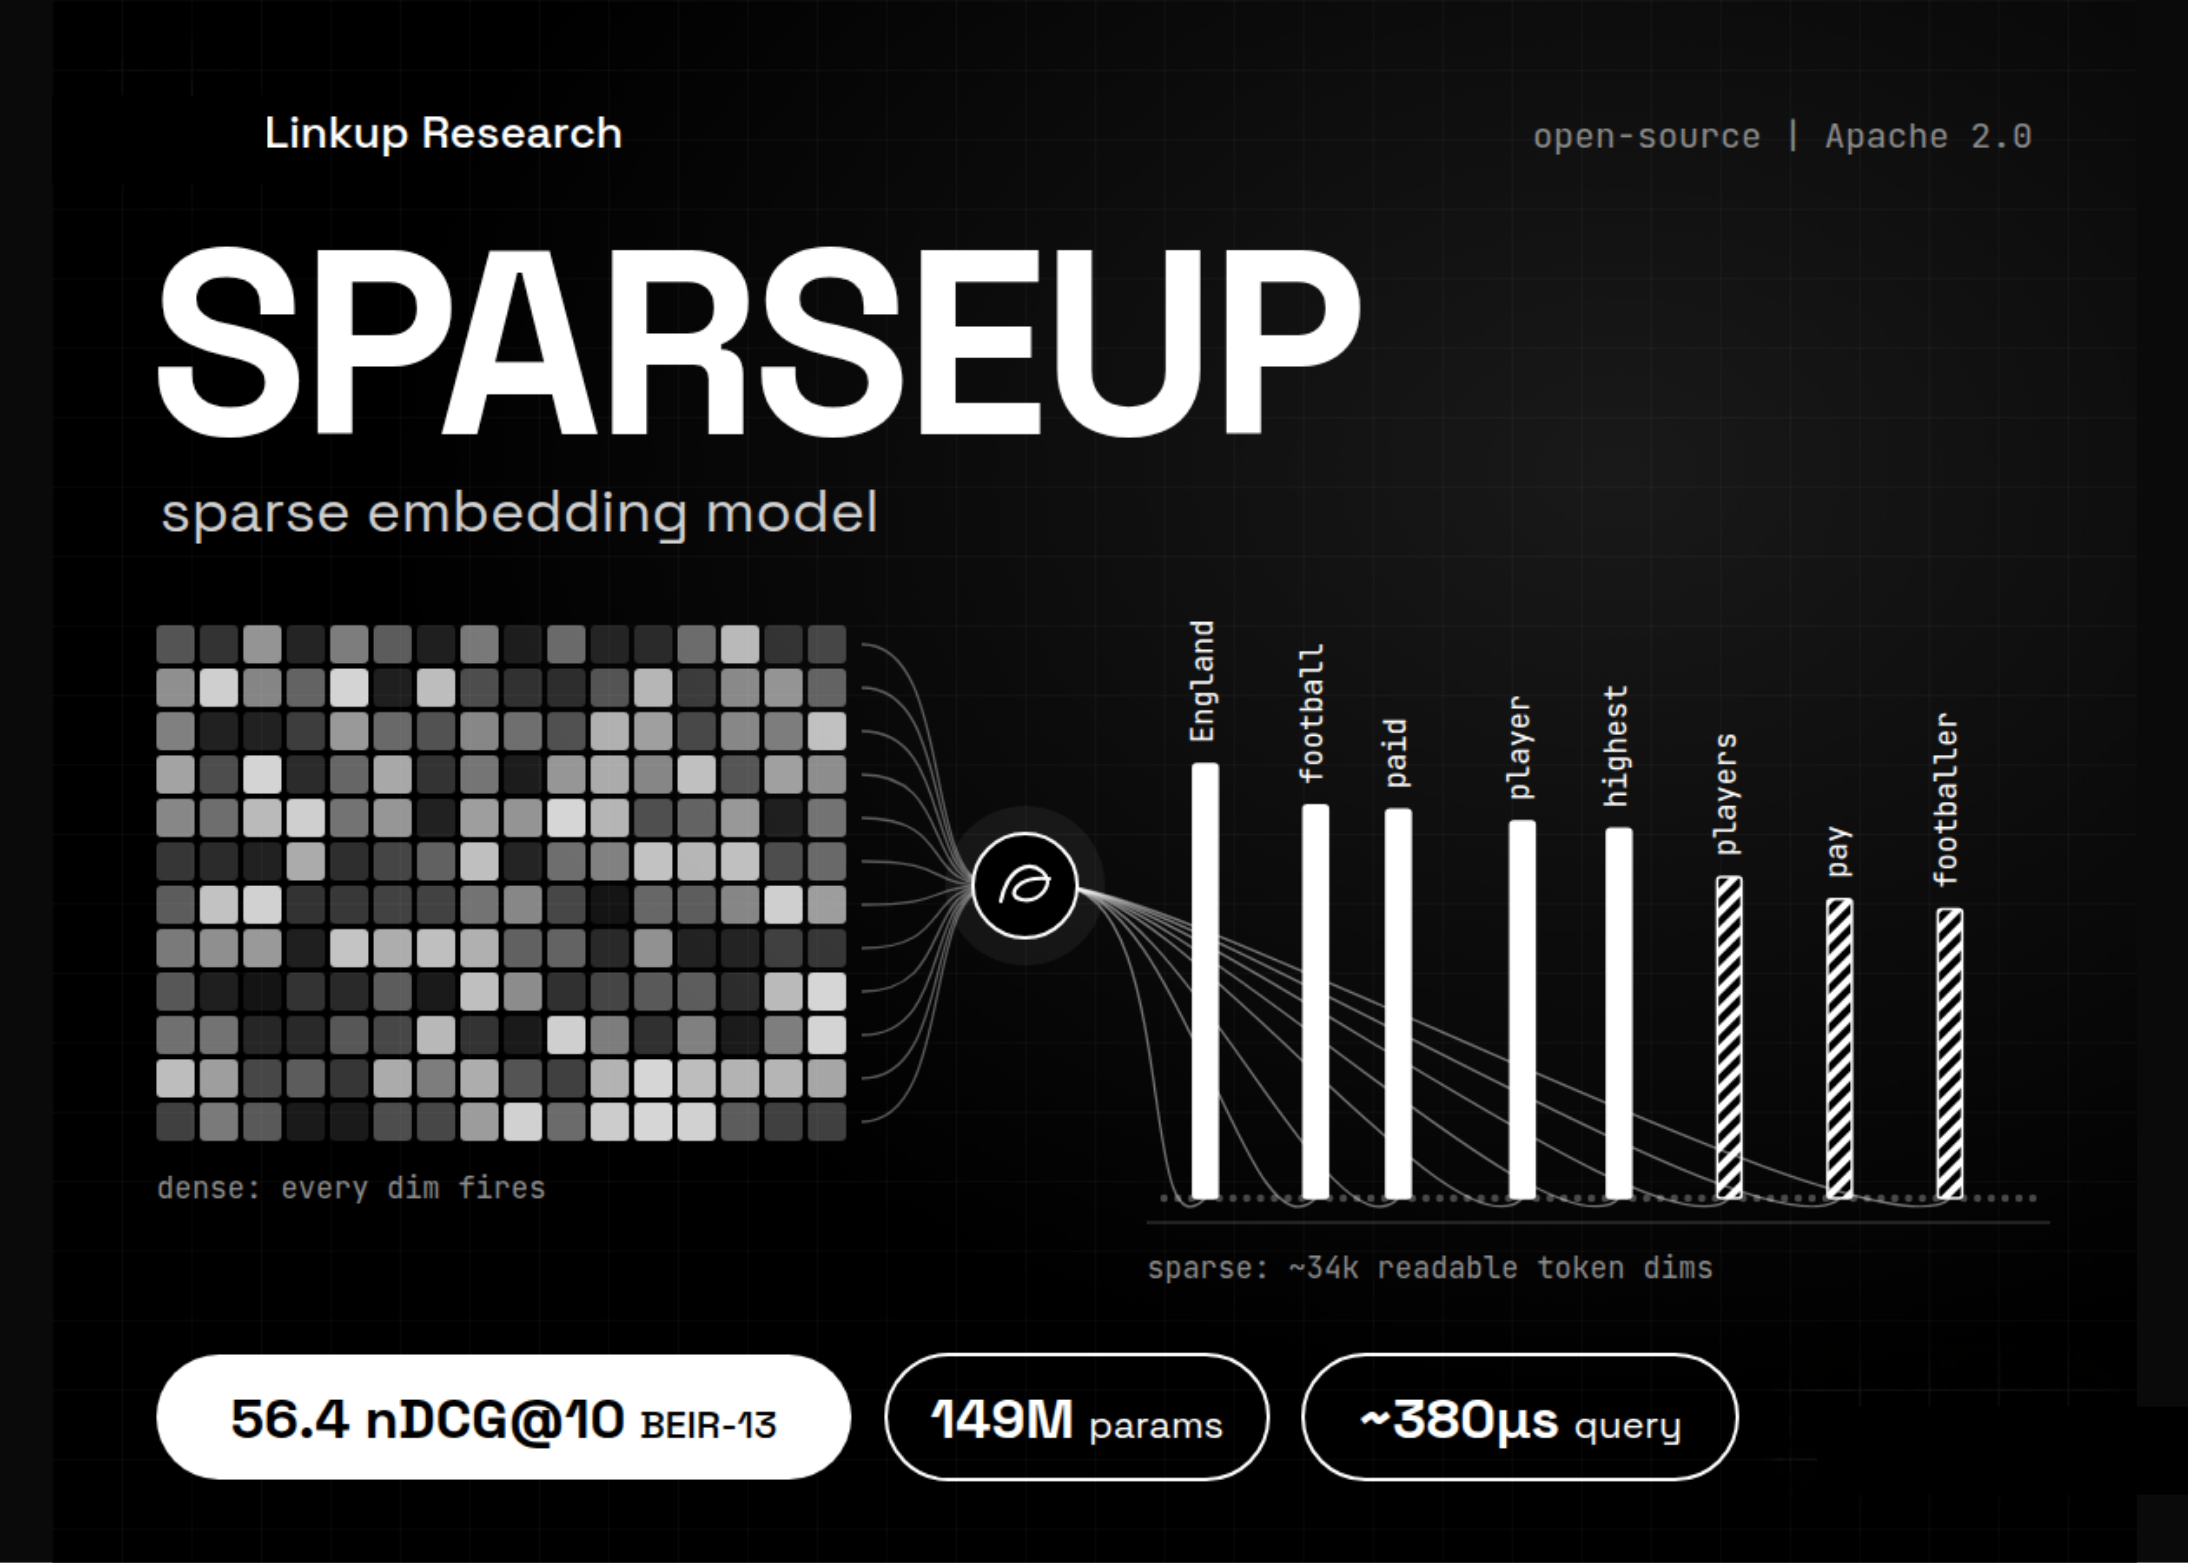
Linkup Research Releases SPARSEUP: A 149M-Parameter Open-Source Sparse Embedding Model
AI & Technology

Linkup Research Releases SPARSEUP: A 149M-Parameter Open-Source Sparse Embedding Model

September 19, 2026
Next Post
Supreme Court takes up abortion pill case

Supreme Court takes up abortion pill case

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Rhode Island Gov. McKee loses primary to Foulkes

Rhode Island Gov. McKee loses primary to Foulkes

September 14, 2026
U.K. government condemns masked protesters who blocked Dover port

U.K. government condemns masked protesters who blocked Dover port

September 17, 2026
U.S. economy adds 162,000 jobs in August, unemployment rate at 4.1%

U.S. economy adds 162,000 jobs in August, unemployment rate at 4.1%

September 17, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!