• bitcoinBitcoin(BTC)$80,998.00-0.25%
  • ethereumEthereum(ETH)$2,625.57-0.40%
  • tetherTether(USDT)$1.00-0.01%
  • binancecoinBNB(BNB)$760.29-0.55%
  • rippleXRP(XRP)$1.421.10%
  • usd-coinUSDC(USDC)$1.00-0.01%
  • solanaSolana(SOL)$110.74-2.43%
  • tronTRON(TRX)$0.3392450.18%
  • zcashZcash(ZEC)$1,470.31-1.69%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.00-2.99%
  • HyperliquidHyperliquid(HYPE)$91.23-0.52%
  • dogecoinDogecoin(DOGE)$0.088023-0.25%
  • moneroMonero(XMR)$540.67-5.55%
  • whitebitWhiteBIT Coin(WBT)$82.78-0.72%
  • RainRain(RAIN)$0.0137802.07%
  • USDSUSDS(USDS)$1.00-0.03%
  • chainlinkChainlink(LINK)$12.410.31%
  • cardanoCardano(ADA)$0.2270801.16%
  • leo-tokenLEO Token(LEO)$8.90-0.04%
  • stellarStellar(XLM)$0.1973451.71%
  • uniswapUniswap(UNI)$8.59-5.22%
  • bitcoin-cashBitcoin Cash(BCH)$251.96-1.53%
  • Ethena USDeEthena USDe(USDE)$1.00-0.02%
  • nearNEAR Protocol(NEAR)$3.53-3.89%
  • daiDai(DAI)$1.00-0.02%
  • litecoinLitecoin(LTC)$57.520.45%
  • CantonCanton(CC)$0.110013-0.94%
  • USD1USD1(USD1)$1.00-0.02%
  • avalanche-2Avalanche(AVAX)$9.6616.79%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.380.42%
  • hedera-hashgraphHedera(HBAR)$0.0809241.35%
  • suiSui(SUI)$0.865.37%
  • MemeCoreMemeCore(M)$1.5114.21%
  • Global DollarGlobal Dollar(USDG)$1.00-0.01%
  • shiba-inuShiba Inu(SHIB)$0.0000050.01%
  • BittensorBittensor(TAO)$261.164.83%
  • crypto-com-chainCronos(CRO)$0.059205-1.41%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.03%
  • tether-goldTether Gold(XAUT)$4,372.60-0.06%
  • Circle USYCCircle USYC(USYC)$1.140.00%
  • okbOKB(OKB)$117.991.06%
  • Ripple USDRipple USD(RLUSD)$1.00-0.01%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.14-0.37%
  • aaveAave(AAVE)$140.880.94%
  • AsterAster(ASTER)$0.771.04%
  • mantleMantle(MNT)$0.62-0.51%
  • OndoOndo(ONDO)$0.4165194.51%
  • EthenaEthena(ENA)$0.20022517.82%
  • Pump.funPump.fun(PUMP)$0.004169-5.03%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Llama3-V: A SOTA Open-Source VLM Model Comparable performance to GPT4-V, Gemini Ultra, Claude Opus with a 100x Smaller Model

June 1, 2024
in AI & Technology
Reading Time: 5 mins read
A A
Llama3-V: A SOTA Open-Source VLM Model Comparable performance to GPT4-V, Gemini Ultra, Claude Opus with a 100x Smaller Model
ShareShareShareShareShare

Llama 3 has significantly outperformed GPT-3.5 and even surpassed GPT-4 in several benchmarks, showcasing its strength in efficiency and task-specific performance despite having fewer parameters. However, GPT-4o emerged with advanced multimodal capabilities, reclaiming the top position. Llama 3, utilizing innovations like Grouped-Query Attention, excels in translation and dialogue generation, while GPT-4 demonstrates superior reasoning and problem-solving skills. GPT-4o further enhances these abilities, solidifying its dominance with improved neural architecture and multimodal proficiency.

This study presents Llama3-V, a multimodal model based on Llama3, trained for under $500. It integrates visual information by embedding input images into patch embeddings using the SigLIP model. These embeddings align with textual tokens via a projection block using self-attention blocks, placing visual and textual embeddings on the same plane. The visual tokens are then prepended to the textual tokens, and the joint representation is processed through Llama3, enhancing its ability to understand and integrate visual data.

✅ [Featured Article] LLMWare.ai Selected for 2024 GitHub Accelerator: Enabling the Next Wave of Innovation in Enterprise RAG with Small Specialized Language Models

SigLIP, an image embedding model, uses a pairwise sigmoid loss for processing each image-text pair independently, unlike CLIP’s contrastive loss with softmax normalization. SigLIP’s vision encoder divides images into non-overlapping patches, projecting them into a lower-dimensional embedding space and applying self-attention for higher-level feature extraction. To align SigLIP’s image embeddings with Llama3’s textual embeddings, a projection module with two self-attention blocks is used. Visual tokens from these embeddings are prepended to textual tokens, creating a joint input for Llama3.

To optimize computational resources, two major strategies were employed. First, a caching mechanism precomputes SigLIP image embeddings, increasing GPU utilization and batch size without causing out-of-memory errors. This separation of SigLIP and Llama3 processing stages enhances efficiency. Second, utilization of MPS/MLX optimizations, SigLIP, due to its smaller size, runs inference on Macbooks and achieves a throughput of 32 images/second. These optimizations save training and inference time by efficiently managing resources and maximizing GPU usage.

Precomputing image embeddings via SigLIP involves loading the SigLIP model, preprocessing images, and obtaining vector representations. High-resolution images are split into patches for efficient encoding. Sigmoid activation is applied to logits to extract embeddings, which are then projected into a joint multimodal space using a learned weight matrix. These projected embeddings, or “latents,” are prepended to text tokens for pretraining Llama3. Pretraining uses 600,000 image-text pairs, updating only the projection matrix. Supervised finetuning enhances performance using 1M examples, focusing on the vision and projection matrices.

Llama3-V achieves a 10–20% performance boost over Llava, the leading model for multimodal understanding. It also performs comparably to much larger closed-source models across most metrics, except for MMMU, demonstrating its efficiency and competitiveness despite a smaller size.

To recapitulate, Llama3-V demonstrates significant advancements in multimodal AI, outperforming Llava and rivaling larger closed-source models in most metrics. By integrating SigLIP for efficient image embedding and employing strategic computational optimizations, Llama3-V maximizes GPU utilization and reduces training costs. Pretraining and supervised finetuning enhance its multimodal capabilities, leading to a significant 10–20% performance boost over Llava. Llama3-V’s innovative approach and cost-effective training establish it as a competitive and efficient state-of-the-art model for multimodal understanding.


Check out the Github, Model, and Blog. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter. Join our Telegram Channel, Discord Channel, and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our 43k+ ML SubReddit | Also, check out our AI Events Platform

YOU MAY ALSO LIKE

SpaceX Targets September 28 For Starship’s First Orbital Flight

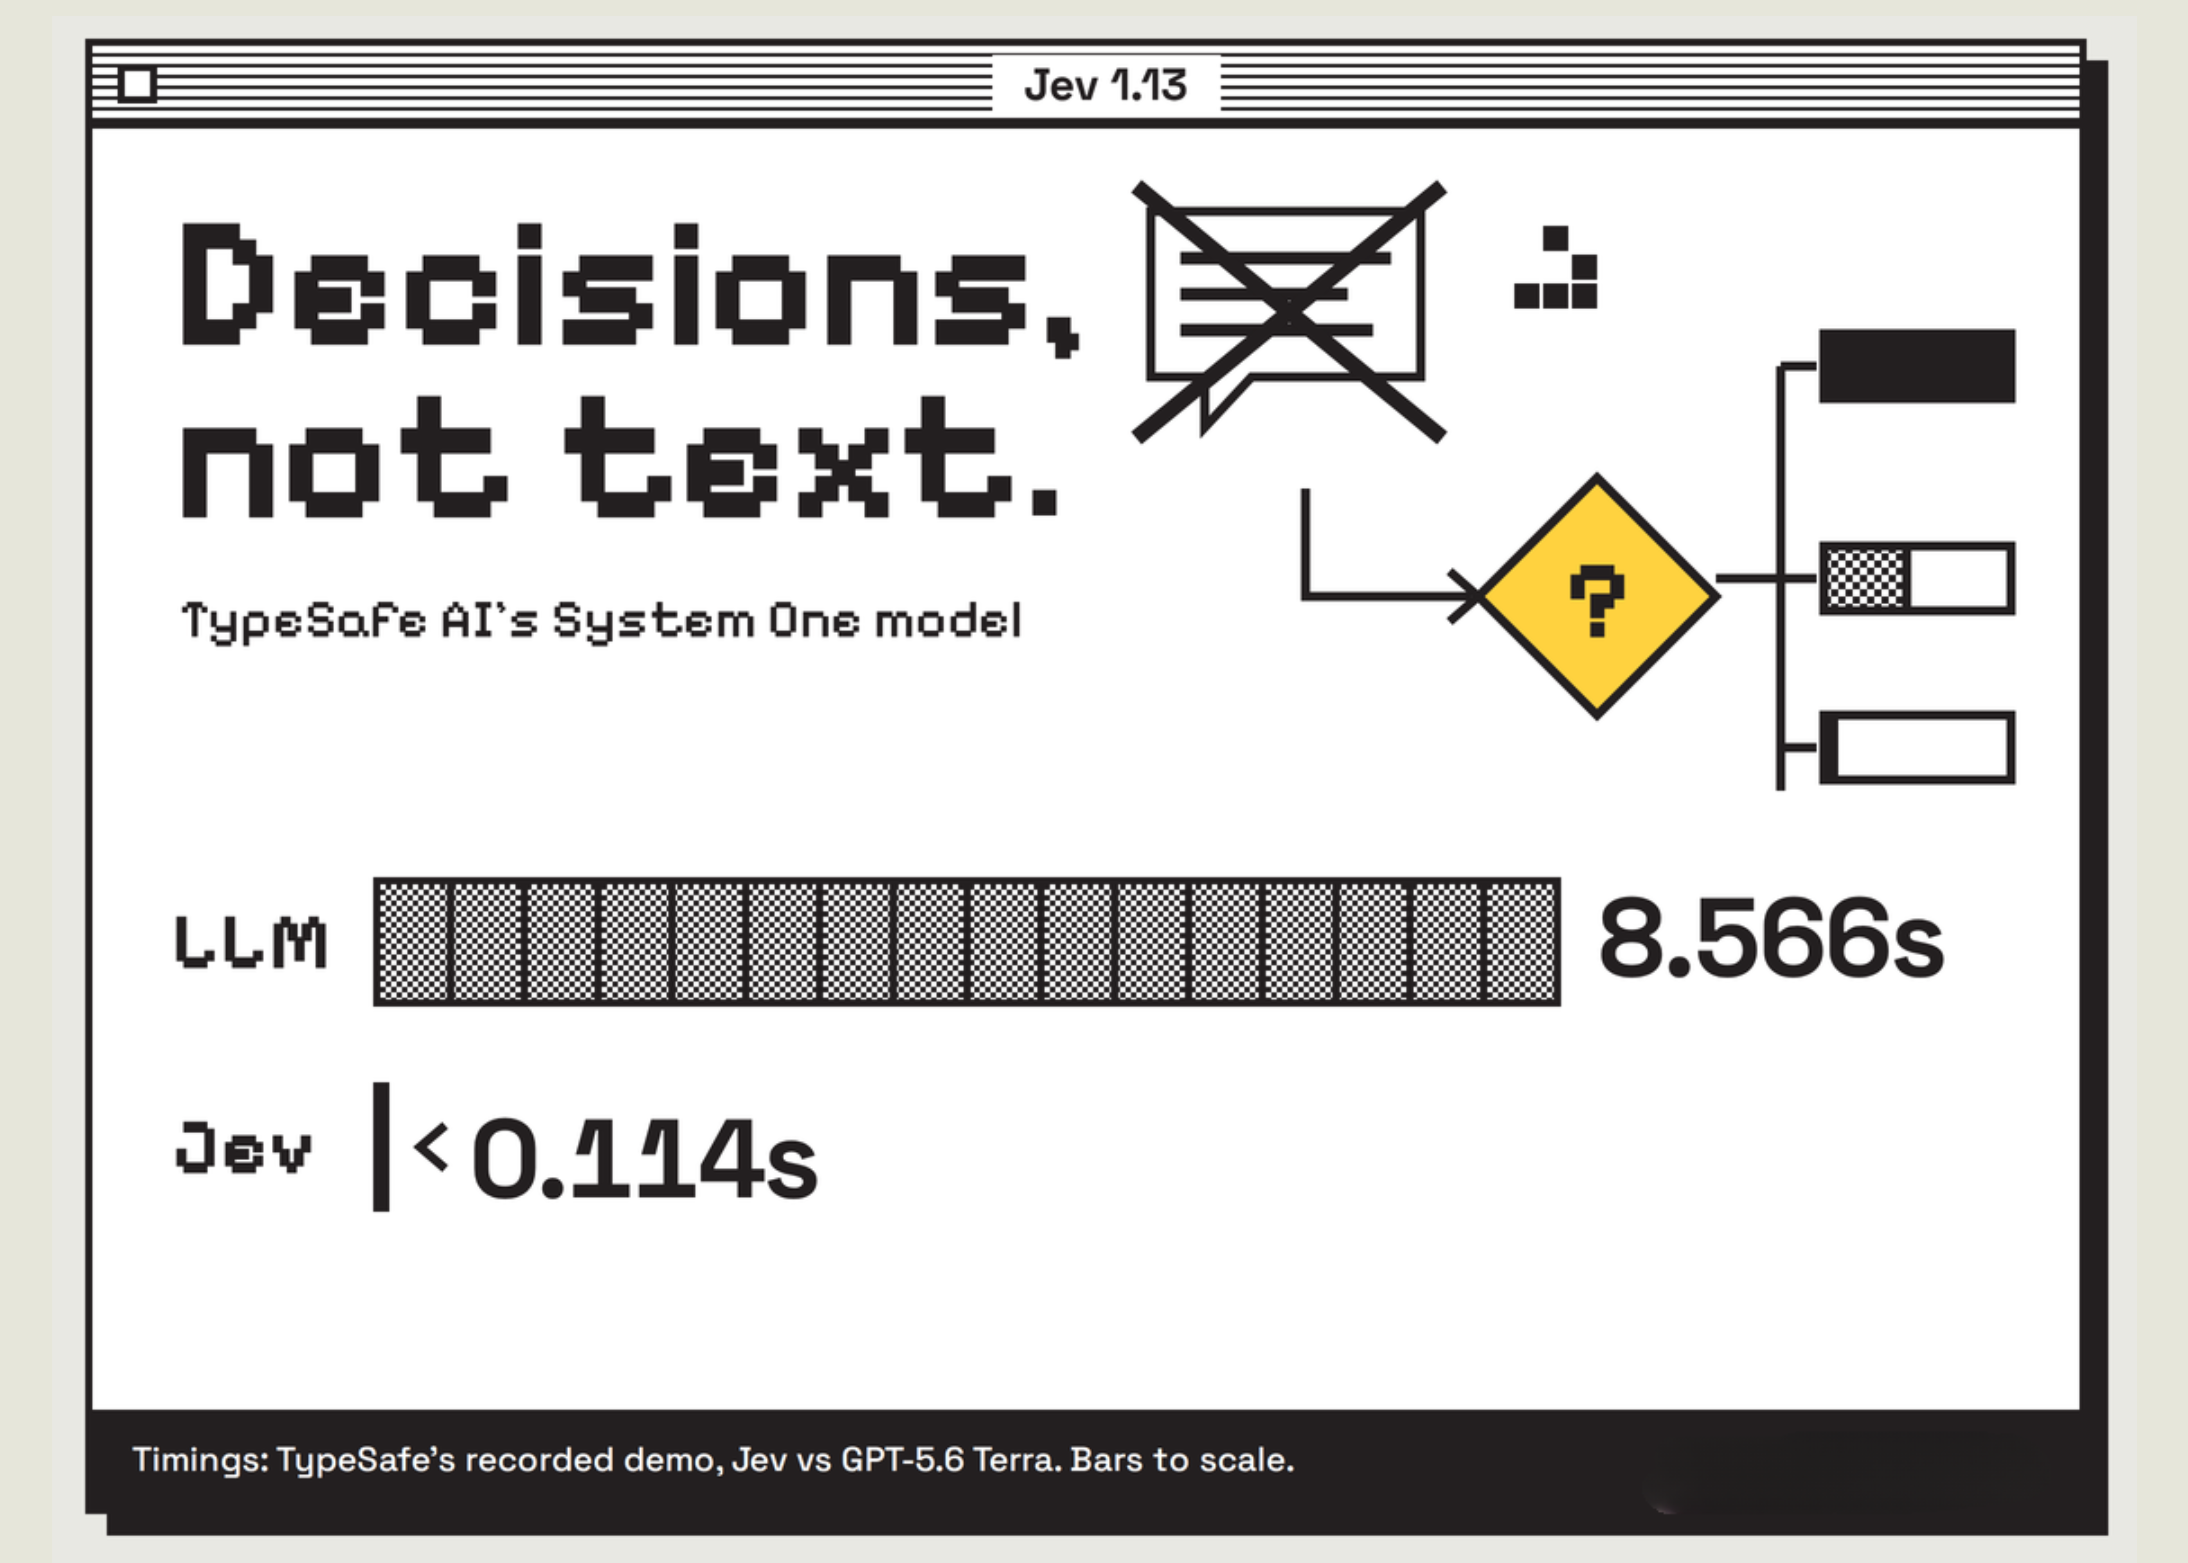
TypeSafe AI Releases Jev: A System One Model That Returns Typed, Calibrated Decisions Instead of Text

Asjad is an intern consultant at Marktechpost. He is persuing B.Tech in mechanical engineering at the Indian Institute of Technology, Kharagpur. Asjad is a Machine learning and deep learning enthusiast who is always researching the applications of machine learning in healthcare.


🐝 Join the Fastest Growing AI Research Newsletter Read by Researchers from Google + NVIDIA + Meta + Stanford + MIT + Microsoft and many others…


Credit: Source link

ShareTweetSendSharePin

Related Posts

SpaceX Targets September 28 For Starship’s First Orbital Flight
AI & Technology

SpaceX Targets September 28 For Starship’s First Orbital Flight

September 19, 2026
TypeSafe AI Releases Jev: A System One Model That Returns Typed, Calibrated Decisions Instead of Text
AI & Technology

TypeSafe AI Releases Jev: A System One Model That Returns Typed, Calibrated Decisions Instead of Text

September 19, 2026
Why Is Your iPad Not Charging (And How To Fix It)
AI & Technology

Why Is Your iPad Not Charging (And How To Fix It)

September 19, 2026
How To Block And Unblock A Number On Your Android Phone
AI & Technology

How To Block And Unblock A Number On Your Android Phone

September 19, 2026
Next Post
South Korean lawmakers vote to ban dog meat trade

South Korean lawmakers vote to ban dog meat trade

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Doctors fill CDC guidance void with new vaccine recommendations

Doctors fill CDC guidance void with new vaccine recommendations

September 18, 2026
NVIDIA Reports Early Production Results for DSX AI Factory Platform – Unite.AI

NVIDIA Reports Early Production Results for DSX AI Factory Platform – Unite.AI

September 15, 2026
Lindsay Clancy’s defense attorney requests Trump pardon: Is it legally possible?

Lindsay Clancy’s defense attorney requests Trump pardon: Is it legally possible?

September 16, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!