• bitcoinBitcoin(BTC)$81,184.000.11%
  • ethereumEthereum(ETH)$2,627.870.36%
  • tetherTether(USDT)$1.00-0.02%
  • binancecoinBNB(BNB)$760.60-0.30%
  • rippleXRP(XRP)$1.411.16%
  • usd-coinUSDC(USDC)$1.00-0.01%
  • solanaSolana(SOL)$110.59-2.09%
  • tronTRON(TRX)$0.3399010.45%
  • zcashZcash(ZEC)$1,475.95-2.44%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.02-1.61%
  • HyperliquidHyperliquid(HYPE)$91.48-0.85%
  • dogecoinDogecoin(DOGE)$0.087602-0.70%
  • moneroMonero(XMR)$542.89-4.12%
  • whitebitWhiteBIT Coin(WBT)$82.79-0.49%
  • RainRain(RAIN)$0.0137422.24%
  • USDSUSDS(USDS)$1.00-0.04%
  • chainlinkChainlink(LINK)$12.380.73%
  • cardanoCardano(ADA)$0.2273790.57%
  • leo-tokenLEO Token(LEO)$8.90-0.09%
  • stellarStellar(XLM)$0.1959541.75%
  • uniswapUniswap(UNI)$8.60-1.97%
  • bitcoin-cashBitcoin Cash(BCH)$253.04-3.60%
  • Ethena USDeEthena USDe(USDE)$1.00-0.02%
  • nearNEAR Protocol(NEAR)$3.58-4.21%
  • daiDai(DAI)$1.000.00%
  • litecoinLitecoin(LTC)$57.31-0.81%
  • USD1USD1(USD1)$1.00-0.03%
  • CantonCanton(CC)$0.109091-2.26%
  • avalanche-2Avalanche(AVAX)$9.7519.11%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.37-0.45%
  • hedera-hashgraphHedera(HBAR)$0.0812172.49%
  • suiSui(SUI)$0.865.00%
  • MemeCoreMemeCore(M)$1.4813.71%
  • Global DollarGlobal Dollar(USDG)$1.00-0.01%
  • shiba-inuShiba Inu(SHIB)$0.0000050.33%
  • BittensorBittensor(TAO)$264.476.18%
  • crypto-com-chainCronos(CRO)$0.059328-0.45%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.04%
  • tether-goldTether Gold(XAUT)$4,373.48-0.07%
  • Circle USYCCircle USYC(USYC)$1.140.00%
  • okbOKB(OKB)$117.650.90%
  • Ripple USDRipple USD(RLUSD)$1.000.00%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.15-0.16%
  • aaveAave(AAVE)$141.072.32%
  • AsterAster(ASTER)$0.76-1.43%
  • mantleMantle(MNT)$0.62-0.49%
  • OndoOndo(ONDO)$0.4198326.03%
  • EthenaEthena(ENA)$0.20080420.22%
  • Pump.funPump.fun(PUMP)$0.004201-1.70%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

PyramidInfer: Allowing Efficient KV Cache Compression for Scalable LLM Inference

May 24, 2024
in AI & Technology
Reading Time: 5 mins read
A A
PyramidInfer: Allowing Efficient KV Cache Compression for Scalable LLM Inference
ShareShareShareShareShare

LLMs like GPT-4 excel in language comprehension but struggle with high GPU memory usage during inference, limiting their scalability for real-time applications like chatbots. Existing methods reduce memory by compressing the KV cache but overlook inter-layer dependencies and pre-computation memory demands. Inference memory usage primarily comes from model parameters and the KV cache, with the latter consuming significantly more memory. For instance, a 7 billion parameter model uses 14 GB for parameters but 72 GB for the KV cache. This substantial memory requirement restricts the throughput of LLM inference on GPUs.

Researchers from Shanghai Jiao Tong University, Xiaohongshu Inc., and South China University of Technology developed PyramidInfer, which enhances LLM inference by compressing the KV cache. Unlike existing methods that overlook inter-layer dependencies and the memory demands of pre-computation, PyramidInfer retains only crucial context keys and values layer-by-layer. Inspired by recent tokens’ consistency in attention weights, this approach significantly reduces GPU memory usage. Experiments show PyramidInfer improves throughput by 2.2x and reduces KV cache memory by over 54% compared to existing methods, demonstrating its effectiveness across various tasks and models.

Efficient strategies are essential to handle the growing demand for chatbot queries, aiming to maximize throughput by leveraging GPU parallelism. One approach is increasing GPU memory through pipeline parallelism and KV cache offload, utilizing multiple GPUs or RAM. For limited GPU memory, reducing the KV cache is another option. Techniques like FlashAttention 2 and PagedAttention minimize memory waste by optimizing CUDA operations. Methods such as StreamingLLM, H2O, and Scissorhands compress the KV cache by focusing on recent context or attention mechanisms but overlook layer differences and prefill phase compression. PyramidInfer addresses these gaps by considering layer-specific compression in both phases.
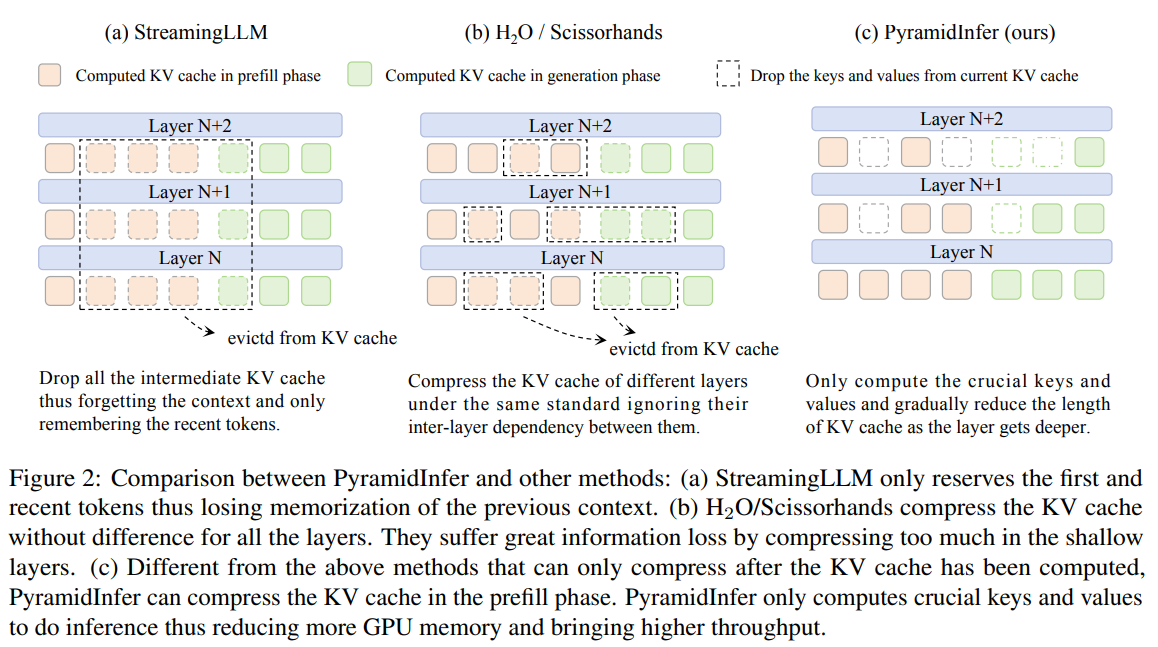
Verification of the Inference Context Redundancy (ICR) and Recent Attention Consistency (RAC) hypotheses inspired the design of PyramidInfer. ICR posits that many context keys and values are redundant during inference and are only necessary in training to predict the next token. Experiments with a 40-layer LLaMA 2-13B model revealed that deeper layers have higher redundancy, allowing for significant KV cache reduction without affecting output quality. RAC confirms that certain keys and values are consistently attended by recent tokens, enabling the selection of pivotal contexts (PVCs) for efficient inference. PyramidInfer leverages these insights to compress the KV cache effectively in both prefill and generation phases.

PyramidInfer’s performance was evaluated across various tasks and models, demonstrating significant reductions in GPU memory usage and increased throughput while maintaining generation quality. The evaluation included language modeling on wikitext-v2, LLM benchmarks like MMLU and BBH, mathematical reasoning with GSM8K, coding via HumanEval, conversation handling with MT-Bench, and long text summarization using LEval. PyramidInfer was tested on models such as LLaMA 2, LLaMA 2-Chat, Vicuna 1.5-16k, and CodeLLaMA across different sizes. Results showed that PyramidInfer effectively maintained generation quality with less GPU memory than full cache methods and significantly outperformed local strategies.

In conclusion, PyramidInfer introduces an efficient method to compress the KV cache during both prefill and generation phases, inspired by ICR and RAC. This approach significantly reduces GPU memory usage without compromising model performance, making it ideal for deploying large language models in resource-constrained environments. Despite its effectiveness, PyramidInfer requires additional computation, limiting speedup with small batch sizes. As the first to compress the KV cache in the prefill phase, PyramidInfer is yet to be a lossless method, indicating potential for future improvements in this area.


Check out the Paper. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter. Join our Telegram Channel, Discord Channel, and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our 42k+ ML SubReddit

YOU MAY ALSO LIKE

Trump Proposes Renaming Artificial Intelligence, Announces AI Force – Unite.AI

SpaceX Targets September 28 For Starship’s First Orbital Flight

Sana Hassan, a consulting intern at Marktechpost and dual-degree student at IIT Madras, is passionate about applying technology and AI to address real-world challenges. With a keen interest in solving practical problems, he brings a fresh perspective to the intersection of AI and real-life solutions.


✅ [Featured Tool] Check out Taipy Enterprise Edition


Credit: Source link

ShareTweetSendSharePin

Related Posts

Trump Proposes Renaming Artificial Intelligence, Announces AI Force – Unite.AI
AI & Technology

Trump Proposes Renaming Artificial Intelligence, Announces AI Force – Unite.AI

September 19, 2026
SpaceX Targets September 28 For Starship’s First Orbital Flight
AI & Technology

SpaceX Targets September 28 For Starship’s First Orbital Flight

September 19, 2026
Now Trump Says He’s Creating An AI Force
AI & Technology

Now Trump Says He’s Creating An AI Force

September 19, 2026
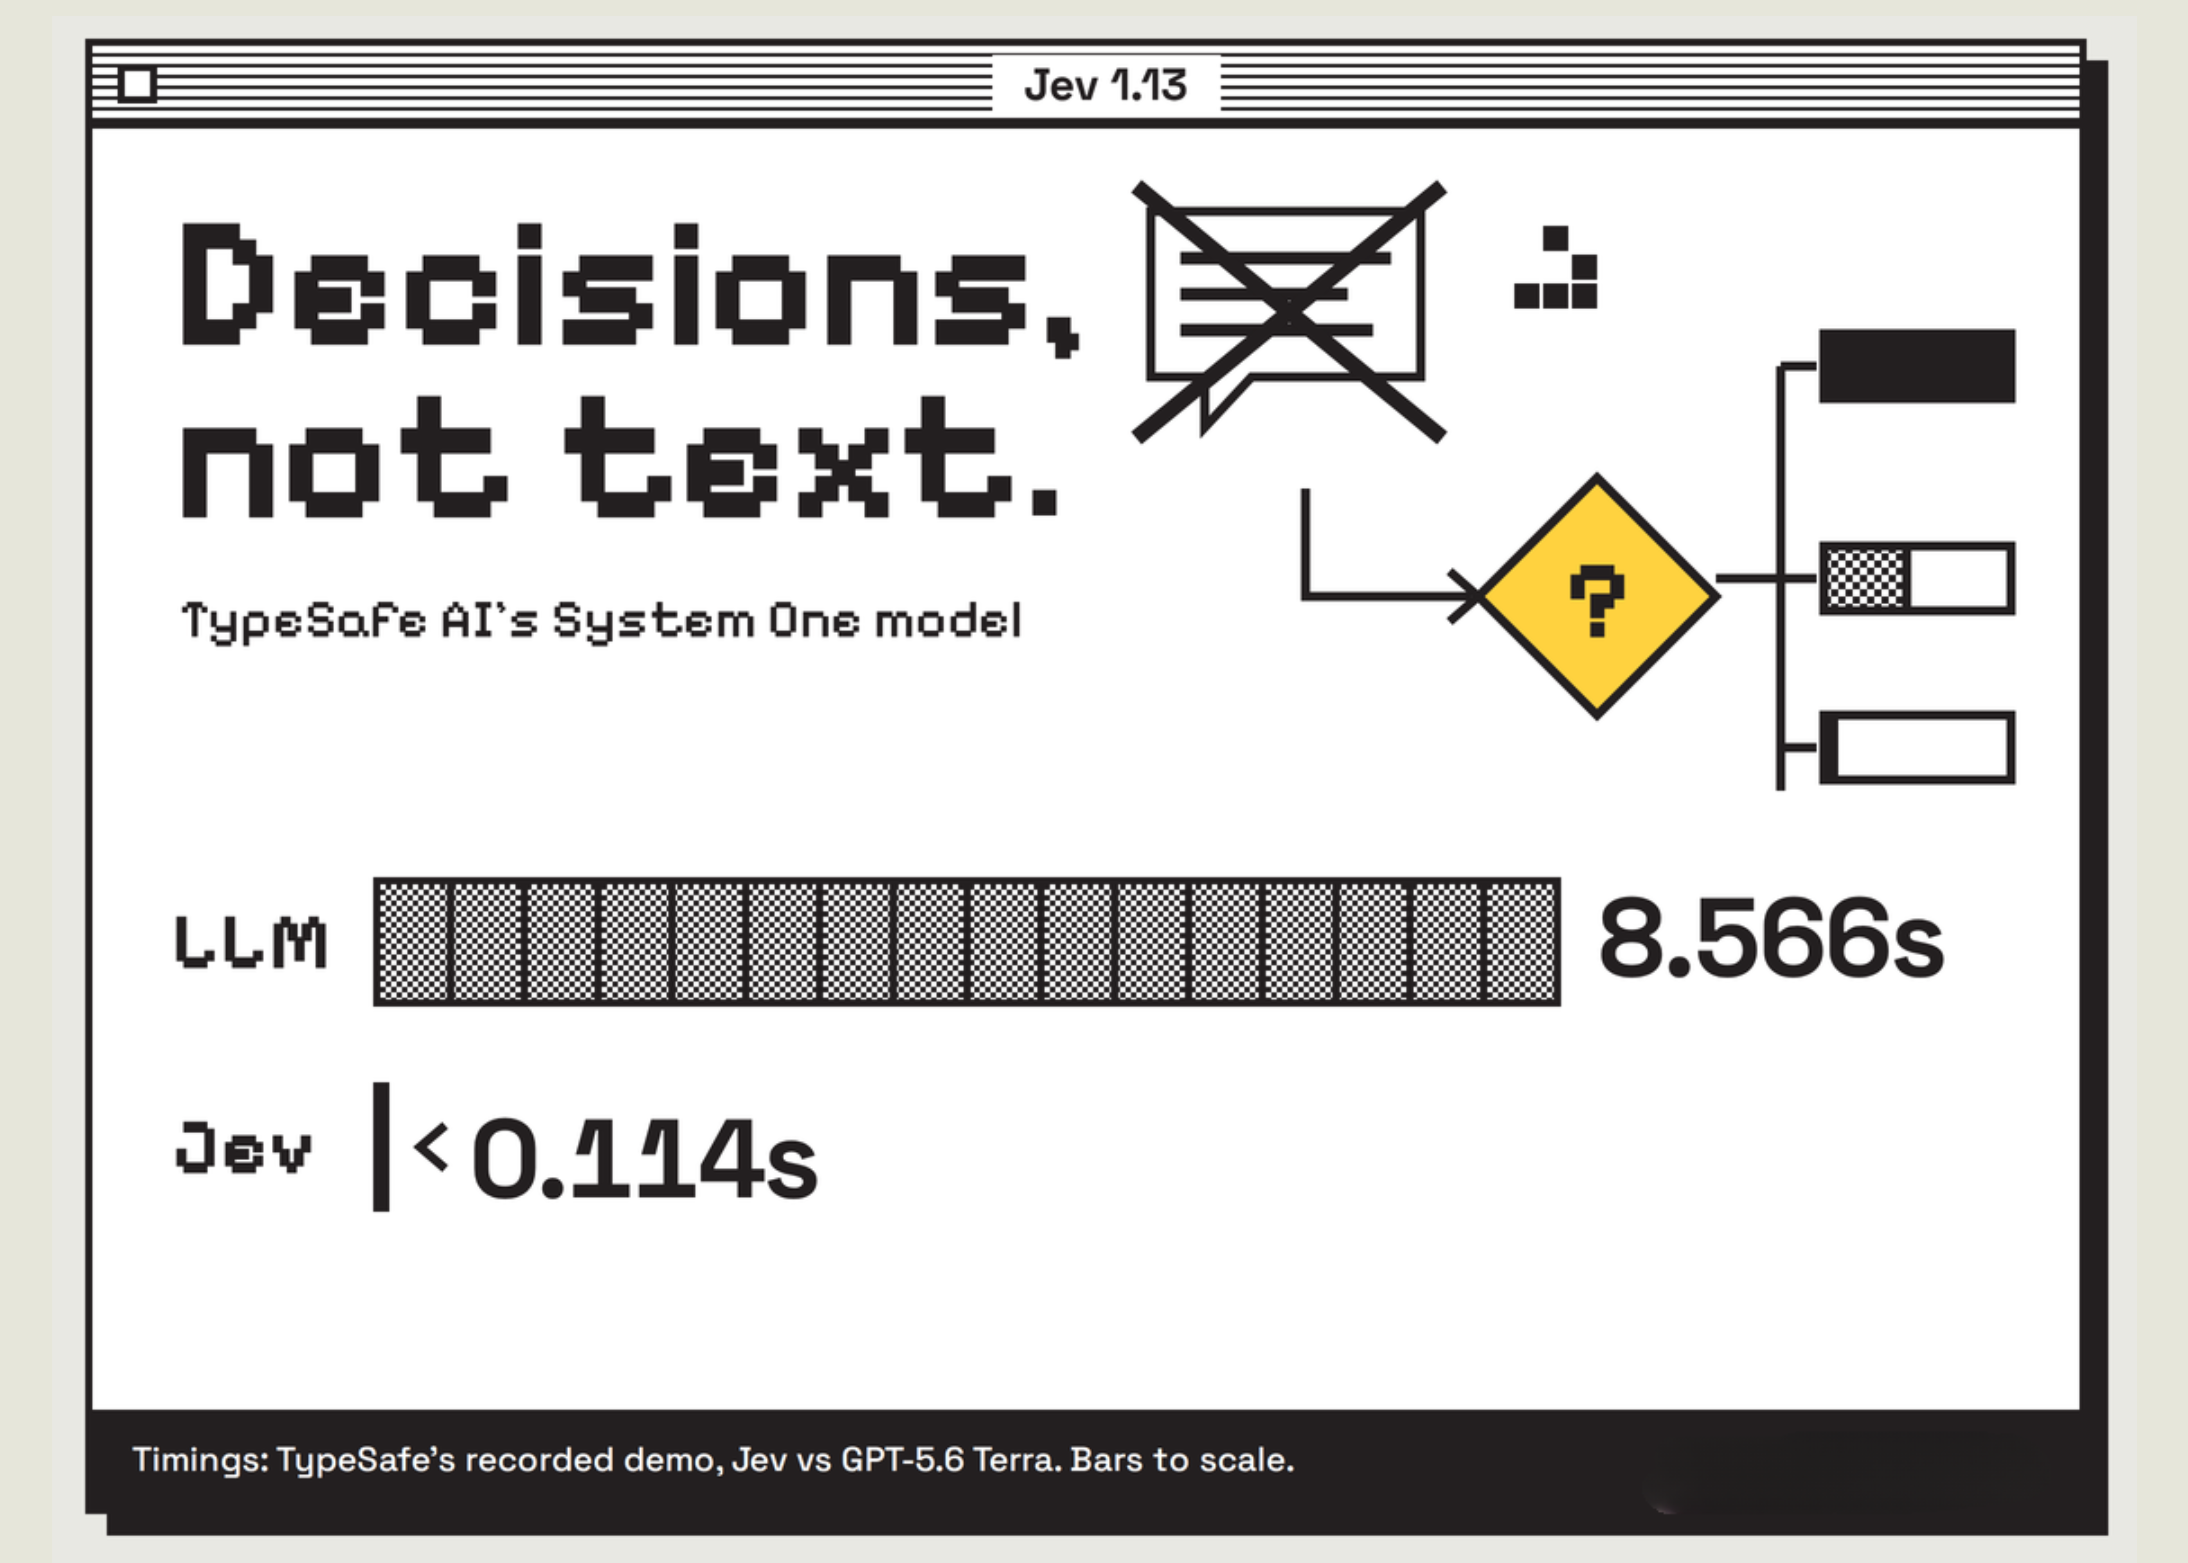
TypeSafe AI Releases Jev: A System One Model That Returns Typed, Calibrated Decisions Instead of Text
AI & Technology

TypeSafe AI Releases Jev: A System One Model That Returns Typed, Calibrated Decisions Instead of Text

September 19, 2026
Next Post
The ONE Thing Keeping You From Building Wealth – Dave Ramsey Rant

The ONE Thing Keeping You From Building Wealth – Dave Ramsey Rant

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Reddington: What people misunderstand about the Clancy trial

Reddington: What people misunderstand about the Clancy trial

September 15, 2026
US 10-year Treasury yield briefly surges past 5% on sky-high diesel prices

US 10-year Treasury yield briefly surges past 5% on sky-high diesel prices

September 14, 2026
U.S. envoys Witkoff and Kushner meet Putin in Moscow

U.S. envoys Witkoff and Kushner meet Putin in Moscow

September 16, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!