• bitcoinBitcoin(BTC)$85,373.004.87%
  • ethereumEthereum(ETH)$2,730.902.44%
  • tetherTether(USDT)$1.000.01%
  • binancecoinBNB(BNB)$789.061.43%
  • rippleXRP(XRP)$1.516.30%
  • usd-coinUSDC(USDC)$1.000.02%
  • solanaSolana(SOL)$116.484.28%
  • tronTRON(TRX)$0.3473311.28%
  • zcashZcash(ZEC)$1,452.77-4.66%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.011.27%
  • HyperliquidHyperliquid(HYPE)$92.27-0.88%
  • dogecoinDogecoin(DOGE)$0.09924411.88%
  • moneroMonero(XMR)$573.99-1.02%
  • whitebitWhiteBIT Coin(WBT)$85.913.24%
  • RainRain(RAIN)$0.013824-2.59%
  • chainlinkChainlink(LINK)$12.881.77%
  • USDSUSDS(USDS)$1.000.00%
  • cardanoCardano(ADA)$0.2454285.01%
  • leo-tokenLEO Token(LEO)$8.960.21%
  • stellarStellar(XLM)$0.2123026.39%
  • nearNEAR Protocol(NEAR)$4.401.33%
  • uniswapUniswap(UNI)$9.022.85%
  • bitcoin-cashBitcoin Cash(BCH)$263.893.46%
  • avalanche-2Avalanche(AVAX)$11.14-0.57%
  • Ethena USDeEthena USDe(USDE)$1.000.01%
  • litecoinLitecoin(LTC)$60.341.95%
  • CantonCanton(CC)$0.1169484.71%
  • daiDai(DAI)$1.000.03%
  • USD1USD1(USD1)$1.000.00%
  • suiSui(SUI)$1.049.98%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.443.67%
  • hedera-hashgraphHedera(HBAR)$0.0916405.33%
  • BittensorBittensor(TAO)$313.3316.58%
  • shiba-inuShiba Inu(SHIB)$0.0000067.34%
  • crypto-com-chainCronos(CRO)$0.0662647.46%
  • Global DollarGlobal Dollar(USDG)$1.000.01%
  • MemeCoreMemeCore(M)$1.43-5.53%
  • paypal-usdPayPal USD(PYUSD)$1.000.02%
  • tether-goldTether Gold(XAUT)$4,345.50-0.39%
  • okbOKB(OKB)$121.901.59%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • Ripple USDRipple USD(RLUSD)$1.000.00%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • BitwayBitway(BTW)$0.8311.51%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.01%
  • aaveAave(AAVE)$141.702.11%
  • pepePepe(PEPE)$0.00000527.94%
  • mantleMantle(MNT)$0.644.76%
  • OndoOndo(ONDO)$0.4352110.85%
  • EthenaEthena(ENA)$0.209540-2.08%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

This AI Paper from KAUST and Purdue University Presents Efficient Stochastic Methods for Large Discrete Action Spaces

May 21, 2024
in AI & Technology
Reading Time: 4 mins read
A A
This AI Paper from KAUST and Purdue University Presents Efficient Stochastic Methods for Large Discrete Action Spaces
ShareShareShareShareShare

Reinforcement learning (RL) is a specialized area of machine learning where agents are trained to make decisions by interacting with their environment. This interaction involves taking action and receiving feedback through rewards or penalties. RL has been instrumental in developing advanced robotics, autonomous vehicles, and strategic game-playing technologies and solving complex problems in various scientific and industrial domains.

A significant challenge in RL is managing the complexity of environments with large discrete action spaces. Traditional RL methods like Q-learning involve a computationally expensive process of evaluating the value of all possible actions at each decision point. This exhaustive search process becomes increasingly impractical as the number of actions grows, leading to substantial inefficiencies and limitations in real-world applications where quick and effective decision-making is crucial.

Current value-based RL methods, including Q-learning and its variants, face considerable challenges in large-scale applications. These methods rely heavily on maximizing a value function’s overall potential actions to update the agent’s policy. While deep Q-networks (DQN) leverage neural networks to approximate value functions, they still need to work on scalability issues due to the extensive computational resources required to evaluate numerous actions in complex environments.

Researchers from KAUST and Purdue University have introduced innovative stochastic value-based RL methods to address these inefficiencies. These methods include Stochastic Q-learning, StochDQN, and StochDDQN, which utilize stochastic maximization techniques. These methods significantly reduce the computational load by considering only a subset of possible actions in each iteration. This approach allows for scalable solutions that can more effectively handle large discrete action spaces.

By incorporating stochastic maximization techniques, the researchers implemented stochastic value-based RL methods, including Stochastic Q-learning, StochDQN, and StochDDQN. They tested these methods on various datasets, including Gymnasium environments like FrozenLake-v1 and MuJoCo control tasks such as InvertedPendulum-v4 and HalfCheetah-v4. The framework involved replacing traditional max and arg max operations with stochastic equivalents, reducing computational complexity. The evaluations demonstrated that the stochastic methods achieved faster convergence and higher efficiency than non-stochastic methods, handling up to 4096 actions with significantly reduced computational time per step.

The results show that stochastic methods significantly improve performance and efficiency. In the FrozenLake-v1 environment, Stochastic Q-learning achieved optimal cumulative rewards in 50% fewer steps than traditional Q-learning. In the InvertedPendulum-v4 task, StochDQN reached an average return of 90 in 10,000 steps, while DQN took 30,000 steps. For HalfCheetah-v4, StochDDQN completed 100,000 steps in 2 hours, whereas DDQN required 17 hours for the same task. Furthermore, the time per step for stochastic methods was reduced to 0.003 seconds from 0.18 seconds in tasks with 1000 actions, representing a 60-fold increase in speed. These quantitative results highlight the efficiency and effectiveness of the stochastic methods.

To conclude, research introduces stochastic methods to enhance the efficiency of RL in large discrete action spaces. By incorporating stochastic maximization, the methods significantly reduce computational complexity while maintaining high performance. Tested across various environments, these methods achieved faster convergence and higher efficiency than traditional approaches. This work is crucial as it offers scalable solutions for real-world applications, making RL more practical and effective in complex environments. The innovations presented hold significant potential for advancing RL technologies in diverse fields. 


Check out the Paper. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter. Join our Telegram Channel, Discord Channel, and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our 42k+ ML SubReddit

YOU MAY ALSO LIKE

Why It’s Important To Unplug Your PC During A Power Outage

Why Is Your Laptop Fan So Loud?

Nikhil is an intern consultant at Marktechpost. He is pursuing an integrated dual degree in Materials at the Indian Institute of Technology, Kharagpur. Nikhil is an AI/ML enthusiast who is always researching applications in fields like biomaterials and biomedical science. With a strong background in Material Science, he is exploring new advancements and creating opportunities to contribute.


🐝 Join the Fastest Growing AI Research Newsletter Read by Researchers from Google + NVIDIA + Meta + Stanford + MIT + Microsoft and many others…


Credit: Source link

ShareTweetSendSharePin

Related Posts

Why It’s Important To Unplug Your PC During A Power Outage
AI & Technology

Why It’s Important To Unplug Your PC During A Power Outage

September 22, 2026
Why Is Your Laptop Fan So Loud?
AI & Technology

Why Is Your Laptop Fan So Loud?

September 22, 2026
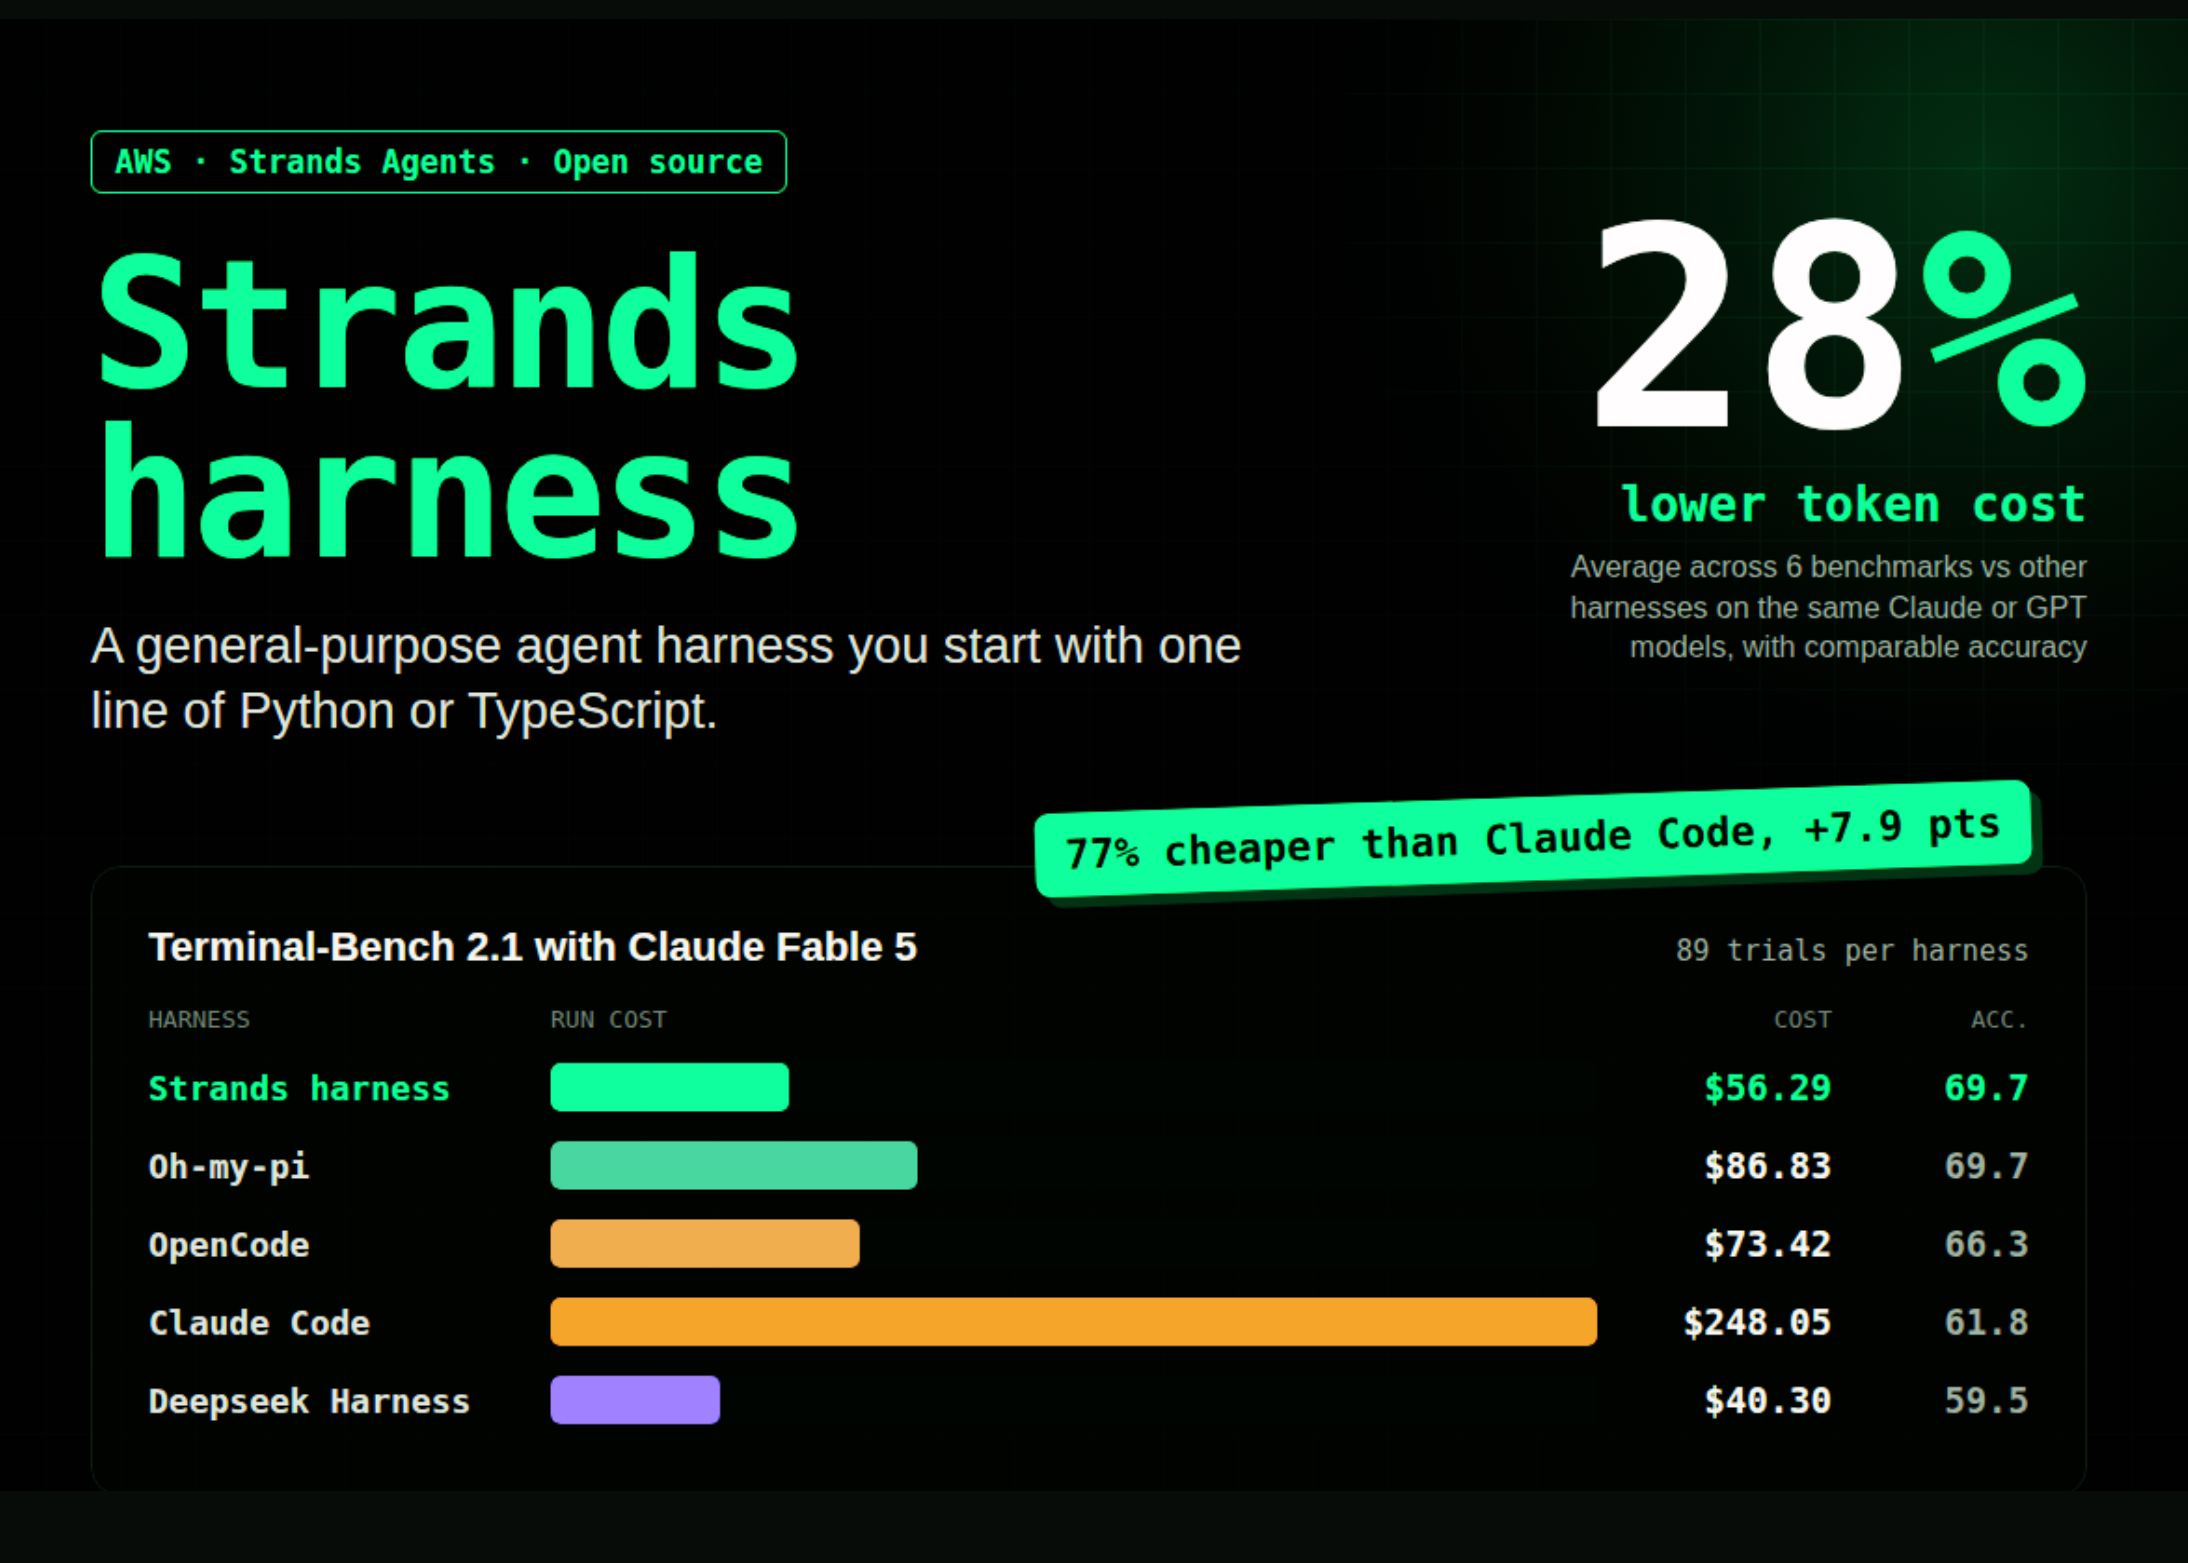
AWS Strands Agents Team Releases Strands Harness: An Open-Source Agent Harness With 28% Lower Token Cost at Comparable Accuracy
AI & Technology

AWS Strands Agents Team Releases Strands Harness: An Open-Source Agent Harness With 28% Lower Token Cost at Comparable Accuracy

September 21, 2026
Bungie Leaders Now Say The Studio’s ‘Not Done With Destiny’
AI & Technology

Bungie Leaders Now Say The Studio’s ‘Not Done With Destiny’

September 21, 2026
Next Post
U.S. economy shows more robust growth as recession fears ease

U.S. economy shows more robust growth as recession fears ease

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Vance says he won’t make a ‘promise’ about when gas prices will lower

Vance says he won’t make a ‘promise’ about when gas prices will lower

September 18, 2026
At least 21 killed after war-damaged Gaza building collapses – BBC

At least 21 killed after war-damaged Gaza building collapses – BBC

September 16, 2026
LIVE: Vice President JD Vance holds White House press briefing | NBC News

LIVE: Vice President JD Vance holds White House press briefing | NBC News

September 18, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!