• bitcoinBitcoin(BTC)$81,238.004.06%
  • ethereumEthereum(ETH)$2,636.685.19%
  • tetherTether(USDT)$1.000.05%
  • binancecoinBNB(BNB)$765.852.07%
  • rippleXRP(XRP)$1.437.89%
  • usd-coinUSDC(USDC)$1.000.02%
  • solanaSolana(SOL)$111.805.87%
  • tronTRON(TRX)$0.3377660.14%
  • zcashZcash(ZEC)$1,536.064.97%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.030.00%
  • HyperliquidHyperliquid(HYPE)$91.972.26%
  • dogecoinDogecoin(DOGE)$0.0880733.45%
  • moneroMonero(XMR)$585.639.09%
  • whitebitWhiteBIT Coin(WBT)$83.083.28%
  • RainRain(RAIN)$0.0138938.08%
  • USDSUSDS(USDS)$1.000.01%
  • chainlinkChainlink(LINK)$12.505.99%
  • cardanoCardano(ADA)$0.2259205.79%
  • leo-tokenLEO Token(LEO)$8.89-0.29%
  • stellarStellar(XLM)$0.1934504.38%
  • uniswapUniswap(UNI)$9.124.77%
  • bitcoin-cashBitcoin Cash(BCH)$251.131.63%
  • Ethena USDeEthena USDe(USDE)$1.000.04%
  • nearNEAR Protocol(NEAR)$3.655.04%
  • daiDai(DAI)$1.00-0.01%
  • litecoinLitecoin(LTC)$57.253.81%
  • CantonCanton(CC)$0.1105032.88%
  • USD1USD1(USD1)$1.000.06%
  • avalanche-2Avalanche(AVAX)$9.2616.45%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.370.36%
  • suiSui(SUI)$0.869.10%
  • hedera-hashgraphHedera(HBAR)$0.0804554.37%
  • Global DollarGlobal Dollar(USDG)$1.000.00%
  • shiba-inuShiba Inu(SHIB)$0.0000051.86%
  • BittensorBittensor(TAO)$270.0110.34%
  • crypto-com-chainCronos(CRO)$0.0598521.18%
  • MemeCoreMemeCore(M)$1.301.35%
  • paypal-usdPayPal USD(PYUSD)$1.000.02%
  • tether-goldTether Gold(XAUT)$4,373.49-0.04%
  • okbOKB(OKB)$122.327.35%
  • Circle USYCCircle USYC(USYC)$1.140.03%
  • Ripple USDRipple USD(RLUSD)$1.000.00%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.23%
  • aaveAave(AAVE)$143.186.48%
  • AsterAster(ASTER)$0.772.25%
  • mantleMantle(MNT)$0.612.84%
  • OndoOndo(ONDO)$0.4106146.20%
  • Pump.funPump.fun(PUMP)$0.004133-1.70%
  • polkadotPolkadot(DOT)$1.130.39%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Alignment Lab AI Releases ‘Buzz Dataset’: The Largest Supervised Fine-Tuning Open-Sourced Dataset

May 13, 2024
in AI & Technology
Reading Time: 4 mins read
A A
Alignment Lab AI Releases ‘Buzz Dataset’: The Largest Supervised Fine-Tuning Open-Sourced Dataset
ShareShareShareShareShare

Language models, a subset of artificial intelligence, focus on interpreting and generating human-like text. These models are integral to various applications, ranging from automated chatbots to advanced predictive text and language translation services. The ongoing challenge in this field is enhancing these models’ efficiency and performance, which involves refining their ability to process & understand vast amounts of data while optimizing the computational power required.

A significant challenge in natural language processing is the efficient scalability of language models to handle increasingly complex tasks. This includes improving their speed, accuracy, and ability to interact in a human-like manner without escalating computational costs. Researchers continuously seek methods to refine these models, making them more adept at understanding the context and subtleties of language.

Traditionally, language models undergo extensive pre-training on massive datasets, including everything from literary works to internet text. This training is designed to equip the models with a broad understanding of language & context. The next phase typically involves fine-tuning more specialized datasets to adapt the model for specific tasks, such as legal document analysis or conversational interfaces.

One pivotal aspect of this research is the introduction of the Buzz dataset by Alignment Lab AI, in collaboration with Hive Digital Technologies, a meticulously curated collection used to train the new model. This dataset encompasses a variety of text sources and is designed to provide a comprehensive foundation for model training. Notable for its volume and diversity, the Buzz dataset includes over 85 million conversational turns pulled from 435 unique sources. This extensive compilation allows for nuanced training processes that significantly improve the model’s ability to generate contextually relevant and syntactically diverse text.

The new methodology employs an innovative approach to this fine-tuning phase. The research team has developed an iterative fine-tuning process that reuses existing pre-trained models and enhances their performance through strategic modifications. This process involves adjusting the models based on feedback from their performance in specific tasks, effectively allowing the model to ‘learn’ from its outputs.

The essence of this approach lies in its use of iterative cycles of feedback and adjustment, which significantly reduce the need for re-training from scratch. This method utilizes distributions of “grounding” data collected from previous epochs phases of the model’s training, which guide the adjustment process. Such a strategy conserves computational resources and sharpens the model’s accuracy and efficiency.

The research’s performance indicates substantial improvements in model efficiency. For instance, the models have been shown to achieve lower error rates in text generation tasks through iterative fine-tuning. They demonstrate up to a 30% reduction in computational overhead compared to traditional fine-tuning methods. Furthermore, these models maintain robustness in output quality, indicating that the iterative process helps prevent overfitting.

In conclusion, the collaborative efforts between Alignment Lab AI and Hive Digital Technologies advance the development of language models. Their research on iterative fine-tuning introduces a sustainable, cost-effective method that enhances model performance without the extensive use of additional resources. This breakthrough addresses key issues like computational efficiency and model accuracy and sets a new standard for how language models can be developed and improved upon in the future.


Check out the Dataset and HF Page. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter. Join our Telegram Channel, Discord Channel, and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our 42k+ ML SubReddit


YOU MAY ALSO LIKE

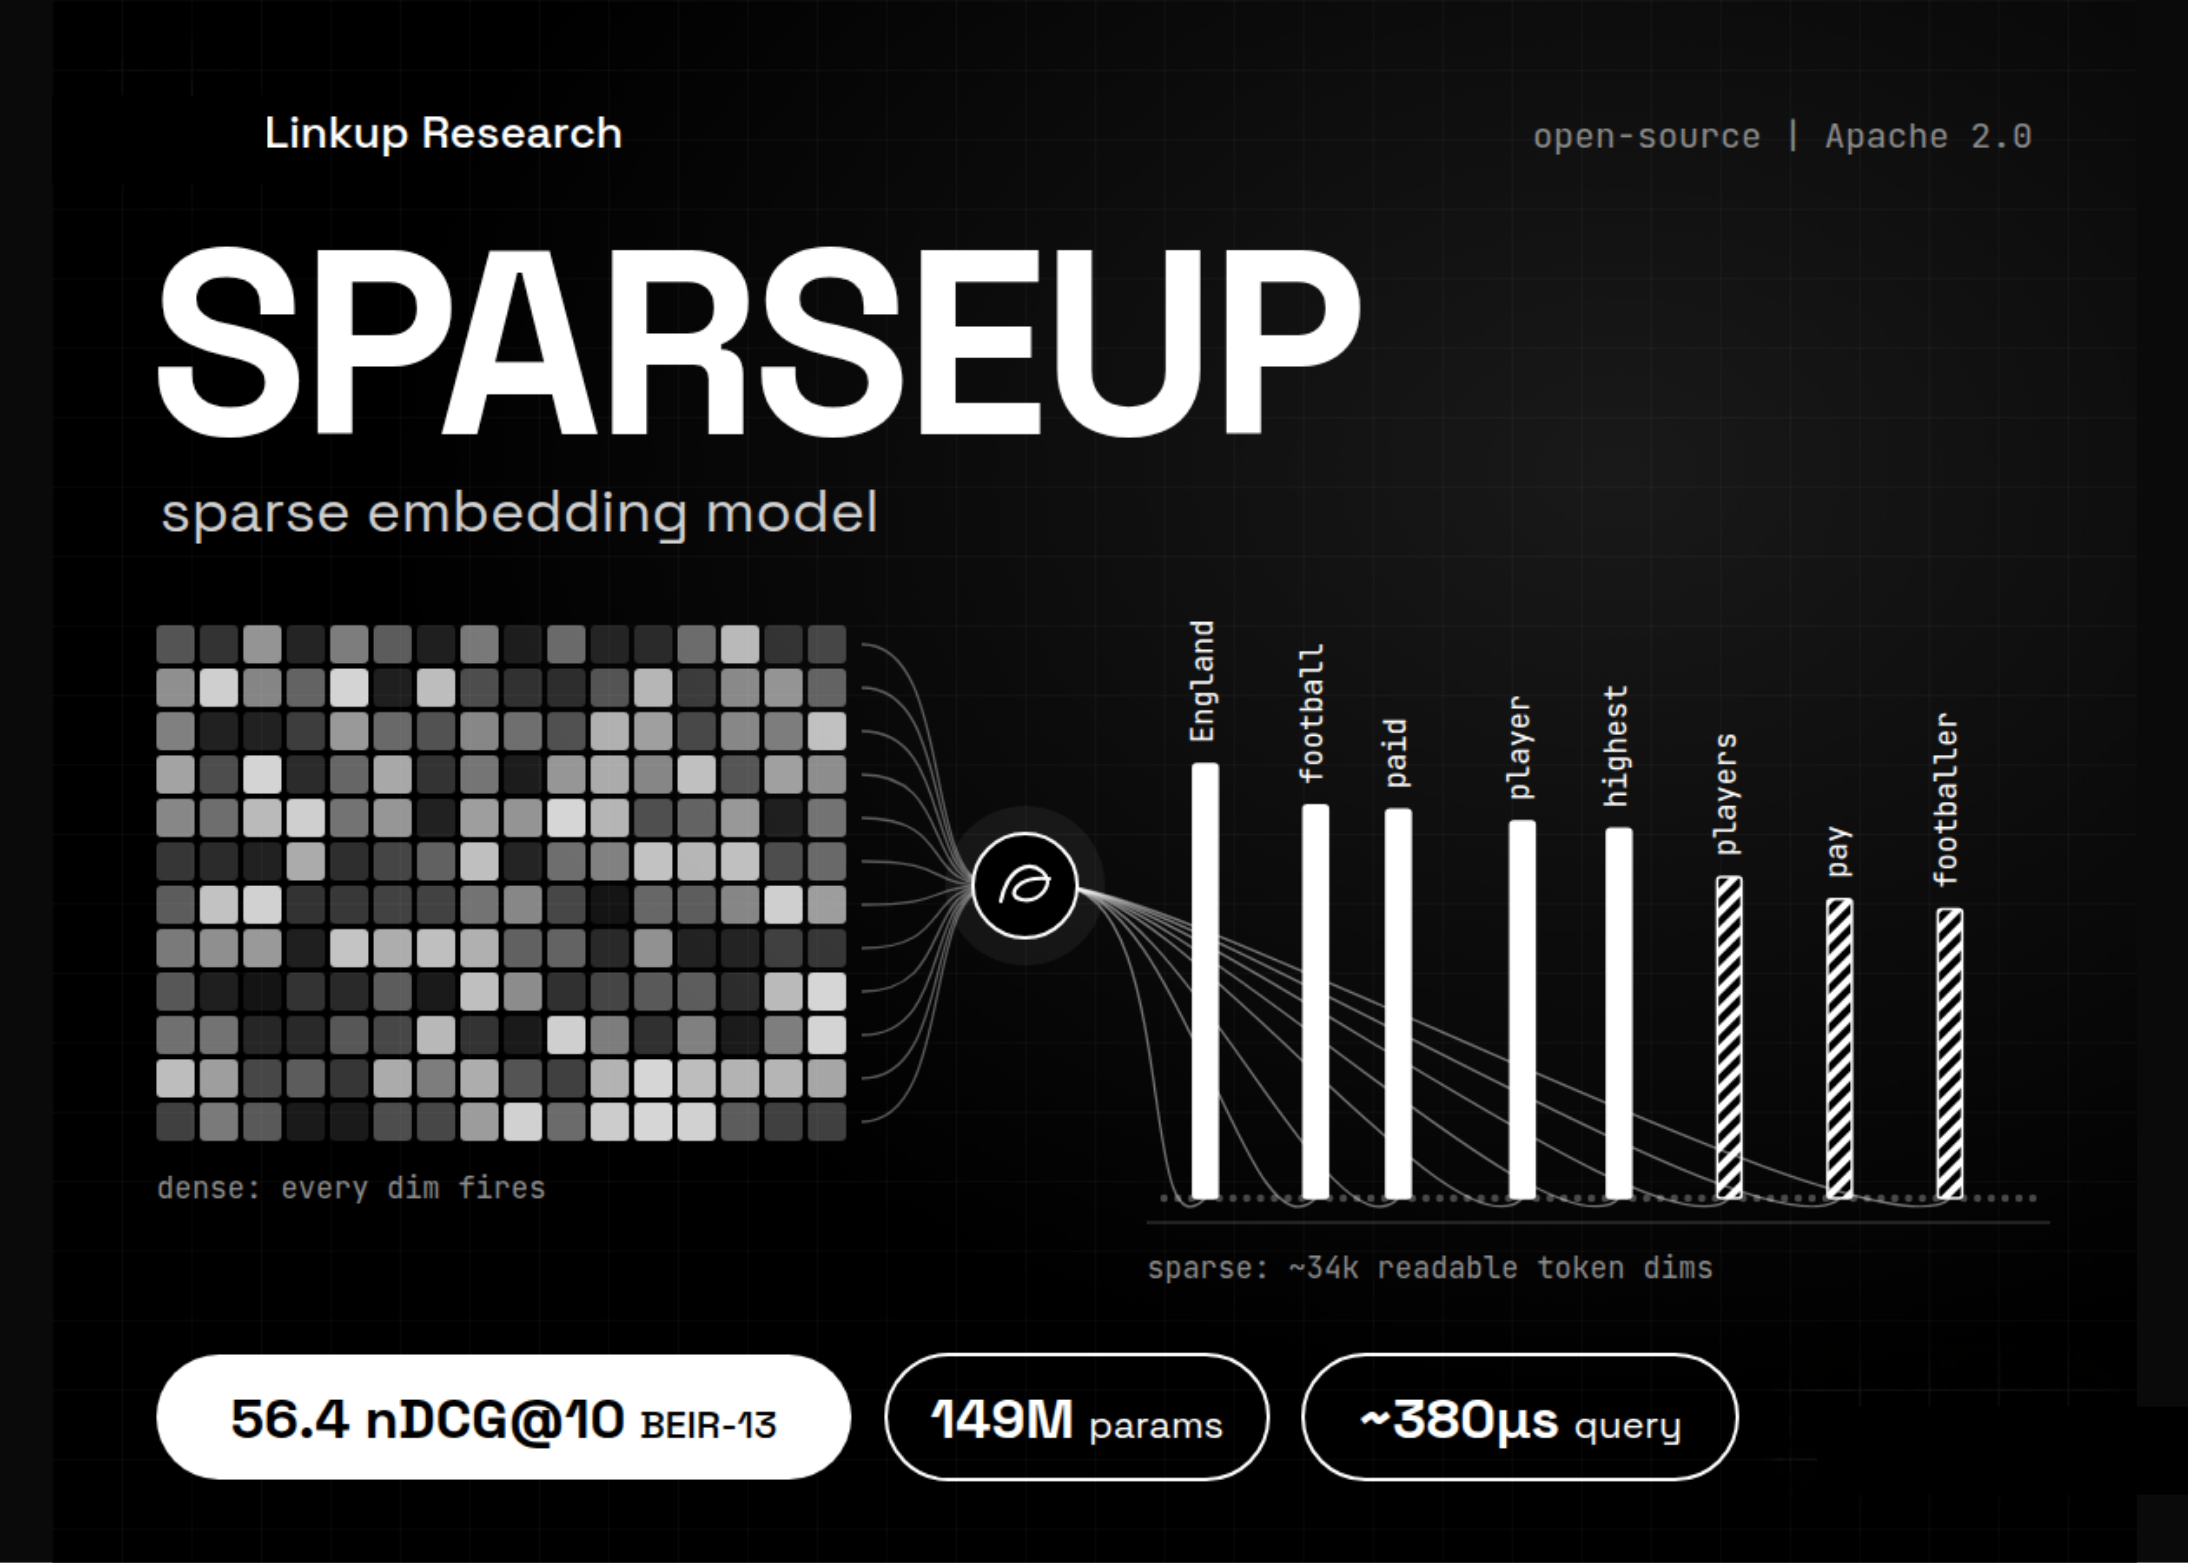
Linkup Research Releases SPARSEUP: A 149M-Parameter Open-Source Sparse Embedding Model

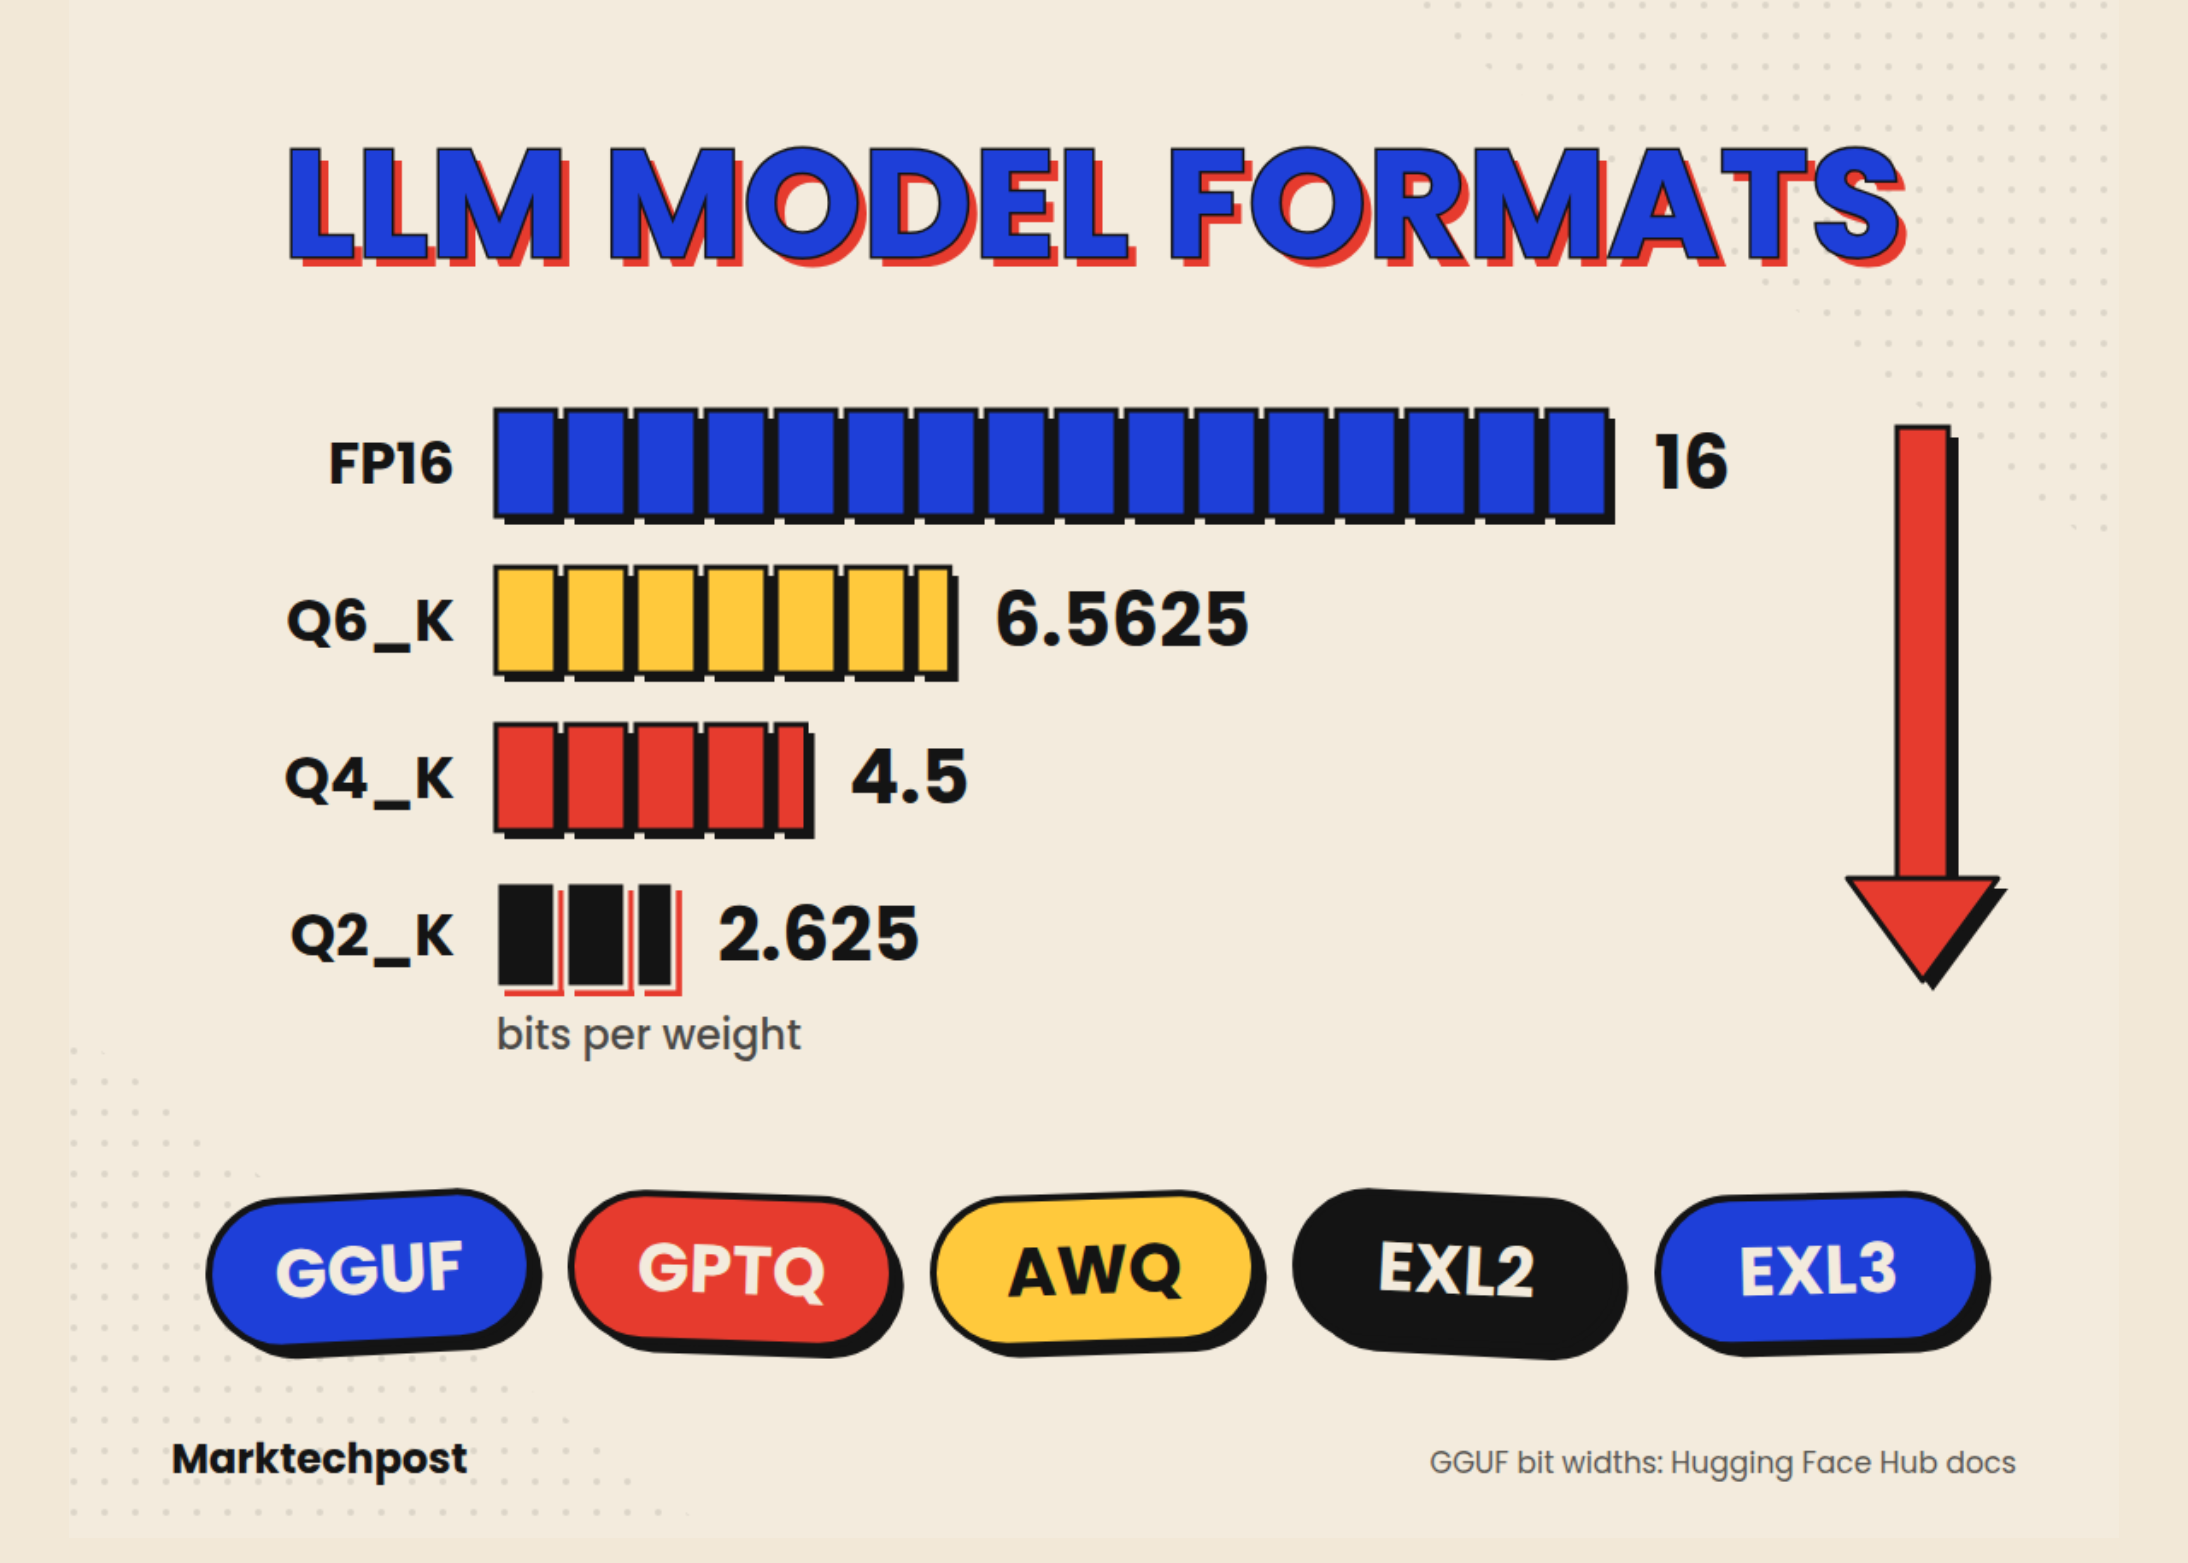
GGUF vs GPTQ vs AWQ vs EXL2: LLM Model Formats Explained (2026)

Asif Razzaq is the CEO of Marktechpost Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.


[Recommended Read] Rightsify’s GCX: Your Go-To Source for High-Quality, Ethically Sourced, Copyright-Cleared AI Music Training Datasets with Rich Metadata


Credit: Source link

ShareTweetSendSharePin

Related Posts

Linkup Research Releases SPARSEUP: A 149M-Parameter Open-Source Sparse Embedding Model
AI & Technology

Linkup Research Releases SPARSEUP: A 149M-Parameter Open-Source Sparse Embedding Model

September 19, 2026
GGUF vs GPTQ vs AWQ vs EXL2: LLM Model Formats Explained (2026)
AI & Technology

GGUF vs GPTQ vs AWQ vs EXL2: LLM Model Formats Explained (2026)

September 19, 2026
Consumers Sue Anthropic, OpenAI, SpaceXAI and Google Over Alleged AI Pact – Unite.AI
AI & Technology

Consumers Sue Anthropic, OpenAI, SpaceXAI and Google Over Alleged AI Pact – Unite.AI

September 19, 2026
How Focus Mode Has Changed In iOS 27
AI & Technology

How Focus Mode Has Changed In iOS 27

September 18, 2026
Next Post
Special counsel says Biden will not be charged for retaining classified documents

Special counsel says Biden will not be charged for retaining classified documents

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Jurors from Clancy trial speak out after deadlocked jury

Jurors from Clancy trial speak out after deadlocked jury

September 15, 2026
Stalking suspect arrested near Kris Jenner’s L.A. home

Stalking suspect arrested near Kris Jenner’s L.A. home

September 14, 2026
Top soccer bosses demand slice of FIFA’s B pie, blast scrapped Kushner deal

Top soccer bosses demand slice of FIFA’s $6B pie, blast scrapped Kushner deal

September 18, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!