• bitcoinBitcoin(BTC)$76,900.00-1.16%
  • ethereumEthereum(ETH)$2,475.73-1.35%
  • tetherTether(USDT)$1.000.01%
  • binancecoinBNB(BNB)$718.45-0.42%
  • rippleXRP(XRP)$1.410.49%
  • usd-coinUSDC(USDC)$1.000.00%
  • solanaSolana(SOL)$100.92-0.61%
  • tronTRON(TRX)$0.338267-0.58%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.030.66%
  • zcashZcash(ZEC)$1,127.94-0.43%
  • HyperliquidHyperliquid(HYPE)$79.27-1.03%
  • dogecoinDogecoin(DOGE)$0.082649-1.58%
  • USDSUSDS(USDS)$1.000.01%
  • moneroMonero(XMR)$518.171.41%
  • whitebitWhiteBIT Coin(WBT)$79.55-1.26%
  • RainRain(RAIN)$0.013141-12.67%
  • chainlinkChainlink(LINK)$11.370.20%
  • leo-tokenLEO Token(LEO)$8.970.10%
  • cardanoCardano(ADA)$0.204981-2.17%
  • stellarStellar(XLM)$0.1961951.80%
  • Ethena USDeEthena USDe(USDE)$1.000.01%
  • daiDai(DAI)$1.000.02%
  • bitcoin-cashBitcoin Cash(BCH)$222.640.06%
  • USD1USD1(USD1)$1.000.00%
  • uniswapUniswap(UNI)$6.716.69%
  • litecoinLitecoin(LTC)$52.44-2.25%
  • CantonCanton(CC)$0.095137-1.15%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.34-0.76%
  • hedera-hashgraphHedera(HBAR)$0.0787182.03%
  • avalanche-2Avalanche(AVAX)$7.530.41%
  • Global DollarGlobal Dollar(USDG)$1.000.01%
  • nearNEAR Protocol(NEAR)$2.37-1.54%
  • shiba-inuShiba Inu(SHIB)$0.000005-1.87%
  • suiSui(SUI)$0.71-1.97%
  • paypal-usdPayPal USD(PYUSD)$1.000.00%
  • crypto-com-chainCronos(CRO)$0.057378-3.98%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • tether-goldTether Gold(XAUT)$4,283.19-0.02%
  • Circle USYCCircle USYC(USYC)$1.140.00%
  • BittensorBittensor(TAO)$224.15-4.18%
  • MemeCoreMemeCore(M)$1.11-1.70%
  • okbOKB(OKB)$112.71-1.00%
  • Ripple USDRipple USD(RLUSD)$1.000.02%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.15-0.03%
  • aaveAave(AAVE)$127.751.60%
  • BitwayBitway(BTW)$0.711.32%
  • AsterAster(ASTER)$0.69-0.90%
  • pax-goldPAX Gold(PAXG)$4,284.31-0.08%
  • mantleMantle(MNT)$0.56-2.20%
  • World Liberty FinancialWorld Liberty Financial(WLFI)$0.0571370.15%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Google DeepMind and Anthropic Researchers Introduce Equal-Info Windows: A Groundbreaking AI Method for Efficient LLM Training on Compressed Text

April 9, 2024
in AI & Technology
Reading Time: 5 mins read
A A
Google DeepMind and Anthropic Researchers Introduce Equal-Info Windows: A Groundbreaking AI Method for Efficient LLM Training on Compressed Text
ShareShareShareShareShare

The training of Large Language Models (LLMs) has been shackled by the limitations of subword tokenization, a method that, while effective to a degree, demands considerable computational resources. This has not only capped the potential for model scaling but also restricted the training on expansive datasets without incurring prohibitive costs. The challenge has been twofold: how to significantly compress text to facilitate efficient model training and simultaneously maintain or even enhance the performance of these models.

Existing research includes leveraging transformer language models, such as the Chinchilla model, for efficient data compression, demonstrating substantial text size reduction capabilities. Innovations in Arithmetic Coding, adjusted for better LLM compatibility, and exploring “token-free” language modeling through convolutional downsampling offer alternative paths for neural tokenization. Using learned tokenizers in audio compression and applying GZip’s modeling components for varied AI tasks extend the utility of compression algorithms. Studies employing static Huffman coding with n-gram models present a different approach, prioritizing simplicity over maximum compression efficiency.

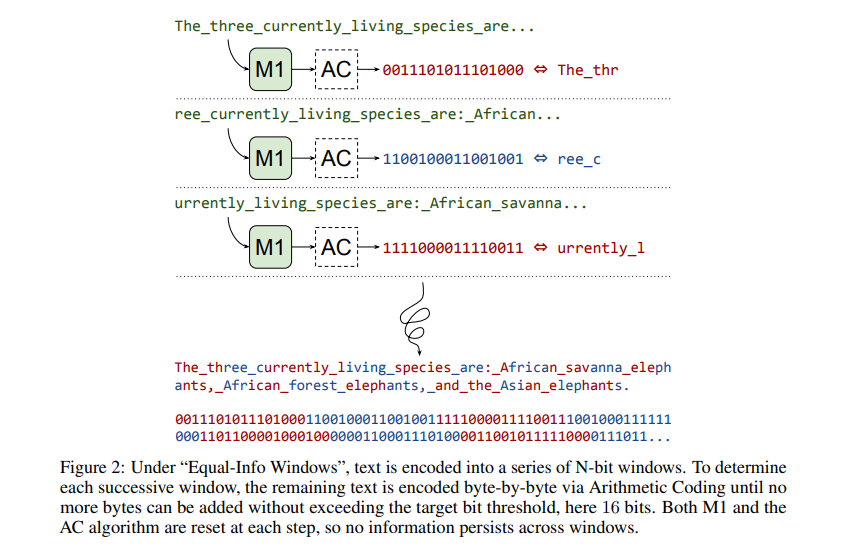
Google Deepmind and Anthropic researchers have introduced a novel approach for training LLMs on neurally compressed text, named ‘Equal-Info Windows.’ This technique achieves significantly higher compression rates than traditional methods without compromising the learnability or performance of LLMs. The key innovation lies in processing highly compressed text that retains efficiency and effectiveness in model training and inference tasks.

The methodology employs a two-model system: M1, a smaller language model for compressing text using Arithmetic Coding, and M2, a larger LLM trained on the compressed output. The process involves segmenting text into uniform blocks that each compress to a specific bit length and then tokenizing this compressed data for M2 training. The research utilizes the C4 (Cleaned Common Crawl Corpus) dataset for model training. This setup aims to maintain efficiency and effectiveness in model performance across large datasets by ensuring consistent compression rates and providing stable inputs for the LLM, highlighting the practical application of the “Equal-Info Windows” technique.
The results show that models trained using “Equal-Info Windows” significantly outperform traditional methods. Specifically, LLMs utilizing this technique remarkably improved perplexity scores and inference speeds. For example, models trained with “Equal-Info Windows” on perplexity benchmarks surpassed byte-level baselines by a wide margin, reducing perplexity by up to 30% across various tests. Furthermore, there was a noticeable acceleration in inference speed, with models demonstrating up to a 40% increase in processing speed compared to conventional training setups. These metrics underscore the effectiveness of the proposed method in enhancing the efficiency and performance of large language models trained on compressed text.

In conclusion, the research introduced “Equal-Info Windows,” a novel method for training large language models on compressed text, achieving higher efficiency without compromising performance. Segmenting text into uniform blocks for consistent compression enhances model learnability and inference speeds. The successful application of the C4 dataset demonstrates the method’s effectiveness, marking a significant advancement in model training methodologies. This work improves the scalability and performance of language models and opens new avenues for research in data compression and efficient model training.


Check out the Paper. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter. Join our Telegram Channel, Discord Channel, and LinkedIn Group.

If you like our work, you will love our newsletter with 24k+ members…

Don’t Forget to join our 40k+ ML SubReddit

YOU MAY ALSO LIKE

2 Ways Android Users Can Take Advantage Of Apple’s MagSafe Accessories

Apple TV Cleaned Up At The Emmys With Eight Wins For Widow’s Bay And Pluribus

Nikhil is an intern consultant at Marktechpost. He is pursuing an integrated dual degree in Materials at the Indian Institute of Technology, Kharagpur. Nikhil is an AI/ML enthusiast who is always researching applications in fields like biomaterials and biomedical science. With a strong background in Material Science, he is exploring new advancements and creating opportunities to contribute.


🐝 Join the Fastest Growing AI Research Newsletter Read by Researchers from Google + NVIDIA + Meta + Stanford + MIT + Microsoft and many others…


Credit: Source link

ShareTweetSendSharePin

Related Posts

2 Ways Android Users Can Take Advantage Of Apple’s MagSafe Accessories
AI & Technology

2 Ways Android Users Can Take Advantage Of Apple’s MagSafe Accessories

September 15, 2026
Apple TV Cleaned Up At The Emmys With Eight Wins For Widow’s Bay And Pluribus
AI & Technology

Apple TV Cleaned Up At The Emmys With Eight Wins For Widow’s Bay And Pluribus

September 15, 2026
Elsevier Integrates LG AI Research’s Chemistry Vision Model Into Reaxys – Unite.AI
AI & Technology

Elsevier Integrates LG AI Research’s Chemistry Vision Model Into Reaxys – Unite.AI

September 15, 2026
Double The Range And Smarter Safety, Too
AI & Technology

Double The Range And Smarter Safety, Too

September 15, 2026
Next Post
FirstCash Stands To Benefit From Pressures On Both Consumers And Other Lenders (FCFS)

FirstCash Stands To Benefit From Pressures On Both Consumers And Other Lenders (FCFS)

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Anthropic Adds Plugin Evals to Claude Code: 6 Grader Types, a No-Plugin Baseline, and a CI Gate for Skills

Anthropic Adds Plugin Evals to Claude Code: 6 Grader Types, a No-Plugin Baseline, and a CI Gate for Skills

September 11, 2026
Morning News NOW Full Episode – Sept. 9

Morning News NOW Full Episode – Sept. 9

September 15, 2026
Documents show presidents were warned about plane attack

Documents show presidents were warned about plane attack

September 12, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!