• bitcoinBitcoin(BTC)$76,845.00-0.10%
  • ethereumEthereum(ETH)$2,259.980.35%
  • tetherTether(USDT)$1.000.02%
  • binancecoinBNB(BNB)$692.38-0.50%
  • rippleXRP(XRP)$1.250.36%
  • usd-coinUSDC(USDC)$1.000.02%
  • solanaSolana(SOL)$91.81-0.22%
  • tronTRON(TRX)$0.3223610.71%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.03-0.22%
  • zcashZcash(ZEC)$1,200.515.30%
  • HyperliquidHyperliquid(HYPE)$82.92-1.10%
  • moneroMonero(XMR)$631.184.18%
  • dogecoinDogecoin(DOGE)$0.074007-0.18%
  • USDSUSDS(USDS)$1.000.04%
  • whitebitWhiteBIT Coin(WBT)$73.87-0.05%
  • leo-tokenLEO Token(LEO)$9.30-0.07%
  • chainlinkChainlink(LINK)$10.85-1.97%
  • cardanoCardano(ADA)$0.187241-0.76%
  • stellarStellar(XLM)$0.159916-1.06%
  • bitcoin-cashBitcoin Cash(BCH)$271.04-1.30%
  • nearNEAR Protocol(NEAR)$3.77-1.41%
  • RainRain(RAIN)$0.006471-4.08%
  • daiDai(DAI)$1.000.03%
  • Ethena USDeEthena USDe(USDE)$1.000.10%
  • uniswapUniswap(UNI)$7.092.46%
  • litecoinLitecoin(LTC)$53.19-1.18%
  • CantonCanton(CC)$0.0967343.49%
  • USD1USD1(USD1)$1.000.16%
  • avalanche-2Avalanche(AVAX)$8.420.95%
  • suiSui(SUI)$0.881.30%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.16-1.61%
  • tether-goldTether Gold(XAUT)$3,932.430.05%
  • hedera-hashgraphHedera(HBAR)$0.068495-1.56%
  • Global DollarGlobal Dollar(USDG)$1.000.02%
  • quant-networkQuant(QNT)$190.17-1.48%
  • paypal-usdPayPal USD(PYUSD)$1.000.03%
  • shiba-inuShiba Inu(SHIB)$0.0000050.05%
  • BittensorBittensor(TAO)$221.96-0.36%
  • Ripple USDRipple USD(RLUSD)$1.000.01%
  • crypto-com-chainCronos(CRO)$0.049628-0.75%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.16%
  • EthenaEthena(ENA)$0.1705361.17%
  • okbOKB(OKB)$106.99-1.82%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • pepePepe(PEPE)$0.0000050.63%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • MemeCoreMemeCore(M)$0.863.03%
  • Pump.funPump.fun(PUMP)$0.0042106.67%
  • aaveAave(AAVE)$125.25-0.30%
  • Spiko Amundi Overnight Swap Fund (EUR)Spiko Amundi Overnight Swap Fund (EUR)(EURSAFO)$1.140.45%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Bridging Modalities with VisionLLaMA: A Unified Architecture for Vision Tasks

March 9, 2024
in AI & Technology
Reading Time: 4 mins read
A A
Bridging Modalities with VisionLLaMA: A Unified Architecture for Vision Tasks
ShareShareShareShareShare

Large language models, predominantly based on transformer architectures, have reshaped natural language processing. The LLaMA family of models has emerged as a prominent example. However, a fundamental question arises: can the same transformer architecture be effectively applied to process 2D images? This paper introduces VisionLLaMA, a vision transformer tailored to bridge the gap between language and vision modalities. In this article, we explore the key aspects of VisionLLaMA, from its architecture and design principles to its performance in various vision tasks.

VisionLLaMA closely follows the pipeline of Vision Transformer (ViT) while retaining the architectural design of LLaMA. The image is segmented into non-overlapping patches and processed through VisionLLaMA blocks, which include features such as self-attention via Rotary Positional Encodings (RoPE) and SwiGLU activation. Notably, VisionLLaMA varies from ViT by relying solely on the inherent positional encoding of its basic block.

The paper focuses on two versions of VisionLLaMA: plain and pyramid transformers. The plain variant is consistent with the ViT architecture, whereas the pyramid variant investigates extending VisionLLaMA to window-based transformers (Twins). The purpose is not to construct new pyramid transformers but rather to show how VisionLLaMA adapts to existing designs, exhibiting adaptability across architectures.

Numerous experiments assess VisionLLaMA’s performance in image generation, classification, segmentation, and detection. VisionLLaMA has been incorporated into the DiT diffusion framework for image generation and the SiT generative model framework to evaluate its merits in model architecture. Results show that VisionLLaMA consistently outperforms across model sizes, validating its efficiency as a vision backbone. VisionLLaMA’s design choices, such as using SwiGLU, normalization techniques, positional encoding ratios, and feature abstraction methods, are investigated in ablation studies. The study offers insights into the dependability and efficiency of VisionLLaMA’s constituent parts, directing decisions about its implementation.

The experiments can be summarized as:

  • Image Generation on DiT and SiT Diffusion Frameworks
  • Classification on ImageNet-1K Dataset
  • Semantic Segmentation on ADE20K Dataset
  • Object Detection on COCO 

The performances of supervised and self-supervised training were compared, and the models were fine-tuned accordingly. 

Additional analysis of the underlying mechanisms enabling VisionLLaMA’s improved performance can be found in the discussion section. The model’s positional encoding technique and insights into how it affects convergence speed and overall performance are highlighted. The flexibility provided by RoPE is highlighted as an essential factor in efficiently leveraging model capacity.

The paper proposes VisionLLaMA as an appealing architecture for vision tasks, laying the groundwork for further investigations. The exploration of its capabilities in various applications suggests further possibilities, like expanding the capabilities of VisionLLaMA beyond text and vision to create a more inclusive and adaptable model architecture.

In conclusion, VisionLLaMA provides a seamless architecture that cuts across modalities, bridging the link between language and vision. Together, its theoretical justification, experimental validation, and design choices highlight VisionLLaMA’s ability to significantly impact the field of vision tasks. The open-source release promotes cooperative research and creativity in the field of large vision transformers a lot further.


Check out the Paper and Github. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter and Google News. Join our 38k+ ML SubReddit, 41k+ Facebook Community, Discord Channel, and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our Telegram Channel

You may also like our FREE AI Courses….


YOU MAY ALSO LIKE

Cat Wu Steps Down as Claude Code Product Chief After Two Years – Unite.AI

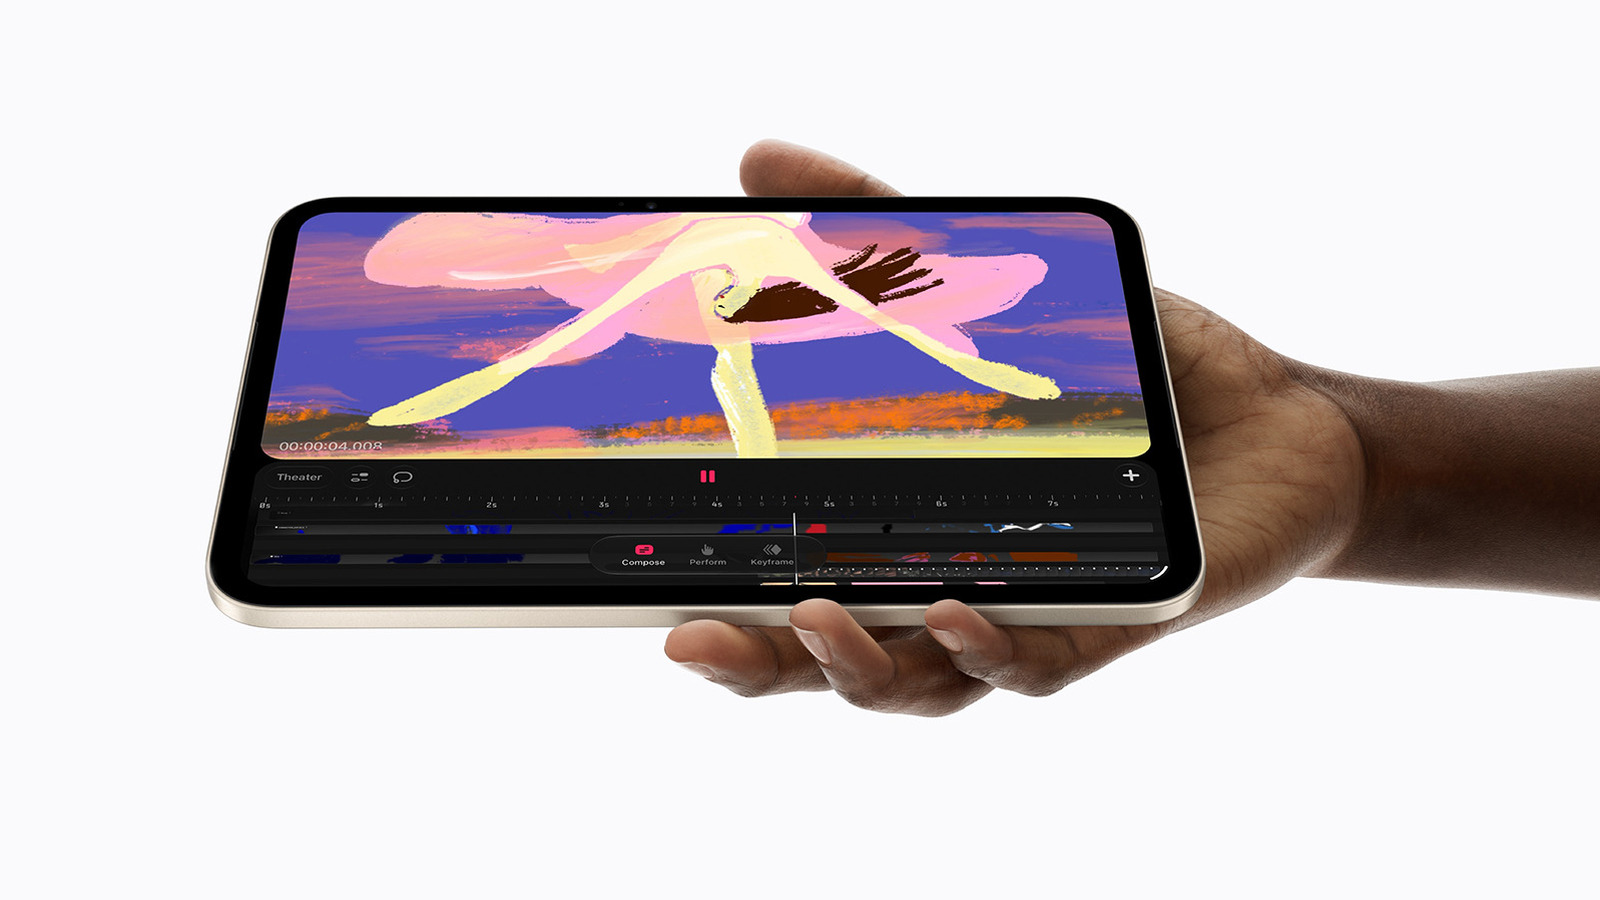
iPad Mini OLED Vs. iPad Mini: What’s New?

Vibhanshu Patidar is a consulting intern at MarktechPost. Currently pursuing B.S. at Indian Institute of Technology (IIT) Kanpur. He is a Robotics and Machine Learning enthusiast with a knack for unraveling the complexities of algorithms that bridge theory and practical applications.


🚀 [FREE AI WEBINAR] ‘Building with Google’s New Open Gemma Models’ (March 11, 2024) [Promoted]


Credit: Source link

ShareTweetSendSharePin

Related Posts

Cat Wu Steps Down as Claude Code Product Chief After Two Years – Unite.AI
AI & Technology

Cat Wu Steps Down as Claude Code Product Chief After Two Years – Unite.AI

November 4, 2026
iPad Mini OLED Vs. iPad Mini: What’s New?
AI & Technology

iPad Mini OLED Vs. iPad Mini: What’s New?

November 4, 2026
Ouster Revenue Rises 50% as Physical AI Sensor Shipments Set Record – Unite.AI
AI & Technology

Ouster Revenue Rises 50% as Physical AI Sensor Shipments Set Record – Unite.AI

November 3, 2026
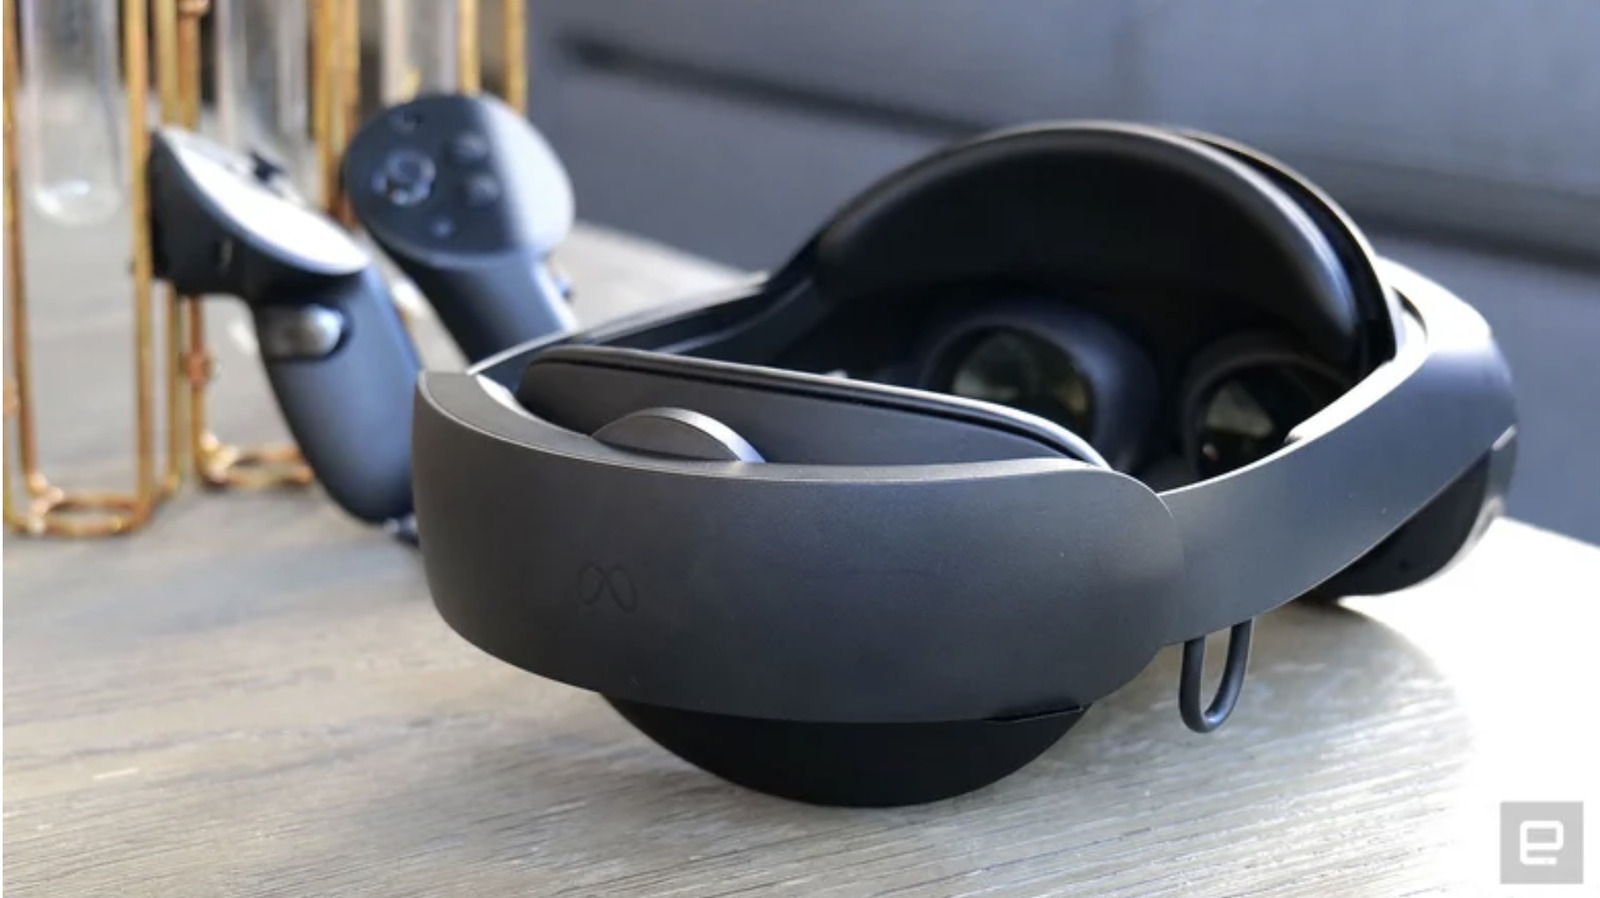
Meta’s Quest 2 And Quest Pro Reach ‘End Of Feature Development’
AI & Technology

Meta’s Quest 2 And Quest Pro Reach ‘End Of Feature Development’

November 3, 2026
Next Post
Petróleo Brasileiro S.A. – Petrobras (PBR) Q4 2023 Earnings Call Transcript

Petróleo Brasileiro S.A. - Petrobras (PBR) Q4 2023 Earnings Call Transcript

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Reporter describes intensity of Hurricane Isaias winds

Reporter describes intensity of Hurricane Isaias winds

October 28, 2026
Meta Weighs Delaying ‘Alarming’ New Business Terms As Backlash Grows

Meta Weighs Delaying ‘Alarming’ New Business Terms As Backlash Grows

October 28, 2026
Flydubai hero recounts risking his life on flight to save family

Flydubai hero recounts risking his life on flight to save family

November 1, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!