• bitcoinBitcoin(BTC)$73,630.00-2.08%
  • ethereumEthereum(ETH)$2,046.71-4.06%
  • tetherTether(USDT)$1.000.01%
  • binancecoinBNB(BNB)$677.54-1.83%
  • usd-coinUSDC(USDC)$1.000.01%
  • rippleXRP(XRP)$1.06-4.28%
  • solanaSolana(SOL)$82.86-4.46%
  • tronTRON(TRX)$0.3176750.16%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.04-0.95%
  • zcashZcash(ZEC)$1,037.82-11.30%
  • HyperliquidHyperliquid(HYPE)$72.21-4.32%
  • dogecoinDogecoin(DOGE)$0.067782-3.13%
  • moneroMonero(XMR)$560.13-5.58%
  • leo-tokenLEO Token(LEO)$9.30-0.02%
  • USDSUSDS(USDS)$1.000.00%
  • whitebitWhiteBIT Coin(WBT)$70.95-2.09%
  • chainlinkChainlink(LINK)$10.29-3.58%
  • cardanoCardano(ADA)$0.173406-2.46%
  • stellarStellar(XLM)$0.144722-2.09%
  • Ethena USDeEthena USDe(USDE)$1.000.05%
  • nearNEAR Protocol(NEAR)$3.55-2.36%
  • bitcoin-cashBitcoin Cash(BCH)$230.68-3.38%
  • daiDai(DAI)$1.000.02%
  • uniswapUniswap(UNI)$6.65-5.47%
  • litecoinLitecoin(LTC)$50.55-1.80%
  • avalanche-2Avalanche(AVAX)$8.34-3.36%
  • CantonCanton(CC)$0.088971-3.75%
  • suiSui(SUI)$0.82-3.01%
  • tether-goldTether Gold(XAUT)$4,022.18-2.23%
  • USD1USD1(USD1)$1.000.08%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.149.93%
  • hedera-hashgraphHedera(HBAR)$0.065551-2.32%
  • RainRain(RAIN)$0.003873-14.80%
  • paypal-usdPayPal USD(PYUSD)$1.000.01%
  • Ripple USDRipple USD(RLUSD)$1.000.01%
  • Global DollarGlobal Dollar(USDG)$1.000.00%
  • quant-networkQuant(QNT)$181.49-7.14%
  • shiba-inuShiba Inu(SHIB)$0.0000040.02%
  • BittensorBittensor(TAO)$217.03-2.84%
  • crypto-com-chainCronos(CRO)$0.047161-1.87%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.03%
  • pepePepe(PEPE)$0.0000053.49%
  • Circle USYCCircle USYC(USYC)$1.140.02%
  • okbOKB(OKB)$97.530.77%
  • EthenaEthena(ENA)$0.150688-2.24%
  • Spiko Amundi Overnight Swap Fund (EUR)Spiko Amundi Overnight Swap Fund (EUR)(EURSAFO)$1.14-0.48%
  • aaveAave(AAVE)$123.97-6.52%
  • Falcon USDFalcon USD(USDF)$0.990.00%
  • pax-goldPAX Gold(PAXG)$4,025.23-2.26%
  • MemeCoreMemeCore(M)$0.780.26%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Researchers from UCI and Zhejiang University Introduce Lossless Large Language Model Acceleration via Self-Speculative Decoding Using Drafting And Verifying Stages

September 22, 2023
in AI & Technology
Reading Time: 4 mins read
A A
Researchers from UCI and Zhejiang University Introduce Lossless Large Language Model Acceleration via Self-Speculative Decoding Using Drafting And Verifying Stages
ShareShareShareShareShare

Large Language Models (LLMs) based on transformers, such as GPT, PaLM, and LLaMA, have become widely used in a variety of real-world applications. These models have been applied to a variety of tasks, including text production, translation, and natural language interpretation. However, these models’ high inference costs, particularly in situations where low latency is important, are a major concern. The autoregressive decoding method used by these models is the main cause of the high inference costs. Since each output token is produced sequentially during autoregressive decoding, there are a lot of Transformer calls. The memory bandwidth of each Transformer call is limited, leading to inefficient computation and prolonged execution times.

In order to speed up the inference process of Large Language Models (LLMs), a recent study has introduced a unique method called self-speculative decoding that does not require an auxiliary model. This approach tackles the problem of producing the inference more quickly while preserving output quality. It is characterized by a two-stage procedure that combines drafting and verification.

  1. Drafting Stage – The objective of the drafting stage is to produce draught tokens more quickly, even if they are marginally of worse quality than tokens produced using the conventional autoregressive method. The method bypasses some intermediary layers during drafting to accomplish this. These intermediary layers in LLMs often refine the output, but they also take up a lot of time and resources during inference. 
  1. Verification Stage: The technique generates the draught output tokens in the drafting stage and then validates them in a single forward pass using the original, unaltered LLM. Using the conventional autoregressive decoding technique, the LLM would have produced the same end result, which is ensured by this verification step. Because of this, even if the drafting stage generated tokens more quickly, the end product’s quality is preserved.

Self-speculative decoding does not require further neural network training, which is one of its main advantages. Training auxiliary models or making significant changes to the LLM’s architecture, which can be challenging and resource-intensive, are common components of existing methods for faster inference. Self-speculative decoding, on the other hand, is a “plug-and-play” approach that can be added to existing LLMs without additional training or model alterations.

The research has offered empirical support for self-speculative decoding’s efficacy. The benchmark results are shown using LLaMA-2 and its improved models. Based on these benchmarks, the self-speculative decoding method can decode data up to 1.73 times faster than the conventional autoregressive method. This has the important benefit of making the inference process approximately twice as quick while preserving output quality, which is important in situations when latency is an issue.

In conclusion, self-speculative decoding is a revolutionary method that enhances how Large Language Models infer information. It accomplishes this by establishing a two-step process of drafting and verification, choosing which layers to skip during the drafting stage to generate tokens more quickly, and verifying the output quality during the verification stage. This method speeds up LLM inference without adding any extra memory burden or training requirements for neural networks. 


Check out the Paper. All Credit For This Research Goes To the Researchers on This Project. Also, don’t forget to join our 30k+ ML SubReddit, 40k+ Facebook Community, Discord Channel, and Email Newsletter, where we share the latest AI research news, cool AI projects, and more.

If you like our work, you will love our newsletter..


YOU MAY ALSO LIKE

Meta Warns Some Of Its AI Glasses May Get ‘Too Warm’ If They Get Wet

SPARETECH Secures $20M Series B Funding for North American Growth – Unite.AI

Tanya Malhotra is a final year undergrad from the University of Petroleum & Energy Studies, Dehradun, pursuing BTech in Computer Science Engineering with a specialization in Artificial Intelligence and Machine Learning.
She is a Data Science enthusiast with good analytical and critical thinking, along with an ardent interest in acquiring new skills, leading groups, and managing work in an organized manner.


🚀 The end of project management by humans (Sponsored)

Credit: Source link

ShareTweetSendSharePin

Related Posts

Meta Warns Some Of Its AI Glasses May Get ‘Too Warm’ If They Get Wet
AI & Technology

Meta Warns Some Of Its AI Glasses May Get ‘Too Warm’ If They Get Wet

November 10, 2026
SPARETECH Secures M Series B Funding for North American Growth – Unite.AI
AI & Technology

SPARETECH Secures $20M Series B Funding for North American Growth – Unite.AI

November 10, 2026
The Best-Selling Game Console Of All Time Is Over 25 Years Old
AI & Technology

The Best-Selling Game Console Of All Time Is Over 25 Years Old

November 10, 2026
Ohio State and Microsoft Form Five-Year Clinical AI Partnership – Unite.AI
AI & Technology

Ohio State and Microsoft Form Five-Year Clinical AI Partnership – Unite.AI

November 10, 2026
Next Post
Car Sales, Healthcare Lead Stocks Higher

Car Sales, Healthcare Lead Stocks Higher

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Stocks Are UP But Your Portfolio Is RED?! Here’s Why.

Stocks Are UP But Your Portfolio Is RED?! Here’s Why.

November 5, 2026
College Football Playoff top 12 projection after Week 10 – ESPN

College Football Playoff top 12 projection after Week 10 – ESPN

November 8, 2026
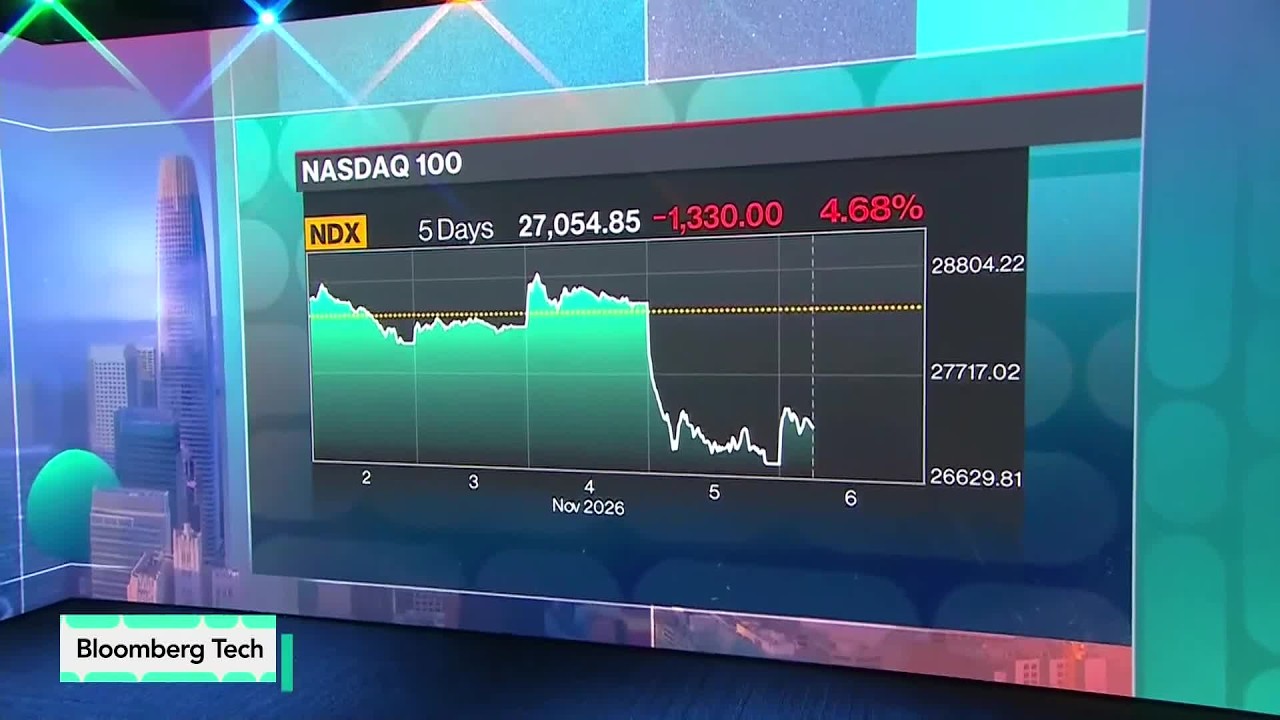
How Fast-Money Systematic Funds Stoked .3T Tech Rout

How Fast-Money Systematic Funds Stoked $2.3T Tech Rout

November 7, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!