• bitcoinBitcoin(BTC)$77,339.000.21%
  • ethereumEthereum(ETH)$2,244.711.80%
  • tetherTether(USDT)$1.000.12%
  • binancecoinBNB(BNB)$705.39-0.58%
  • rippleXRP(XRP)$1.263.33%
  • usd-coinUSDC(USDC)$1.000.12%
  • solanaSolana(SOL)$96.872.03%
  • tronTRON(TRX)$0.325830-8.24%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.03-0.30%
  • zcashZcash(ZEC)$1,274.791.28%
  • HyperliquidHyperliquid(HYPE)$89.78-1.03%
  • dogecoinDogecoin(DOGE)$0.0758691.58%
  • moneroMonero(XMR)$591.84-2.50%
  • USDSUSDS(USDS)$1.000.38%
  • chainlinkChainlink(LINK)$11.578.52%
  • whitebitWhiteBIT Coin(WBT)$74.260.57%
  • leo-tokenLEO Token(LEO)$9.460.71%
  • cardanoCardano(ADA)$0.1944423.17%
  • stellarStellar(XLM)$0.1693504.37%
  • bitcoin-cashBitcoin Cash(BCH)$290.825.41%
  • nearNEAR Protocol(NEAR)$4.357.40%
  • daiDai(DAI)$1.000.08%
  • Ethena USDeEthena USDe(USDE)$1.000.22%
  • RainRain(RAIN)$0.006284-3.44%
  • uniswapUniswap(UNI)$7.056.72%
  • litecoinLitecoin(LTC)$55.410.81%
  • CantonCanton(CC)$0.0981406.64%
  • USD1USD1(USD1)$1.000.11%
  • avalanche-2Avalanche(AVAX)$8.613.77%
  • suiSui(SUI)$0.904.82%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.192.41%
  • hedera-hashgraphHedera(HBAR)$0.0721663.95%
  • tether-goldTether Gold(XAUT)$3,874.89-2.88%
  • Global DollarGlobal Dollar(USDG)$1.000.07%
  • quant-networkQuant(QNT)$196.018.53%
  • paypal-usdPayPal USD(PYUSD)$1.000.30%
  • shiba-inuShiba Inu(SHIB)$0.0000055.14%
  • BittensorBittensor(TAO)$237.102.27%
  • crypto-com-chainCronos(CRO)$0.0518093.02%
  • EthenaEthena(ENA)$0.1923646.61%
  • Ripple USDRipple USD(RLUSD)$1.000.12%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.05%
  • Circle USYCCircle USYC(USYC)$1.140.03%
  • okbOKB(OKB)$111.271.10%
  • MemeCoreMemeCore(M)$0.96-4.37%
  • pepePepe(PEPE)$0.0000055.67%
  • OndoOndo(ONDO)$0.41889111.21%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • aaveAave(AAVE)$130.778.03%
  • Pump.funPump.fun(PUMP)$0.0041275.50%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Do You Really Need Reinforcement Learning (RL) in RLHF? A New Stanford Research Proposes DPO (Direct Preference Optimization): A Simple Training Paradigm For Training Language Models From Preferences Without RL

June 3, 2023
in AI & Technology
Reading Time: 4 mins read
A A
Do You Really Need Reinforcement Learning (RL) in RLHF? A New Stanford Research Proposes DPO (Direct Preference Optimization): A Simple Training Paradigm For Training Language Models From Preferences Without RL
ShareShareShareShareShare

When trained on massive datasets, huge unsupervised LMs acquire powers that surprise even their creators. These models, however, are trained on information produced by people with a diverse range of motivations, objectives, and abilities. Not all of these ambitions and abilities may be emulated. It is important to carefully select the model’s desired responses and behavior from its vast store of information and skills to create reliable, effective, and manageable systems.  

Without using explicit reward modeling or reinforcement learning, Stanford University and CZ researchers demonstrate how to optimize a language model to conform to human tastes. Their work shows that the RL-based objective employed by present approaches can be optimized exactly with a simple binary cross-entropy objective, considerably streamlining the preference learning process and demonstrating how this can be done in practice. 

They propose Direct Preference Optimization (DPO). This new algorithm implicitly achieves the same objective as existing RLHF algorithms (reward maximization with a KL-divergence constraint) but is easier to construct and train. While the DPO update intuitively boosts the log ratio of preferred to dispreferred replies, it also includes a dynamic, per-example significance weight that stops the model from degrading.

🚀 JOIN the fastest ML Subreddit Community

Like other algorithms, DPO evaluates the consistency of a reward function with empirical preference data using a theoretical preference model. While conventional approaches define a preference loss using the preference model to train a reward model, DPO instead trains a policy that maximizes the learned reward model using a variable switch. Therefore, DPO may optimize a policy with a simple binary cross-entropy goal given a dataset of human preferences over model responses without explicitly learning a reward function or sampling from the policy during training. 

The work’s findings demonstrate that DPO is as effective as state-of-the-art approaches, such as PPO-based RLHF, for preference-based learning on various tasks, including sentiment modulation, summarization, and dialogue, with language models containing up to 6B parameters. 58% of people prefer DPO summaries to PPO summaries (human evaluations), and 61% prefer DPO summaries to human evaluations in the test set. On Anthropic HH, 60% of the time, single-turn responses from DPOs are preferred over selective completions. 

The team states that DPO has many potential uses beyond only training language models based on human preferences. For example, it can train generative models in various modalities.

The proposed model evaluations go as high as 6B parameters, but the team believes that further work should explore scaling DPO to state-of-the-art models with orders of magnitude more data. The researchers also discovered that the prompt affects GPT -4’s computed win rates. In the future, they plan to investigate the most effective means of eliciting expert opinions from machines. 


Check Out The Paper. Don’t forget to join our 22k+ ML SubReddit, Discord Channel, and Email Newsletter, where we share the latest AI research news, cool AI projects, and more. If you have any questions regarding the above article or if we missed anything, feel free to email us at [email protected]

🚀 Check Out 100’s AI Tools in AI Tools Club


YOU MAY ALSO LIKE

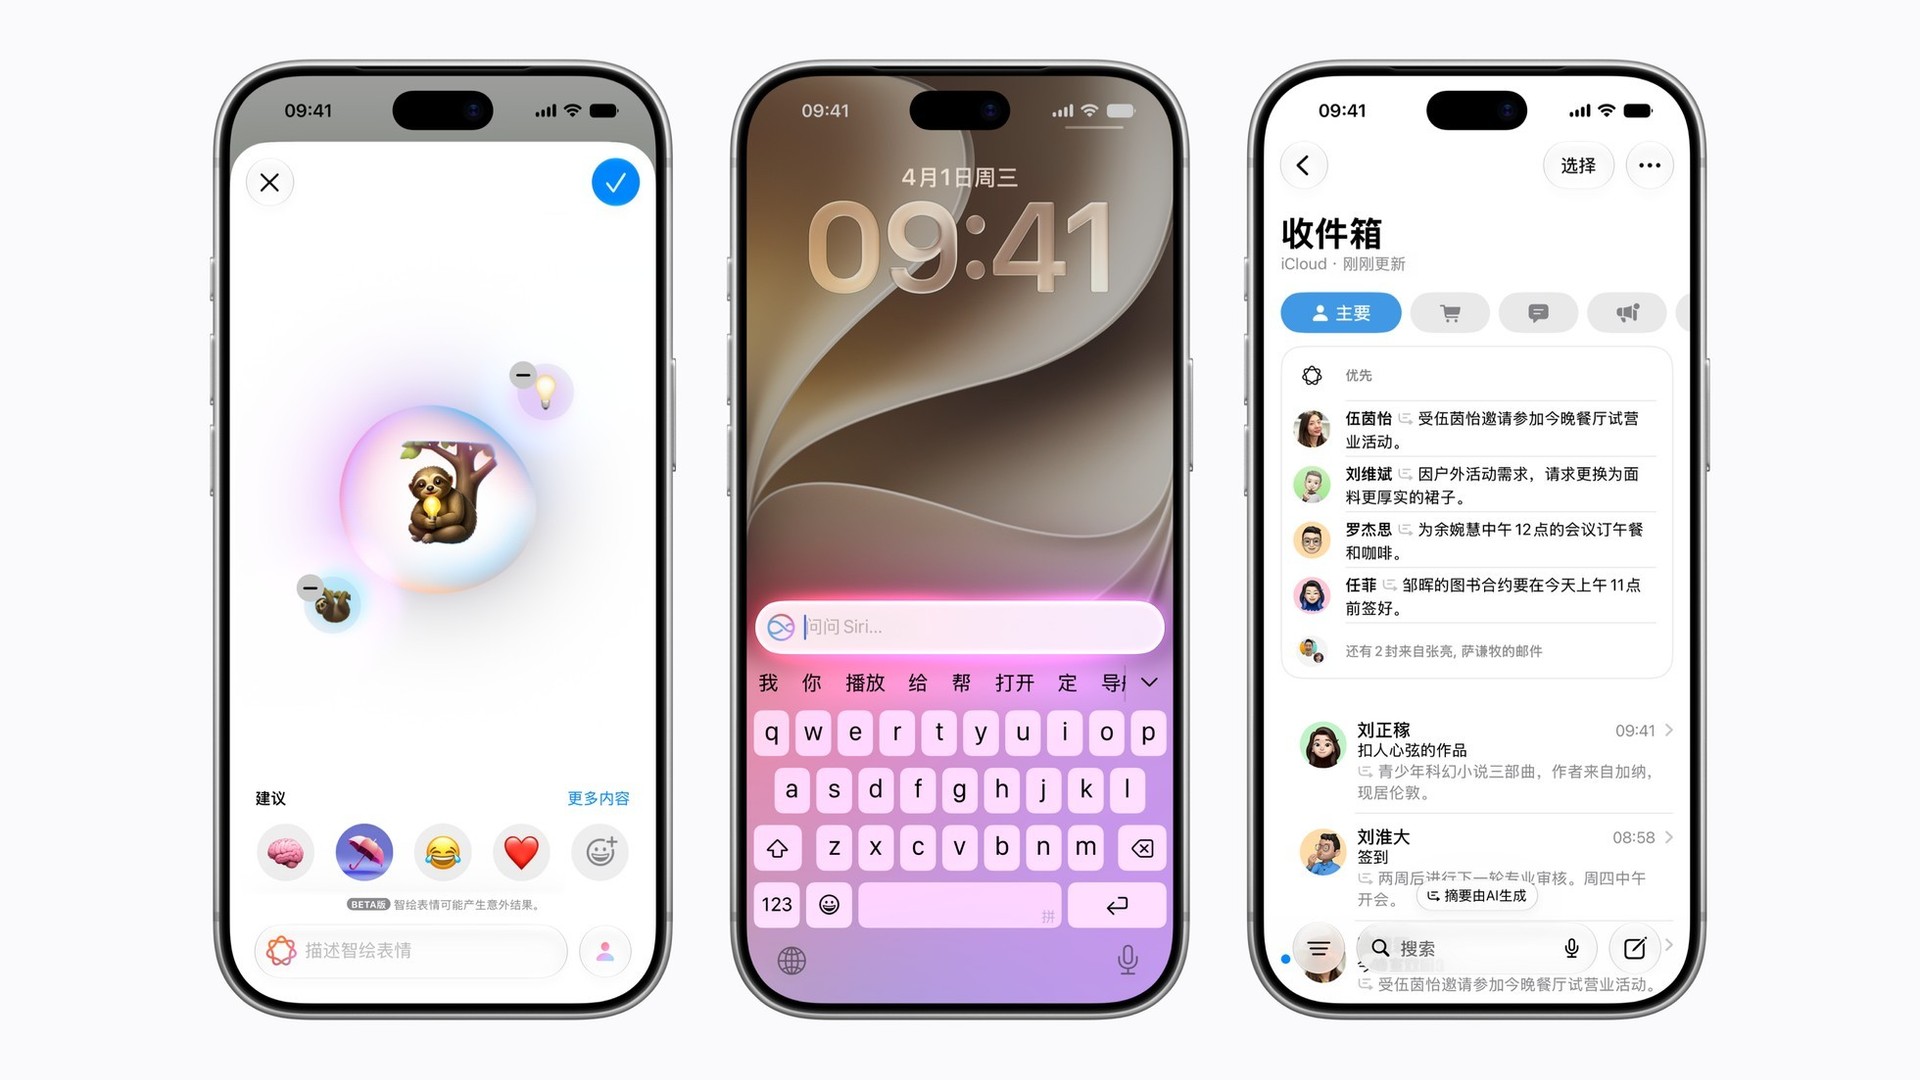
Apple Brings First Apple Intelligence Features to China in iOS 27.3 – Unite.AI

Powerlattice Raises $86M in Equity Offering, SEC Filing Shows – Unite.AI

Tanushree Shenwai is a consulting intern at MarktechPost. She is currently pursuing her B.Tech from the Indian Institute of Technology(IIT), Bhubaneswar. She is a Data Science enthusiast and has a keen interest in the scope of application of artificial intelligence in various fields. She is passionate about exploring the new advancements in technologies and their real-life application.


➡️ Ultimate Guide to Data Labeling in Machine Learning

Credit: Source link

ShareTweetSendSharePin

Related Posts

Apple Brings First Apple Intelligence Features to China in iOS 27.3 – Unite.AI
AI & Technology

Apple Brings First Apple Intelligence Features to China in iOS 27.3 – Unite.AI

October 30, 2026
Powerlattice Raises M in Equity Offering, SEC Filing Shows – Unite.AI
AI & Technology

Powerlattice Raises $86M in Equity Offering, SEC Filing Shows – Unite.AI

October 30, 2026
Databricks Expands SAP Partnership with Genie, Lakeflow, and Lakebase – Unite.AI
AI & Technology

Databricks Expands SAP Partnership with Genie, Lakeflow, and Lakebase – Unite.AI

October 30, 2026
Meta Settles Another Social Media Addiction Case Just Before Trial
AI & Technology

Meta Settles Another Social Media Addiction Case Just Before Trial

October 30, 2026
Next Post
Uber Deal with China’s Didi Said to be Worth  Billion

Uber Deal with China's Didi Said to be Worth $35 Billion

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Passenger steals airport vehicle in California

Passenger steals airport vehicle in California

October 29, 2026
AI Hurricane Tracking; Livestreaming an Execution; Michelle Buteau ‘Survives and Thrives’ in Comedy

AI Hurricane Tracking; Livestreaming an Execution; Michelle Buteau ‘Survives and Thrives’ in Comedy

October 28, 2026
The Fed Holds, but the Pressure Builds

The Fed Holds, but the Pressure Builds

October 30, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!