










• bitcoinBitcoin(BTC)$80,670.000.68%
  • ethereumEthereum(ETH)$2,354.781.66%
  • tetherTether(USDT)$1.00-0.02%
  • binancecoinBNB(BNB)$741.462.42%
  • rippleXRP(XRP)$1.302.28%
  • usd-coinUSDC(USDC)$1.00-0.01%
  • solanaSolana(SOL)$101.821.62%
  • tronTRON(TRX)$0.3297650.18%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.062.32%
  • zcashZcash(ZEC)$1,233.917.20%
  • HyperliquidHyperliquid(HYPE)$77.222.16%
  • dogecoinDogecoin(DOGE)$0.0773191.39%
  • moneroMonero(XMR)$600.59-0.56%
  • USDSUSDS(USDS)$1.00-0.03%
  • whitebitWhiteBIT Coin(WBT)$77.790.91%
  • chainlinkChainlink(LINK)$11.490.70%
  • leo-tokenLEO Token(LEO)$8.99-0.52%
  • cardanoCardano(ADA)$0.2058710.92%
  • nearNEAR Protocol(NEAR)$4.666.21%
  • RainRain(RAIN)$0.0084751.97%
  • stellarStellar(XLM)$0.1697250.42%
  • bitcoin-cashBitcoin Cash(BCH)$279.622.78%
  • Ethena USDeEthena USDe(USDE)$1.00-0.01%
  • daiDai(DAI)$1.00-0.05%
  • litecoinLitecoin(LTC)$57.152.18%
  • uniswapUniswap(UNI)$6.934.26%
  • CantonCanton(CC)$0.1021882.53%
  • avalanche-2Avalanche(AVAX)$8.921.16%
  • USD1USD1(USD1)$1.00-0.02%
  • suiSui(SUI)$0.930.90%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.261.33%
  • hedera-hashgraphHedera(HBAR)$0.0778521.77%
  • tether-goldTether Gold(XAUT)$3,993.390.16%
  • Global DollarGlobal Dollar(USDG)$1.00-0.01%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.04%
  • shiba-inuShiba Inu(SHIB)$0.0000051.16%
  • BittensorBittensor(TAO)$253.212.73%
  • quant-networkQuant(QNT)$191.668.38%
  • crypto-com-chainCronos(CRO)$0.0548250.70%
  • EthenaEthena(ENA)$0.20484010.30%
  • BitwayBitway(BTW)$1.67-4.13%
  • Ripple USDRipple USD(RLUSD)$1.000.00%
  • Circle USYCCircle USYC(USYC)$1.140.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.15-0.10%
  • okbOKB(OKB)$108.200.74%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • aaveAave(AAVE)$138.182.19%
  • MemeCoreMemeCore(M)$0.92-4.99%
  • Pump.funPump.fun(PUMP)$0.0043364.56%
  • OndoOndo(ONDO)$0.4100072.12%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Perplexity Details Its GPU Embedding Stack: How Ivy, Tulip and ROSE Serve pplx-embed

September 6, 2026
in AI & Technology
Reading Time: 12 mins read
A A
Perplexity Details Its GPU Embedding Stack: How Ivy, Tulip and ROSE Serve pplx-embed
ShareShareShareShareShare

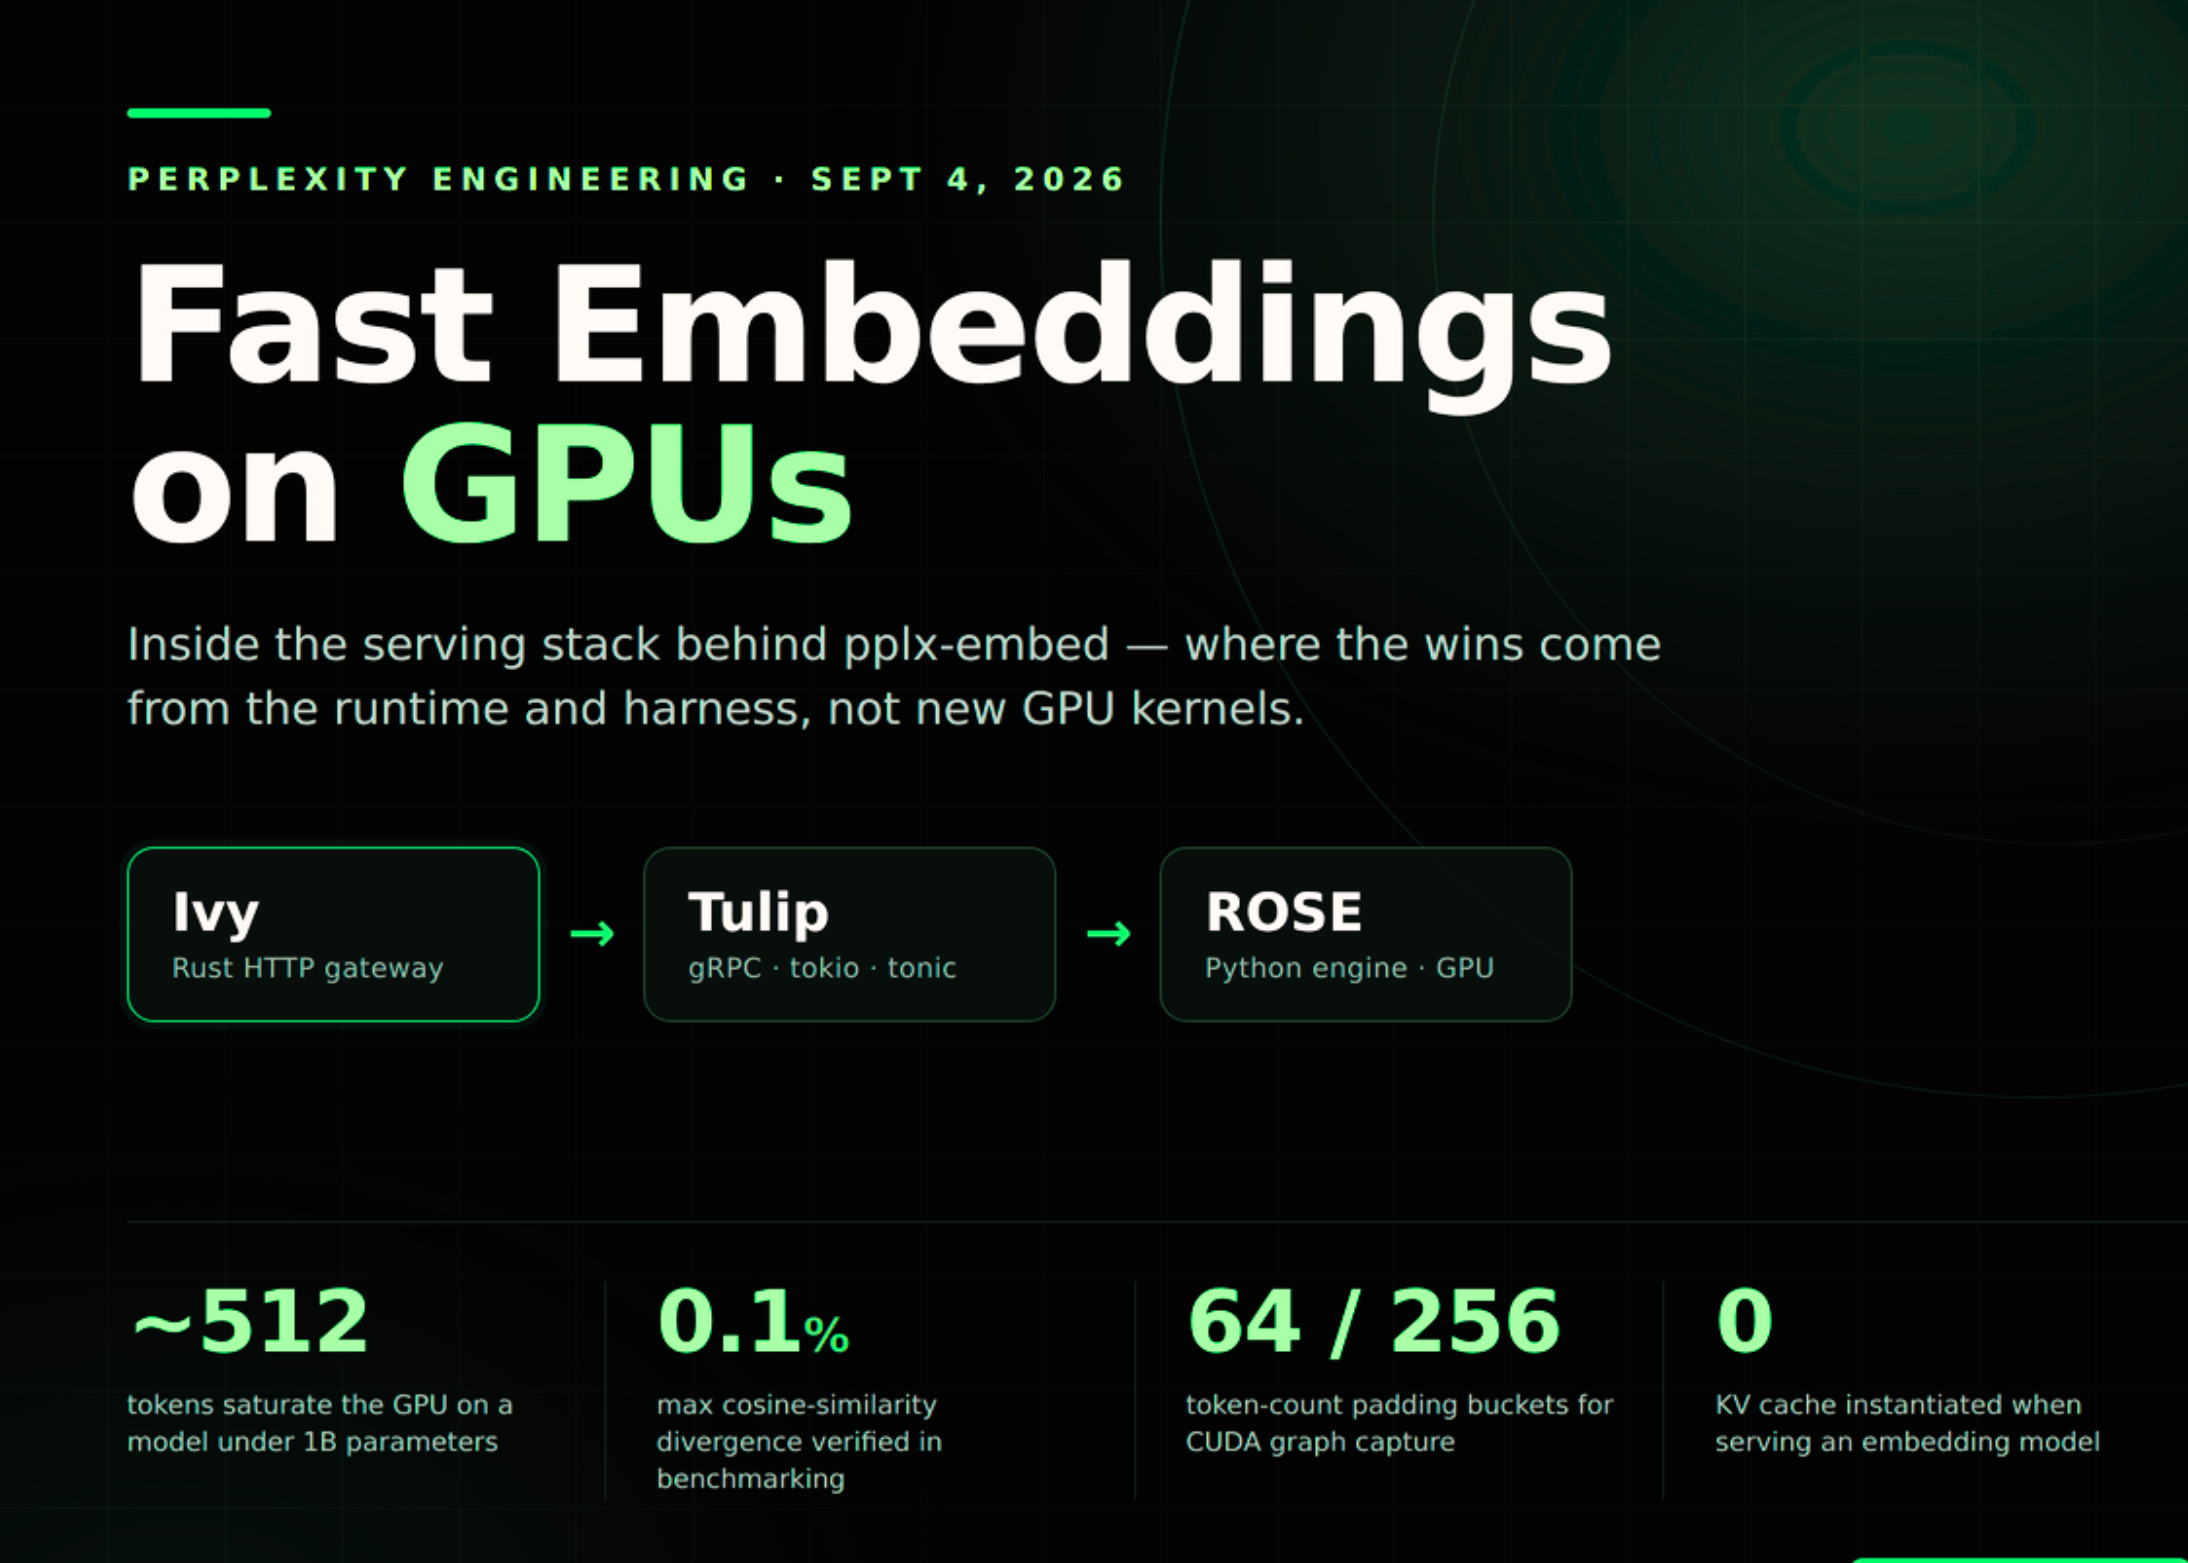
Retrieval quality in an AI search product is bounded by two things: how good the embedding model is, and how cheaply you can run it across an index. This week, Perplexity Engineering team published Fast Embeddings on GPUs, an under-the-hood account of the second — the serving infrastructure behind pplx-embed and the ranking models used across Perplexity Search, Computer and the API Platform.

Perplexity team states that embedding inference on the GPU side has largely converged across engines on mature Hopper and Blackwell hardware. The wins sit in the runtime and harness around the model: CUDA graph management, an async result-tracking abstraction, and a Rust request path.

YOU MAY ALSO LIKE

Tesla Unveils Flying Roadster and Glimpse Into Its Future

Netflix Earnings Beat Expectations, but Growth Expectations Come Up Short

Two traffic patterns, one engine

Perplexity frames embedding serving as two workloads. Batch embedding happens when building or re-indexing the vector database, where throughput minimizes cost. Online embedding happens at query time, where a short query must be embedded fast. Scoring sits in between: after vector search, large document batches are ranked, balancing both.

The key decision is that Perplexity did not build a separate embedding engine. Because embedding models are small Transformers, batch embedding resembles compute-bound prefill and online embedding, often a few tokens, resembles memory-bound decode. So the research team reuses the prefill and decode kernels from its LLM stack.

Ivy, Tulip and ROSE

Three services handle a request:

  • Ivy is a Rust HTTP gateway. It does the CPU-side work — JSON parsing, tokenization, input templating, batch splitting — and translates requests into a custom gRPC protocol. It also splits large-batch requests into chunks and load-balances them across replicas, which corrects the load imbalance that arises when production payloads vary in size.
  • Tulip is the inference server interface: a gRPC server built with Rust, tokio and tonic, handling scheduling and batching before dispatching to the engine.
  • ROSE (Runtime-Optimized Serving Engine) implements model inference. It is primarily Python, provides kernels, layers and model definitions, manages CUDA graphs, and exposes a step() function to Tulip.

Why the scheduler is deliberately simple

Tulip picks sequences first-come, first-served while requests accumulate. That simplicity is justified by a measurement: for small embedding models at the sequence lengths Perplexity serves, the linear cost of dense layers dominates the quadratic cost of attention. Latency is therefore roughly proportional to token count, not sequence count. Once a batch saturates the GPU, around 512 tokens on a sub-billion-parameter model, packing in more sequences does not improve efficiency.

CUDA graphs and LazyTensors

On small batches, CPU-side kernel launching can outweigh GPU execution. Perplexity builds whole-model CUDA graphs for all embedding models, capturing every launch into a single driver call. Because embedding models are small, the inflection point where GPU work exceeds launch cost arrives at batches of thousands of tokens and tens of sequences. Some attention implementations block full-model graphs by depending on dynamic host-side inputs; Perplexity upstreamed changes to FlashInfer to enable capture.

Graphs must be captured per configuration, so token counts are padded to buckets that are multiples of 64 or 256. That still yields thousands of graphs and multiple minutes of capture per model. The fix is lazy capture: each configuration gets an eager warmup run, then triggers capture and replay on its second hit. This costs p99 latency at startup but spreads minutes of eager work across hours.

The second piece is the LazyTensor, which tracks a page-locked host buffer plus a cudaMemcpyAsync and a CUDA event. Instead of step() blocking on the device, it returns a LazyTensor, letting a Rust async task wait on batch N while the CPU enqueues N+1.

Credit: Source link
ShareTweetSendSharePin

Related Posts

Tesla Unveils Flying Roadster and Glimpse Into Its Future
AI & Technology

Tesla Unveils Flying Roadster and Glimpse Into Its Future

October 25, 2026
Netflix Earnings Beat Expectations, but Growth Expectations Come Up Short
AI & Technology

Netflix Earnings Beat Expectations, but Growth Expectations Come Up Short

October 25, 2026
Musk Teases SpaceX-Tesla Merger in Earnings Call
AI & Technology

Musk Teases SpaceX-Tesla Merger in Earnings Call

October 25, 2026
Hugging Face Releases Carbon-X, a 14B Open DNA Language Model that Brings DNA and Natural Language Together for the First Time
AI & Technology

Hugging Face Releases Carbon-X, a 14B Open DNA Language Model that Brings DNA and Natural Language Together for the First Time

October 25, 2026
Next Post
Lululemon billionaire founder Chip Wilson files for divorce after 20 years of marriage — with no prenup in place

Lululemon billionaire founder Chip Wilson files for divorce after 20 years of marriage — with no prenup in place

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Musk Teases SpaceX-Tesla Merger in Earnings Call

Musk Teases SpaceX-Tesla Merger in Earnings Call

October 25, 2026
Trump and Melania sign women’s health executive order

Trump and Melania sign women’s health executive order

October 22, 2026
Tesla unveils its next generation ‘flying’ Roadster

Tesla unveils its next generation ‘flying’ Roadster

October 24, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!