
Microsoft has announced the release of Harrier-OSS-v1, a family of three multilingual text embedding models designed to provide high-quality semantic representations across a wide range of languages. The release includes three distinct scales: a 270M parameter model, a 0.6B model, and a 27B model.
The Harrier-OSS-v1 models achieved state-of-the-art (SOTA) results on the Multilingual MTEB (Massive Text Embedding Benchmark) v2. For AI professionals, this release marks a significant milestone in open-source retrieval technology, offering a scalable range of models that leverage modern LLM architectures for embedding tasks.
Architecture and Foundation
The Harrier-OSS-v1 family moves away from the traditional bidirectional encoder architectures (such as BERT) that have dominated the embedding landscape for years. Instead, these models utilize decoder-only architectures, similar to those found in modern Large Language Models (LLMs).
The use of decoder-only foundations represents a shift in how context is processed. In a causal (decoder-only) model, each token can only attend to the tokens that come before it. To derive a single vector representing the entire input, Harrier utilizes last-token pooling. This means the hidden state of the very last token in the sequence is used as the aggregate representation of the text, which is then subjected to L2 normalization to ensure the vector has a consistent magnitude.
Technical Specifications
The Harrier-OSS-v1 models are characterized by their varying embedding dimensions and their consistent support for long-context inputs. The following table provides a breakdown of the technical specifications:
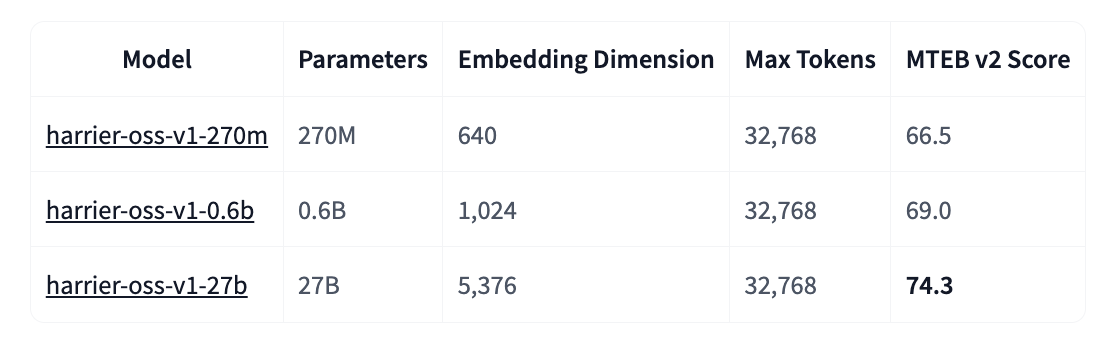
The 32,768 (32k) token context window across all three sizes is a significant feature for Retrieval-Augmented Generation (RAG) systems. Most traditional embedding models are limited to 512 or 1,024 tokens. The expanded window allows AI devs to embed significantly larger documents or code files without the need for aggressive chunking, which often results in a loss of semantic coherence.
Implementation: Instruction-Based Embeddings
One of the most important operational details for AI devs is that Harrier-OSS-v1 is an instruction-tuned embedding family. To achieve the benchmarked performance, the model requires task-specific instructions to be provided at the time of the query.
The implementation follows a specific logic:
- Query-side: All queries should be prepended with a one-sentence task instruction that defines the intent (e.g., retrieving semantically similar text or finding a translation).
- Document-side: Documents should be encoded without instructions.
An example query format would look like this:
"Instruct: Retrieve semantically similar text\nQuery: [User input text]"This instruction-based approach allows the model to adjust its vector space dynamically based on the task, improving retrieval accuracy across different domains such as web search or bitext mining.
Training and Knowledge Distillation
The development of the Harrier-OSS-v1 family involved a multi-stage training process. While the 27B model provides the highest parameter count and dimensionality (5,376), Microsoft team utilized specialized techniques to boost the performance of the smaller variants.
The 270M and 0.6B models were additionally trained using knowledge distillation from larger embedding models. Knowledge distillation is a technique where a ‘student’ model is trained to replicate the output distributions or feature representations of a high-performance ‘teacher’ model. This process allows the smaller Harrier models to achieve higher embedding quality than would typically be expected from their parameter counts, making them more efficient for deployments where memory or latency is a factor.
Performance on Multilingual MTEB v2
The Multilingual MTEB v2 is a comprehensive benchmark that evaluates models across diverse tasks, including:
- Classification: Identifying the category of a text.
- Clustering: Grouping similar documents.
- Pair Classification: Determining if two sentences are paraphrases.
- Retrieval: Finding the most relevant document for a given query.
By achieving SOTA results on this benchmark at release, the Harrier family demonstrates a high level of proficiency in cross-lingual retrieval. This is particularly valuable for global applications where a system may need to process queries and documents in different languages within the same vector space.
Key Takeaways
- Scalable Multilingual SOTA: The family includes three models (270M, 0.6B, and 27B) that achieved State-of-the-Art results on the Multilingual MTEB v2 benchmark as of their release date.
- Decoder-Only Foundation: Moving away from BERT-style encoders, these models use decoder-only architectures with last-token pooling and L2 normalization.
- Expanded 32k Context: All models support a 32,768-token context window, allowing for the representation of long-form documents or codebases without the semantic loss associated with aggressive chunking.
- Instruction-Dependent Retrieval: Best performance requires query-side instructions (a one-sentence task description prepended to the input), while documents should be encoded without any instructions.
- Quality via Distillation: The smaller 270M (640-dim) and 0.6B (1,024-dim) models were trained using knowledge distillation from larger embedding models to improve their semantic representation quality relative to their parameter counts.
Check out the Model Weights here. Also, feel free to follow us on Twitter and don’t forget to join our 120k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Credit: Source link