
• bitcoinBitcoin(BTC)$76,491.000.93%
  • ethereumEthereum(ETH)$2,447.421.95%
  • tetherTether(USDT)$1.000.01%
  • binancecoinBNB(BNB)$729.231.67%
  • rippleXRP(XRP)$1.290.09%
  • usd-coinUSDC(USDC)$1.000.00%
  • solanaSolana(SOL)$100.803.12%
  • tronTRON(TRX)$0.334047-0.40%
  • zcashZcash(ZEC)$1,485.3215.40%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.021.94%
  • HyperliquidHyperliquid(HYPE)$82.695.70%
  • dogecoinDogecoin(DOGE)$0.0815281.82%
  • moneroMonero(XMR)$510.812.91%
  • USDSUSDS(USDS)$1.000.05%
  • whitebitWhiteBIT Coin(WBT)$78.841.37%
  • RainRain(RAIN)$0.0129272.08%
  • chainlinkChainlink(LINK)$11.303.87%
  • leo-tokenLEO Token(LEO)$8.920.74%
  • cardanoCardano(ADA)$0.2013434.46%
  • stellarStellar(XLM)$0.1852432.82%
  • Ethena USDeEthena USDe(USDE)$1.000.05%
  • uniswapUniswap(UNI)$7.6220.66%
  • bitcoin-cashBitcoin Cash(BCH)$231.926.44%
  • daiDai(DAI)$1.00-0.02%
  • USD1USD1(USD1)$1.000.01%
  • litecoinLitecoin(LTC)$53.756.04%
  • nearNEAR Protocol(NEAR)$3.0119.09%
  • CantonCanton(CC)$0.0989986.01%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.343.52%
  • avalanche-2Avalanche(AVAX)$7.583.81%
  • hedera-hashgraphHedera(HBAR)$0.0750692.78%
  • Global DollarGlobal Dollar(USDG)$1.00-0.01%
  • shiba-inuShiba Inu(SHIB)$0.0000056.34%
  • suiSui(SUI)$0.734.41%
  • crypto-com-chainCronos(CRO)$0.0575112.93%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.01%
  • MemeCoreMemeCore(M)$1.206.48%
  • tether-goldTether Gold(XAUT)$4,340.551.68%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • BittensorBittensor(TAO)$230.355.93%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • Ripple USDRipple USD(RLUSD)$1.000.01%
  • okbOKB(OKB)$112.221.69%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.15-0.06%
  • AsterAster(ASTER)$0.747.79%
  • aaveAave(AAVE)$127.5610.18%
  • BitwayBitway(BTW)$0.71-4.31%
  • pax-goldPAX Gold(PAXG)$4,340.121.66%
  • mantleMantle(MNT)$0.574.37%
  • World Liberty FinancialWorld Liberty Financial(WLFI)$0.0578181.43%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Liquid AI’s New LFM2-24B-A2B Hybrid Architecture Blends Attention with Convolutions to Solve the Scaling Bottlenecks of Modern LLMs

February 25, 2026
in AI & Technology
Reading Time: 6 mins read
A A
Liquid AI’s New LFM2-24B-A2B Hybrid Architecture Blends Attention with Convolutions to Solve the Scaling Bottlenecks of Modern LLMs
ShareShareShareShareShare

The generative AI race has long been a game of ‘bigger is better.’ But as the industry hits the limits of power consumption and memory bottlenecks, the conversation is shifting from raw parameter counts to architectural efficiency. Liquid AI team is leading this charge with the release of LFM2-24B-A2B, a 24-billion parameter model that redefines what we should expect from edge-capable AI.

https://www.liquid.ai/blog/lfm2-24b-a2b

The ‘A2B’ Architecture: A 1:3 Ratio for Efficiency

The ‘A2B’ in the model’s name stands for Attention-to-Base. In a traditional Transformer, every layer uses Softmax Attention, which scales quadratically (O(N2)) with sequence length. This leads to massive KV (Key-Value) caches that devour VRAM.

YOU MAY ALSO LIKE

Anthropic Launches Life Sciences Verification Program in Beta – Unite.AI

Lofi Girl Returns With A New House Music Station And Vinyl Compilation

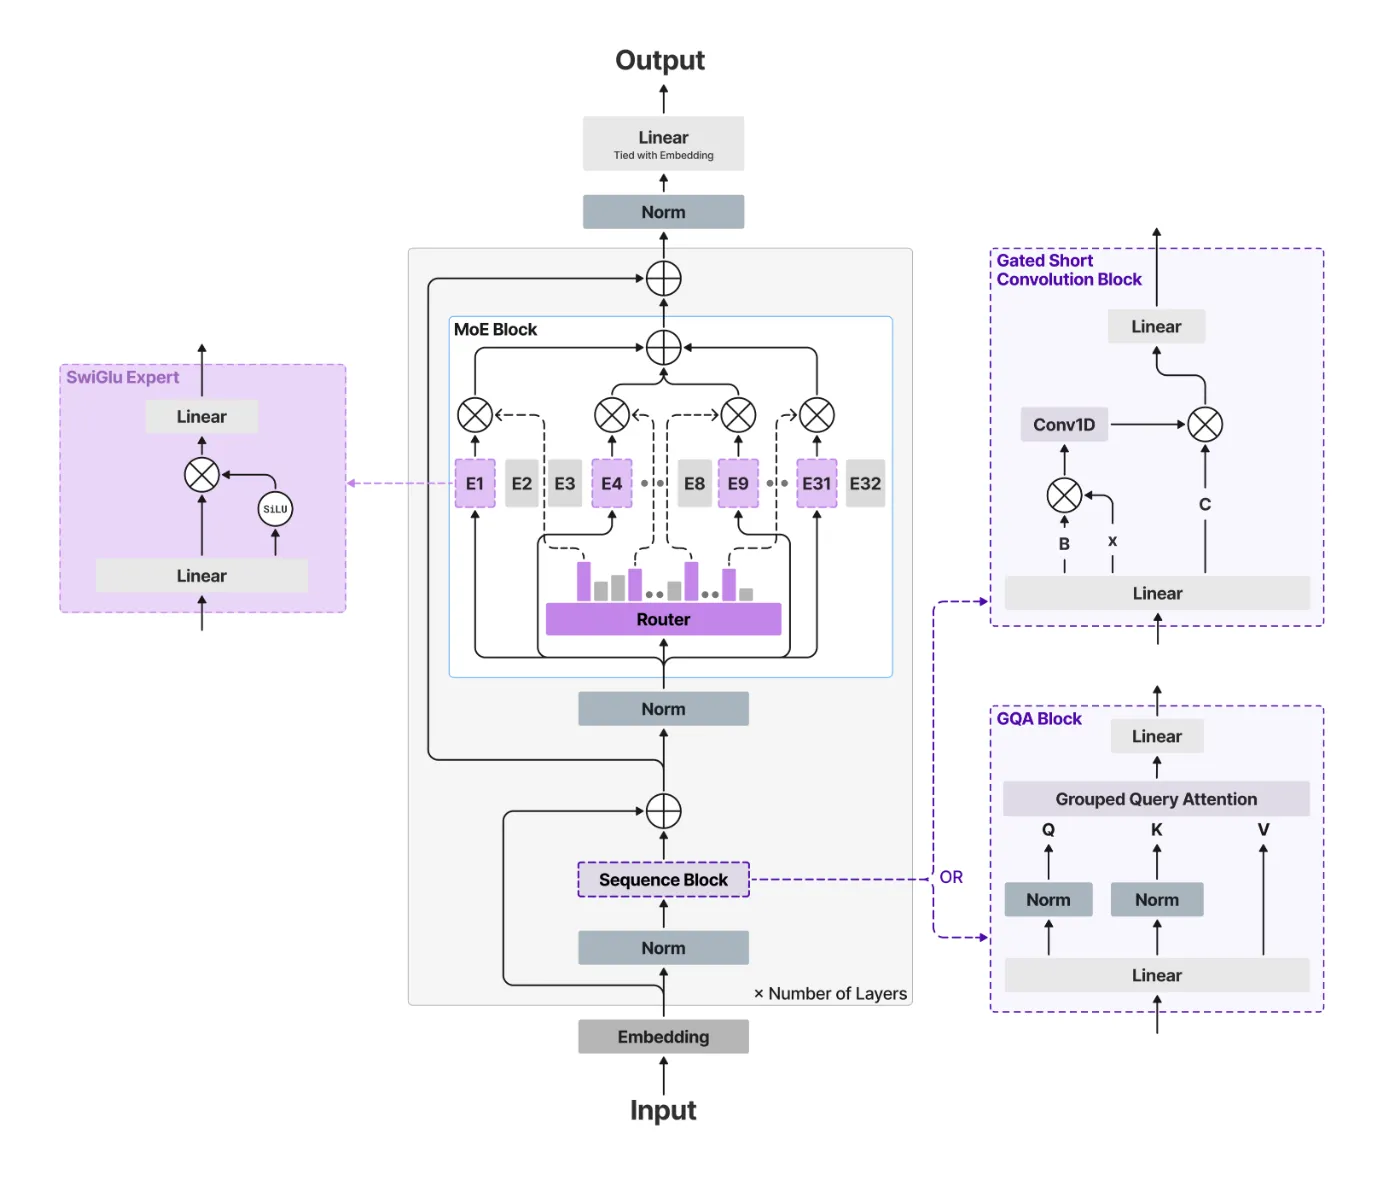
Liquid AI team bypasses this by using a hybrid structure. The ‘Base‘ layers are efficient gated short convolution blocks, while the ‘Attention‘ layers utilize Grouped Query Attention (GQA).

In the LFM2-24B-A2B configuration, the model uses a 1:3 ratio:

  • Total Layers: 40
  • Convolution Blocks: 30
  • Attention Blocks: 10

By interspersing a small number of GQA blocks with a majority of gated convolution layers, the model retains the high-resolution retrieval and reasoning of a Transformer while maintaining the fast prefill and low memory footprint of a linear-complexity model.

Sparse MoE: 24B Intelligence on a 2B Budget

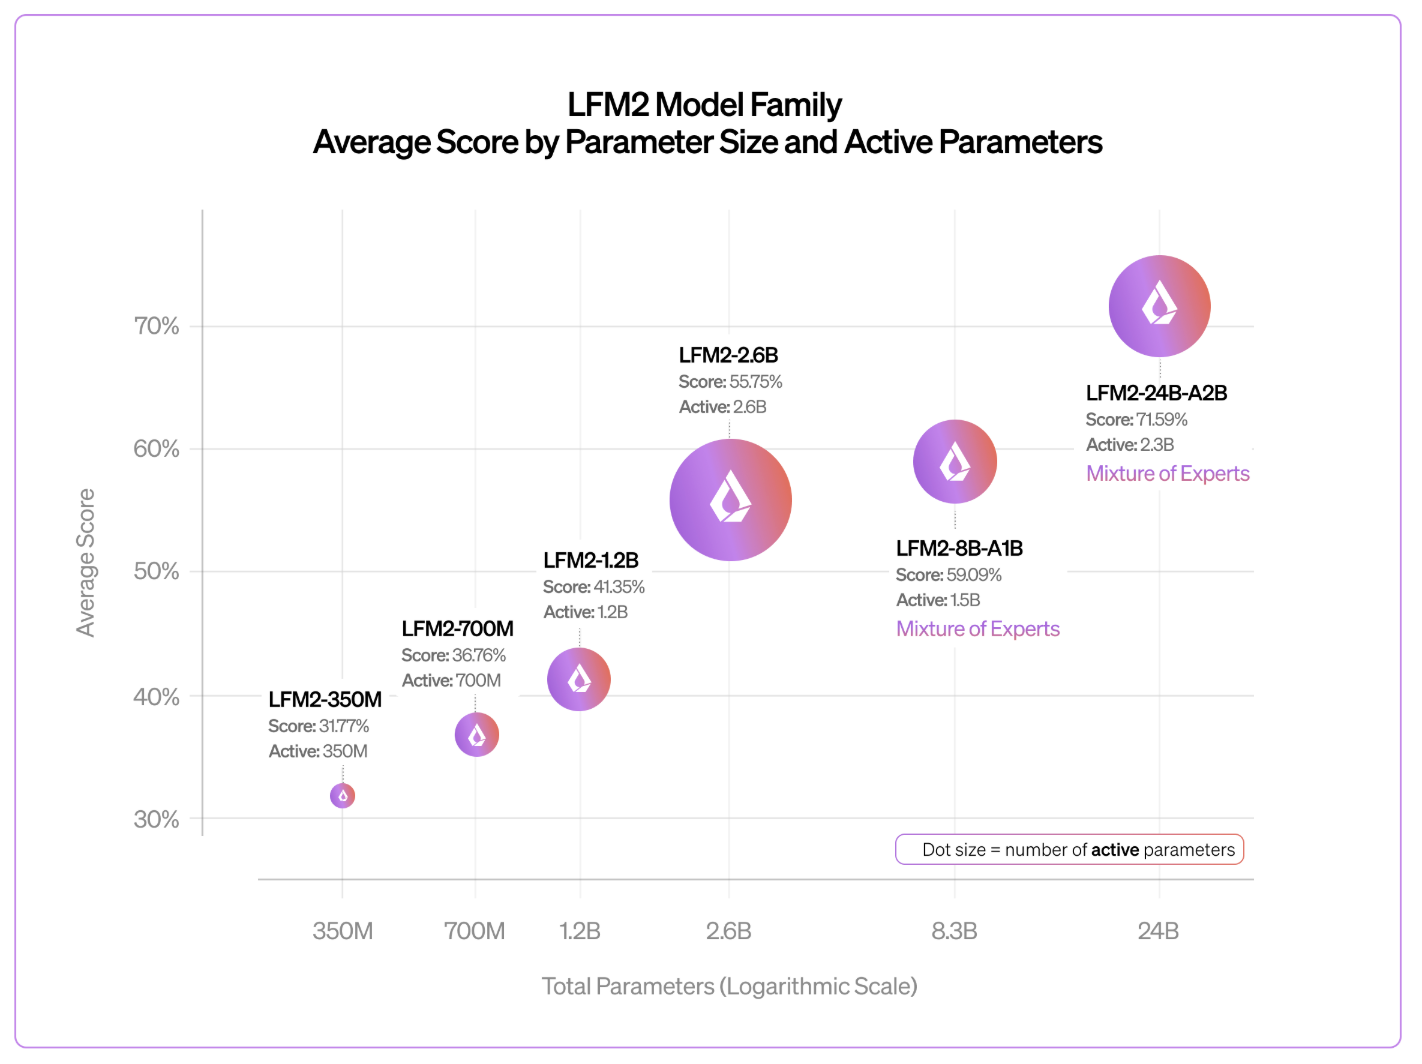
The most important thing of LFM2-24B-A2B is its Mixture of Experts (MoE) design. While the model contains 24 billion parameters, it only activates 2.3 billion parameters per token.

This is a game-changer for deployment. Because the active parameter path is so lean, the model can fit into 32GB of RAM. This means it can run locally on high-end consumer laptops, desktops with integrated GPUs (iGPUs), and dedicated NPUs without needing a data-center-grade A100. It effectively provides the knowledge density of a 24B model with the inference speed and energy efficiency of a 2B model.
https://www.liquid.ai/blog/lfm2-24b-a2b

Benchmarks: Punching Up

Liquid AI team reports that the LFM2 family follows a predictable, log-linear scaling behavior. Despite its smaller active parameter count, the 24B-A2B model consistently outperforms larger rivals.

  • Logic and Reasoning: In tests like GSM8K and MATH-500, it rivals dense models twice its size.
  • Throughput: When benchmarked on a single NVIDIA H100 using vLLM, it reached 26.8K total tokens per second at 1,024 concurrent requests, significantly outpacing Snowflake’s gpt-oss-20b and Qwen3-30B-A3B.
  • Long Context: The model features a 32k token context window, optimized for privacy-sensitive RAG (Retrieval-Augmented Generation) pipelines and local document analysis.

Technical Cheat Sheet

Property Specification
Total Parameters 24 Billion
Active Parameters 2.3 Billion
Architecture Hybrid (Gated Conv + GQA)
Layers 40 (30 Base / 10 Attention)
Context Length 32,768 Tokens
Training Data 17 Trillion Tokens
License LFM Open License v1.0
Native Support llama.cpp, vLLM, SGLang, MLX

Key Takeaways

  • Hybrid ‘A2B’ Architecture: The model uses a 1:3 ratio of Grouped Query Attention (GQA) to Gated Short Convolutions. By utilizing linear-complexity ‘Base’ layers for 30 out of 40 layers, the model achieves much faster prefill and decode speeds with a significantly reduced memory footprint compared to traditional all-attention Transformers.
  • Sparse MoE Efficiency: Despite having 24 billion total parameters, the model only activates 2.3 billion parameters per token. This ‘Sparse Mixture of Experts’ design allows it to deliver the reasoning depth of a large model while maintaining the inference latency and energy efficiency of a 2B-parameter model.
  • True Edge Capability: Optimized via hardware-in-the-loop architecture search, the model is designed to fit in 32GB of RAM. This makes it fully deployable on consumer-grade hardware, including laptops with integrated GPUs and NPUs, without requiring expensive data-center infrastructure.
  • State-of-the-Art Performance: LFM2-24B-A2B outperforms larger competitors like Qwen3-30B-A3B and Snowflake gpt-oss-20b in throughput. Benchmarks show it hits approximately 26.8K tokens per second on a single H100, showing near-linear scaling and high efficiency in long-context tasks up to its 32k token window.

Check out the Technical details and Model weights. Also, feel free to follow us on Twitter and don’t forget to join our 120k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.

The post Liquid AI’s New LFM2-24B-A2B Hybrid Architecture Blends Attention with Convolutions to Solve the Scaling Bottlenecks of Modern LLMs appeared first on MarkTechPost.

Credit: Source link

ShareTweetSendSharePin

Related Posts

Anthropic Launches Life Sciences Verification Program in Beta – Unite.AI
AI & Technology

Anthropic Launches Life Sciences Verification Program in Beta – Unite.AI

September 17, 2026
Lofi Girl Returns With A New House Music Station And Vinyl Compilation
AI & Technology

Lofi Girl Returns With A New House Music Station And Vinyl Compilation

September 17, 2026
Razer Refreshes The One-Handed Tartarus Pro Keyboard With Improved Switches
AI & Technology

Razer Refreshes The One-Handed Tartarus Pro Keyboard With Improved Switches

September 17, 2026
OceanStor M900 Brings PB-Scale Context Memory to Huawei SuperPoDs – Unite.AI
AI & Technology

OceanStor M900 Brings PB-Scale Context Memory to Huawei SuperPoDs – Unite.AI

September 17, 2026
Next Post
Looking back at the career of “Dawson’s Creek” actor James Van Der Beek

Looking back at the career of "Dawson's Creek" actor James Van Der Beek

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Gaming giant Blizzard sued for sexual harassment

Gaming giant Blizzard sued for sexual harassment

September 11, 2026
Newly declassified briefings show clear warnings to presidents before 9/11

Newly declassified briefings show clear warnings to presidents before 9/11

September 13, 2026
Nums AI Releases Causilo: A Tabular Foundation Model That Tops TabArena Among Single Models

Nums AI Releases Causilo: A Tabular Foundation Model That Tops TabArena Among Single Models

September 16, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!