What comes after Transformers? Google Research is proposing a new way to give sequence models usable long term memory with Titans and MIRAS, while keeping training parallel and inference close to linear.
Titans is a concrete architecture that adds a deep neural memory to a Transformer style backbone. MIRAS is a general framework that views most modern sequence models as instances of online optimization over an associative memory.
Why Titans and MIRAS?
Standard Transformers use attention over a key value cache. This gives strong in context learning, but cost grows quadratically with context length, so practical context is limited even with FlashAttention and other kernel tricks.
Efficient linear recurrent neural networks and state space models such as Mamba-2 compress the history into a fixed size state, so cost is linear in sequence length. However, this compression loses information in very long sequences, which hurts tasks such as genomic modeling and extreme long context retrieval.
Titans and MIRAS combine these ideas. Attention acts as a precise short term memory on the current window. A separate neural module provides long term memory, learns at test time, and is trained so that its dynamics are parallelizable on accelerators.
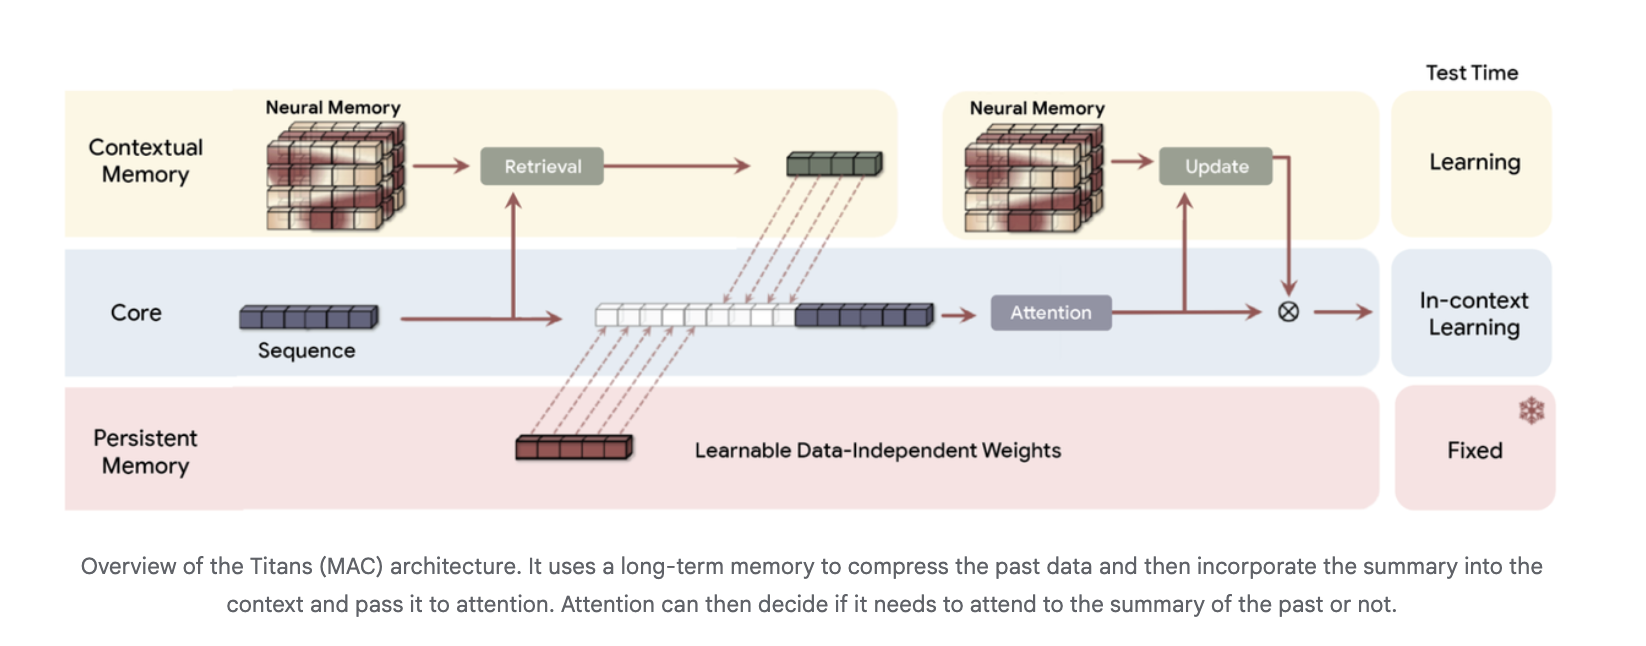
Titans, a neural long term memory that learns at test time
The Titans research paper introduces a neural long term memory module that is itself a deep multi layer perceptron rather than a vector or matrix state. Attention is interpreted as short term memory, since it only sees a limited window, while the neural memory acts as persistent long term memory.
For each token, Titans defines an associative memory loss
ℓ(Mₜ₋₁; kₜ, vₜ) = ‖Mₜ₋₁(kₜ) − vₜ‖²
where Mₜ₋₁ is the current memory, kₜ is the key and vₜ is the value. The gradient of this loss with respect to the memory parameters is the “surprise metric”. Large gradients correspond to surprising tokens that should be stored, small gradients correspond to expected tokens that can be mostly ignored.
The memory parameters are updated at test time by gradient descent with momentum and weight decay, which together act as a retention gate and forgetting mechanism.To keep this online optimization efficient, the research paper shows how to compute these updates with batched matrix multiplications over sequence chunks, which preserves parallel training across long sequences.
Architecturally, Titans uses three memory branches in the backbone, often instanced in the Titans MAC variant:
- a core branch that performs standard in context learning with attention
- a contextual memory branch that learns from the recent sequence
- a persistent memory branch with fixed weights that encodes pretraining knowledge
The long term memory compresses past tokens into a summary, which is then passed as extra context into attention. Attention can choose when to read that summary.
Experimental results for Titans
On language modeling and commonsense reasoning benchmarks such as C4, WikiText and HellaSwag, Titans architectures outperform state of the art linear recurrent baselines Mamba-2 and Gated DeltaNet and Transformer++ models of comparable size. The Google research attribute this to the higher expressive power of deep memory and its ability to maintain performance as context length grows. Deep neural memories with the same parameter budget but higher depth give consistently lower perplexity.
For extreme long context recall, the research team uses the BABILong benchmark, where facts are distributed across very long documents. Titans outperforms all baselines, including very large models such as GPT-4, while using many fewer parameters, and scales to context windows beyond 2,000,000 tokens.
The research team reports that Titans keeps efficient parallel training and fast linear inference. Neural memory alone is slightly slower than the fastest linear recurrent models, but hybrid Titans layers with Sliding Window Attention remain competitive on throughput while improving accuracy.
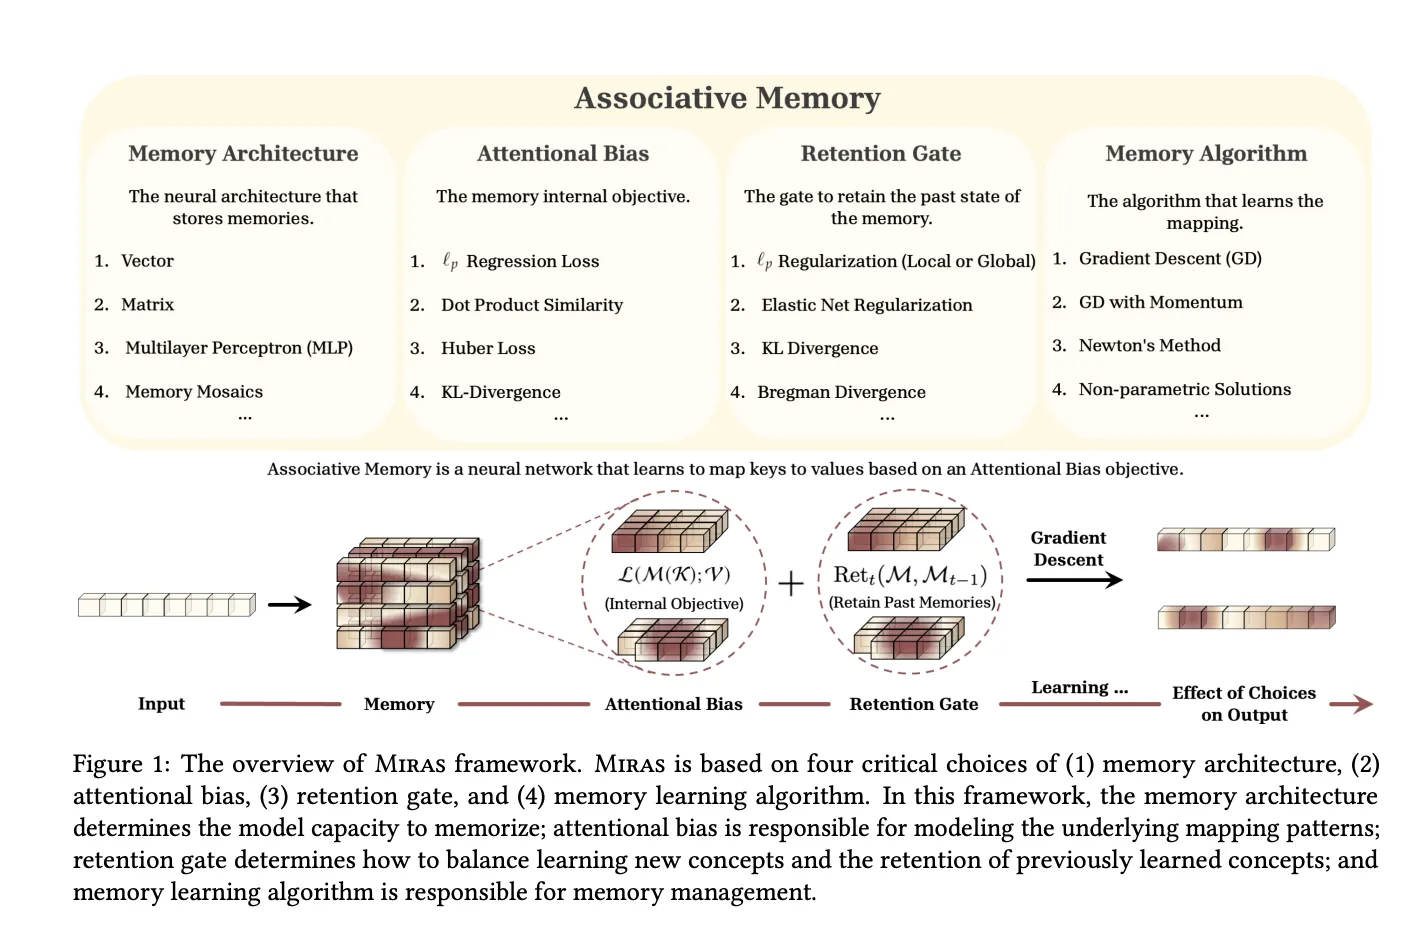
MIRAS, a unified framework for sequence models as associative memory
The MIRAS research paper, “It’s All Connected: A Journey Through Test Time Memorization, Attentional Bias, Retention, and Online Optimization,” generalizes this view. It observes that modern sequence models can be seen as associative memories that map keys to values while balancing learning and forgetting.
MIRAS defines any sequence model through four design choices:
- Memory structure for example a vector, linear map, or MLP
- Attentional bias the internal loss that defines what similarities the memory cares about
- Retention gate the regularizer that keeps the memory close to its past state
- Memory algorithm the online optimization rule, often gradient descent with momentum
Using this lens, MIRAS recovers several families:
- Hebbian style linear recurrent models and RetNet as dot product based associative memories
- Delta rule models such as DeltaNet and Gated DeltaNet as MSE based memories with value replacement and specific retention gates
- Titans LMM as a nonlinear MSE based memory with local and global retention optimized by gradient descent with momentum
Crucially, MIRAS then moves beyond the usual MSE or dot product objectives. The research team constructs new attentional biases based on Lₚ norms, robust Huber loss and robust optimization, and new retention gates based on divergences over probability simplices, elastic net regularization and Bregman divergence.
From this design space, the research team instantiate three attention free models:
- Moneta uses a 2 layer MLP memory with Lₚ attentional bias and a hybrid retention gate based on generalized norms
- Yaad uses the same MLP memory with Huber loss attentional bias and a forget gate related to Titans
- Memora uses regression loss as attentional bias and a KL divergence based retention gate over a probability simplex style memory.
These MIRAS variants replace attention blocks in a Llama style backbone, use depthwise separable convolutions in the Miras layer, and can be combined with Sliding Window Attention in hybrid models. Training remains parallel by chunking sequences and computing gradients with respect to the memory state from the previous chunk.
In research experiments, Moneta, Yaad and Memora match or surpass strong linear recurrent models and Transformer++ on language modeling, commonsense reasoning and recall intensive tasks, while maintaining linear time inference.
Key Takeaways
- Titans introduces a deep neural long term memory that learns at test time, using gradient descent on an L2 associative memory loss so the model selectively stores only surprising tokens while keeping updates parallelizable on accelerators.
- Titans combines attention with neural memory for long context, using branches like core, contextual memory and persistent memory so attention handles short range precision and the neural module maintains information over sequences beyond 2,000,000 tokens.
- Titans outperforms strong linear RNNs and Transformer++ baselines, including Mamba-2 and Gated DeltaNet, on language modeling and commonsense reasoning benchmarks at comparable parameter scales, while staying competitive on throughput.
- On extreme long context recall benchmarks such as BABILong, Titans achieves higher accuracy than all baselines, including larger attention models such as GPT 4, while using fewer parameters and still enabling efficient training and inference.
- MIRAS provides a unifying framework for sequence models as associative memories, defining them by memory structure, attentional bias, retention gate and optimization rule, and yields new attention free architectures such as Moneta, Yaad and Memora that match or surpass linear RNNs and Transformer++ on long context and reasoning tasks.
Check out the Technical details. Feel free to check out our GitHub Page for Tutorials, Codes and Notebooks. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.

Michal Sutter is a data science professional with a Master of Science in Data Science from the University of Padova. With a solid foundation in statistical analysis, machine learning, and data engineering, Michal excels at transforming complex datasets into actionable insights.
Credit: Source link