
How can teams run trillion parameter language models on existing mixed GPU clusters without costly new hardware or deep vendor lock in? Perplexity’s research team has released TransferEngine and the surrounding pplx garden toolkit as open source infrastructure for large language model systems. This provides a way to run models with up to 1 trillion parameters across mixed GPU clusters, without locking into a single cloud provider or buying new GB200 class hardware.
The real bottleneck, network fabrics not FLOPs
Modern deployments of Mixture of Experts models such as DeepSeek V3 with 671 billion parameters and Kimi K2 with 1 trillion parameters no longer fit on a single 8 GPU server. They must span multiple nodes, so the main constraint becomes the network fabric between GPUs.
Here the hardware landscape is fragmented. NVIDIA ConnectX 7 typically uses Reliable Connection transport with in order delivery. AWS Elastic Fabric Adapter uses Scalable Reliable Datagram transport that is reliable but out of order, and a single GPU may need 4 network adapters at 100 Gbps, or 2 at 200 Gbps, to reach 400 Gbps.
Existing libraries such as DeepEP, NVSHMEM, MoonCake and NIXL tend to optimize for one vendor and degrade or lack support on the other side. Perplexity’s research team directly states in the research paper that there was no viable cross provider solution for LLM inference before this work.
TransferEngine, a portable RDMA layer for LLM systems
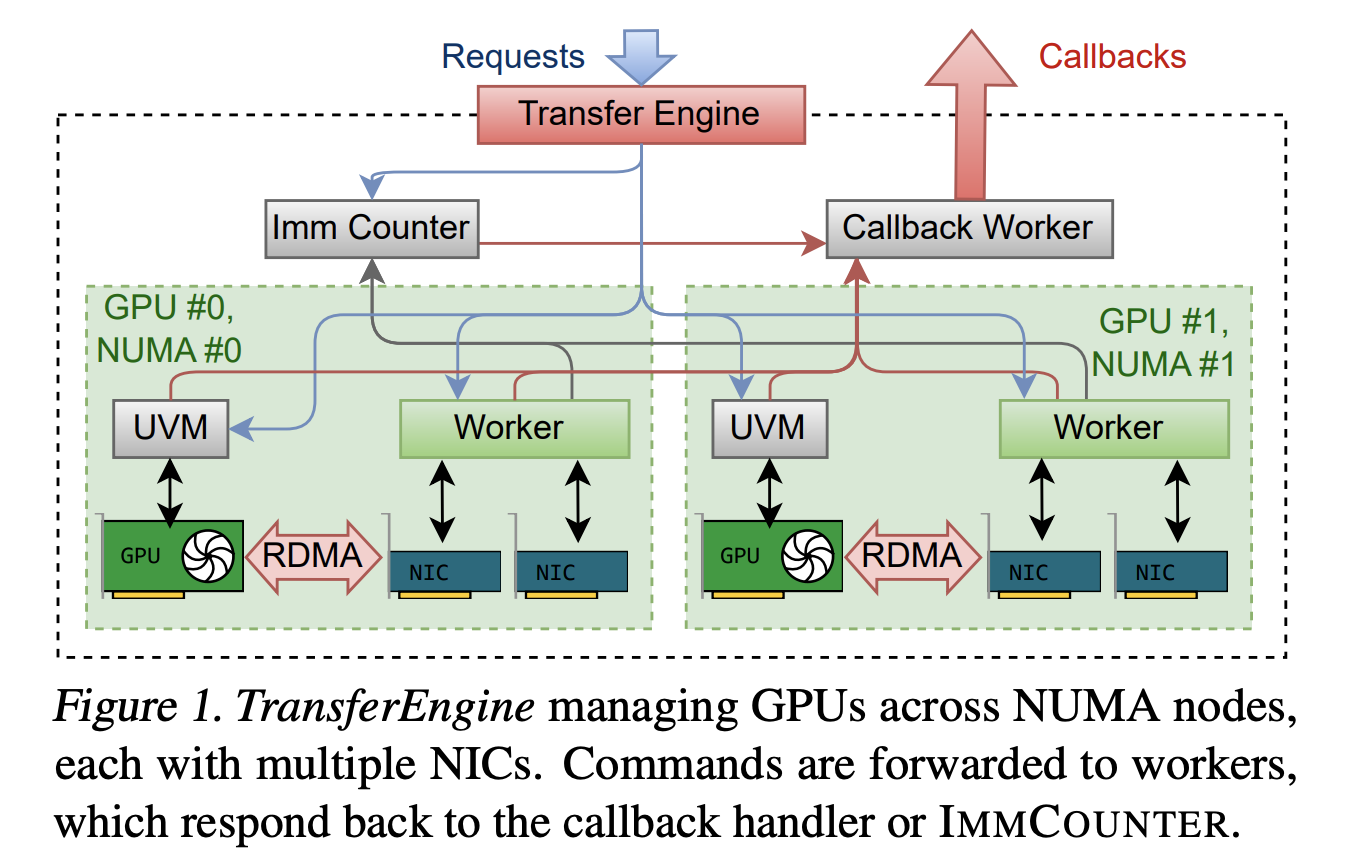
TransferEngine addresses this by targeting only the intersection of guarantees across Network Interface Controllers. It assumes that the underlying RDMA transport is reliable, but does not assume any ordering of messages. On top of this, it exposes one sided WriteImm operations and an ImmCounter primitive for completion notification.
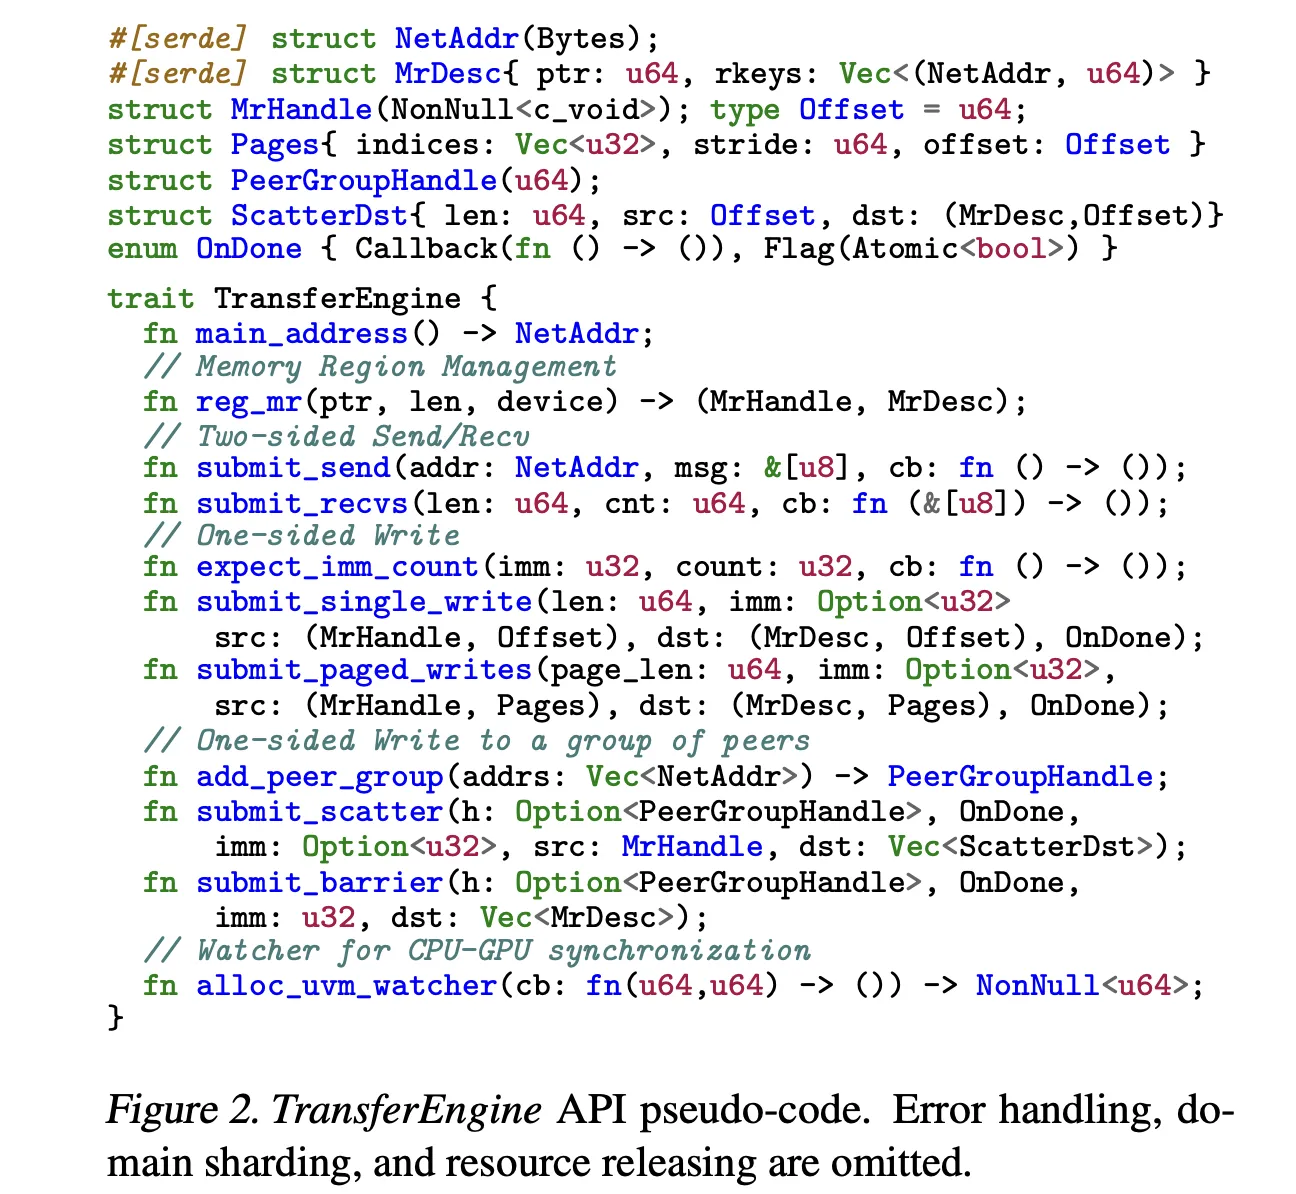
The library provides a minimal API in Rust. It offers two sided Send and Recv for control messages, and three main one sided operations, submit_single_write, submit_paged_writes, and submit_scatter, plus a submit_barrier primitive for synchronization across a group of peers. A NetAddr structure identifies peers and an MrDesc structure describes registered memory regions. An alloc_uvm_watcher call creates a device side watcher for CPU GPU synchronization in advanced pipelines.
Internally, TransferEngine spawns one worker thread per GPU and builds a DomainGroup per GPU that coordinates between 1 and 4 RDMA Network Interface Controllers. A single ConnectX 7 provides 400 Gbps. On EFA, the DomainGroup aggregates 4 network adapters at 100 Gbps, or 2 at 200 Gbps, to reach the same bandwidth. The sharding logic knows about all Network Interface Controllers and can split a transfer across them.
Across hardware, the research team reports peak throughput of 400 Gbps on both NVIDIA ConnectX 7 and AWS EFA. This matches single platform solutions and confirms that the abstraction layer does not leave large performance on the table.
pplx garden, the open source package
TransferEngine ships as part of the pplx garden repository on GitHub under an MIT license. The directory structure is straightforward. fabric-lib contains the RDMA TransferEngine library, p2p-all-to-all implements a Mixture of Experts all to all kernel, python-ext provides the Python extension module from the Rust core, and python/pplx_garden contains the Python package code.
The system requirements reflect a modern GPU cluster. Perplexity research team recommends Linux kernel 5.12 or newer for DMA BUF support, CUDA 12.8 or newer, libfabric, libibverbs, GDRCopy, and an RDMA fabric with GPUDirect RDMA enabled. Each GPU should have at least one dedicated RDMA Network Interface Controller.
Disaggregated prefill and decode
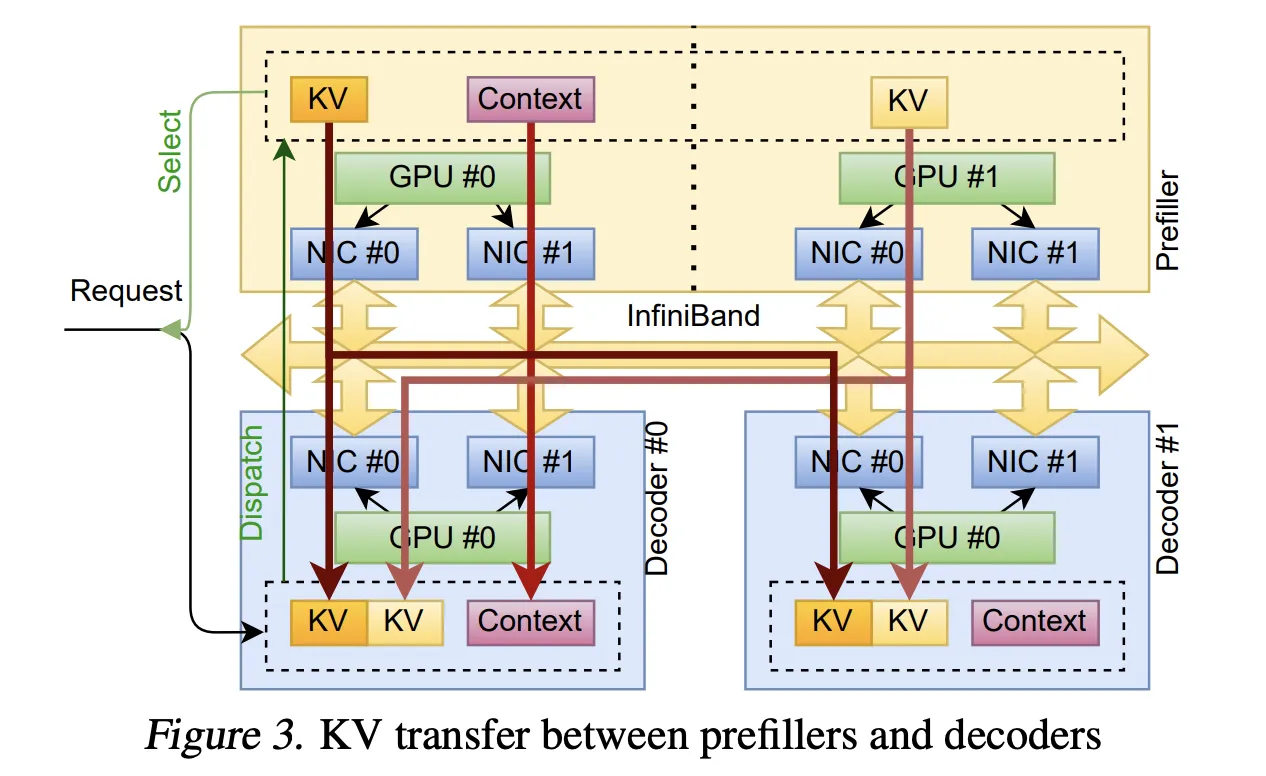
The first production use case is disaggregated inference. Prefill and decode run on separate clusters, so the system must stream KvCache from prefill GPUs to decode GPUs at high speed.
TransferEngine uses alloc_uvm_watcher to track progress in the model. During prefill, the model increments a watcher value after each layer’s attention output projection. When the worker observes a change, it issues paged writes for the KvCache pages of that layer, followed by a single write for the remaining context. This approach allows layer by layer streaming of cache pages without fixed world membership, and it avoids the strict ordering constraints of collectives.
Fast weight transfer for reinforcement learning
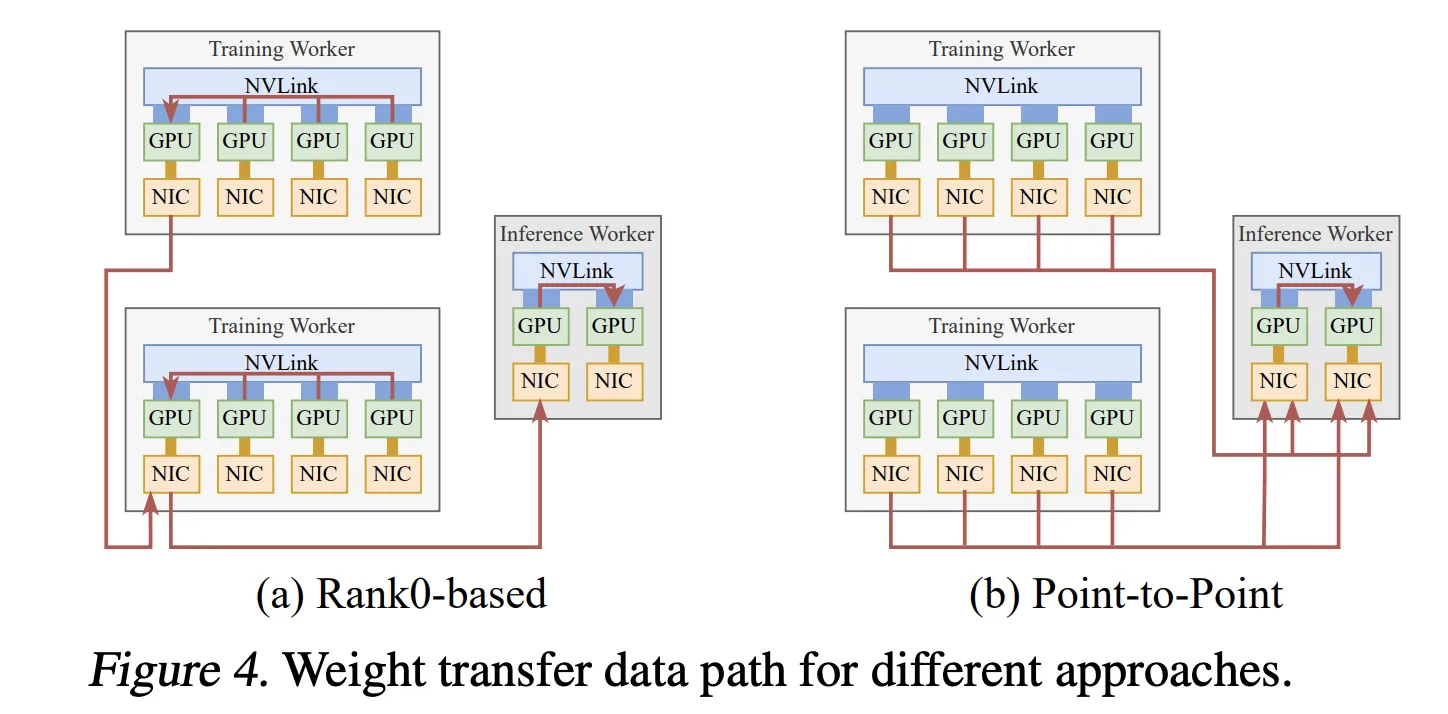
The second system is asynchronous reinforcement learning fine tuning, where training and inference run on separate GPU pools. Traditional designs gather updated parameters to a single rank then broadcast them, which limits throughput to one Network Interface Controller.
Perplexity research team instead uses TransferEngine to perform point to point weight transfer. Each training GPU writes its parameter shard directly into the corresponding inference GPUs using one sided writes. A pipelined execution splits each tensor into stages, host to device copy when Fully Sharded Data Parallel offloads weights, reconstruction and optional quantization, RDMA transfer, and a barrier implemented through scatter and ImmCounter.
In production, this setup delivers weight updates for models such as Kimi K2 at 1 trillion parameters and DeepSeek V3 at 671 billion parameters in about 1.3 seconds from 256 training GPUs to 128 inference GPUs.
Mixture of Experts routing across ConnectX and EFA
The third piece in pplx garden is a point to point Mixture of Experts dispatch and combine kernel. It uses NVLink for intra node traffic and RDMA for inter node traffic. Dispatch and combine are split into separate send and receive phases so that the decoder can micro batch and overlap communication with grouped general matrix multiply.
A host proxy thread polls GPU state and calls TransferEngine when send buffers are ready. Routes are exchanged first, then each rank computes contiguous receive offsets for each expert and writes tokens into private buffers that can be reused between dispatch and combine. This reduces memory footprint and keeps writes large enough to use the full link bandwidth.
On ConnectX 7, Perplexity research team reports state of the art decode latency that is competitive with DeepEP across expert counts. On AWS EFA, the same kernel delivers the first viable MoE decode latencies with higher but still practical values.
In multi node tests with DeepSeek V3 and Kimi K2 on AWS H200 instances, distributing the model across nodes reduces latency at medium batch sizes, which is the common regime for production serving.
Comparison Table
| Key point | TransferEngine (pplx garden) | DeepEP | NVSHMEM (generic MoE use) | Mooncake |
|---|---|---|---|---|
| Primary role | Portable RDMA point to point for LLM systems | MoE all to all dispatch and combine | General GPU shared memory and collectives | Distributed KV cache for LLM inference |
| Hardware focus | NVIDIA ConnectX 7 and AWS EFA, multi NIC per GPU | NVIDIA ConnectX with GPU initiated RDMA IBGDA | NVIDIA GPUs on RDMA fabrics including EFA | RDMA NICs in KV centric serving stacks |
| EFA status | Full support, peak 400 Gbps reported | No support, requires IBGDA on ConnectX | API works but MoE use shows severe degradation on EFA | Paper reports no EFA support in its RDMA engine |
| Portability for LLM systems | Cross vendor, single API across ConnectX 7 and EFA | Vendor specific and ConnectX focused | NVIDIA centric, not viable for EFA MoE routing | Focused on KV sharing, no cross provider support |
Key Takeaways
- TransferEngine gives a single RDMA point to point abstraction that works on both NVIDIA ConnectX 7 and AWS EFA, and manages multiple Network Interface Controllers per GPU transparently.
- The library exposes one sided WriteImm with ImmCounter, and achieves peak 400 Gbps throughput on both NIC families, which lets it match single vendor stacks while remaining portable.
- Perplexity team uses TransferEngine in three production systems, disaggregated prefill decode with KvCache streaming, reinforcement learning weight transfer that updates trillion parameter models in about 1.3 seconds, and Mixture of Experts dispatch combine for large models like Kimi K2.
- On ConnectX 7, pplx garden’s MoE kernels provide state of the art decode latency and exceed DeepEP on the same hardware, while on EFA they deliver the first practical MoE latencies for trillion parameter workloads.
- Because TransferEngine is open source in pplx garden under an MIT license, teams can run very large Mixture of Experts and dense models on heterogeneous H100 or H200 clusters across cloud providers, without rewriting for each vendor specific networking stack.
Editorial Comments
Perplexity’s release of TransferEngine and pplx garden is a practical contribution for LLM infra teams who are blocked by vendor specific networking stacks and expensive fabric upgrades. A portable RDMA abstraction that reaches peak 400 Gbps on both NVIDIA ConnectX 7 and AWS EFA, supports KvCache streaming, fast reinforcement learning weight transfer, and Mixture of Experts routing, directly addresses trillion parameter serving constraints for real systems.
Check out the Paper and Repo. Feel free to check out our GitHub Page for Tutorials, Codes and Notebooks. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
The post Perplexity AI Releases TransferEngine and pplx garden to Run Trillion Parameter LLMs on Existing GPU Clusters appeared first on MarkTechPost.
Credit: Source link