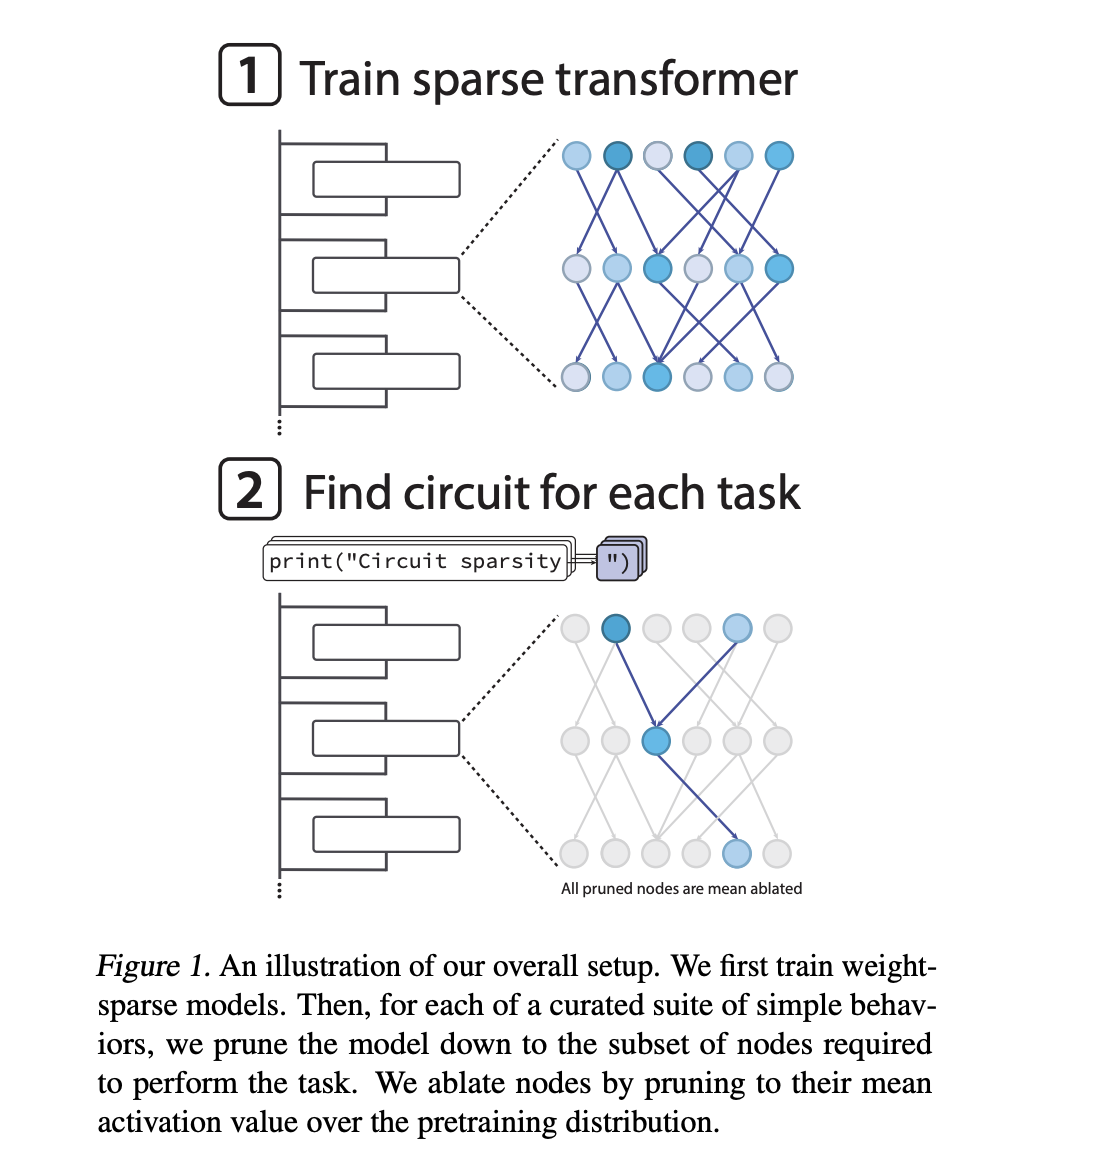

If neural networks are now making decisions everywhere from code editors to safety systems, how can we actually see the specific circuits inside that drive each behavior? OpenAI has introduced a new mechanistic interpretability research study that trains language models to use sparse internal wiring, so that model behavior can be explained using small, explicit circuits.
Training transformers to be weight sparse
Most transformer language models are dense. Each neuron reads from and writes to many residual channels, and features are often in superposition. This makes circuit level analysis difficult. Previous OpenAI work tried to learn sparse feature bases on top of dense models using sparse autoencoders. The new research work instead changes the base model so that the transformer itself is weight sparse.
The OpenAI team trains decoder only transformers with an architecture similar to GPT 2. After each optimizer step with AdamW optimizer, they enforce a fixed sparsity level on every weight matrix and bias, including token embeddings. Only the largest magnitude entries in each matrix are kept. The rest are set to zero. Over training, an annealing schedule gradually drives the fraction of non zero parameters down until the model reaches a target sparsity.
In the most extreme setting, roughly 1 in 1000 weights is non zero. Activations are also somewhat sparse. Around 1 in 4 activations are non zero at a typical node location. The effective connectivity graph is therefore very thin even when the model width is large. This encourages disentangled features that map cleanly onto the residual channels the circuit uses.
Measuring interpretability through task specific pruning
To quantify whether these models are easier to understand, OpenAI team does not rely on qualitative examples alone. The research team define a suite of simple algorithmic tasks based on Python next token prediction. One example, single_double_quote, requires the model to close a Python string with the right quote character. Another example, set_or_string, requires the model to choose between .add and += based on whether a variable was initialized as a set or a string.
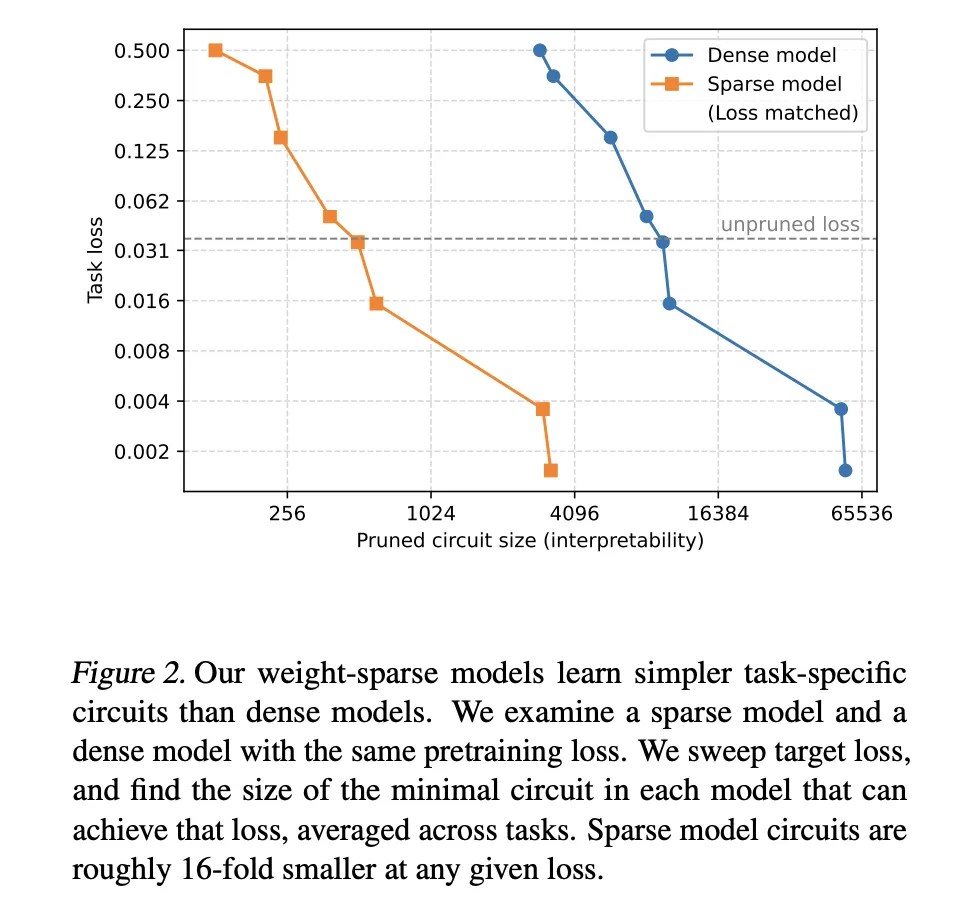
For each task, they search for the smallest subnetwork, called a circuit, that can still perform the task up to a fixed loss threshold. The pruning is node based. A node is an MLP neuron at a specific layer, an attention head, or a residual stream channel at a specific layer. When a node is pruned, its activation is replaced by its mean over the pretraining distribution. This is mean ablation.
The search uses continuous mask parameters for each node and a Heaviside style gate, optimized with a straight through estimator like surrogate gradient. The complexity of a circuit is measured as the count of active edges between retained nodes. The main interpretability metric is the geometric mean of edge counts across all tasks.
Example circuits in sparse transformers
On the single_double_quote task, the sparse models yield a compact and fully interpretable circuit. In an early MLP layer, one neuron behaves as a quote detector that activates on both single and double quotes. A second neuron behaves as a quote type classifier that distinguishes the two quote types. Later, an attention head uses these signals to attend back to the opening quote position and copy its type to the closing position.
In circuit graph terms, the mechanism uses 5 residual channels, 2 MLP neurons in layer 0, and 1 attention head in a later layer with a single relevant query key channel and a single value channel. If the rest of the model is ablated, this subgraph still solves the task. If these few edges are removed, the model fails on the task. The circuit is therefore both sufficient and necessary in the operational sense defined by the paper.

For more complex behaviors, such as type tracking of a variable named current inside a function body, the recovered circuits are larger and only partially understood. The research team show an example where one attention operation writes the variable name into the token set() at the definition, and another attention operation later copies the type information from that token back into a later use of current. This still yields a relatively small circuit graph.
Key Takeaways
- Weight-sparse transformers by design: OpenAI trains GPT-2 style decoder only transformers so that almost all weights are zero, around 1 in 1000 weights is non zero, enforcing sparsity across all weights and biases including token embeddings, which yields thin connectivity graphs that are structurally easier to analyze.
- Interpretability is measured as minimal circuit size: The work defines a benchmark of simple Python next token tasks and, for each task, searches for the smallest subnetwork, in terms of active edges between nodes, that still reaches a fixed loss, using node level pruning with mean ablation and a straight through estimator style mask optimization.
- Concrete, fully reverse engineered circuits emerge: On tasks such as predicting matching quote characters, the sparse model yields a compact circuit with a few residual channels, 2 key MLP neurons and 1 attention head that the authors can fully reverse engineer and verify as both sufficient and necessary for the behavior.
- Sparsity delivers much smaller circuits at fixed capability: At matched pre-training loss levels, weight sparse models require circuits that are roughly 16 times smaller than those recovered from dense baselines, defining a capability interpretability frontier where increased sparsity improves interpretability while slightly reducing raw capability.
Editorial Comments
OpenAI’s work on weight sparse transformers is a pragmatic step toward making mechanistic interpretability operational. By enforcing sparsity directly in the base model, the paper turns abstract discussions of circuits into concrete graphs with measurable edge counts, clear necessity and sufficiency tests, and reproducible benchmarks on Python next token tasks. The models are small and inefficient, but the methodology is relevant for future safety audits and debugging workflows. This research treats interpretability as a first class design constraint rather than an after the fact diagnostic.
Check out the Paper, GitHub Repo and Technical details. Feel free to check out our GitHub Page for Tutorials, Codes and Notebooks. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
The post OpenAI Researchers Train Weight Sparse Transformers to Expose Interpretable Circuits appeared first on MarkTechPost.
Credit: Source link