• bitcoinBitcoin(BTC)$84,884.000.76%
  • ethereumEthereum(ETH)$2,696.170.24%
  • tetherTether(USDT)$1.000.00%
  • binancecoinBNB(BNB)$782.891.38%
  • rippleXRP(XRP)$1.530.58%
  • usd-coinUSDC(USDC)$1.000.00%
  • solanaSolana(SOL)$122.631.52%
  • tronTRON(TRX)$0.333638-0.07%
  • zcashZcash(ZEC)$1,590.76-3.20%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.06-0.38%
  • HyperliquidHyperliquid(HYPE)$91.89-0.41%
  • dogecoinDogecoin(DOGE)$0.0975821.22%
  • chainlinkChainlink(LINK)$14.08-0.22%
  • moneroMonero(XMR)$552.50-1.12%
  • whitebitWhiteBIT Coin(WBT)$84.440.48%
  • USDSUSDS(USDS)$1.00-0.01%
  • cardanoCardano(ADA)$0.2574131.99%
  • RainRain(RAIN)$0.012692-0.51%
  • leo-tokenLEO Token(LEO)$9.020.70%
  • stellarStellar(XLM)$0.2171590.92%
  • nearNEAR Protocol(NEAR)$5.406.02%
  • bitcoin-cashBitcoin Cash(BCH)$333.07-0.32%
  • uniswapUniswap(UNI)$9.740.93%
  • litecoinLitecoin(LTC)$71.05-1.39%
  • CantonCanton(CC)$0.1381132.45%
  • suiSui(SUI)$1.2810.18%
  • Ethena USDeEthena USDe(USDE)$1.000.01%
  • avalanche-2Avalanche(AVAX)$10.950.99%
  • daiDai(DAI)$1.00-0.01%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.631.43%
  • USD1USD1(USD1)$1.00-0.01%
  • quant-networkQuant(QNT)$290.9588.49%
  • hedera-hashgraphHedera(HBAR)$0.0963623.61%
  • BittensorBittensor(TAO)$320.840.16%
  • shiba-inuShiba Inu(SHIB)$0.0000061.25%
  • crypto-com-chainCronos(CRO)$0.066910-1.73%
  • BitwayBitway(BTW)$1.2221.67%
  • Global DollarGlobal Dollar(USDG)$1.00-0.01%
  • tether-goldTether Gold(XAUT)$4,254.59-0.58%
  • OndoOndo(ONDO)$0.599.83%
  • paypal-usdPayPal USD(PYUSD)$1.000.00%
  • EthenaEthena(ENA)$0.2727781.19%
  • MemeCoreMemeCore(M)$1.17-5.26%
  • okbOKB(OKB)$121.470.56%
  • Ripple USDRipple USD(RLUSD)$1.00-0.01%
  • aaveAave(AAVE)$155.840.82%
  • Circle USYCCircle USYC(USYC)$1.140.00%
  • Pump.funPump.fun(PUMP)$0.00514217.06%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.23%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Liquid AI Releases LFM2-8B-A1B: An On-Device Mixture-of-Experts with 8.3B Params and a 1.5B Active Params per Token

October 11, 2025
in AI & Technology
Reading Time: 13 mins read
A A
Liquid AI Releases LFM2-8B-A1B: An On-Device Mixture-of-Experts with 8.3B Params and a 1.5B Active Params per Token
ShareShareShareShareShare

How much capability can a sparse 8.3B-parameter MoE with a ~1.5B active path deliver on your phone without blowing latency or memory? Liquid AI has released LFM2-8B-A1B, a small-scale Mixture-of-Experts (MoE) model built for on-device execution under tight memory, latency, and energy budgets. Unlike most MoE work optimized for cloud batch serving, LFM2-8B-A1B targets phones, laptops, and embedded systems. It showcases 8.3B total parameters but activates only ~1.5B parameters per token, using sparse expert routing to preserve a small compute path while increasing representational capacity. The model is released under the LFM Open License v1.0 (lfm1.0)

Understanding the Architecture

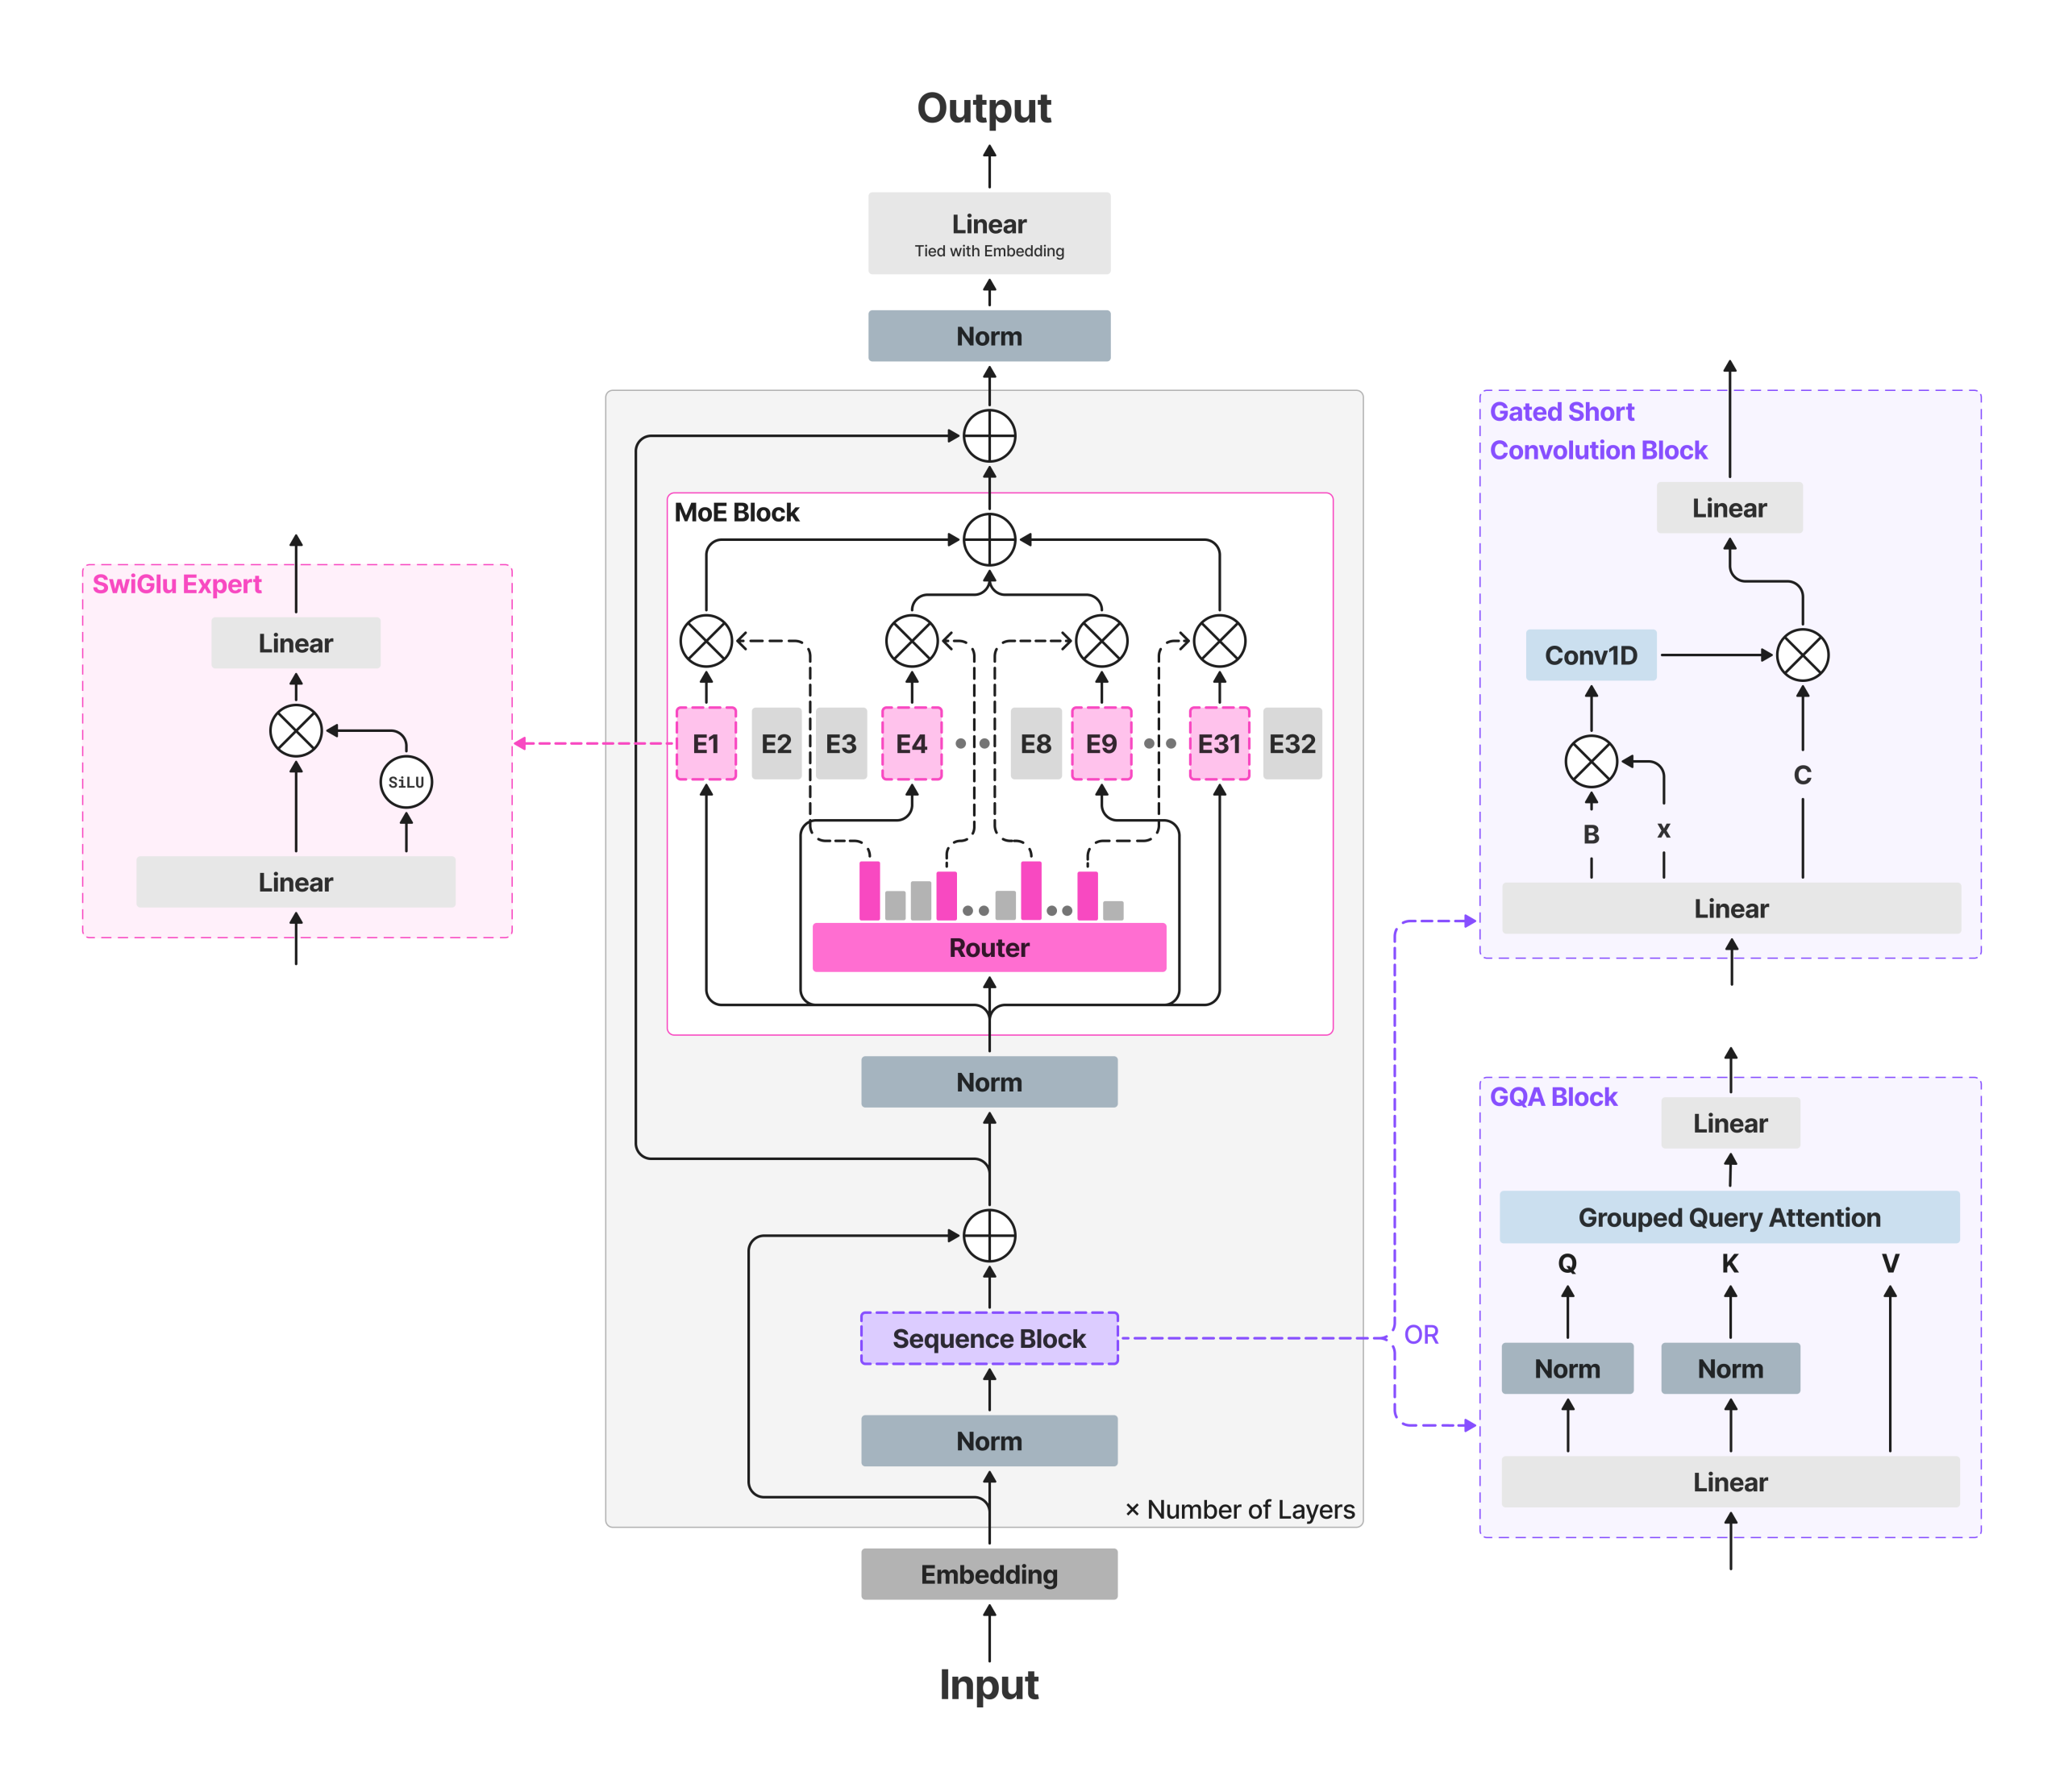
LFM2-8B-A1B retains the LFM2 ‘fast backbone’ and inserts sparse-MoE feed-forward blocks to lift capacity without materially increasing the active compute. The backbone uses 18 gated short-convolution blocks and 6 grouped-query attention (GQA) blocks. All layers except the first two include an MoE block; the first two remain dense for stability. Each MoE block defines 32 experts; the router selects top-4 experts per token with a normalized-sigmoid gate and adaptive routing bias to balance load and stabilize training. Context length is 32,768 tokens; vocabulary size 65,536; reported pre-training budget ~12T tokens.

YOU MAY ALSO LIKE

Bill Gates Says It’s ‘Completely Irresponsible’ For AI To Not Have Safeguards

Should You Ditch Your Tablet For A Foldable Phone?

This approach keeps per-token FLOPs and cache growth bounded by the active path (attention + four expert MLPs), while total capacity allows specialization across domains such as multilingual knowledge, math, and code—use cases that often regress on very small dense models.
https://www.liquid.ai/blog/lfm2-8b-a1b-an-efficient-on-device-mixture-of-experts

Performance signals

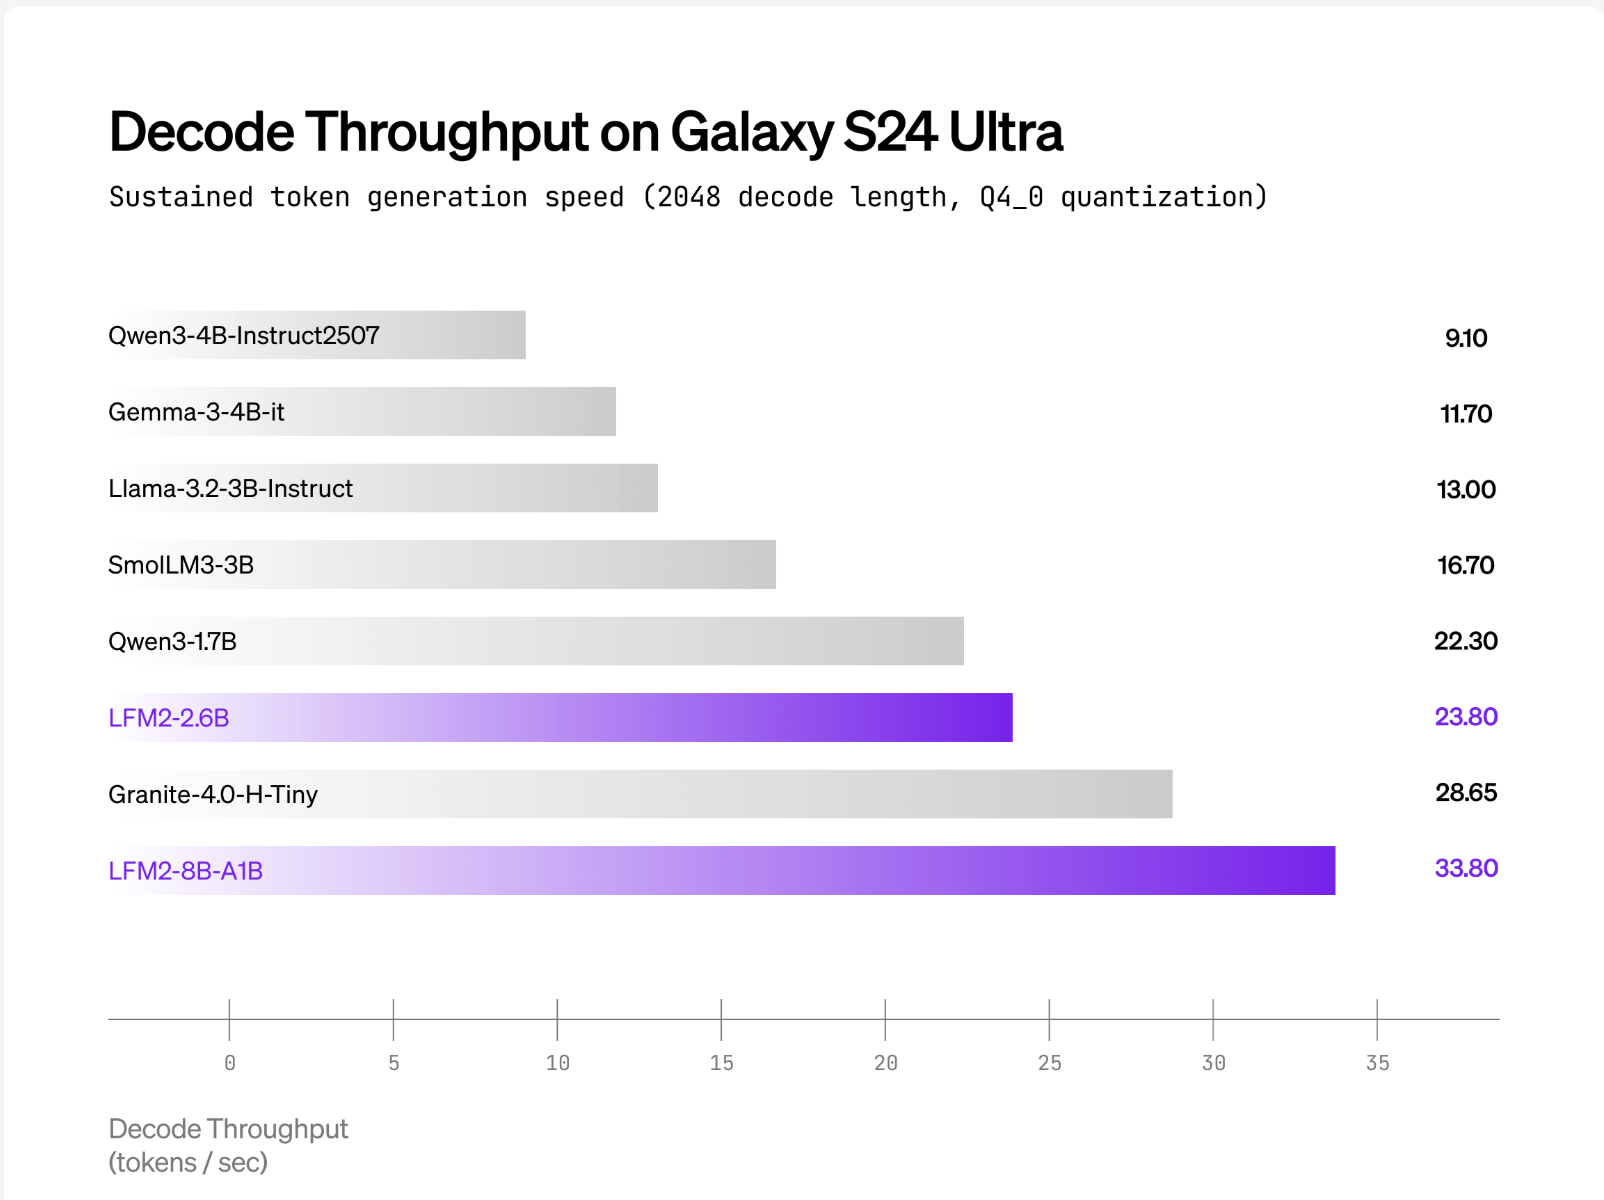
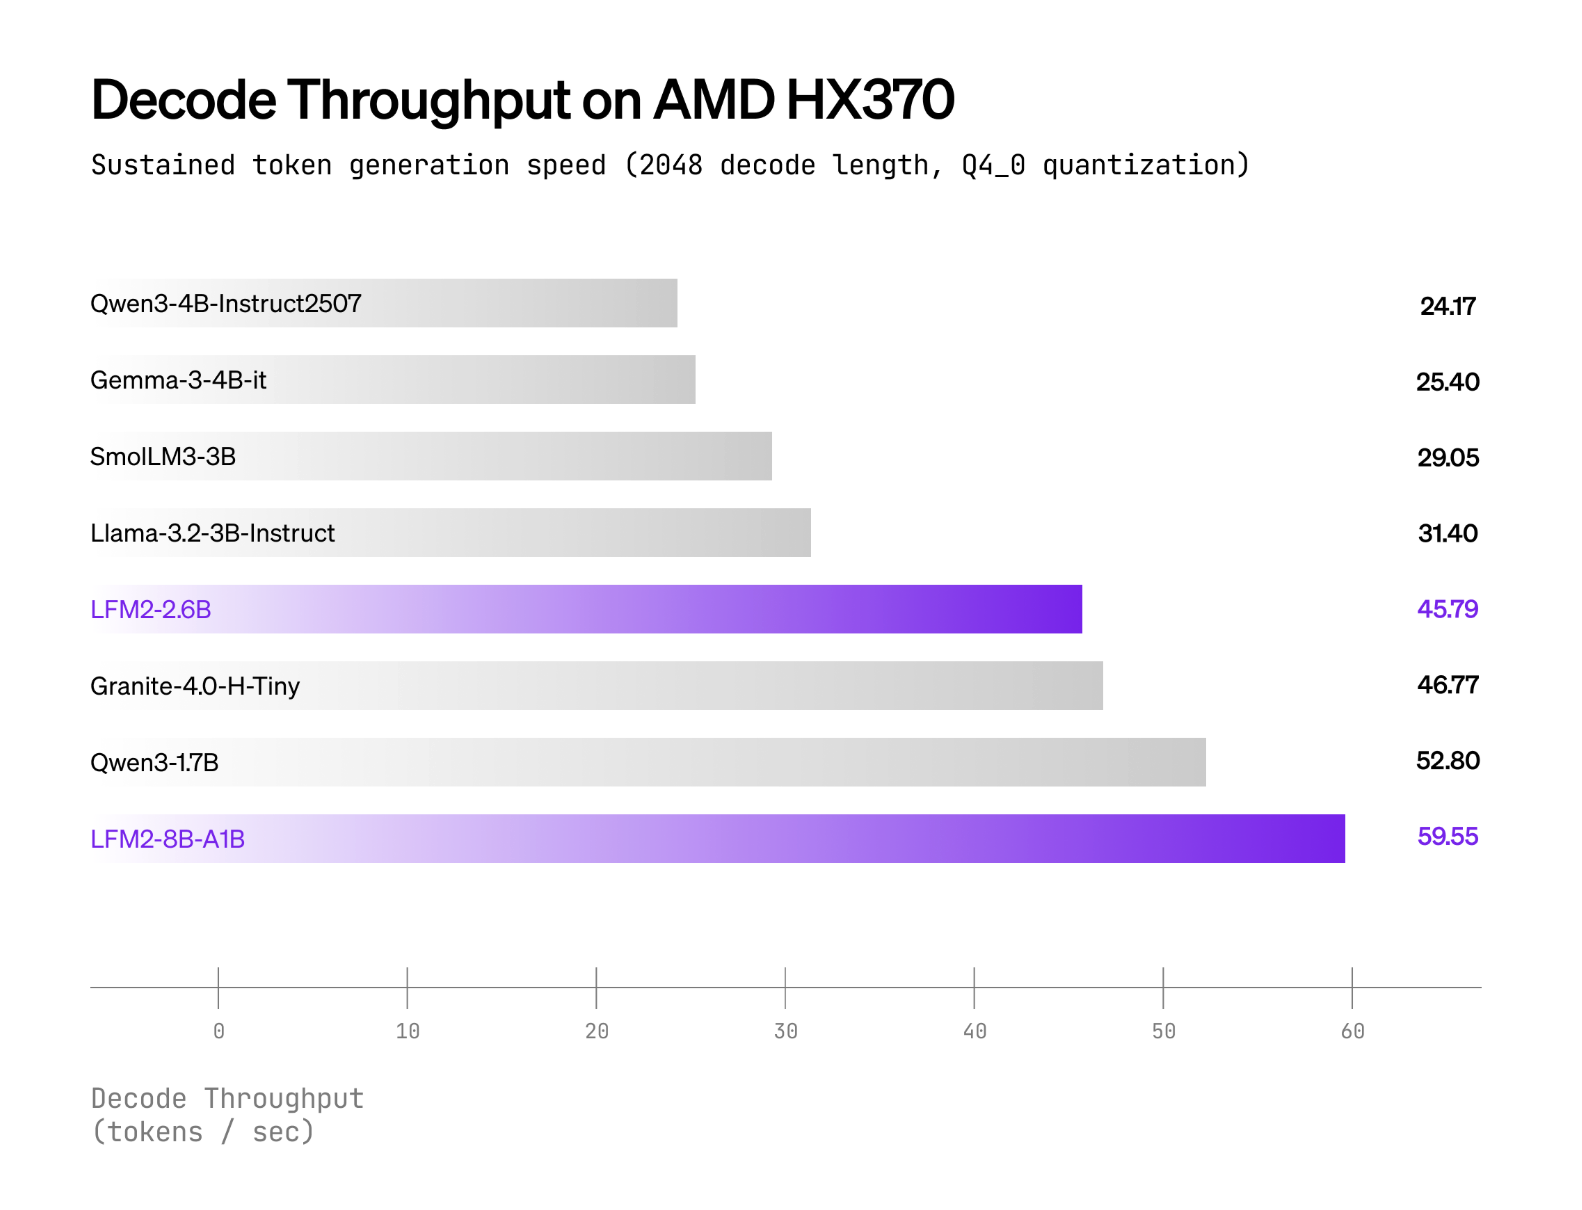
Liquid AI reports that LFM2-8B-A1B runs significantly faster than Qwen3-1.7B under CPU tests using an internal XNNPACK-based stack and a custom CPU MoE kernel. The public plots cover int4 quantization with int8 dynamic activations on AMD Ryzen AI 9 HX370 and Samsung Galaxy S24 Ultra. The Liquid AI team positions quality as comparable to 3–4B dense models, while keeping the active compute near 1.5B. No cross-vendor “×-faster” headline multipliers are published; the claims are framed as per-device comparisons versus similarly active models.

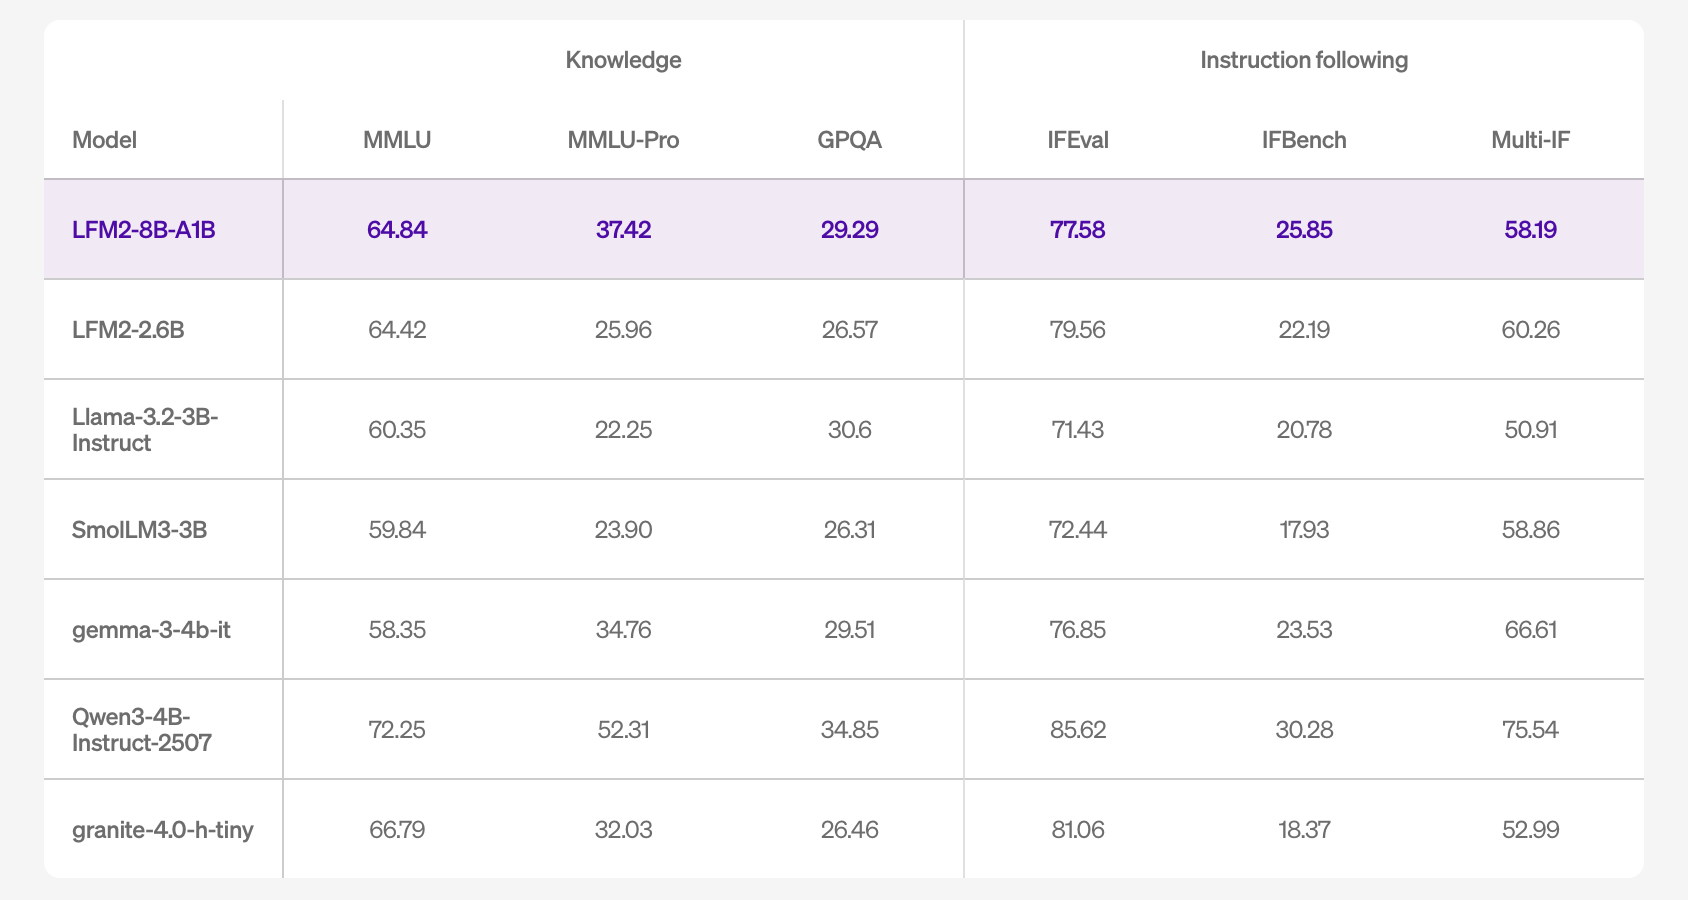
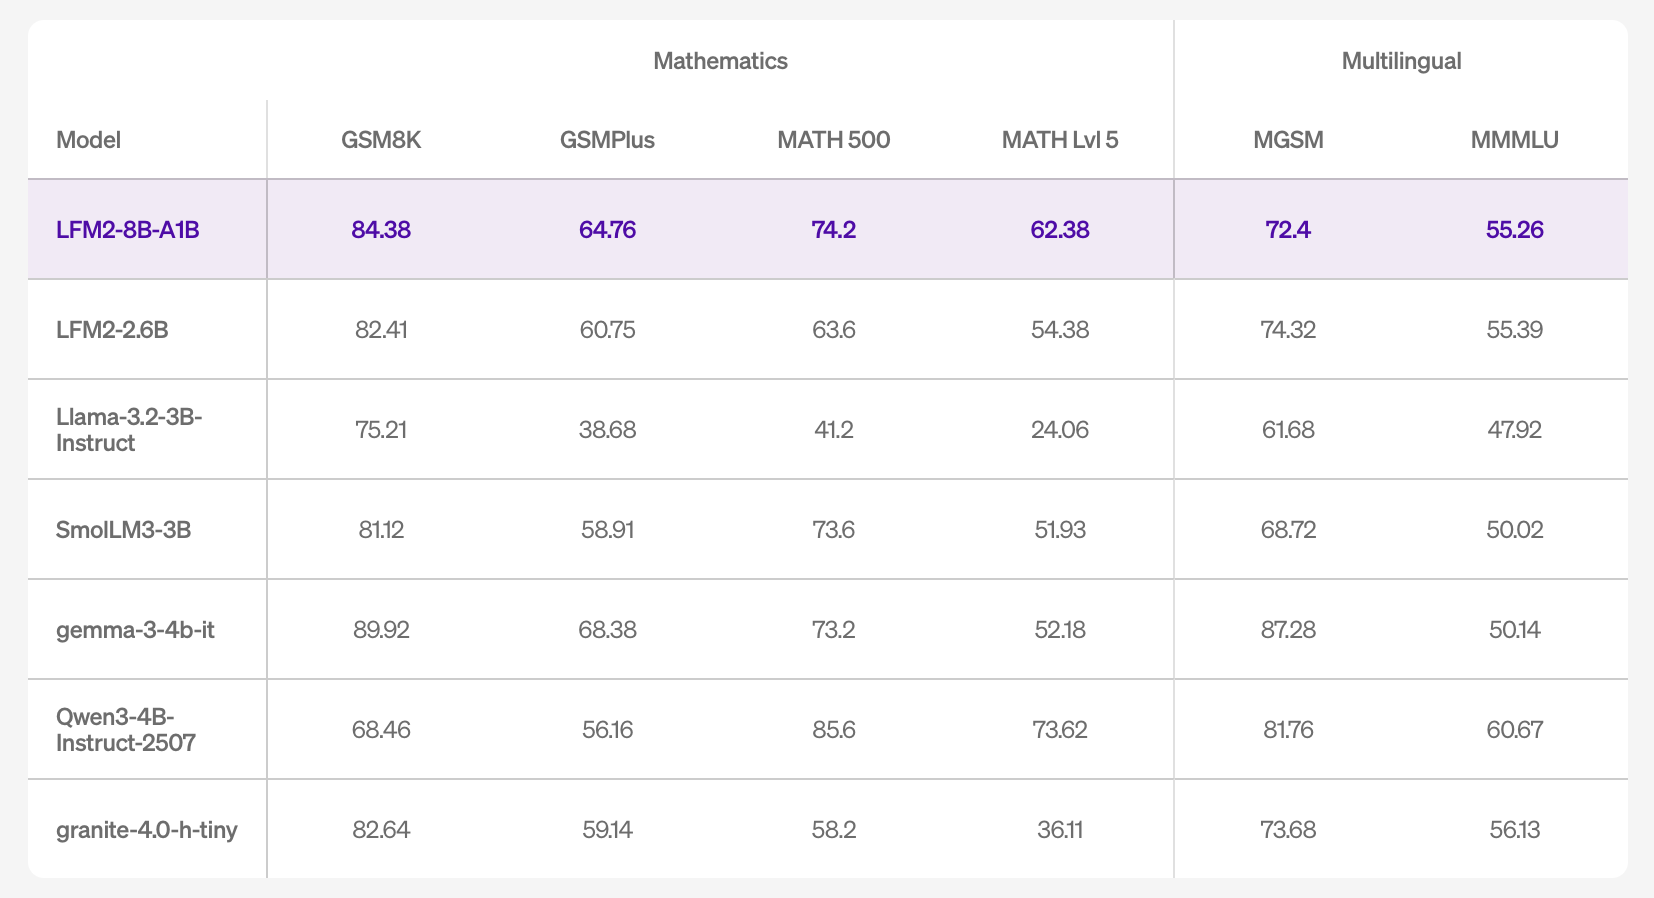
On accuracy, the model card lists results across 16 benchmarks, including MMLU/MMLU-Pro/GPQA (knowledge), IFEval/IFBench/Multi-IF (instruction following), GSM8K/GSMPlus/MATH500/MATH-Lvl-5 (math), and MGSM/MMMLU (multilingual). The numbers indicate competitive instruction-following and math performance within the small-model band, and improved knowledge capacity relative to LFM2-2.6B, consistent with the larger total parameter budget.
https://www.liquid.ai/blog/lfm2-8b-a1b-an-efficient-on-device-mixture-of-experts

Deployment and tooling

LFM2-8B-A1B ships with Transformers/vLLM for GPU inference and GGUF builds for llama.cpp; the official GGUF repo lists common quants from Q4_0 ≈4.7 GB up to F16 ≈16.7 GB for local runs, while llama.cpp requires a recent build with lfm2moe support (b6709+) to avoid “unknown model architecture” errors. Liquid’s CPU validation uses Q4_0 with int8 dynamic activations on AMD Ryzen AI 9 HX370 and Samsung Galaxy S24 Ultra, where LFM2-8B-A1B shows higher decode throughput than Qwen3-1.7B at a similar active-parameter class; ExecuTorch is referenced for mobile/embedded CPU deployment.
https://www.liquid.ai/blog/lfm2-8b-a1b-an-efficient-on-device-mixture-of-experts

Key Takeaways

  • Architecture & routing: LFM2-8B-A1B pairs an LFM2 fast backbone (18 gated short-conv blocks + 6 GQA blocks) with per-layer sparse-MoE FFNs (all layers except the first two), using 32 experts with top-4 routing via normalized-sigmoid gating and adaptive biases; 8.3B total params, ~1.5B active per token.
  • On-device target: Designed for phones, laptops, and embedded CPUs/GPUs; quantized variants “fit comfortably” on high-end consumer hardware for private, low-latency use.
  • Performance positioning. Liquid reports LFM2-8B-A1B is significantly faster than Qwen3-1.7B in CPU tests and aims for 3–4B dense-class quality while keeping an ~1.5B active path.

LFM2-8B-A1B demonstrates that sparse MoE can be practical below the usual server-scale regime. The model combines an LFM2 conv-attention backbone with per-layer expert MLPs (except the first two layers) to keep token compute near 1.5B while lifting quality toward 3–4B dense classes. With standard and GGUF weights, llama.cpp/ExecuTorch/vLLM paths, and a permissive on-device posture, LFM2-8B-A1B is a concrete option for building low-latency, private assistants and application-embedded copilots on consumer and edge hardware.


Check out the Model on Hugging Face and Technical details. Feel free to check out our GitHub Page for Tutorials, Codes and Notebooks. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.

Asif Razzaq is the CEO of Marktechpost Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.

🙌 Follow MARKTECHPOST: Add us as a preferred source on Google.

Credit: Source link

ShareTweetSendSharePin

Related Posts

Bill Gates Says It’s ‘Completely Irresponsible’ For AI To Not Have Safeguards
AI & Technology

Bill Gates Says It’s ‘Completely Irresponsible’ For AI To Not Have Safeguards

September 27, 2026
Should You Ditch Your Tablet For A Foldable Phone?
AI & Technology

Should You Ditch Your Tablet For A Foldable Phone?

September 27, 2026
Why The iPhone Duo Could Be Beneficial For Samsung’s Galaxy Z Fold 8
AI & Technology

Why The iPhone Duo Could Be Beneficial For Samsung’s Galaxy Z Fold 8

September 27, 2026
How To Improve Your Router’s Security In 10 Minutes
AI & Technology

How To Improve Your Router’s Security In 10 Minutes

September 27, 2026
Next Post
Former CDC director says RFK Jr. wanted to change childhood vaccine schedule without evidence

Former CDC director says RFK Jr. wanted to change childhood vaccine schedule without evidence

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
NBC Nightly News Full Episode – Aug. 24

NBC Nightly News Full Episode – Aug. 24

September 24, 2026
Bear steals a gear bag from a fire station in Colorado

Bear steals a gear bag from a fire station in Colorado

September 23, 2026
We Finally Have A Trailer For That Four-Hour Elon Musk Documentary

We Finally Have A Trailer For That Four-Hour Elon Musk Documentary

September 24, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!