
• bitcoinBitcoin(BTC)$83,865.00-0.69%
  • ethereumEthereum(ETH)$2,688.390.06%
  • tetherTether(USDT)$1.000.00%
  • binancecoinBNB(BNB)$767.99-0.89%
  • rippleXRP(XRP)$1.51-0.84%
  • usd-coinUSDC(USDC)$1.000.00%
  • solanaSolana(SOL)$119.55-1.95%
  • tronTRON(TRX)$0.3345690.26%
  • zcashZcash(ZEC)$1,536.71-2.93%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.060.00%
  • HyperliquidHyperliquid(HYPE)$89.27-2.12%
  • dogecoinDogecoin(DOGE)$0.094527-2.43%
  • chainlinkChainlink(LINK)$15.086.88%
  • moneroMonero(XMR)$544.64-0.33%
  • whitebitWhiteBIT Coin(WBT)$83.76-0.58%
  • USDSUSDS(USDS)$1.000.00%
  • cardanoCardano(ADA)$0.246686-3.08%
  • RainRain(RAIN)$0.0125640.06%
  • leo-tokenLEO Token(LEO)$9.060.37%
  • stellarStellar(XLM)$0.2241063.89%
  • nearNEAR Protocol(NEAR)$4.94-5.24%
  • bitcoin-cashBitcoin Cash(BCH)$311.86-6.69%
  • uniswapUniswap(UNI)$8.98-6.94%
  • hedera-hashgraphHedera(HBAR)$0.12682035.58%
  • litecoinLitecoin(LTC)$70.16-1.43%
  • CantonCanton(CC)$0.130411-2.30%
  • avalanche-2Avalanche(AVAX)$10.45-4.32%
  • Ethena USDeEthena USDe(USDE)$1.000.01%
  • suiSui(SUI)$1.17-6.53%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.64-2.75%
  • daiDai(DAI)$1.000.00%
  • USD1USD1(USD1)$1.000.00%
  • BittensorBittensor(TAO)$304.26-6.16%
  • quant-networkQuant(QNT)$236.5727.02%
  • crypto-com-chainCronos(CRO)$0.0690402.81%
  • shiba-inuShiba Inu(SHIB)$0.000006-3.37%
  • Global DollarGlobal Dollar(USDG)$1.000.03%
  • tether-goldTether Gold(XAUT)$4,142.38-3.22%
  • paypal-usdPayPal USD(PYUSD)$1.000.00%
  • MemeCoreMemeCore(M)$1.16-0.96%
  • BitwayBitway(BTW)$0.97-17.98%
  • EthenaEthena(ENA)$0.258882-5.66%
  • OndoOndo(ONDO)$0.52-4.48%
  • Ripple USDRipple USD(RLUSD)$1.000.01%
  • Pump.funPump.fun(PUMP)$0.0053348.23%
  • okbOKB(OKB)$118.11-2.50%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • aaveAave(AAVE)$148.14-4.02%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.15-0.12%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Meta Superintelligence Labs Introduces REFRAG: Scaling RAG with 16× Longer Contexts and 31× Faster Decoding

September 7, 2025
in AI & Technology
Reading Time: 9 mins read
A A
Meta Superintelligence Labs Introduces REFRAG: Scaling RAG with 16× Longer Contexts and 31× Faster Decoding
ShareShareShareShareShare

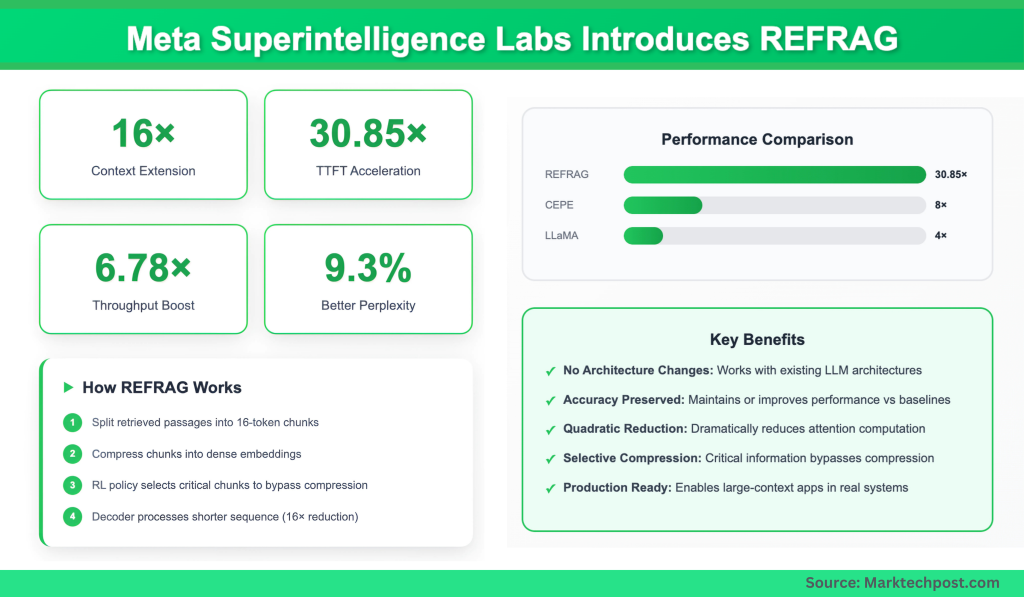
A team of researchers from Meta Superintelligence Labs, National University of Singapore and Rice University has unveiled REFRAG (REpresentation For RAG), a decoding framework that rethinks retrieval-augmented generation (RAG) efficiency. REFRAG extends LLM context windows by 16× and achieves up to a 30.85× acceleration in time-to-first-token (TTFT) without compromising accuracy.

Why is long context such a bottleneck for LLMs?

The attention mechanism in large language models scales quadratically with input length. If a document is twice as long, the compute and memory cost can grow fourfold. This not only slows inference but also increases the size of the key-value (KV) cache, making large-context applications impractical in production systems. In RAG settings, most retrieved passages contribute little to the final answer, but the model still pays the full quadratic price to process them.

YOU MAY ALSO LIKE

How To Improve Your Samsung Galaxy’s Battery Performance

A Modular, Repairable GPS Watch Is A Good First Step

How does REFRAG compress and shorten context?

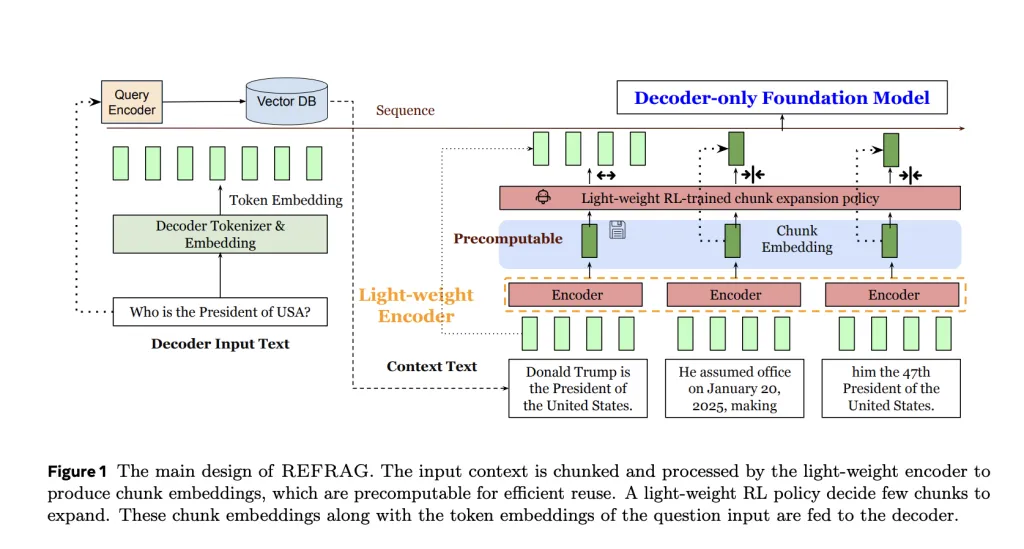
REFRAG introduces a lightweight encoder that splits retrieved passages into fixed-size chunks (e.g., 16 tokens) and compresses each into a dense chunk embedding. Instead of feeding thousands of raw tokens, the decoder processes this shorter sequence of embeddings. The result is a 16× reduction in sequence length, with no change to the LLM architecture.
https://arxiv.org/pdf/2509.01092

How is acceleration achieved?

By shortening the decoder’s input sequence, REFRAG reduces the quadratic attention computation and shrinks the KV cache. Empirical results show 16.53× TTFT acceleration at k=16 and 30.85× acceleration at k=32, far surpassing prior state-of-the-art CEPE (which achieved only 2–8×). Throughput also improves by up to 6.78× compared to LLaMA baselines.

How does REFRAG preserve accuracy?

A reinforcement learning (RL) policy supervises compression. It identifies the most information-dense chunks and allows them to bypass compression, feeding raw tokens directly into the decoder. This selective strategy ensures that critical details—such as exact numbers or rare entities—are not lost. Across multiple benchmarks, REFRAG maintained or improved perplexity compared to CEPE while operating at far lower latency.

What do the experiments reveal?

REFRAG was pretrained on 20B tokens from the SlimPajama corpus (Books + arXiv) and tested on long-context datasets including Book, Arxiv, PG19, and ProofPile. On RAG benchmarks, multi-turn conversation tasks, and long-document summarization, REFRAG consistently outperformed strong baselines:

  • 16× context extension beyond standard LLaMA-2 (4k tokens).
  • ~9.3% perplexity improvement over CEPE across four datasets.
  • Better accuracy in weak retriever settings, where irrelevant passages dominate, due to the ability to process more passages under the same latency budget.
https://arxiv.org/pdf/2509.01092

Summary

REFRAG shows that long-context LLMs don’t have to be slow or memory-hungry. By compressing retrieved passages into compact embeddings, selectively expanding only the important ones, and rethinking how RAG decoding works, Meta Superintelligence Labs has made it possible to process much larger inputs while running dramatically faster. This makes large-context applications—like analyzing entire reports, handling multi-turn conversations, or scaling enterprise RAG systems—not only feasible but efficient, without compromising accuracy.

FAQs

Q1. What is REFRAG?
REFRAG (REpresentation For RAG) is a decoding framework from Meta Superintelligence Labs that compresses retrieved passages into embeddings, enabling faster and longer-context inference in LLMs.

Q2. How much faster is REFRAG compared to existing methods?
REFRAG delivers up to 30.85× faster time-to-first-token (TTFT) and 6.78× throughput improvement compared to LLaMA baselines, while outperforming CEPE.

Q3. Does compression reduce accuracy?
No. A reinforcement learning policy ensures critical chunks remain uncompressed, preserving key details. Across benchmarks, REFRAG maintained or improved accuracy relative to prior methods.

Q4. Where will the code be available?
Meta Superintelligence Labs will release REFRAG on GitHub at facebookresearch/refrag


Check out the PAPER here. Feel free to check out our GitHub Page for Tutorials, Codes and Notebooks. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter.

Asif Razzaq is the CEO of Marktechpost Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.

Credit: Source link

ShareTweetSendSharePin

Related Posts

How To Improve Your Samsung Galaxy’s Battery Performance
AI & Technology

How To Improve Your Samsung Galaxy’s Battery Performance

September 28, 2026
A Modular, Repairable GPS Watch Is A Good First Step
AI & Technology

A Modular, Repairable GPS Watch Is A Good First Step

September 28, 2026
Fireworks AI Releases Ember-1: A Post-Trained Kimi K3 That Uses About 40% Fewer Tokens
AI & Technology

Fireworks AI Releases Ember-1: A Post-Trained Kimi K3 That Uses About 40% Fewer Tokens

September 28, 2026
You Can Now Preorder The Tiny Boox Picco Ereader
AI & Technology

You Can Now Preorder The Tiny Boox Picco Ereader

September 28, 2026
Next Post
Apple Plans AI ‘Answer Engine’ to Rival OpenAI

Apple Plans AI 'Answer Engine' to Rival OpenAI

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
NVIDIA Introduces SoL-Pi: Auto-Research Loops That Cut Coding Agent Token Traffic by Up to 49%

NVIDIA Introduces SoL-Pi: Auto-Research Loops That Cut Coding Agent Token Traffic by Up to 49%

September 22, 2026
How the Ellisons pulled off Paramount-WBD settlement talks and cleared major hurdle to forging media giant

How the Ellisons pulled off Paramount-WBD settlement talks and cleared major hurdle to forging media giant

September 21, 2026
How To Enter VR Mode On Steam

How To Enter VR Mode On Steam

September 22, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!