Spoken Dialogue Models (SDMs) are at the frontier of conversational AI, enabling seamless spoken interactions between humans and machines. Yet, as SDMs become integral to digital assistants, smart devices, and customer service bots, evaluating their true ability to handle the real-world intricacies of human dialogue remains a significant challenge. A new research paper from China introduced C3 benchmark directly addresses this gap, providing a comprehensive, bilingual evaluation suite for SDMs—emphasizing the unique difficulties inherent in spoken conversations.
The Unexplored Complexity of Spoken Dialogue
While text-based Large Language Models (LLMs) have benefited from extensive benchmarking, spoken dialogues present a distinct set of challenges:
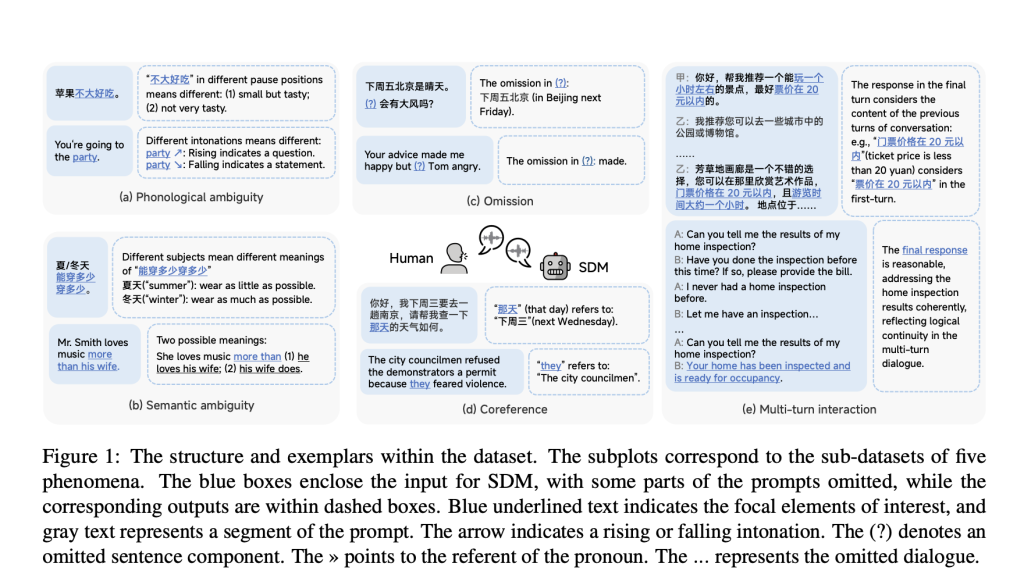
- Phonological Ambiguity: Variations in intonation, stress, pauses, and homophones can entirely alter meaning, especially across languages with tonal elements such as Chinese.
- Semantic Ambiguity: Words and sentences with multiple meanings (lexical and syntactic ambiguity) demand careful disambiguation.
- Omission and Coreference: Speakers often omit words or use pronouns, relying on context for understanding—a recurring challenge for AI models.
- Multi-turn Interaction: Natural dialogue isn’t one-shot; understanding often accumulates over several conversational turns, requiring robust memory and coherent history tracking.
Existing benchmarks for SDMs are often limited to a single language, restricted to single-turn dialogues, and rarely address ambiguity or context-dependency, leaving large evaluation gaps.
C3 Benchmark: Dataset Design and Scope
C3—“A Bilingual Benchmark for Spoken Dialogue Models Exploring Challenges in Complex Conversations”—introduces:
- 1,079 instances across English and Chinese, intentionally spanning five key phenomena:
- Phonological Ambiguity
- Semantic Ambiguity
- Omission
- Coreference
- Multi-turn Interaction
- Audio-text paired samples enabling true spoken dialogue evaluation (with 1,586 pairs due to multi-turn settings).
- Careful manual quality controls: Audio is regenerated or human-voiced to ensure uniform timbre and remove background noise.
- Task-oriented instructions crafted for each type of phenomenon, urging SDMs to detect, interpret, resolve, and generate appropriately.
- Balanced coverage of both languages, with Chinese examples emphasizing tone and unique referential structures not present in English.
Evaluation Methodology: LLM-as-a-Judge and Human Alignment
The research team introduces an innovative LLM-based automatic evaluation method—using strong LLMs (GPT-4o, DeepSeek-R1) to judge SDM responses, with results closely correlating with independent human evaluation (Pearson and Spearman > 0.87, p < 0.001).
- Automatic Evaluation: For most tasks, output audio is transcribed and compared to reference answers by the LLM. For phenomena solely discernible in audio (e.g., intonation), humans annotate responses.
- Task-specific Metrics: For omission and coreference, both detection and resolution accuracy are measured.
- Reliability Testing: Multiple human raters and robust statistical validation confirm that automatic and human judges are highly consistent.
Benchmark Results: Model Performance and Key Findings
Results from evaluating six state-of-the-art end-to-end SDMs across English and Chinese reveal:
| Model | Top Score (English) | Top Score (Chinese) |
|---|---|---|
| GPT-4o-Audio-Preview | 55.68% | 29.45% |
| Qwen2.5-Omni | 51.91%2 | 40.08% |
Analysis by Phenomena:
- Ambiguity is Tougher than Context-Dependency: SDMs score significantly lower on phonological and semantic ambiguity than on omission, coreference, or multi-turn tasks—especially in Chinese, where semantic ambiguity drops below 4% accuracy.
- Language Matters: All SDMs perform better on English than Chinese in most categories. The gap persists even among models designed for both languages.
- Model Variation: Some models (like Qwen2.5-Omni) excel at multi-turn and context tracking, while others (like GPT-4o-Audio-Preview) dominate ambiguity resolution in English.
- Omission and Coreference: Detection is usually easier than resolution/completion—demonstrating that recognizing a problem is distinct from addressing it.
Implications for Future Research
C3 conclusively demonstrates that:
- Current SDMs are far from human-level in challenging conversational phenomena.
- Language-specific features (especially tonal and referential aspects of Chinese) require tailored modeling and evaluation.
- Benchmarking must move beyond single-turn, ambiguity-free settings.
The open-source nature of C3, along with its robust bilingual design, provides the foundation for the next wave of SDMs—enabling researchers and engineers to isolate and improve on the most challenging aspects of spoken AI.2507.22968v1.pdf
Conclusion
The C3 benchmark marks an important advancement in evaluating SDMs, pushing conversations beyond simple scripts toward the genuine messiness of human interaction. By carefully exposing models to phonological, semantic, and contextual complexity in both English and Chinese, C3 lays the groundwork for future systems that can truly understand—and participate in—complex spoken dialogue.
Check out the Paper and GitHub Page. Feel free to check out our GitHub Page for Tutorials, Codes and Notebooks. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter.
Nikhil is an intern consultant at Marktechpost. He is pursuing an integrated dual degree in Materials at the Indian Institute of Technology, Kharagpur. Nikhil is an AI/ML enthusiast who is always researching applications in fields like biomaterials and biomedical science. With a strong background in Material Science, he is exploring new advancements and creating opportunities to contribute.
Credit: Source link