• bitcoinBitcoin(BTC)$84,581.00-1.87%
  • ethereumEthereum(ETH)$2,692.13-2.34%
  • tetherTether(USDT)$1.00-0.01%
  • binancecoinBNB(BNB)$768.18-2.40%
  • rippleXRP(XRP)$1.50-4.57%
  • usd-coinUSDC(USDC)$1.000.00%
  • solanaSolana(SOL)$115.17-2.87%
  • tronTRON(TRX)$0.341269-0.17%
  • zcashZcash(ZEC)$1,501.45-2.76%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.03-0.88%
  • HyperliquidHyperliquid(HYPE)$93.98-2.99%
  • dogecoinDogecoin(DOGE)$0.092796-7.80%
  • moneroMonero(XMR)$551.03-2.80%
  • whitebitWhiteBIT Coin(WBT)$84.97-1.98%
  • USDSUSDS(USDS)$1.00-0.01%
  • chainlinkChainlink(LINK)$12.37-5.13%
  • cardanoCardano(ADA)$0.238987-5.91%
  • RainRain(RAIN)$0.012280-6.28%
  • leo-tokenLEO Token(LEO)$9.010.37%
  • stellarStellar(XLM)$0.202399-6.74%
  • bitcoin-cashBitcoin Cash(BCH)$338.750.07%
  • uniswapUniswap(UNI)$9.26-9.02%
  • nearNEAR Protocol(NEAR)$4.34-1.06%
  • Ethena USDeEthena USDe(USDE)$1.00-0.01%
  • litecoinLitecoin(LTC)$61.51-2.77%
  • daiDai(DAI)$1.00-0.01%
  • avalanche-2Avalanche(AVAX)$10.32-8.07%
  • USD1USD1(USD1)$1.000.00%
  • CantonCanton(CC)$0.109802-4.24%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.42-2.98%
  • hedera-hashgraphHedera(HBAR)$0.090353-9.04%
  • suiSui(SUI)$0.96-6.00%
  • shiba-inuShiba Inu(SHIB)$0.000006-7.61%
  • BittensorBittensor(TAO)$287.22-8.32%
  • Global DollarGlobal Dollar(USDG)$1.00-0.01%
  • crypto-com-chainCronos(CRO)$0.061283-8.31%
  • BitwayBitway(BTW)$1.0313.19%
  • MemeCoreMemeCore(M)$1.22-7.09%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.01%
  • tether-goldTether Gold(XAUT)$4,290.73-1.58%
  • okbOKB(OKB)$118.63-3.44%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • Ripple USDRipple USD(RLUSD)$1.000.00%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.15-0.03%
  • mantleMantle(MNT)$0.65-2.16%
  • aaveAave(AAVE)$138.95-5.44%
  • EthenaEthena(ENA)$0.205625-4.93%
  • OndoOndo(ONDO)$0.414499-5.53%
  • AsterAster(ASTER)$0.69-5.32%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Scalable and Principled Reward Modeling for LLMs: Enhancing Generalist Reward Models RMs with SPCT and Inference-Time Optimization

April 7, 2025
in AI & Technology
Reading Time: 4 mins read
A A
Scalable and Principled Reward Modeling for LLMs: Enhancing Generalist Reward Models RMs with SPCT and Inference-Time Optimization
ShareShareShareShareShare

Reinforcement Learning RL has become a widely used post-training method for LLMs, enhancing capabilities like human alignment, long-term reasoning, and adaptability. A major challenge, however, is generating accurate reward signals in broad, less structured domains, as current high-quality reward models are largely built on rule-based systems or verifiable tasks such as math and coding. In general applications, reward criteria are more diverse and subjective, lacking clear ground truths. To address this, generalist reward models (RMs) are being explored for broader applicability. However, these models must balance input flexibility and scalability during inference, particularly in producing reliable, high-quality rewards across varied tasks and domains.

Existing reward modeling approaches include scalar, semi-scalar, and generative techniques, each with flexibility and inference-time performance trade-offs. For instance, pairwise models are limited to relative comparisons, while scalar models struggle with producing diverse feedback. Generative reward models (GRMs) offer richer, more flexible outputs, making them more suited for evaluating various responses. Recent work has explored training GRMs through offline RL, integrating tools and external knowledge to improve reward quality. However, few methods directly address how RMs can scale efficiently during inference. This has led to research on methods like sampling-based scaling, chain-of-thought prompting, and reward-guided aggregation, aiming to co-scale policy models and reward models during inference. These developments hold promise for more robust, general-purpose reward systems in LLMs.

YOU MAY ALSO LIKE

Microsoft’s New Surface Pro 12 And Surface Laptop 13 Feature Snapdragon X2 Plus Chips

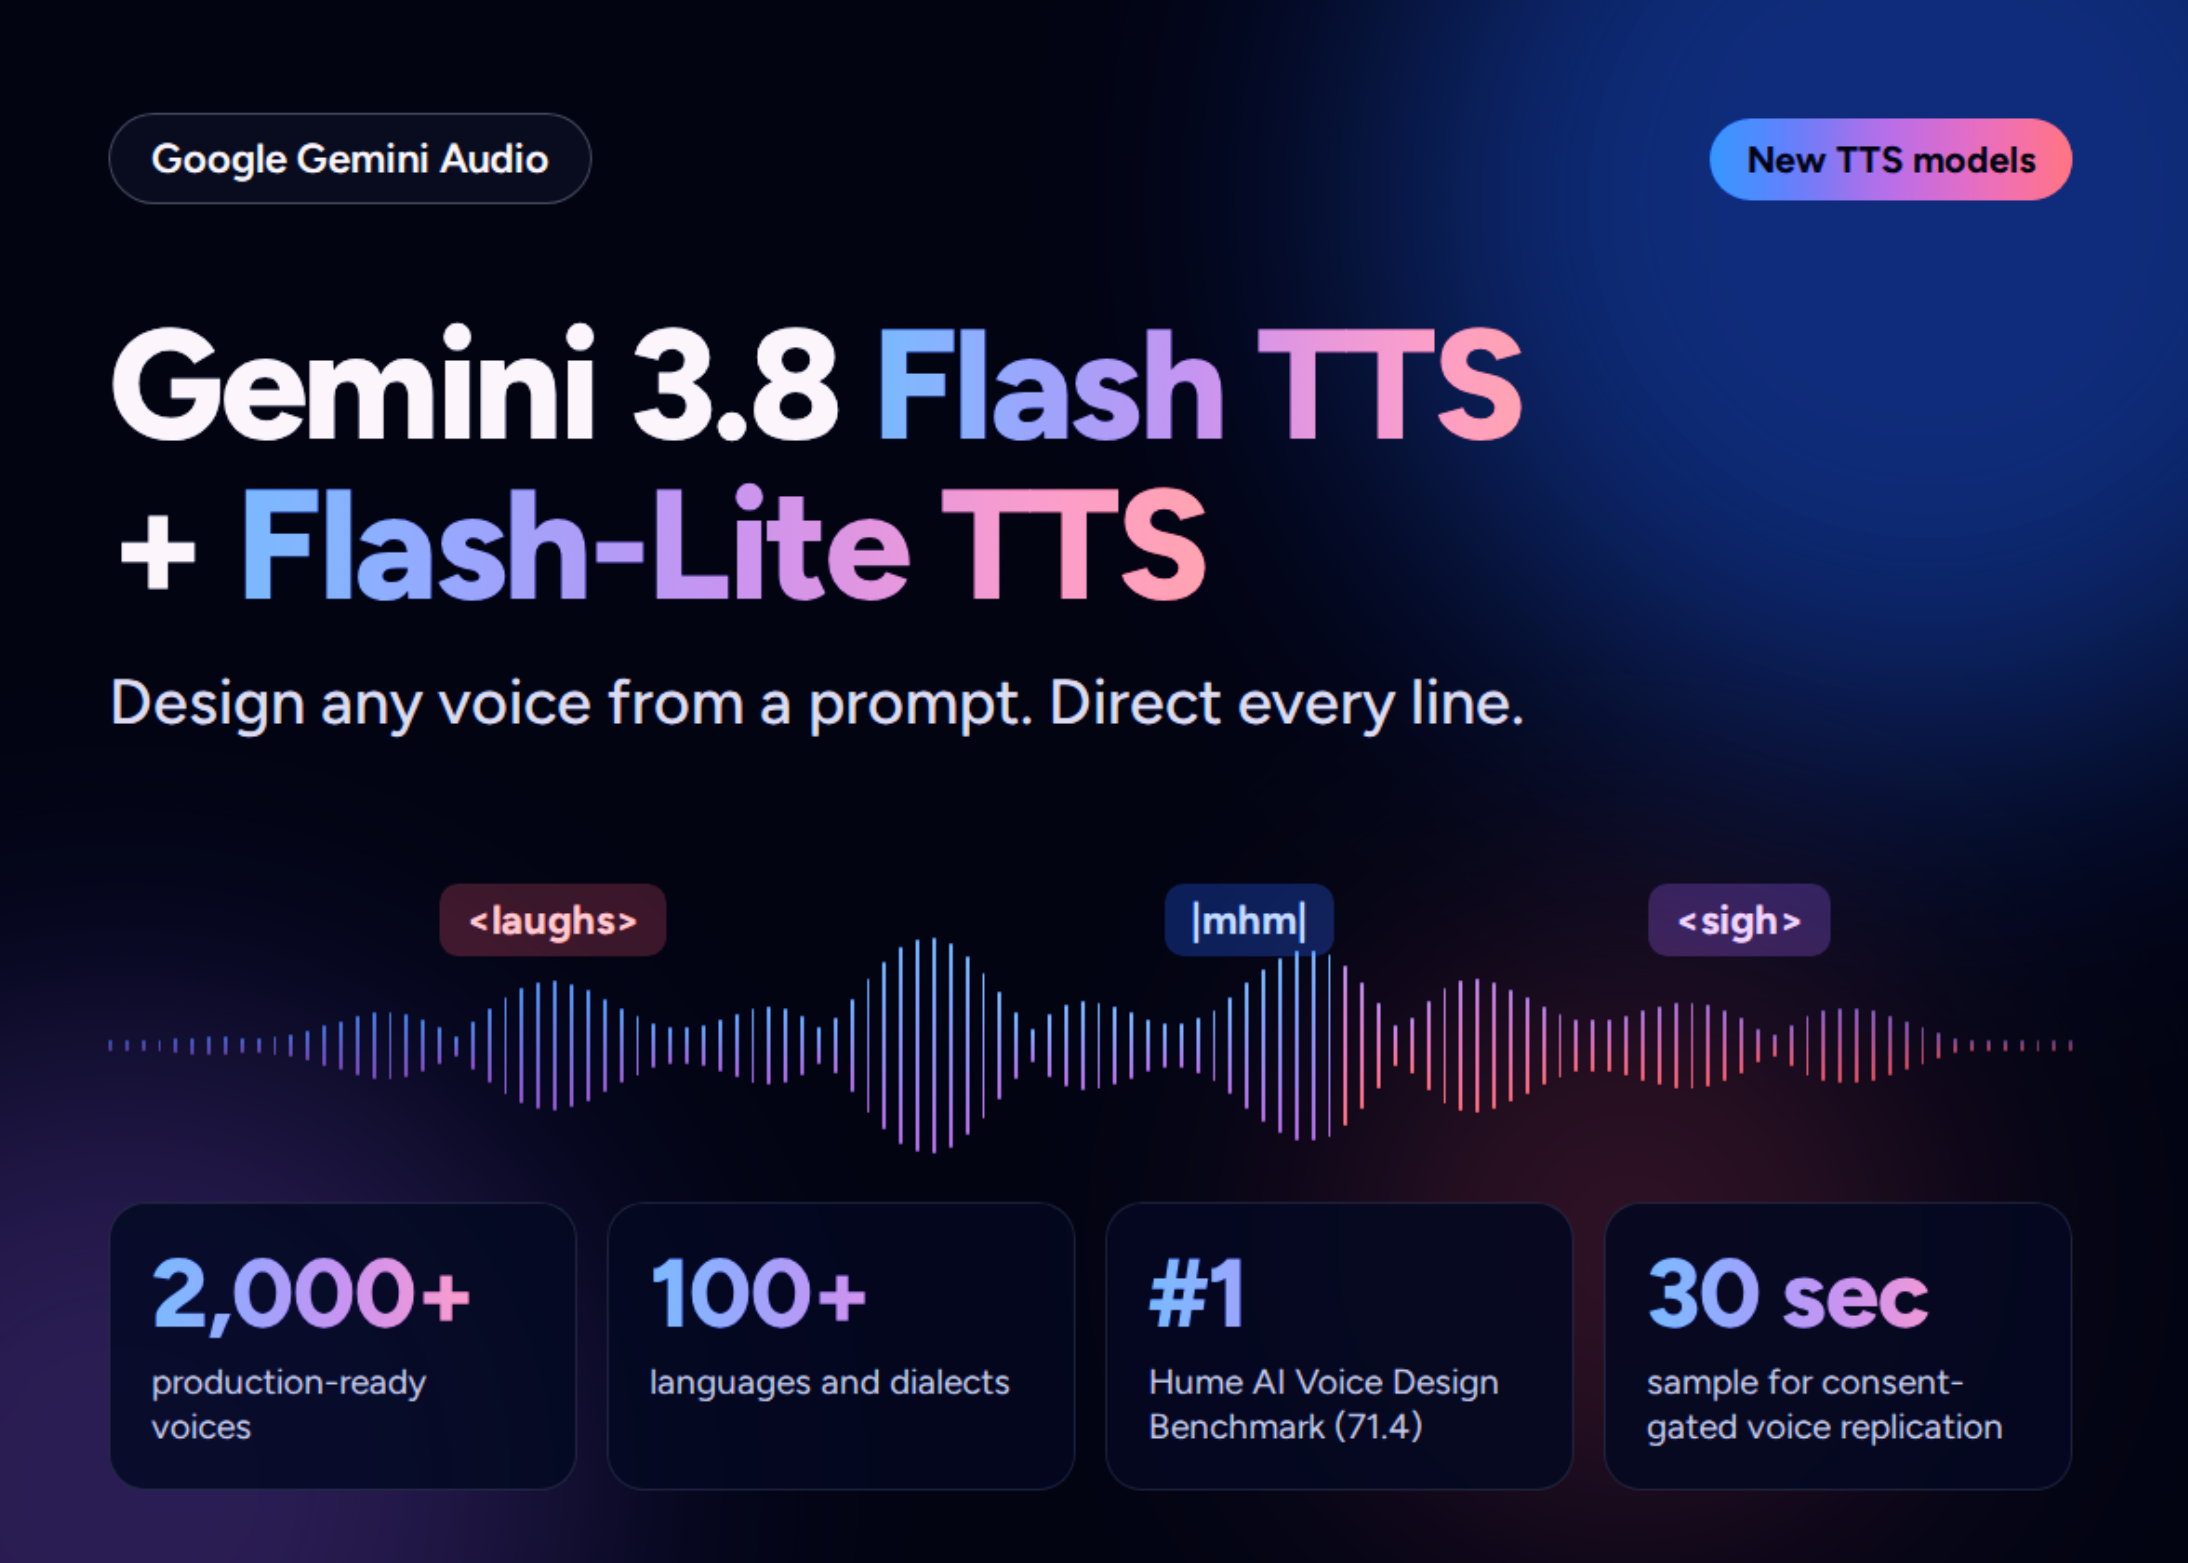
Google Releases Gemini 3.8 Flash TTS and Flash-Lite TTS With Prompt-Based Voice Design

DeepSeek-AI and Tsinghua University researchers explore enhancing reward models RM for general queries by improving inference-time scalability using increased computing and better learning techniques. They employ pointwise GRM for flexible input handling and propose a learning method—Self-Principled Critique Tuning (SPCT)—which helps GRMs generate adaptive principles and accurate critiques during online reinforcement learning. They apply parallel sampling and introduce a meta RM to scale effectively and refine the voting process. Their DeepSeek-GRM models outperform existing benchmark methods, offering higher reward quality and scalability, with plans for open-sourcing despite challenges in some complex tasks.

The researchers introduce SPCT, a method designed to enhance pointwise GRMs by enabling them to generate adaptive principles and accurate critiques. SPCT consists of two stages: rejective fine-tuning for initializing principle and critique generation and rule-based RL for refinement. Instead of treating principles as preprocessing, they are generated dynamically during inference. This promotes scalability by improving reward granularity. Additionally, inference-time performance is boosted through parallel sampling and voting, supported by a meta reward model (meta RM) that filters out low-quality outputs. Overall, SPCT improves reward accuracy, robustness, and scalability in GRMs.

Using standard metrics, the study evaluates various RM methods across benchmarks like Reward Bench, PPE, RMB, and ReaLMistake. DeepSeek-GRM-27B consistently outperforms baselines and rivals strong public models like GPT-4o. Inference-time scaling, especially with voting and meta reward models, significantly boosts performance—achieving results comparable to much larger models. Ablation studies highlight the importance of components like principle generation and non-hinted sampling. Training-time scaling shows diminishing returns compared to inference-time strategies. Overall, DeepSeek-GRM, enhanced with SPCT and meta RM, offers robust, scalable reward modeling with reduced domain bias and strong generalization.

In conclusion, the study presents SPCT, a method that improves inference-time scalability for GRMs through rule-based online reinforcement learning. SPCT enables adaptive principle and critique generation, enhancing reward quality across diverse tasks. DeepSeek-GRM models outperform several baselines and strong public models, especially when paired with a meta reward model for inference-time scaling. Using parallel sampling and flexible input handling, these GRMs achieve strong performance without relying on larger model sizes. Future work includes integrating GRMs into RL pipelines, co-scaling with policy models, and serving as reliable offline evaluators.


Check out the Paper. All credit for this research goes to the researchers of this project. Also, feel free to follow us on Twitter and don’t forget to join our 85k+ ML SubReddit.

🔥 [Register Now] miniCON Virtual Conference on OPEN SOURCE AI: FREE REGISTRATION + Certificate of Attendance + 3 Hour Short Event (April 12, 9 am- 12 pm PST) + Hands on Workshop [Sponsored]

Sana Hassan, a consulting intern at Marktechpost and dual-degree student at IIT Madras, is passionate about applying technology and AI to address real-world challenges. With a keen interest in solving practical problems, he brings a fresh perspective to the intersection of AI and real-life solutions.
Credit: Source link

ShareTweetSendSharePin

Related Posts

Microsoft’s New Surface Pro 12 And Surface Laptop 13 Feature Snapdragon X2 Plus Chips
AI & Technology

Microsoft’s New Surface Pro 12 And Surface Laptop 13 Feature Snapdragon X2 Plus Chips

September 23, 2026
Google Releases Gemini 3.8 Flash TTS and Flash-Lite TTS With Prompt-Based Voice Design
AI & Technology

Google Releases Gemini 3.8 Flash TTS and Flash-Lite TTS With Prompt-Based Voice Design

September 23, 2026
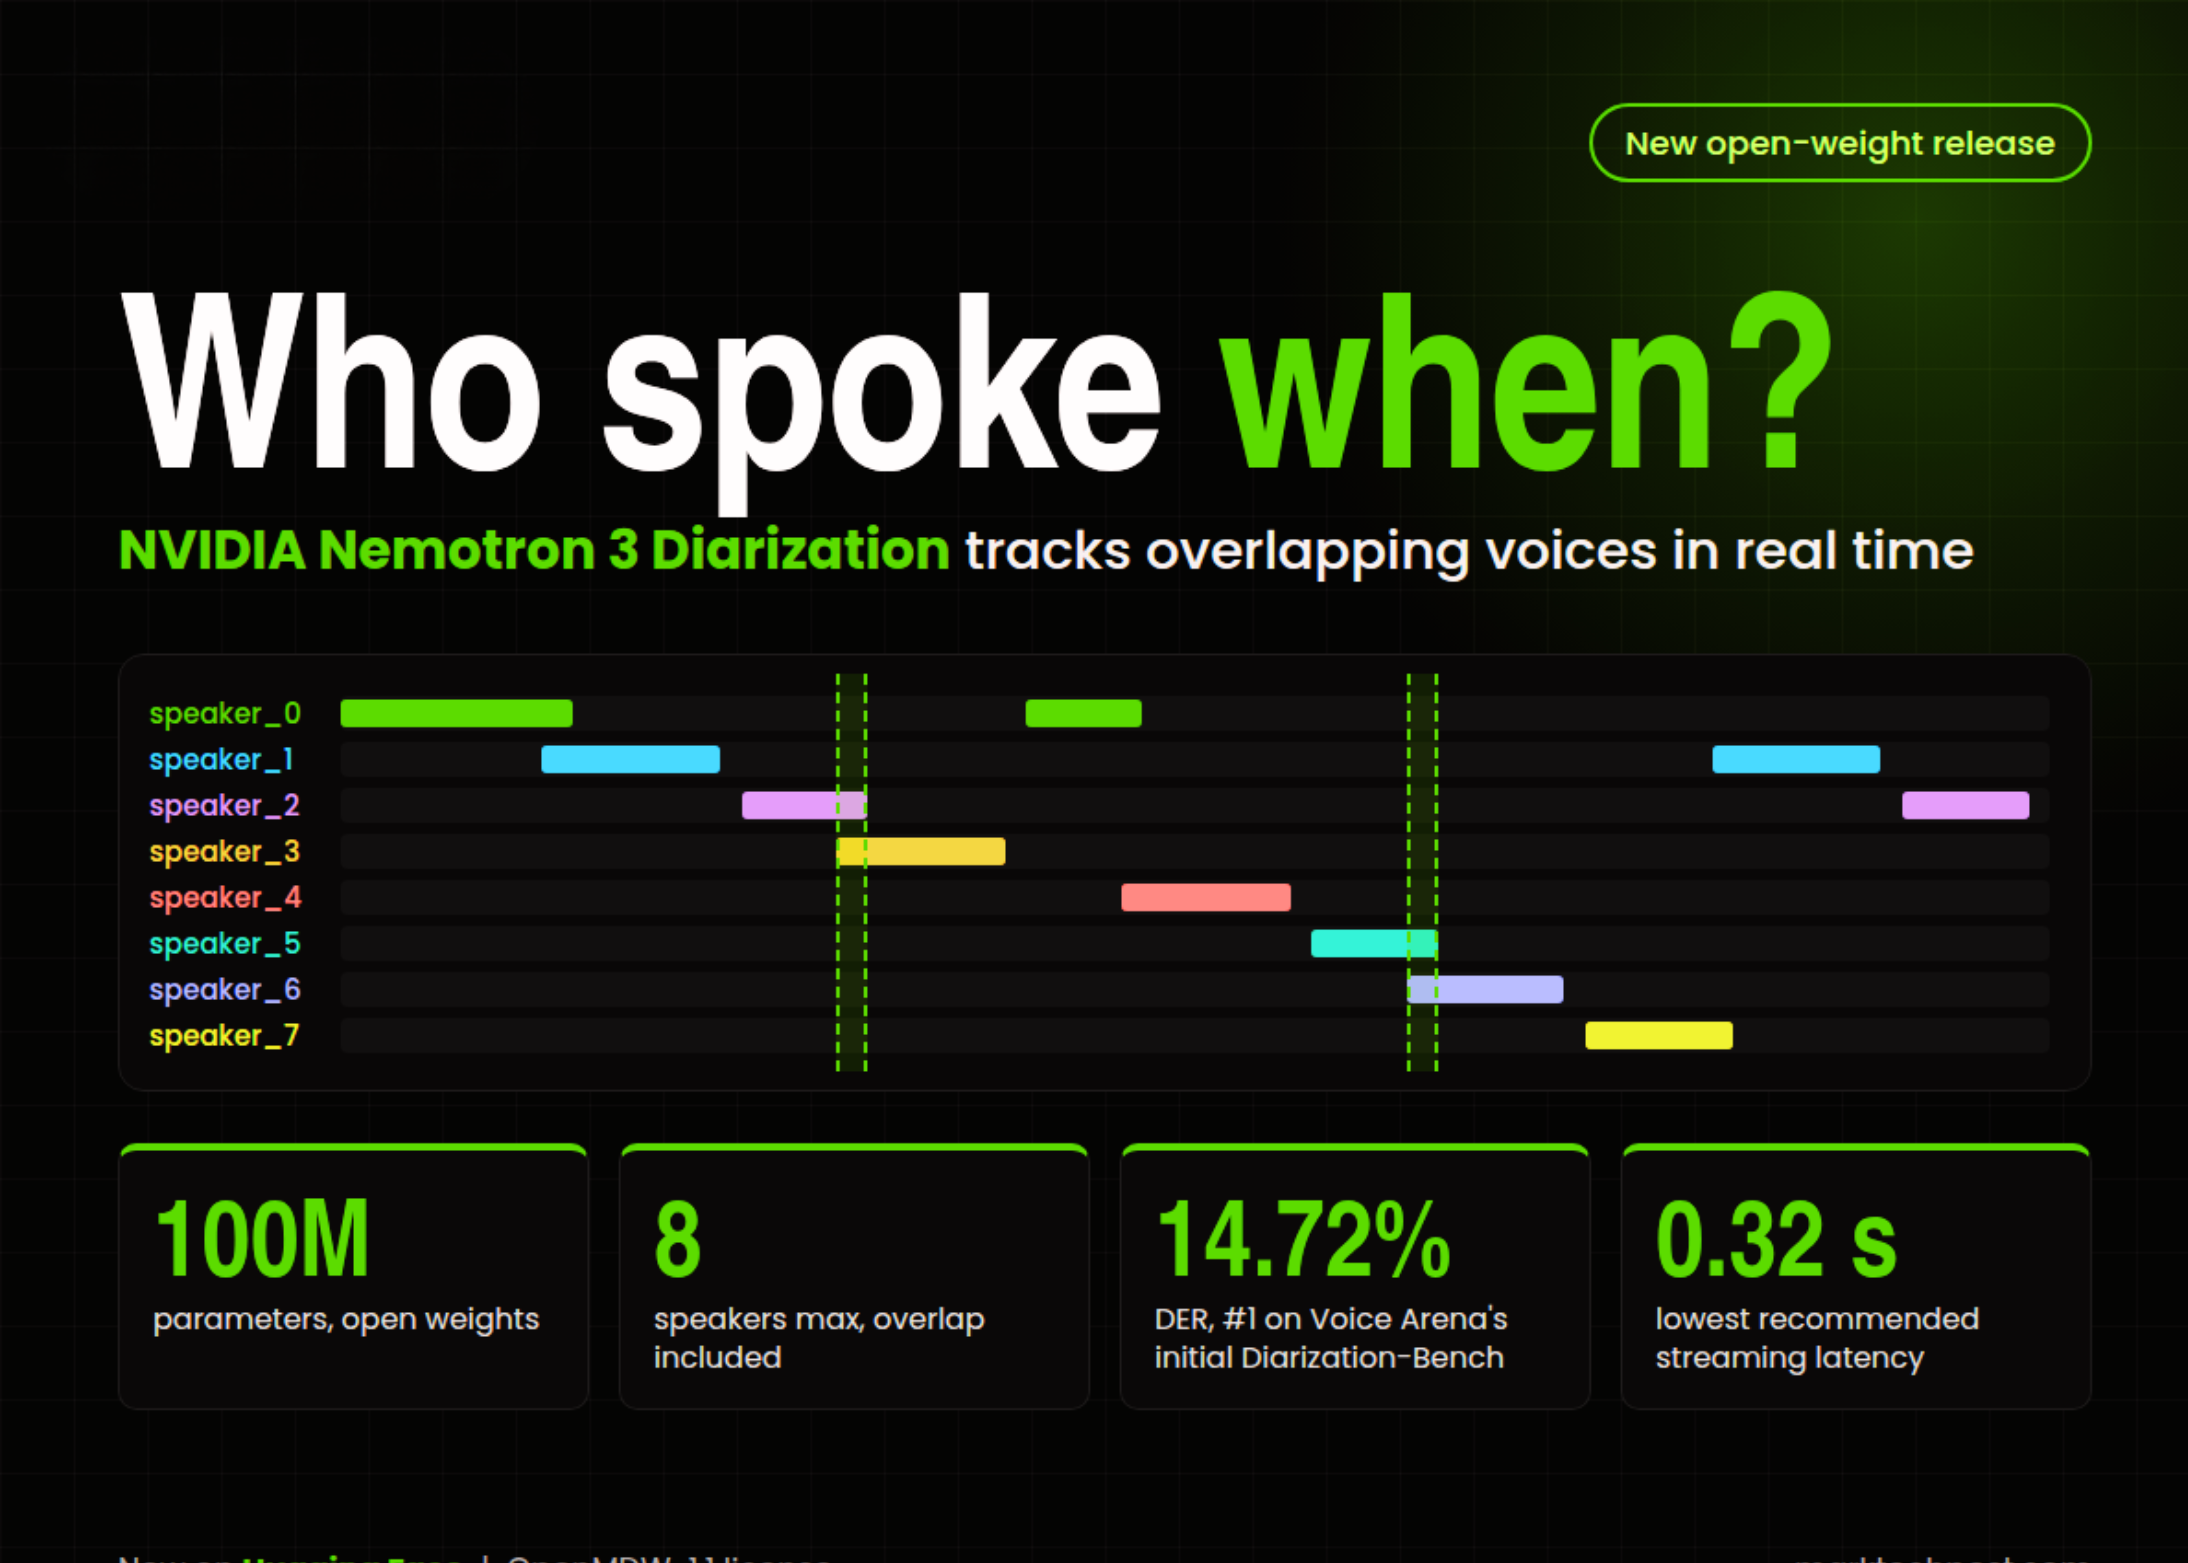
NVIDIA Releases Nemotron 3 Diarization: A 100M-Parameter Open-Weight Model That Tracks 8 Speakers in Real Time
AI & Technology

NVIDIA Releases Nemotron 3 Diarization: A 100M-Parameter Open-Weight Model That Tracks 8 Speakers in Real Time

September 23, 2026
Disney+ And Hulu Are Getting Even More Expensive (Again)
AI & Technology

Disney+ And Hulu Are Getting Even More Expensive (Again)

September 23, 2026
Next Post
NBC News’ Garrett Haake pushes back on White House claim that judge is a Democrat

NBC News' Garrett Haake pushes back on White House claim that judge is a Democrat

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Minneapolis mayor praises police officers in shooting

Minneapolis mayor praises police officers in shooting

September 18, 2026
JD Vance says U.S. is not at ‘war’ with Iran

JD Vance says U.S. is not at ‘war’ with Iran

September 18, 2026
Meta to pay  billion to settle child harm lawsuit

Meta to pay $18 billion to settle child harm lawsuit

September 23, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!