• bitcoinBitcoin(BTC)$84,329.00-2.53%
  • ethereumEthereum(ETH)$2,666.85-3.41%
  • tetherTether(USDT)$1.00-0.01%
  • binancecoinBNB(BNB)$766.42-2.92%
  • rippleXRP(XRP)$1.49-6.46%
  • usd-coinUSDC(USDC)$1.00-0.01%
  • solanaSolana(SOL)$114.28-3.48%
  • tronTRON(TRX)$0.340173-0.37%
  • zcashZcash(ZEC)$1,520.86-0.05%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.03-1.24%
  • HyperliquidHyperliquid(HYPE)$93.58-3.23%
  • dogecoinDogecoin(DOGE)$0.092100-8.26%
  • moneroMonero(XMR)$553.90-2.81%
  • whitebitWhiteBIT Coin(WBT)$84.53-2.78%
  • USDSUSDS(USDS)$1.00-0.02%
  • chainlinkChainlink(LINK)$12.23-6.49%
  • cardanoCardano(ADA)$0.237960-6.09%
  • RainRain(RAIN)$0.012243-6.79%
  • leo-tokenLEO Token(LEO)$8.95-0.15%
  • stellarStellar(XLM)$0.202019-7.04%
  • bitcoin-cashBitcoin Cash(BCH)$347.830.47%
  • nearNEAR Protocol(NEAR)$4.36-0.25%
  • uniswapUniswap(UNI)$9.16-0.99%
  • Ethena USDeEthena USDe(USDE)$1.00-0.01%
  • litecoinLitecoin(LTC)$60.85-3.31%
  • daiDai(DAI)$1.00-0.01%
  • avalanche-2Avalanche(AVAX)$10.29-6.95%
  • USD1USD1(USD1)$1.000.00%
  • CantonCanton(CC)$0.107969-5.11%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.41-3.50%
  • hedera-hashgraphHedera(HBAR)$0.090116-8.88%
  • suiSui(SUI)$0.96-4.96%
  • shiba-inuShiba Inu(SHIB)$0.000006-8.21%
  • BittensorBittensor(TAO)$289.45-6.68%
  • Global DollarGlobal Dollar(USDG)$1.00-0.01%
  • crypto-com-chainCronos(CRO)$0.061018-9.62%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.01%
  • MemeCoreMemeCore(M)$1.21-7.64%
  • BitwayBitway(BTW)$1.0015.14%
  • tether-goldTether Gold(XAUT)$4,287.58-1.61%
  • okbOKB(OKB)$117.73-4.13%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • Ripple USDRipple USD(RLUSD)$1.000.00%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.14-0.26%
  • mantleMantle(MNT)$0.65-2.50%
  • aaveAave(AAVE)$138.72-4.12%
  • EthenaEthena(ENA)$0.2083950.87%
  • OndoOndo(ONDO)$0.412046-5.54%
  • AsterAster(ASTER)$0.69-5.59%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Speech-to-Speech Foundation Models Pave the Way for Seamless Multilingual Interactions

March 18, 2025
in AI & Technology
Reading Time: 4 mins read
A A
Speech-to-Speech Foundation Models Pave the Way for Seamless Multilingual Interactions
ShareShareShareShareShare

At NVIDIA GTC25, Gnani.ai experts unveiled groundbreaking advancements in voice AI, focusing on the development and deployment of Speech-to-Speech Foundation Models. This innovative approach promises to overcome the limitations of traditional cascaded voice AI architectures, ushering in an era of seamless, multilingual, and emotionally aware voice interactions.

The Limitations of Cascaded Architectures

YOU MAY ALSO LIKE

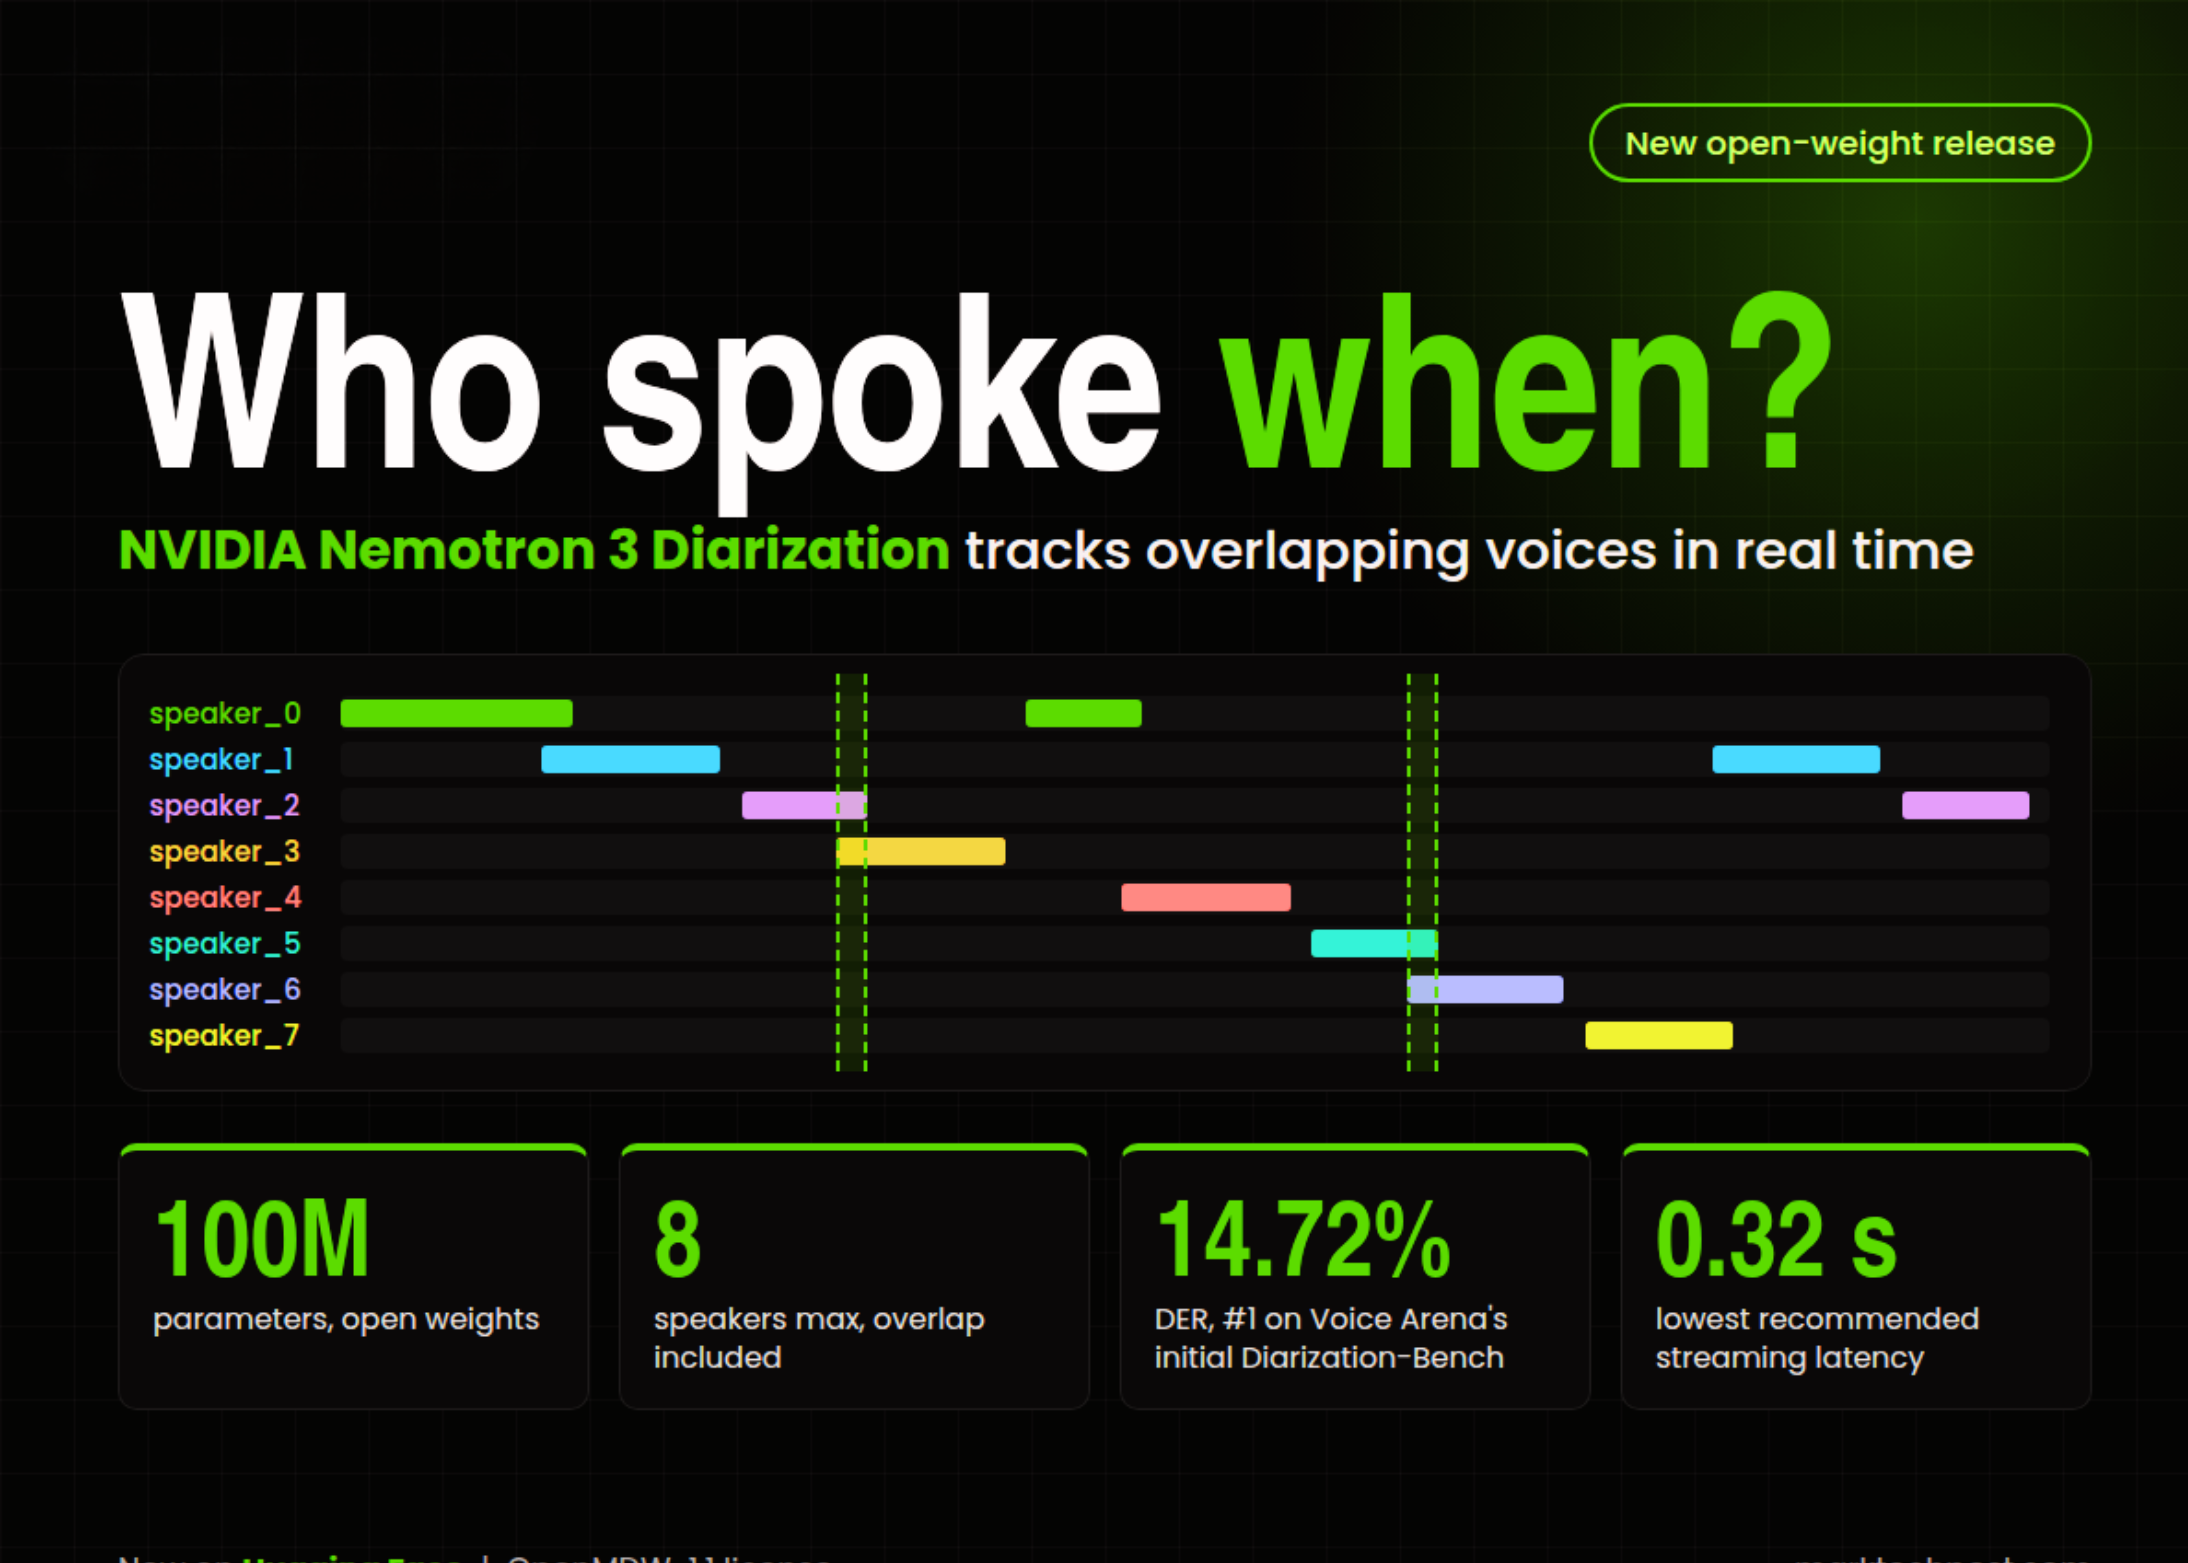
NVIDIA Releases Nemotron 3 Diarization: A 100M-Parameter Open-Weight Model That Tracks 8 Speakers in Real Time

Disney+ And Hulu Are Getting Even More Expensive (Again)

Current state-of-the-art architecture powering voice agents involves a three-stage pipeline: Speech-to-Text (STT), Large Language Models (LLMs), and Text-to-Speech (TTS). While effective, this cascaded architecture suffers from significant drawbacks, primarily latency and error propagation. A cascaded architecture has multiple blocks in the pipeline, and each block will add its own latency. The cumulative latency across these stages can range from 2.5 to 3 seconds, leading to a poor user experience. Moreover, errors introduced in the STT stage propagate through the pipeline, compounding inaccuracies. This traditional architecture also loses critical paralinguistic features such as sentiment, emotion, and tone, resulting in monotonous and emotionally flat responses.

Introducing Speech-to-Speech Foundation Models

To address these limitations, Gnani.ai presents a novel Speech-to-Speech Foundation Model. This model directly processes and generates audio, eliminating the need for intermediate text representations. The key innovation lies in training a massive audio encoder with 1.5 million hours of labeled data across 14 languages, capturing nuances of emotion, empathy, and tonality. This model employs a nested XL encoder, retrained with comprehensive data, and an input audio projector layer to map audio features into textual embeddings. For real-time streaming, audio and text features are interleaved, while non-streaming use cases utilize an embedding merge layer. The LLM layer, initially based on Llama 8B, was expanded to include 14 languages, necessitating the rebuilding of tokenizers. An output projector model generates mel spectrograms, enabling the creation of hyper-personalized voices.

Key Benefits and Technical Hurdles

The Speech-to-Speech model offers several significant benefits. Firstly, it significantly reduces latency, moving from 2 seconds to approximately 850-900 milliseconds for the first token output. Secondly, it enhances accuracy by fusing ASR with the LLM layer, improving performance, especially for short and long speeches. Thirdly, the model achieves emotional awareness by capturing and modeling tonality, stress, and rate of speech. Fourthly, it enables improved interruption handling through contextual awareness, facilitating more natural interactions. Finally, the model is designed to handle low bandwidth audio effectively, which is crucial for telephony networks. Building this model presented several challenges, notably the massive data requirements. The team created a crowd-sourced system with 4 million users to generate emotionally rich conversational data. They also leveraged foundation models for synthetic data generation and trained on 13.5 million hours of publicly available data. The final model comprises a 9 billion parameter model, with 636 million for the audio input, 8 billion for the LLM, and 300 million for the TTS system.

NVIDIA’s Role in Development

The development of this model was heavily reliant on the NVIDIA stack. NVIDIA Nemo was used for training encoder-decoder models, and NeMo Curator facilitated synthetic text data generation. NVIDIA EVA was employed to generate audio pairs, combining proprietary information with synthetic data.

Use Cases 

Gnani.ai showcased two primary use cases: real-time language translation and customer support. The real-time language translation demo featured an AI engine facilitating a conversation between an English-speaking agent and a French-speaking customer. The customer support demo highlighted the model’s ability to handle cross-lingual conversations, interruptions, and emotional nuances. 

Speech-to-Speech Foundation Model

The Speech-to-Speech Foundation Model represents a significant leap forward in voice AI. By eliminating the limitations of traditional architectures, this model enables more natural, efficient, and emotionally aware voice interactions. As the technology continues to evolve, it promises to transform various industries, from customer service to global communication.

Jean-marc is a successful AI business executive .He leads and accelerates growth for AI powered solutions and started a computer vision company in 2006. He is a recognized speaker at AI conferences and has an MBA from Stanford.

Credit: Source link

ShareTweetSendSharePin

Related Posts

NVIDIA Releases Nemotron 3 Diarization: A 100M-Parameter Open-Weight Model That Tracks 8 Speakers in Real Time
AI & Technology

NVIDIA Releases Nemotron 3 Diarization: A 100M-Parameter Open-Weight Model That Tracks 8 Speakers in Real Time

September 23, 2026
Disney+ And Hulu Are Getting Even More Expensive (Again)
AI & Technology

Disney+ And Hulu Are Getting Even More Expensive (Again)

September 23, 2026
Logitech’s Yeti 2 Brings The 17-Year-Old USB Mic Into The Modern Age
AI & Technology

Logitech’s Yeti 2 Brings The 17-Year-Old USB Mic Into The Modern Age

September 23, 2026
Never Use ChatGPT For These Five Tasks
AI & Technology

Never Use ChatGPT For These Five Tasks

September 23, 2026
Next Post
My 0% Interest Debt Is Coming Due (I Owe ,000)

My 0% Interest Debt Is Coming Due (I Owe $50,000)

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Millions under severe weather threat over Labor Day weekend

Millions under severe weather threat over Labor Day weekend

September 17, 2026
BREAKING: Judge declares mistrial in Lindsay Clancy trial

BREAKING: Judge declares mistrial in Lindsay Clancy trial

September 17, 2026
Toys ‘R’ Us to open 120 stores, biggest expansion in years — thanks to adults who ‘didn’t wanna grow up’

Toys ‘R’ Us to open 120 stores, biggest expansion in years — thanks to adults who ‘didn’t wanna grow up’

September 17, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!