• bitcoinBitcoin(BTC)$84,433.000.22%
  • ethereumEthereum(ETH)$2,678.22-0.33%
  • tetherTether(USDT)$1.000.00%
  • binancecoinBNB(BNB)$776.830.58%
  • rippleXRP(XRP)$1.51-0.48%
  • usd-coinUSDC(USDC)$1.000.00%
  • solanaSolana(SOL)$121.720.25%
  • tronTRON(TRX)$0.333398-0.28%
  • zcashZcash(ZEC)$1,592.02-4.19%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.063.17%
  • HyperliquidHyperliquid(HYPE)$91.44-0.58%
  • dogecoinDogecoin(DOGE)$0.096398-0.05%
  • chainlinkChainlink(LINK)$14.00-0.61%
  • moneroMonero(XMR)$549.55-1.15%
  • whitebitWhiteBIT Coin(WBT)$84.120.10%
  • USDSUSDS(USDS)$1.00-0.01%
  • cardanoCardano(ADA)$0.2538530.54%
  • RainRain(RAIN)$0.012568-2.47%
  • leo-tokenLEO Token(LEO)$9.050.91%
  • stellarStellar(XLM)$0.215048-0.68%
  • nearNEAR Protocol(NEAR)$5.429.29%
  • bitcoin-cashBitcoin Cash(BCH)$331.84-1.11%
  • uniswapUniswap(UNI)$9.64-0.79%
  • litecoinLitecoin(LTC)$70.92-1.29%
  • CantonCanton(CC)$0.136037-0.25%
  • suiSui(SUI)$1.268.74%
  • Ethena USDeEthena USDe(USDE)$1.000.02%
  • avalanche-2Avalanche(AVAX)$10.840.85%
  • daiDai(DAI)$1.00-0.01%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.632.69%
  • USD1USD1(USD1)$1.000.00%
  • hedera-hashgraphHedera(HBAR)$0.0943651.34%
  • BittensorBittensor(TAO)$324.071.63%
  • shiba-inuShiba Inu(SHIB)$0.000006-0.59%
  • quant-networkQuant(QNT)$230.0175.57%
  • BitwayBitway(BTW)$1.2219.00%
  • crypto-com-chainCronos(CRO)$0.066001-1.73%
  • Global DollarGlobal Dollar(USDG)$1.000.00%
  • EthenaEthena(ENA)$0.2765192.40%
  • paypal-usdPayPal USD(PYUSD)$1.000.00%
  • OndoOndo(ONDO)$0.564.23%
  • MemeCoreMemeCore(M)$1.19-2.88%
  • tether-goldTether Gold(XAUT)$4,266.72-0.30%
  • okbOKB(OKB)$121.200.37%
  • Ripple USDRipple USD(RLUSD)$1.000.02%
  • Circle USYCCircle USYC(USYC)$1.140.00%
  • aaveAave(AAVE)$154.37-0.34%
  • Pump.funPump.fun(PUMP)$0.00503915.22%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.09%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

LightThinker: Dynamic Compression of Intermediate Thoughts for More Efficient LLM Reasoning

March 2, 2025
in AI & Technology
Reading Time: 4 mins read
A A
LightThinker: Dynamic Compression of Intermediate Thoughts for More Efficient LLM Reasoning
ShareShareShareShareShare

Methods like Chain-of-Thought (CoT) prompting have enhanced reasoning by breaking complex problems into sequential sub-steps. More recent advances, such as o1-like thinking modes, introduce capabilities, including trial-and-error, backtracking, correction, and iteration, to improve model performance on difficult problems. However, these improvements come with substantial computational costs. The increased token generation creates significant memory overhead due to the Transformer architecture’s limitations, where attention mechanism complexity grows quadratically with context length, while KV Cache storage increases linearly. For instance, when Qwen32B’s context length reaches 10,000 tokens, the KV Cache consumes memory comparable to the entire model.

Current approaches to accelerate LLM inference fall into three main categories: Quantizing Model, Generating Fewer Tokens, and Reducing KV Cache. The quantizing model involves both parameter and KV Cache quantization techniques. Within the Reducing KV Cache category, pruning-based selection in discrete space and merging-based compression in continuous space emerge as key strategies. Pruning-based strategies implement specific eviction policies to retain only important tokens during inference. Merging-based strategies introduce anchor tokens that compress historically important information. The difference between these two methods is that Pruning-based methods are training-free but require applying eviction policies for every generated token, and Merging-based methods require model training.

YOU MAY ALSO LIKE

Bill Gates Says It’s ‘Completely Irresponsible’ For AI To Not Have Safeguards

Why The iPhone Duo Could Be Beneficial For Samsung’s Galaxy Z Fold 8

Researchers from Zhejiang University, Ant Group, and Zhejiang University – Ant Group Joint Laboratory of Knowledge Graph have proposed LightThinker to enable LLMs to compress intermediate thoughts during reasoning dynamically. Inspired by human cognition, LightThinker compresses verbose reasoning steps into compact representations and discards original reasoning chains, significantly reducing the number of tokens stored in the context window. The researchers also introduce the Dependency (Dep) metric to quantify compression effectiveness by measuring reliance on historical tokens during generation. Moreover, the LightThinker reduces peak memory usage and inference time while maintaining competitive accuracy, offering a promising direction for enhancing LLM efficiency in complex reasoning tasks.

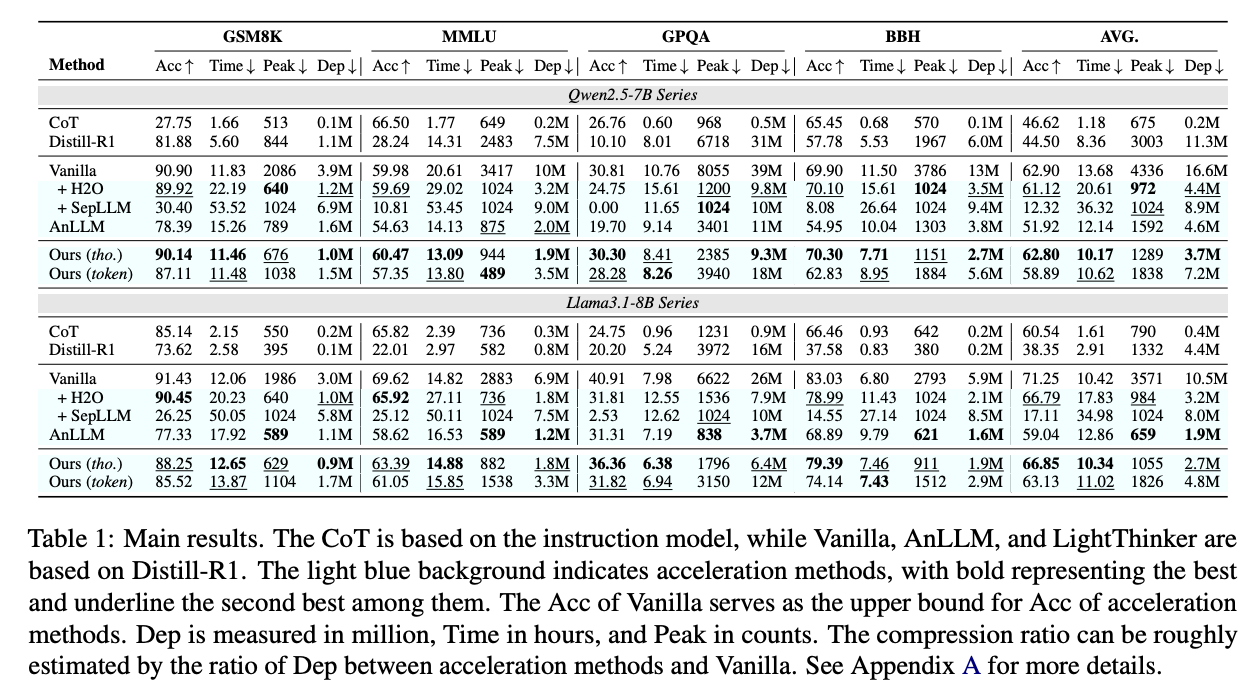
The LightThinker approach is evaluated using the Qwen2.5-7B and Llama3.1-8B models. The researchers conducted full parameter instruction tuning using the Bespoke-Stratos-17k dataset, with the resulting model designated as Vanilla. Five comparison baselines were implemented: two training-free acceleration methods (H2O and SepLLM), one training-based method (AnLLM), and CoT prompting applied to both instruction and R1-Distill models. Evaluation occurred across four datasets (GSM8K, MMLU, GPQA, and BBH), measuring effectiveness and efficiency (via inference time, peak token count, and dependency metrics). The implementation features two compression approaches: token-level compression (converting every 6 tokens into 2) and thought-level compression (using “\n\n” as a delimiter to segment thoughts).

Evaluation results across the four metrics for both models on all datasets reveal several significant findings. Distill-R1 consistently underperforms compared to CoT across all datasets, with the performance gap attributed to repetition issues caused by Greedy Decoding. H2O effectively preserves model performance while reducing memory usage, validating its greedy eviction policy for long-text generation. However, H2O substantially increases inference time (51% for Qwen and 72% for Llama) due to its token-wise eviction policy creating overhead for each generated token. Moreover, LightThinker matches H2O’s performance with similar compression rates while reducing inference time with a 52% reduction for Qwen and 41% for Llama.
In this paper, researchers introduced LightThinker, a novel approach to enhancing LLM efficiency in complex reasoning tasks through the dynamic compression of intermediate thoughts during generation. By training models to learn optimal timing and methods for compressing verbose reasoning steps into compact representations, LightThinker significantly reduces memory overhead and computational costs while maintaining competitive accuracy. However, several limitations remain: the compatibility with parameter-efficient fine-tuning methods like LoRA or QLoRA is unexplored, the potential benefits of larger training datasets are unknown, and performance degradation is notable on Llama series models when training on small datasets with next-token prediction.


Check out the Paper. All credit for this research goes to the researchers of this project. Also, feel free to follow us on Twitter and don’t forget to join our 80k+ ML SubReddit.

🚨 Recommended Read- LG AI Research Releases NEXUS: An Advanced System Integrating Agent AI System and Data Compliance Standards to Address Legal Concerns in AI Datasets

Sajjad Ansari is a final year undergraduate from IIT Kharagpur. As a Tech enthusiast, he delves into the practical applications of AI with a focus on understanding the impact of AI technologies and their real-world implications. He aims to articulate complex AI concepts in a clear and accessible manner.

🚨 Recommended Open-Source AI Platform: ‘IntellAgent is a An Open-Source Multi-Agent Framework to Evaluate Complex Conversational AI System’ (Promoted)

Credit: Source link

ShareTweetSendSharePin

Related Posts

Bill Gates Says It’s ‘Completely Irresponsible’ For AI To Not Have Safeguards
AI & Technology

Bill Gates Says It’s ‘Completely Irresponsible’ For AI To Not Have Safeguards

September 27, 2026
Why The iPhone Duo Could Be Beneficial For Samsung’s Galaxy Z Fold 8
AI & Technology

Why The iPhone Duo Could Be Beneficial For Samsung’s Galaxy Z Fold 8

September 27, 2026
How To Improve Your Router’s Security In 10 Minutes
AI & Technology

How To Improve Your Router’s Security In 10 Minutes

September 27, 2026
Humanoid Robots Are Getting Even Creepier (This One Can Cry On Command)
AI & Technology

Humanoid Robots Are Getting Even Creepier (This One Can Cry On Command)

September 27, 2026
Next Post
Tesla Faces Protesters, Vandals, Falling Sales

Tesla Faces Protesters, Vandals, Falling Sales

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
End-to-End Multimodal Data Augmentation and Adversarial Robustness Benchmark with AugLy for Images, Text, Audio, and PyTorch

End-to-End Multimodal Data Augmentation and Adversarial Robustness Benchmark with AugLy for Images, Text, Audio, and PyTorch

September 26, 2026
National Park Service conducts evacuations at Grand Canyon

National Park Service conducts evacuations at Grand Canyon

September 21, 2026
Desperate search for Nepal flood survivors enters critical new phase

Desperate search for Nepal flood survivors enters critical new phase

September 20, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!