Quantization is a crucial technique in deep learning for reducing computational costs and improving model efficiency. Large-scale language models demand significant processing power, which makes quantization essential for minimizing memory usage and enhancing inference speed. By converting high-precision weights to lower-bit formats such as int8, int4, or int2, quantization reduces storage requirements. However, standard techniques often degrade accuracy, especially at low precisions like int2. Researchers must compromise accuracy for efficiency or maintain multiple models with different quantization levels. New strategies are strongly needed to preserve model quality while optimizing computational efficiency.
The fundamental problem with quantization is handling precision reduction accurately. The approaches available so far either train unique models per precision or don’t take advantage of the integer data type’s hierarchical nature. Accuracy loss in quantization, as in the case of Int2, is most difficult because its memory gains hamper widespread utilization. LLMs like Gemma-2 9B and Mistral 7B are very computationally intensive, and a technique that enables a single model to operate on multiple precision levels would significantly improve efficiency. The necessity for a high-performance, flexible quantization method has prompted researchers to seek solutions outside of conventional methods.
Several quantization techniques exist, each balancing accuracy and efficiency. Learning-free methods like MinMax and GPTQ use statistical scaling to map model weights to lower bit widths without modifying parameters, but they lose accuracy at low precisions. Learning-based methods like Quantization Aware Training (QAT) and OmniQuant optimize quantization parameters using gradient descent. QAT updates model parameters to reduce post-quantization accuracy loss, while OmniQuant learns to scale and shift parameters without modifying core weights. However, both methods still require separate models for different precisions, complicating deployment.
Researchers at Google DeepMind introduced Matryoshka Quantization (MatQuant) to create a single model that functions across multiple precision levels. Unlike conventional methods that treat each bit-width separately, MatQuant optimizes a model for int8, int4, and int2 using a shared bit representation. This allows models to be deployed at different precisions without retraining, reducing computational and storage costs. MatQuant extracts lower-bit models from a high-bit model while preserving accuracy by leveraging the hierarchical structure of integer data types. Testing on Gemma-2 2B, Gemma-2 9B, and Mistral 7B models showed that MatQuant improves int2 accuracy by up to 10% over standard quantization techniques like QAT and OmniQuant.
MatQuant represents model weights at different precision levels using shared most significant bits (MSBs) and optimizes them jointly to maintain accuracy. The training process incorporates co-training and co-distillation, ensuring that the int2 representation retains critical information typically lost in conventional quantization. Instead of discarding lower-bit structures, MatQuant integrates them into a multi-scale optimization framework for efficient compression without performance loss.
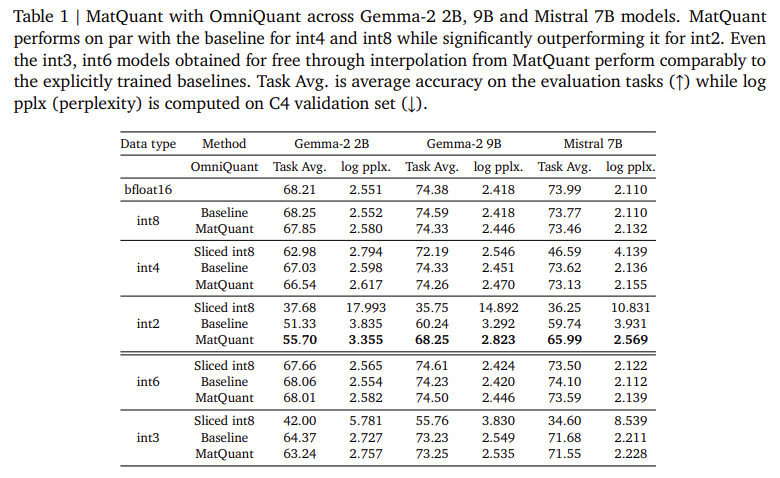
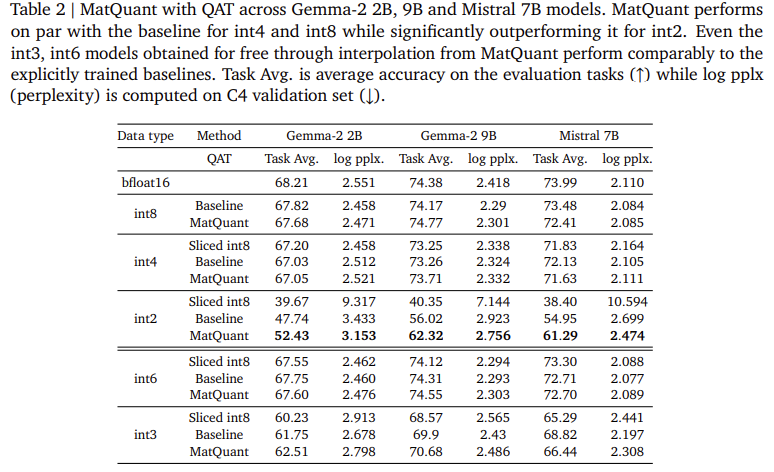
Experimental evaluations of MatQuant demonstrate its ability to mitigate accuracy loss from quantization. Researchers tested the method on Transformer-based LLMs, focusing on quantizing Feed-Forward Network (FFN) parameters, a key factor in inference latency. Results show that MatQuant’s int8 and int4 models achieve comparable accuracy to independently trained baselines while outperforming them at int2 precision. On the Gemma-2 9B model, MatQuant improved int2 accuracy by 8.01%, while the Mistral 7B model saw a 6.35% improvement over traditional quantization methods. The study also found that MatQuant’s right-shifted quantized weight distribution enhances accuracy across all bit-widths, particularly benefiting lower-precision models. Also, MatQuant enables seamless bit-width interpolation and layer-wise Mix’n’Match configurations, allowing flexible deployment based on hardware constraints.
Several Key Takeaways emerge from the Research on MatQuant:
- Multi-Scale Quantization: MatQuant introduces a novel approach to quantization by training a single model that can operate at multiple precision levels (e.g., int8, int4, int2).
- Nested Bit Structure Exploitation: The technique leverages the inherent nested structure within integer data types, allowing smaller bit-width integers to be derived from larger ones.
- Enhanced Low-Precision Accuracy: MatQuant significantly improves the accuracy of int2 quantized models, outperforming traditional quantization methods like QAT and OmniQuant by up to 8%.
- Versatile Application: MatQuant is compatible with existing learning-based quantization techniques such as Quantization Aware Training (QAT) and OmniQuant.
- Demonstrated Performance: The method was successfully applied to quantize the FFN parameters of LLMs like Gemma-2 2B, 9B, and Mistral 7B, showcasing its practical utility.
- Efficiency Gains: MatQuant enables the creation of models that offer a better trade-off between accuracy and computational cost, making it ideal for resource-constrained environments.
- Pareto-Optimal Trade-Offs: It allows for seamless extraction of interpolative bit-widths, such as int6 and int3, and admits a dense accuracy-vs-cost Pareto-optimal trade-off by enabling layer-wise Mix’n’Match of different precisions.
In conclusion, MatQuant presents a solution to managing multiple quantized models by utilizing a multi-scale training approach that exploits the nested structure of integer data types. This provides a flexible, high-performance option for low-bit quantization in efficient LLM inference. This research demonstrates that a single model can be trained to operate at multiple precision levels without significantly declining accuracy, particularly at very low bit widths, marking an important advancement in model quantization techniques.
Check out the Paper. All credit for this research goes to the researchers of this project. Also, feel free to follow us on Twitter and don’t forget to join our 75k+ ML SubReddit.
🚨 Recommended Open-Source AI Platform: ‘IntellAgent is a An Open-Source Multi-Agent Framework to Evaluate Complex Conversational AI System’ (Promoted)

Asif Razzaq is the CEO of Marktechpost Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.
Credit: Source link