• bitcoinBitcoin(BTC)$84,126.000.21%
  • ethereumEthereum(ETH)$2,691.70-0.02%
  • tetherTether(USDT)$1.000.00%
  • binancecoinBNB(BNB)$773.97-0.17%
  • rippleXRP(XRP)$1.55-1.86%
  • usd-coinUSDC(USDC)$1.000.00%
  • solanaSolana(SOL)$121.801.09%
  • tronTRON(TRX)$0.3366560.03%
  • zcashZcash(ZEC)$1,550.930.08%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.02-0.38%
  • HyperliquidHyperliquid(HYPE)$92.501.58%
  • dogecoinDogecoin(DOGE)$0.0985530.77%
  • chainlinkChainlink(LINK)$14.242.64%
  • moneroMonero(XMR)$554.11-0.33%
  • whitebitWhiteBIT Coin(WBT)$83.890.11%
  • cardanoCardano(ADA)$0.2599521.97%
  • USDSUSDS(USDS)$1.000.00%
  • RainRain(RAIN)$0.0127988.06%
  • leo-tokenLEO Token(LEO)$8.981.76%
  • stellarStellar(XLM)$0.2201030.53%
  • bitcoin-cashBitcoin Cash(BCH)$335.820.48%
  • nearNEAR Protocol(NEAR)$4.85-5.47%
  • uniswapUniswap(UNI)$9.710.99%
  • litecoinLitecoin(LTC)$72.953.85%
  • CantonCanton(CC)$0.13760110.73%
  • Ethena USDeEthena USDe(USDE)$1.00-0.02%
  • avalanche-2Avalanche(AVAX)$10.975.71%
  • suiSui(SUI)$1.186.73%
  • daiDai(DAI)$1.000.00%
  • USD1USD1(USD1)$1.000.00%
  • hedera-hashgraphHedera(HBAR)$0.0952091.70%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.484.35%
  • BittensorBittensor(TAO)$337.6411.09%
  • shiba-inuShiba Inu(SHIB)$0.0000062.82%
  • crypto-com-chainCronos(CRO)$0.0659420.18%
  • Global DollarGlobal Dollar(USDG)$1.000.00%
  • BitwayBitway(BTW)$1.06-14.48%
  • MemeCoreMemeCore(M)$1.223.97%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.01%
  • EthenaEthena(ENA)$0.2737808.14%
  • tether-goldTether Gold(XAUT)$4,279.34-0.22%
  • OndoOndo(ONDO)$0.551.79%
  • okbOKB(OKB)$121.951.66%
  • Ripple USDRipple USD(RLUSD)$1.00-0.01%
  • Circle USYCCircle USYC(USYC)$1.140.00%
  • aaveAave(AAVE)$154.873.64%
  • mantleMantle(MNT)$0.705.35%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.15-0.08%
  • polkadotPolkadot(DOT)$1.298.69%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

UC Berkeley Researchers Explore the Role of Task Vectors in Vision-Language Models

December 8, 2024
in AI & Technology
Reading Time: 6 mins read
A A
UC Berkeley Researchers Explore the Role of Task Vectors in Vision-Language Models
ShareShareShareShareShare

Vision-and-language models (VLMs) are important tools that use text to handle different computer vision tasks. Tasks like recognizing images, reading text from images (OCR), and detecting objects can be approached as answering visual questions with text responses. While VLMs have shown limited success on tasks, what remains unclear is how they process and represent multimodal inputs like images and text to produce those answers, which raises doubts about the kind of representations that enable them to achieve such tasks.

The current methods in vision-and-language models treat tasks as either text-based or image-based, focusing on one input type at a time. This misses the deeper possibilities of combining information from images and text. In-context learning (ICL), a feature of large language models (LLMs), allows models to adapt to tasks with minimal examples, driven by mechanisms like attention heads or task vectors that encode tasks as latent activations. Vision-and-language models (VLMs), inspired by LLMs, combine visual and text data using either late-fusion (pre-trained components) or early-fusion (end-to-end training) methods. Studies revealed that task representations can transfer across modalities, and even VLMs without image ICL can use task vectors for better performance, highlighting similarities between image and text ICL processes. Combining image and text input can allow VLMs to perform complex tasks more effectively.

YOU MAY ALSO LIKE

This App Lets You Use An Apple Watch With An Android Phone

These Xbox Players Got GTA 6 For Free The Hard Way

To solve this, researchers from the University of California, Berkeley, experimented to analyze how task vectors are encoded and transferred in VLMs. Researchers found that VLMs map inputs into a shared task representation space, regardless of whether text examples, image examples, or explicit instructions define the task. 

Researchers created six tasks to test whether VLMs behave similarly to task vectors and see how well task vectors could transfer across different modalities, using text, images, or direct instructions to define them. These vectors were then applied in cross-modal scenarios, like using text examples to define tasks but querying with images. Analyzing how token representations changed in VLMs showed a three-phase process: encoding input, forming a task representation, and generating outputs. The decoding of task vectors often summarized the task concept and aligned text and image modalities, although image-based tasks were less clear. 

The study evaluated the cross-modal transfer performance of task vectors from text and image in-context learning (ICL), revealing significant improvements. Cross-modal patching (xPatch) surpassed same-context examples (xBase), boosting accuracy by 14–33% over text ICL xBase and 8–13% over image ICL Patch. Text-based task vectors proved more efficient than the image-based ones, as those involved extra recognition steps. Adding instruction-based and exemplar-based task vectors into a single vector improves task representation, reducing variance and increasing efficiency by 18%. Cross-modal transfer from text to image results were as high as 37–52% accuracy compared with the baselines. LLM-to-VLM transfers exhibited a high similarity in the task vectors (cosine similarity: 0.89–0.95). Thus, the results highlighted cross-modal patching and vector integration as key to optimizing task performance.


In summary, VLMs can effectively encode and transfer task representations across different modalities, which shows potential for achieving more versatile and efficient multi-modal models. Researchers attempted possible explanations, such as shared structures between language and perception or the models learning from the same underlying reality. They found better performance in transferring tasks from text to images than from images to text, likely because VLM training focuses more on text. Thus, this work can be a future baseline for further research and innovation!


Check out the Paper and Project. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter and join our Telegram Channel and LinkedIn Group. If you like our work, you will love our newsletter.. Don’t Forget to join our 60k+ ML SubReddit.

🚨 [Must Attend Webinar]: ‘Transform proofs-of-concept into production-ready AI applications and agents’ (Promoted)

Divyesh is a consulting intern at Marktechpost. He is pursuing a BTech in Agricultural and Food Engineering from the Indian Institute of Technology, Kharagpur. He is a Data Science and Machine learning enthusiast who wants to integrate these leading technologies into the agricultural domain and solve challenges.

🚨🚨FREE AI WEBINAR: ‘Fast-Track Your LLM Apps with deepset & Haystack'(Promoted)


Credit: Source link

ShareTweetSendSharePin

Related Posts

This App Lets You Use An Apple Watch With An Android Phone
AI & Technology

This App Lets You Use An Apple Watch With An Android Phone

September 26, 2026
These Xbox Players Got GTA 6 For Free The Hard Way
AI & Technology

These Xbox Players Got GTA 6 For Free The Hard Way

September 26, 2026
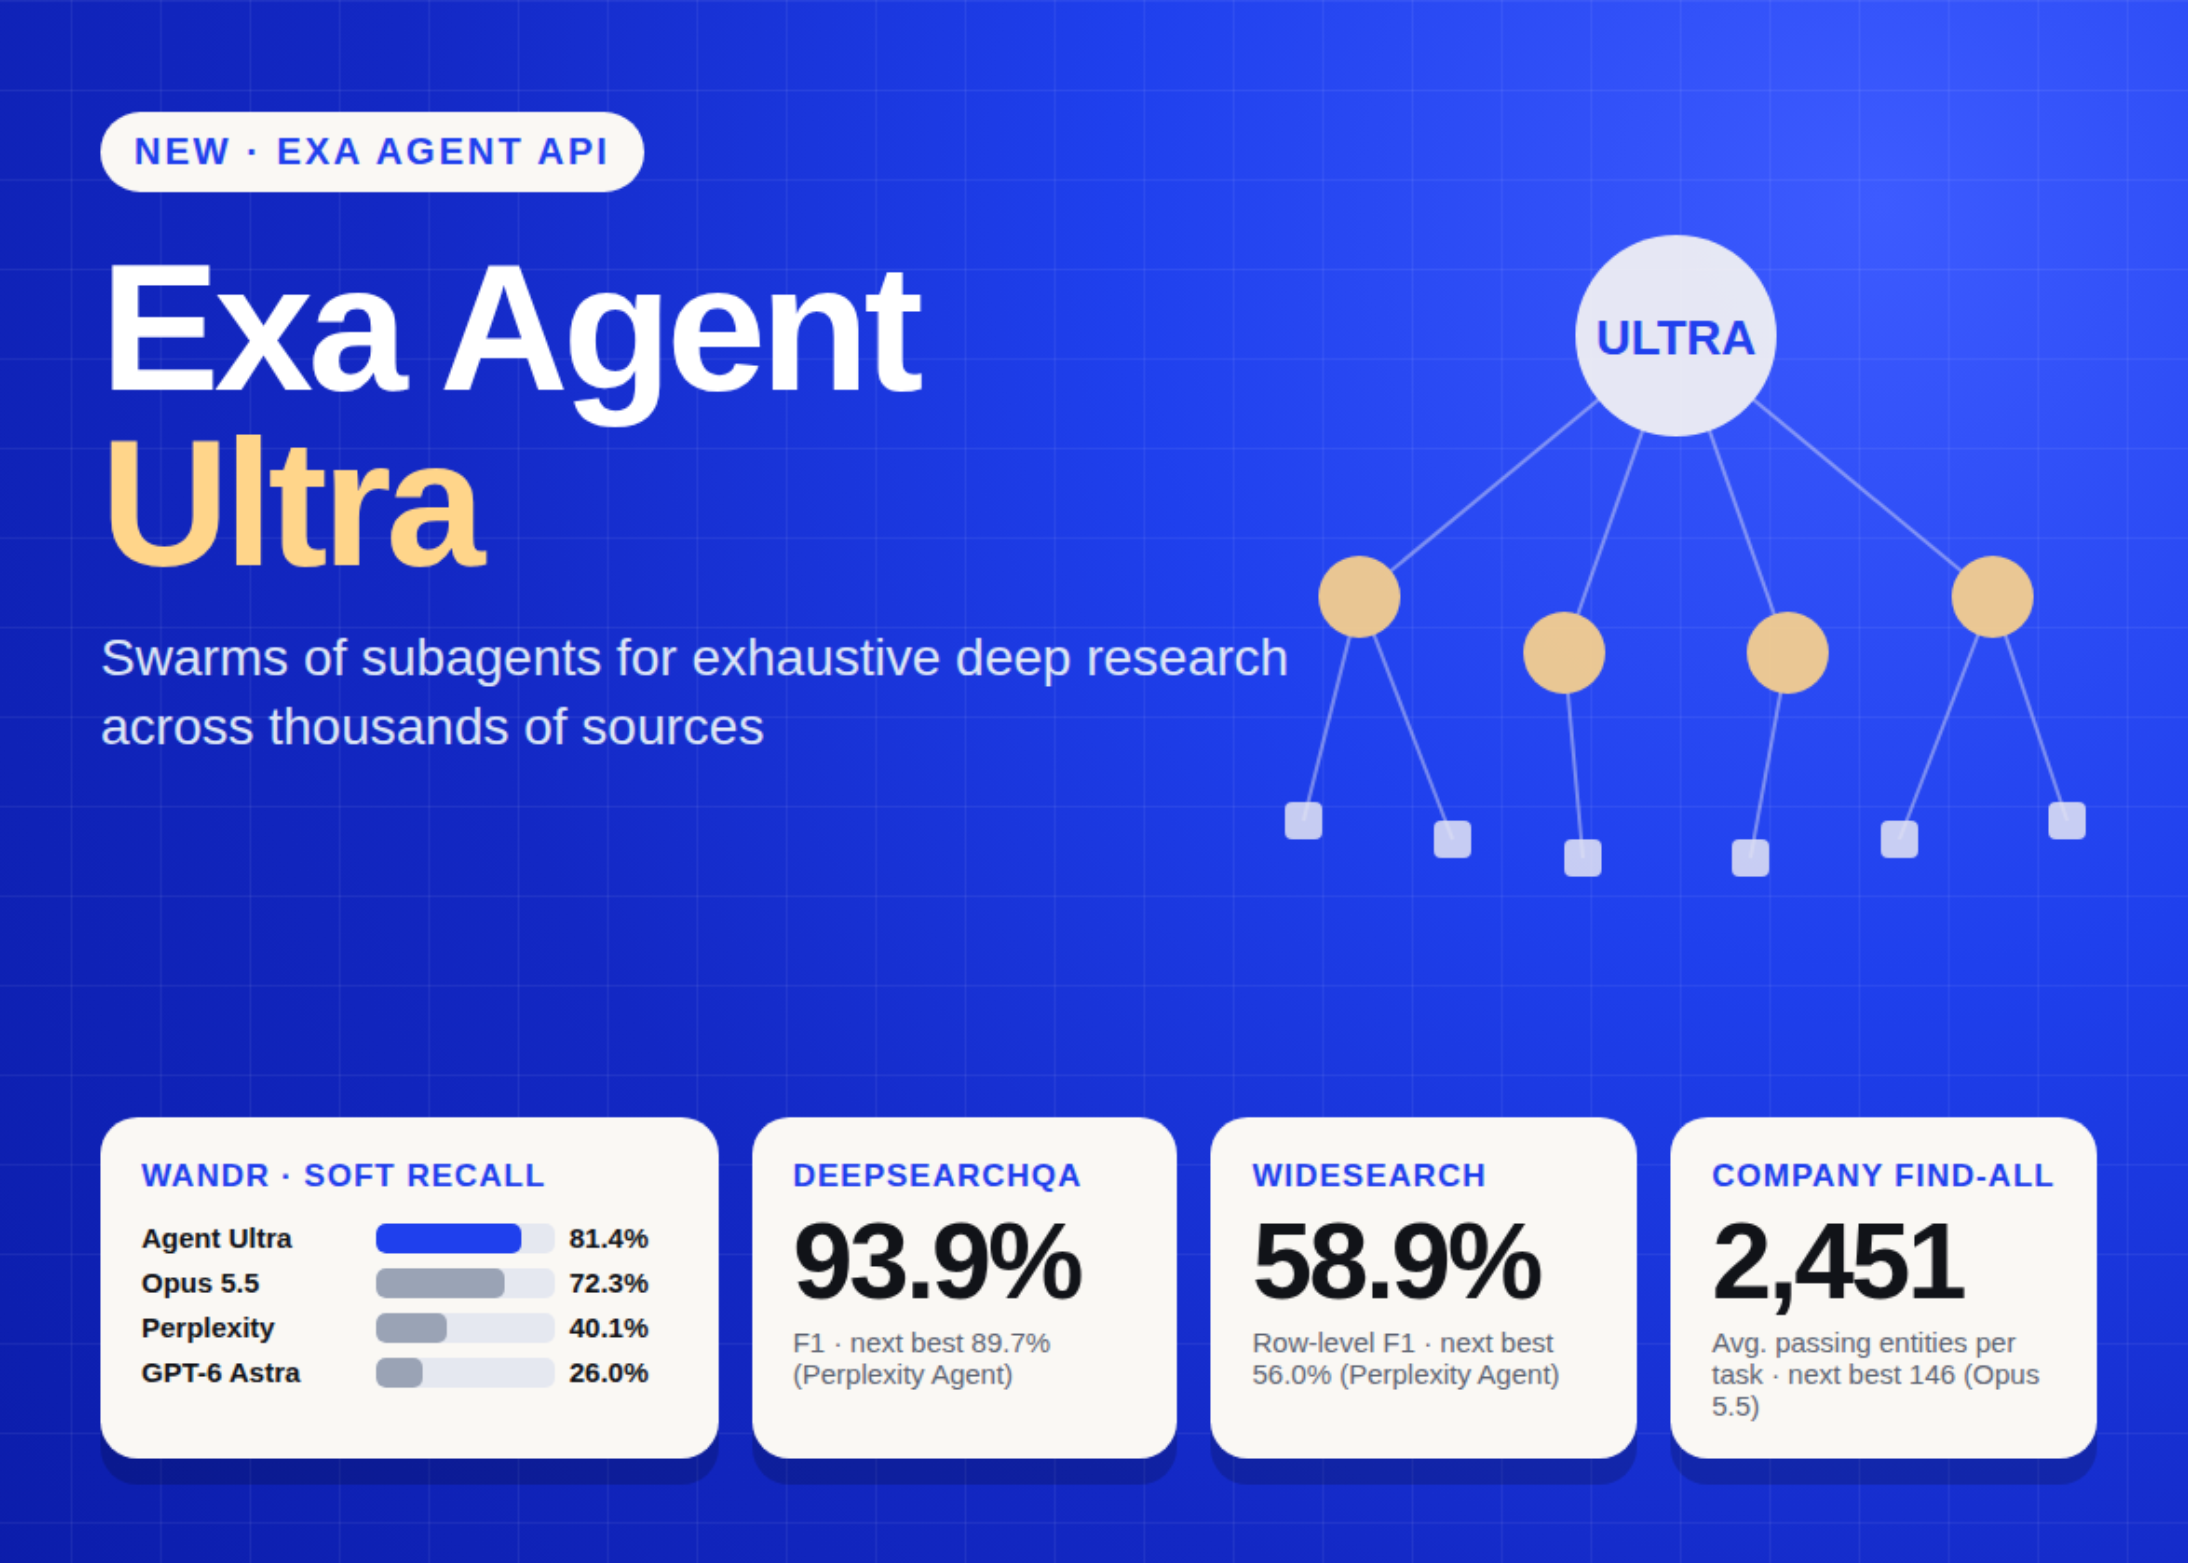
Exa Launches Agent Ultra: A Subagent Swarm Deep Research API Built for Exhaustive List Building
AI & Technology

Exa Launches Agent Ultra: A Subagent Swarm Deep Research API Built for Exhaustive List Building

September 26, 2026
End-to-End Multimodal Data Augmentation and Adversarial Robustness Benchmark with AugLy for Images, Text, Audio, and PyTorch
AI & Technology

End-to-End Multimodal Data Augmentation and Adversarial Robustness Benchmark with AugLy for Images, Text, Audio, and PyTorch

September 26, 2026
Next Post
Alone against a renewed insurgency, Assad may face the end of his rule without his strongest allies – The Associated Press

Alone against a renewed insurgency, Assad may face the end of his rule without his strongest allies - The Associated Press

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Nicolas Cage Is Anything But Subtle In The Madden Trailer

Nicolas Cage Is Anything But Subtle In The Madden Trailer

September 24, 2026
Steve Kornacki previews generational change fights in Massachusetts primary

Steve Kornacki previews generational change fights in Massachusetts primary

September 20, 2026
Korn Ferry (KFY) Presents at William Blair Human Capital Services Virtual Conference – Slideshow

Korn Ferry (KFY) Presents at William Blair Human Capital Services Virtual Conference – Slideshow

September 19, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!