• bitcoinBitcoin(BTC)$84,110.00-2.76%
  • ethereumEthereum(ETH)$2,686.74-2.60%
  • tetherTether(USDT)$1.000.00%
  • binancecoinBNB(BNB)$772.25-2.45%
  • rippleXRP(XRP)$1.50-7.11%
  • usd-coinUSDC(USDC)$1.000.00%
  • solanaSolana(SOL)$115.05-3.14%
  • tronTRON(TRX)$0.343232-0.20%
  • zcashZcash(ZEC)$1,525.45-5.47%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.040.37%
  • HyperliquidHyperliquid(HYPE)$92.86-4.81%
  • dogecoinDogecoin(DOGE)$0.094307-7.50%
  • moneroMonero(XMR)$556.66-2.54%
  • whitebitWhiteBIT Coin(WBT)$84.51-2.79%
  • USDSUSDS(USDS)$1.00-0.01%
  • chainlinkChainlink(LINK)$12.39-5.20%
  • cardanoCardano(ADA)$0.240524-7.13%
  • RainRain(RAIN)$0.012175-7.17%
  • leo-tokenLEO Token(LEO)$8.95-0.31%
  • stellarStellar(XLM)$0.202852-7.84%
  • bitcoin-cashBitcoin Cash(BCH)$338.54-5.36%
  • uniswapUniswap(UNI)$9.29-10.46%
  • nearNEAR Protocol(NEAR)$4.28-5.03%
  • litecoinLitecoin(LTC)$67.565.40%
  • Ethena USDeEthena USDe(USDE)$1.00-0.02%
  • daiDai(DAI)$1.00-0.01%
  • avalanche-2Avalanche(AVAX)$10.25-8.67%
  • USD1USD1(USD1)$1.000.00%
  • CantonCanton(CC)$0.108787-6.14%
  • hedera-hashgraphHedera(HBAR)$0.091647-7.82%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.43-2.95%
  • suiSui(SUI)$0.96-6.74%
  • shiba-inuShiba Inu(SHIB)$0.000006-7.29%
  • BittensorBittensor(TAO)$289.39-8.21%
  • Global DollarGlobal Dollar(USDG)$1.00-0.01%
  • crypto-com-chainCronos(CRO)$0.062319-8.38%
  • BitwayBitway(BTW)$1.0714.83%
  • MemeCoreMemeCore(M)$1.26-3.38%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.01%
  • tether-goldTether Gold(XAUT)$4,283.41-1.05%
  • okbOKB(OKB)$120.10-4.29%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • Ripple USDRipple USD(RLUSD)$1.000.00%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.14-0.21%
  • mantleMantle(MNT)$0.66-4.19%
  • aaveAave(AAVE)$139.46-8.02%
  • EthenaEthena(ENA)$0.210630-4.14%
  • OndoOndo(ONDO)$0.431959-2.12%
  • polkadotPolkadot(DOT)$1.12-5.76%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

AMPLIFY: Leveraging Data Quality Over Scale for Efficient Protein Language Model Development

September 30, 2024
in AI & Technology
Reading Time: 4 mins read
A A
AMPLIFY: Leveraging Data Quality Over Scale for Efficient Protein Language Model Development
ShareShareShareShareShare

Protein language models (pLMs), trained on protein sequence databases, aim to capture the fitness landscape for property prediction and design tasks. While scaling these models has become common, it assumes that the source databases accurately reflect the fitness landscape, which may not be true. Understanding protein function was historically tied to predicting structure based on physical models. However, as machine learning techniques evolved, they have proven more effective in modeling dynamic protein behaviors. By treating protein sequences like natural language, pLMs can capture structural insights without relying solely on structure databases, revealing deeper functional relationships.

Researchers from Chandar Lab, Mila, and Amgen developed AMPLIFY, an efficient pLM that significantly reduces the cost of training and deployment compared to previous models. Unlike large-scale models like ESM2 and ProGen2, AMPLIFY focuses on improving data quality rather than model size, achieving superior performance with 43 times fewer parameters. The team evaluated three strategies—data quality, quantity, and training steps—finding that improving data quality alone can create state-of-the-art models. AMPLIFY has been open-sourced, including its codebase, data, and models, to make pLM development more accessible.

YOU MAY ALSO LIKE

Contrastive-LM Releases CLM-8B: An Open System One Model That Scores Agent Actions Up to 9× Faster Than Jev

A Coding Guide to TypeSafe AI Jev: Typed Decisions, Calibrated Confidence, and Speculative Fan-Out with a System One Model

The validation data sequence sets for the pLM were created by combining reference proteome sequences with sequences from the Observed Antibody Space (OAS) and the Structural Classification of Proteins (SCOP) database. The aim was to enable task-specific validation, particularly for complementarity-determining regions of antibody sequences and sequence-to-structure tasks. High-quality reference proteomes were selected based on their BUSCO completeness scores, ensuring representation across Bacteria, Archaea, and Eukarya. Sequences lacking experimental validation or containing non-canonical amino acids were excluded. The final validation sets included 10,000 randomly selected sequences from each source after clustering to reduce redundancy.

For training data, the UniRef, OAS, SCOP, and UniProt databases were processed to remove sequences with ambiguous amino acids and those similar to validation set sequences. The training dataset specifically utilized paired heavy and light chain antibody sequences formatted with a chain break token. The AMPLIFY model architecture incorporated recent improvements from large language models in natural language processing, including a SwiGLU activation function and a memory-efficient attention mechanism. The optimization process involved enhanced AdamW and a cosine annealing scheduler, with training conducted at lower precision using advanced techniques like DeepSpeed. The vocabulary was streamlined to accommodate better multi-chain proteins, and sequences longer than 512 residues were truncated during training to improve efficiency. After initial training, the context length was expanded to 2048 residues, followed by additional training steps for both AMPLIFY models.

The study compared the impact of adjusting pLM size with factors like training dataset content, size, and duration. The authors improved their validation dataset by using sequences from UniRef100, antibody pairs from OAS, and SCOP domains, aiming for a more representative sample. They found that data curation significantly enhances model performance, independent of model size or training duration. Contrary to previous findings, they observed that performance improved beyond 500K updates, suggesting that using diverse training data is crucial. Additionally, larger models risk overfitting, indicating the need for regular retraining to adapt to evolving data quality and quantity.

Recent advancements in ML have focused on scaling neural networks, particularly in language models for text and proteins. This trend has made training state-of-the-art models prohibitively expensive for many researchers, often leading to restricted access. However, this study suggests that expertise from protein scientists can enhance the curation process, yielding competitive performance without the need for a massive scale. Effective curation relies on a community-wide understanding of proteins, which remains limited. The study emphasizes the importance of collaborative expertise and advocates for open-source methods to facilitate iterative data curation and model development, ultimately aiding therapeutic advancements.


Check out the Paper and GitHub. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter and join our Telegram Channel and LinkedIn Group. If you like our work, you will love our newsletter..

Don’t Forget to join our 52k+ ML SubReddit.

We are inviting startups, companies, and research institutions who are working on small language models to participate in this upcoming ‘Small Language Models’ Magazine/Report by Marketchpost.com. This Magazine/Report will be released in late October/early November 2024. Click here to set up a call!

Sana Hassan, a consulting intern at Marktechpost and dual-degree student at IIT Madras, is passionate about applying technology and AI to address real-world challenges. With a keen interest in solving practical problems, he brings a fresh perspective to the intersection of AI and real-life solutions.


Credit: Source link

ShareTweetSendSharePin

Related Posts

Contrastive-LM Releases CLM-8B: An Open System One Model That Scores Agent Actions Up to 9× Faster Than Jev
AI & Technology

Contrastive-LM Releases CLM-8B: An Open System One Model That Scores Agent Actions Up to 9× Faster Than Jev

September 24, 2026
A Coding Guide to TypeSafe AI Jev: Typed Decisions, Calibrated Confidence, and Speculative Fan-Out with a System One Model
AI & Technology

A Coding Guide to TypeSafe AI Jev: Typed Decisions, Calibrated Confidence, and Speculative Fan-Out with a System One Model

September 24, 2026
Everything Announced At Meta Connect 2026
AI & Technology

Everything Announced At Meta Connect 2026

September 24, 2026
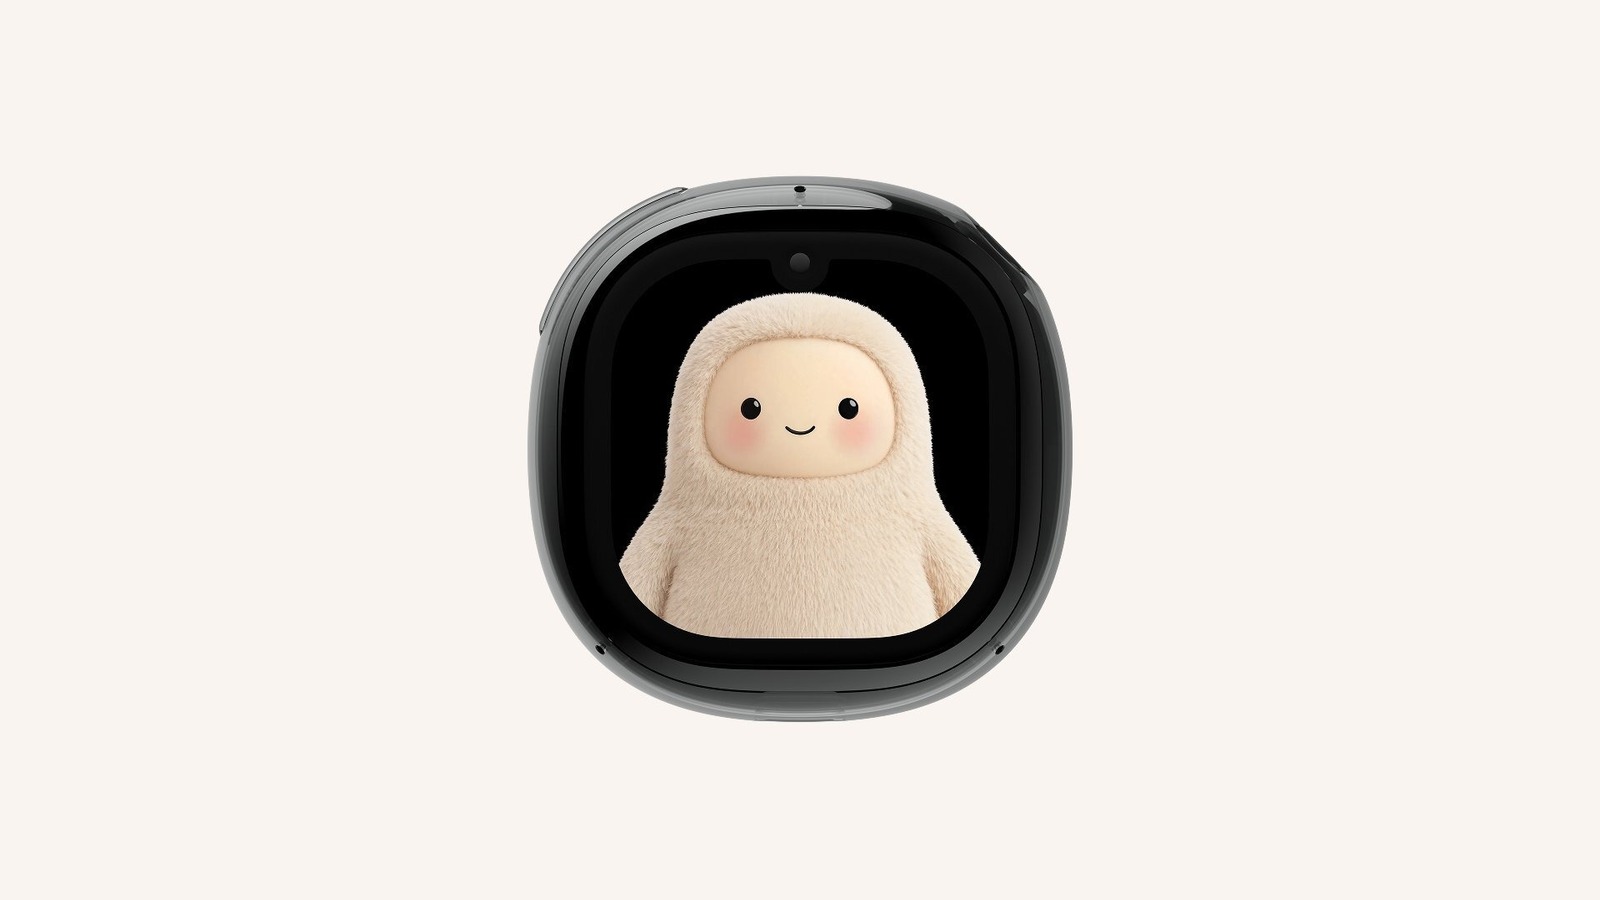
Meta Put Muse In A Tamagotchi Like ‘Charm’ Device
AI & Technology

Meta Put Muse In A Tamagotchi Like ‘Charm’ Device

September 24, 2026
Next Post
Apple Tax Boon to Go Toward Housing, Energy

Apple Tax Boon to Go Toward Housing, Energy

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
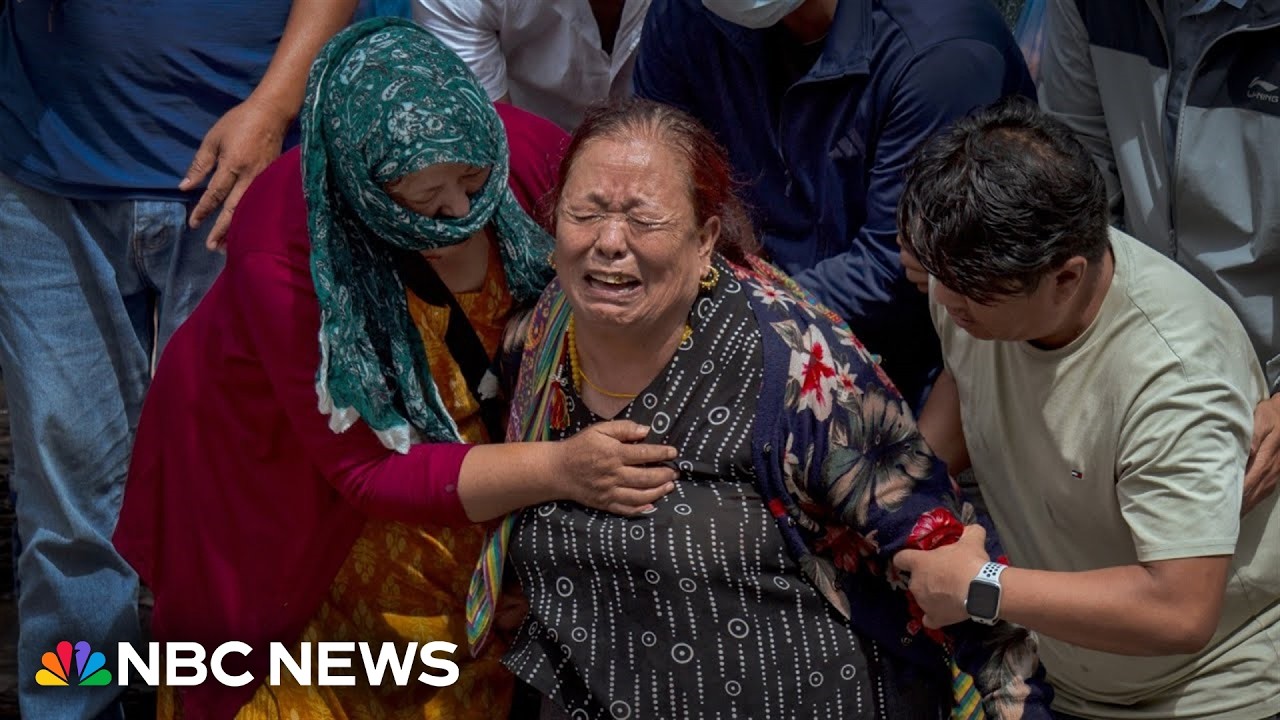
Search for survivors from deadly Nepal floods enters eighth day

Search for survivors from deadly Nepal floods enters eighth day

September 18, 2026
Sen. John Barrasso says Trump isn’t violating the Constitution by banning reporters from the White House – NBC News

Sen. John Barrasso says Trump isn’t violating the Constitution by banning reporters from the White House – NBC News

September 20, 2026
Building a portfolio from scratch? David Wagner goes rapid-fire on the top names that make the cut

Building a portfolio from scratch? David Wagner goes rapid-fire on the top names that make the cut

September 17, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!