• bitcoinBitcoin(BTC)$81,273.004.26%
  • ethereumEthereum(ETH)$2,637.955.39%
  • tetherTether(USDT)$1.000.05%
  • binancecoinBNB(BNB)$767.622.57%
  • rippleXRP(XRP)$1.438.62%
  • usd-coinUSDC(USDC)$1.000.03%
  • solanaSolana(SOL)$111.775.90%
  • tronTRON(TRX)$0.3378260.08%
  • zcashZcash(ZEC)$1,542.125.96%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.030.22%
  • HyperliquidHyperliquid(HYPE)$92.453.08%
  • dogecoinDogecoin(DOGE)$0.0883393.74%
  • moneroMonero(XMR)$589.219.79%
  • RainRain(RAIN)$0.0139348.72%
  • whitebitWhiteBIT Coin(WBT)$83.123.52%
  • USDSUSDS(USDS)$1.000.02%
  • chainlinkChainlink(LINK)$12.526.09%
  • cardanoCardano(ADA)$0.2265095.90%
  • leo-tokenLEO Token(LEO)$8.89-0.28%
  • stellarStellar(XLM)$0.1947945.02%
  • uniswapUniswap(UNI)$9.104.46%
  • bitcoin-cashBitcoin Cash(BCH)$251.571.41%
  • nearNEAR Protocol(NEAR)$3.685.28%
  • Ethena USDeEthena USDe(USDE)$1.000.03%
  • daiDai(DAI)$1.000.01%
  • litecoinLitecoin(LTC)$57.975.20%
  • CantonCanton(CC)$0.1107892.79%
  • USD1USD1(USD1)$1.000.05%
  • avalanche-2Avalanche(AVAX)$9.3417.74%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.381.17%
  • hedera-hashgraphHedera(HBAR)$0.0807084.80%
  • suiSui(SUI)$0.869.38%
  • Global DollarGlobal Dollar(USDG)$1.000.00%
  • shiba-inuShiba Inu(SHIB)$0.0000052.08%
  • BittensorBittensor(TAO)$268.839.68%
  • crypto-com-chainCronos(CRO)$0.0599861.50%
  • MemeCoreMemeCore(M)$1.290.75%
  • paypal-usdPayPal USD(PYUSD)$1.000.02%
  • tether-goldTether Gold(XAUT)$4,373.370.02%
  • okbOKB(OKB)$122.748.05%
  • Circle USYCCircle USYC(USYC)$1.140.03%
  • Ripple USDRipple USD(RLUSD)$1.000.01%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.140.08%
  • aaveAave(AAVE)$142.916.01%
  • AsterAster(ASTER)$0.772.49%
  • mantleMantle(MNT)$0.613.66%
  • OndoOndo(ONDO)$0.4100855.36%
  • Pump.funPump.fun(PUMP)$0.004156-0.31%
  • polkadotPolkadot(DOT)$1.140.91%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Google AI Introduces CoverBench: A Challenging Benchmark Focused on Verifying Language Model LM Outputs in Complex Reasoning Settings

August 8, 2024
in AI & Technology
Reading Time: 5 mins read
A A
Google AI Introduces CoverBench: A Challenging Benchmark Focused on Verifying Language Model LM Outputs in Complex Reasoning Settings
ShareShareShareShareShare

One of the primary challenges in AI research is verifying the correctness of language models (LMs) outputs, especially in contexts requiring complex reasoning. As LMs are increasingly used for intricate queries that demand multiple reasoning steps, domain expertise, and quantitative analysis, ensuring the accuracy and reliability of these models is crucial. This task is particularly important in fields like finance, law, and biomedicine, where incorrect information can lead to significant adverse outcomes.

Current methods for verifying LM outputs include fact-checking and natural language inference (NLI) techniques. These methods typically rely on datasets designed for specific reasoning tasks, such as question answering (QA) or financial analysis. However, these datasets are not tailored for claim verification, and existing methods exhibit limitations like high computational complexity, dependence on large volumes of labeled data, and inadequate performance on tasks requiring long-context reasoning or multi-hop inferences. High label noise and the domain-specific nature of many datasets further hinder the generalizability and applicability of these methods in broader contexts.

YOU MAY ALSO LIKE

Linkup Research Releases SPARSEUP: A 149M-Parameter Open-Source Sparse Embedding Model

GGUF vs GPTQ vs AWQ vs EXL2: LLM Model Formats Explained (2026)

A team of researchers from Google and Tel Aviv University proposed CoverBench, a benchmark specifically designed for evaluating complex claim verification across diverse domains and reasoning types. CoverBench addresses the limitations of existing methods by providing a unified format and a diverse set of 733 examples requiring complex reasoning, including long-context understanding, multi-step reasoning, and quantitative analysis. The benchmark includes true and false claims vetted for quality, ensuring low levels of label noise. This novel approach allows for a comprehensive evaluation of LM verification capabilities, highlighting areas needing improvement and setting a higher standard for claim verification tasks.

CoverBench comprises datasets from nine different sources, including FinQA, QRData, TabFact, MultiHiertt, HybridQA, ContractNLI, PubMedQA, TACT, and Feverous. These datasets cover a range of domains such as finance, Wikipedia, biomedical, legal, and statistics. The benchmark involves converting various QA tasks into declarative claims, standardizing table representations, and generating negative examples using seed models like GPT-4. The final dataset contains long input contexts, averaging 3,500 tokens, which challenge current models’ capabilities. The datasets were manually vetted to ensure the correctness and difficulty of the claims.
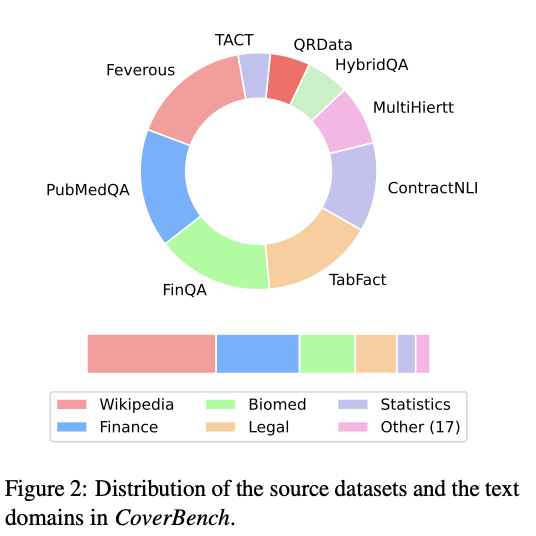
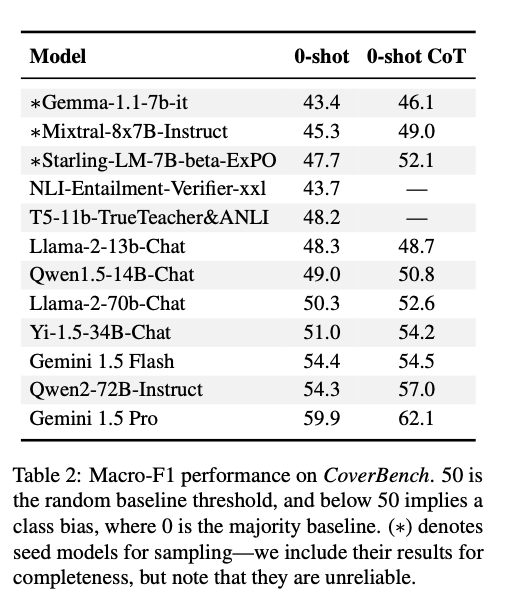
The evaluation of CoverBench demonstrates that current competitive LMs struggle significantly with the tasks presented, achieving performance near the random baseline in many instances. The highest-performing models, such as Gemini 1.5 Pro, achieved a Macro-F1 score of 62.1, indicating substantial room for improvement. In contrast, models like Gemma-1.1-7b-it performed much lower, underscoring the benchmark’s difficulty. These results highlight the challenges LMs face in complex claim verification and the significant headroom for advancements in this area.
In conclusion, CoverBench significantly contributes to AI research by providing a challenging benchmark for complex claim verification. It overcomes the limitations of existing datasets by offering a diverse set of tasks that require multi-step reasoning, long-context understanding, and quantitative analysis. The benchmark’s thorough evaluation reveals that current LMs have substantial room for improvement in these areas. CoverBench thus sets a new standard for claim verification, pushing the boundaries of what LMs can achieve in complex reasoning tasks.


Check out the Paper. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter and join our Telegram Channel and LinkedIn Group. If you like our work, you will love our newsletter..

Don’t Forget to join our 48k+ ML SubReddit

Find Upcoming AI Webinars here


Aswin AK is a consulting intern at MarkTechPost. He is pursuing his Dual Degree at the Indian Institute of Technology, Kharagpur. He is passionate about data science and machine learning, bringing a strong academic background and hands-on experience in solving real-life cross-domain challenges.


Credit: Source link

ShareTweetSendSharePin

Related Posts

Linkup Research Releases SPARSEUP: A 149M-Parameter Open-Source Sparse Embedding Model
AI & Technology

Linkup Research Releases SPARSEUP: A 149M-Parameter Open-Source Sparse Embedding Model

September 19, 2026
GGUF vs GPTQ vs AWQ vs EXL2: LLM Model Formats Explained (2026)
AI & Technology

GGUF vs GPTQ vs AWQ vs EXL2: LLM Model Formats Explained (2026)

September 19, 2026
Consumers Sue Anthropic, OpenAI, SpaceXAI and Google Over Alleged AI Pact – Unite.AI
AI & Technology

Consumers Sue Anthropic, OpenAI, SpaceXAI and Google Over Alleged AI Pact – Unite.AI

September 19, 2026
How Focus Mode Has Changed In iOS 27
AI & Technology

How Focus Mode Has Changed In iOS 27

September 18, 2026
Next Post
White Sox fire manager Pedro Grifol in wake of franchise-record losing streak – The Athletic – The New York Times

White Sox fire manager Pedro Grifol in wake of franchise-record losing streak - The Athletic - The New York Times

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Massive snake found in the engine of a car in Wisconsin

Massive snake found in the engine of a car in Wisconsin

September 14, 2026
Evacuated house collapses in China after torrential rain

Evacuated house collapses in China after torrential rain

September 18, 2026
Sole 9/11 ‘triple survivor’ reflects on attack 25 years later

Sole 9/11 ‘triple survivor’ reflects on attack 25 years later

September 14, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!