• bitcoinBitcoin(BTC)$84,666.001.74%
  • ethereumEthereum(ETH)$2,708.982.46%
  • tetherTether(USDT)$1.000.01%
  • binancecoinBNB(BNB)$777.241.43%
  • rippleXRP(XRP)$1.566.74%
  • usd-coinUSDC(USDC)$1.000.01%
  • solanaSolana(SOL)$118.514.67%
  • tronTRON(TRX)$0.337188-0.55%
  • zcashZcash(ZEC)$1,591.557.76%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.030.00%
  • HyperliquidHyperliquid(HYPE)$93.742.97%
  • dogecoinDogecoin(DOGE)$0.0970365.40%
  • moneroMonero(XMR)$567.772.80%
  • chainlinkChainlink(LINK)$14.0215.04%
  • whitebitWhiteBIT Coin(WBT)$84.471.43%
  • USDSUSDS(USDS)$1.000.01%
  • cardanoCardano(ADA)$0.2539568.22%
  • RainRain(RAIN)$0.011879-1.24%
  • leo-tokenLEO Token(LEO)$8.80-1.42%
  • stellarStellar(XLM)$0.22020310.98%
  • bitcoin-cashBitcoin Cash(BCH)$339.233.36%
  • nearNEAR Protocol(NEAR)$4.9216.72%
  • uniswapUniswap(UNI)$9.344.94%
  • litecoinLitecoin(LTC)$70.895.45%
  • Ethena USDeEthena USDe(USDE)$1.000.01%
  • CantonCanton(CC)$0.11812710.36%
  • avalanche-2Avalanche(AVAX)$10.443.36%
  • daiDai(DAI)$1.000.02%
  • USD1USD1(USD1)$1.000.02%
  • suiSui(SUI)$1.0410.51%
  • hedera-hashgraphHedera(HBAR)$0.0931544.75%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.421.20%
  • BittensorBittensor(TAO)$305.048.60%
  • shiba-inuShiba Inu(SHIB)$0.0000064.93%
  • crypto-com-chainCronos(CRO)$0.0655678.16%
  • Global DollarGlobal Dollar(USDG)$1.000.01%
  • BitwayBitway(BTW)$1.087.25%
  • MemeCoreMemeCore(M)$1.20-1.64%
  • OndoOndo(ONDO)$0.5631.28%
  • paypal-usdPayPal USD(PYUSD)$1.000.02%
  • tether-goldTether Gold(XAUT)$4,288.740.71%
  • okbOKB(OKB)$120.021.99%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • Ripple USDRipple USD(RLUSD)$1.000.03%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.140.07%
  • EthenaEthena(ENA)$0.22344011.06%
  • aaveAave(AAVE)$145.887.20%
  • mantleMantle(MNT)$0.681.16%
  • MorphoMorpho(MORPHO)$2.9610.75%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Optimizing Memory for Large-Scale NLP Models: A Look at MINI-SEQUENCE TRANSFORMER

July 30, 2024
in AI & Technology
Reading Time: 5 mins read
A A
Optimizing Memory for Large-Scale NLP Models: A Look at MINI-SEQUENCE TRANSFORMER
ShareShareShareShareShare

The evolution of Transformer models has revolutionized natural language processing (NLP) by significantly advancing model performance and capabilities. However, this rapid development has introduced substantial challenges, particularly regarding the memory requirements for training these large-scale models. As Transformer models grow in size and complexity, managing the memory demands becomes increasingly critical. The paper addresses this pressing issue by proposing a novel methodology to optimize memory usage without compromising the performance of long-sequence training.

Traditional approaches, such as multi-query attention and grouped query attention (GQA), have significantly reduced memory usage during inference by optimizing the key-value cache size. These techniques have been successfully implemented in large-scale models like PaLM and LLaMA. However, the ongoing enhancements in model architecture, such as the increased vocabulary size and intermediate layers in Llama3, continue exacerbating memory challenges during training.

YOU MAY ALSO LIKE

Fastino Releases GLiNER2.5-Decide: A 340M Open-Weight Decision Model That Runs on CPU

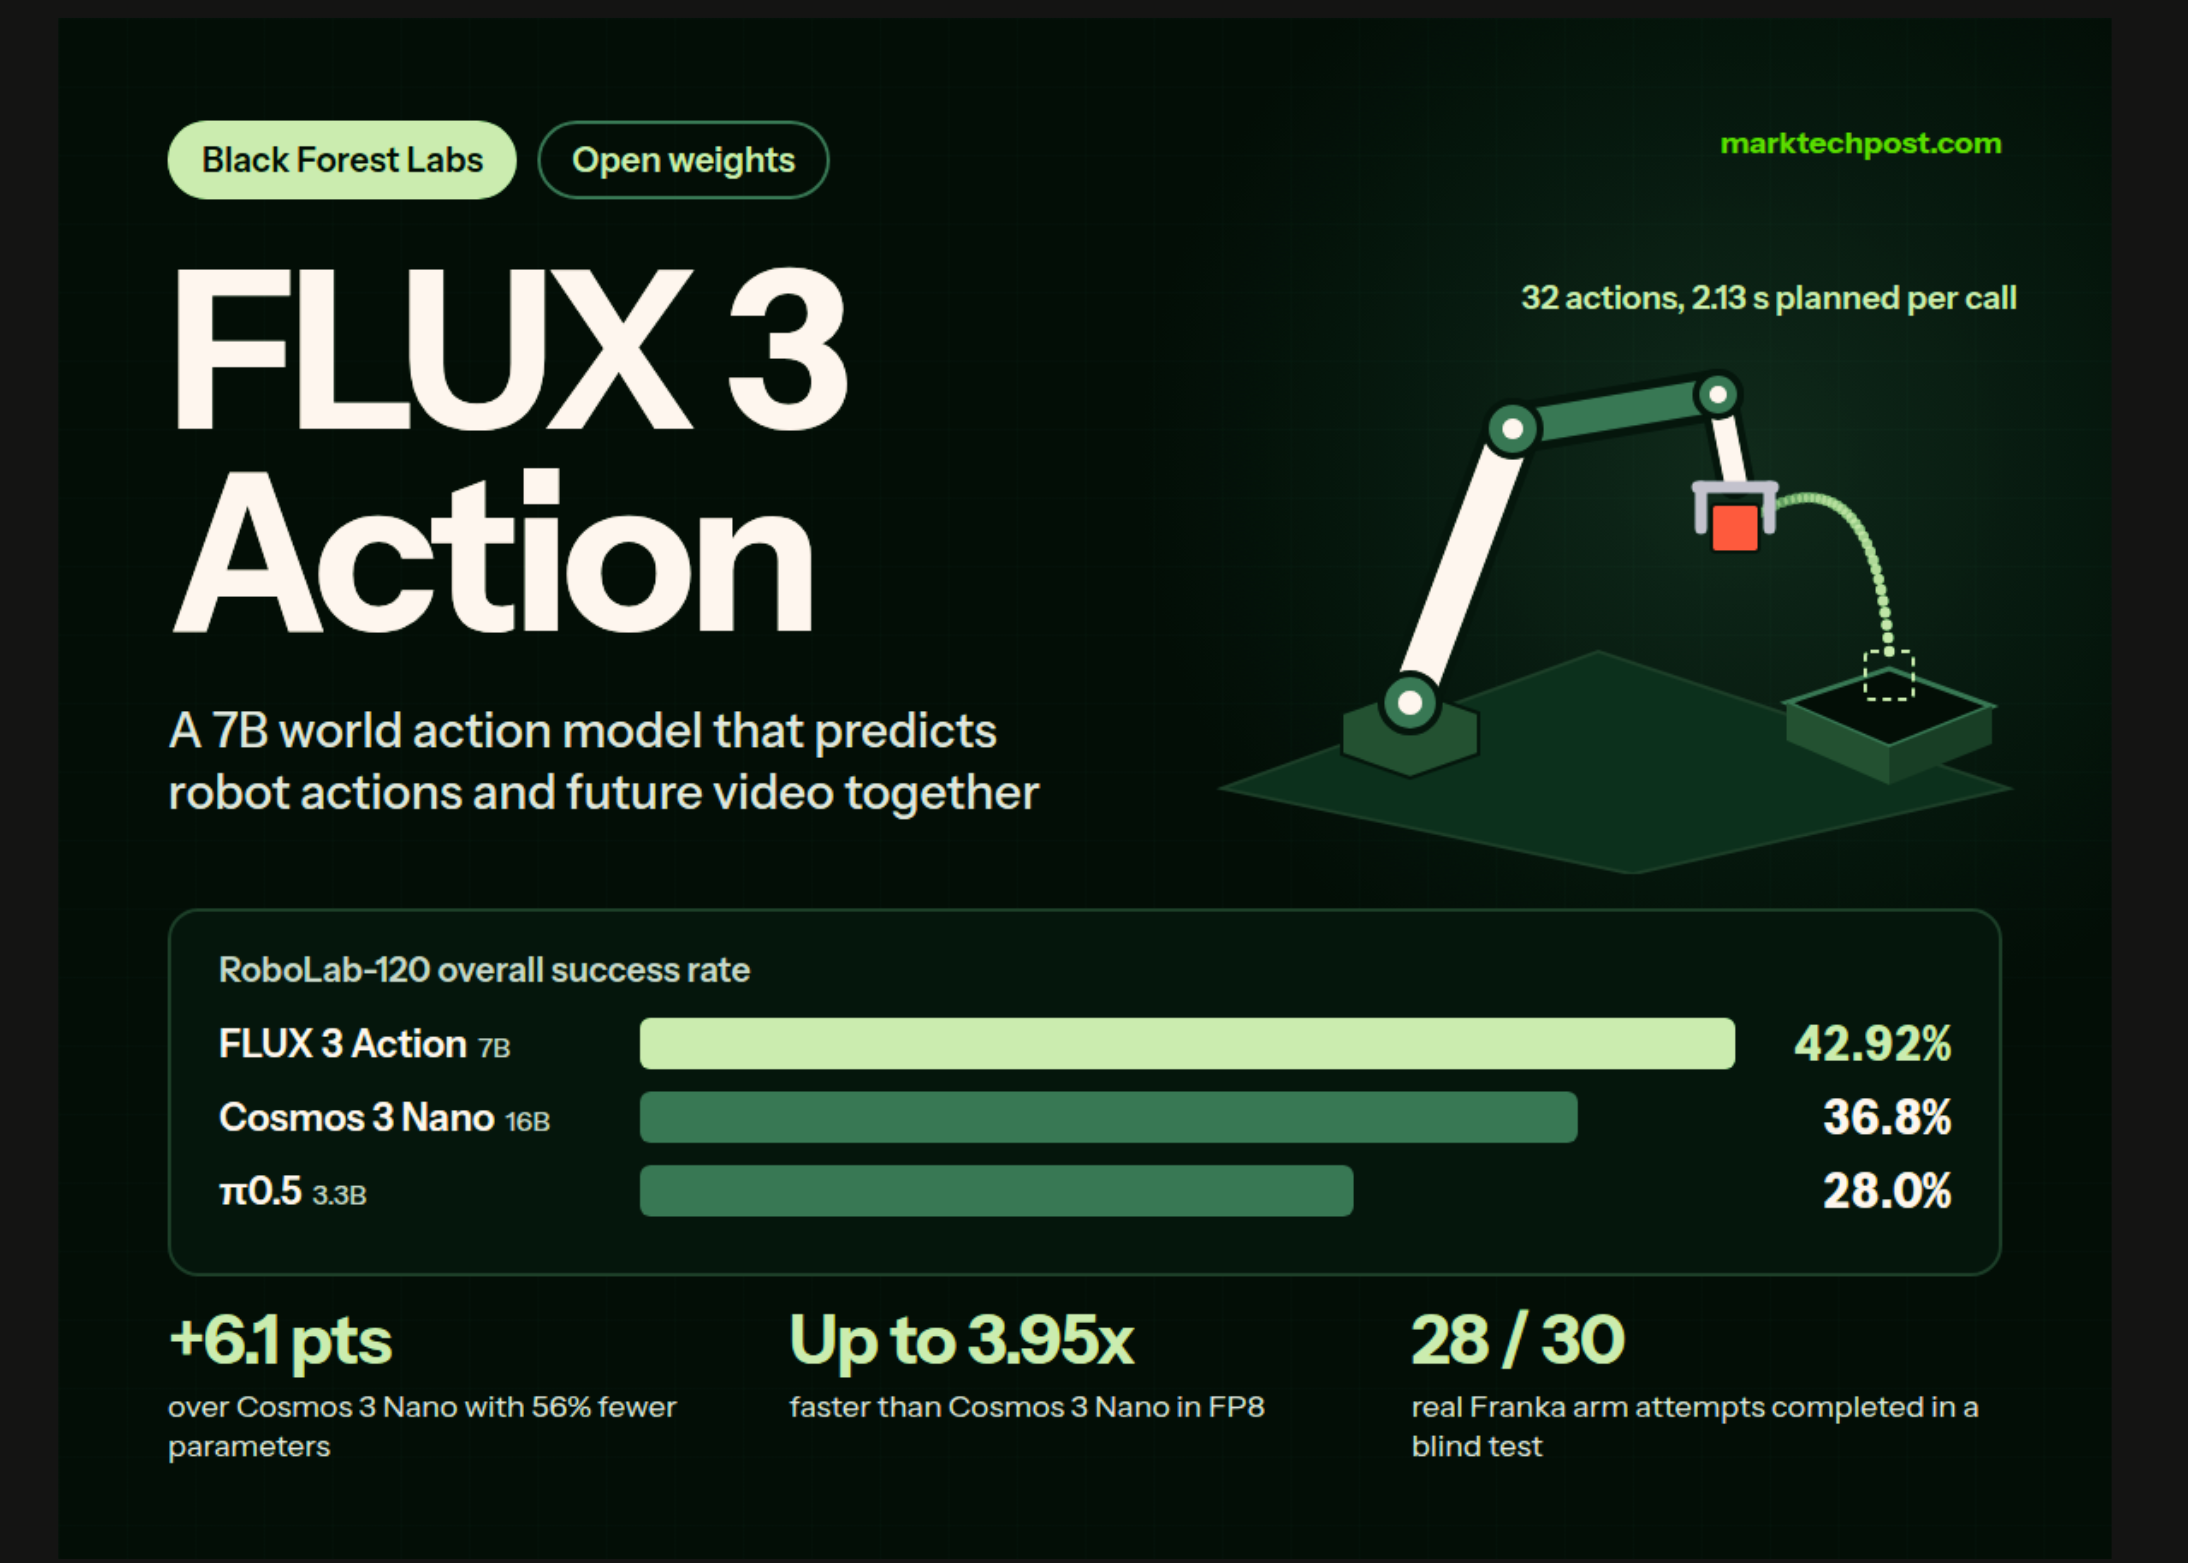
Black Forest Labs Releases FLUX 3 Action: A 7B Open-Weights World Action Model That Tops RoboLab-120

A team of researchers from Caltech and CMU propose the MINI-SEQUENCE TRANSFORMER (MST) to address these challenges. MST introduces a method that partitions input sequences and processes them iteratively as mini-sequences. This approach significantly reduces intermediate memory usage by integrating activation recomputation, a technique that involves recalculating the activations of certain layers during the backward pass, which saves memory in both forward and backward passes. MST is designed to be implementation-agnostic and requires minimal code modifications to integrate with existing training frameworks. This method maintains high efficiency and accuracy even when dealing with extremely long sequences.

The MST methodology reduces memory usage by partitioning input sequences into smaller mini-sequences. During the training of models like Llama3-8B, the memory allocated for activations in the forward pass is substantial, and similar challenges arise during the backward pass. MST mitigates this by processing smaller chunks iteratively, thereby reducing the memory footprint. This approach also involves optimizing the memory allocated for gradients and optimizer states, further enhancing the overall efficiency of the training process.

In addition to the basic MST, the researchers extend this method to a distributed setting. By combining MST with DeepSpeed-Ulysses, the input tensor of each Transformer layer is divided along the sequence dimension, allowing for parallel computation across multiple GPUs—this segmentation, along with activation recomputation, results in a substantial reduction in activation memory requirements. The distributed MST maintains compatibility with various sequence parallelism techniques, such as Megatron-LM and Ring Attention, ensuring scalability and flexibility in different training environments.

The researchers conducted extensive experiments to validate the efficacy of MST. They trained Llama3-8B and Llama2 models with MST, significantly improving sequence length capabilities. For instance, MST enabled the training of Llama3-8B with a context length of up to 60k on a single A100 GPU, outperforming standard implementations by 12 to 20 times in terms of sequence length. Furthermore, MST maintained the same training throughput as standard long-sequence training methods, ensuring that the optimization did not come at the cost of performance.

The evaluation also highlighted the scalability of MST in distributed settings. By leveraging DeepSpeed-Ulysses, MST could scale the sequence length linearly with the number of GPUs, demonstrating its potential for large-scale deployments. The memory optimization achieved by MST was particularly pronounced for the LM-Head component, which significantly reduced memory usage while having a minimal impact on execution time for longer sequences.

The paper presents a compelling solution to the memory challenges of training large-scale Transformer models with long sequences. By introducing the MINI-SEQUENCE TRANSFORMER, the researchers offer a methodology that optimizes memory usage through mini-sequence processing and activation recomputation. This approach reduces the memory footprint and maintains high efficiency and accuracy, making it a valuable addition to existing training frameworks. The successful implementation and evaluation of MST underscore its potential to enhance the scalability and performance of long-sequence training in NLP and other domains.


Check out the Paper and GitHub. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter and join our Telegram Channel and LinkedIn Group. If you like our work, you will love our newsletter..

Don’t Forget to join our 47k+ ML SubReddit

Find Upcoming AI Webinars here


Shreya Maji is a consulting intern at MarktechPost. She is pursued her B.Tech at the Indian Institute of Technology (IIT), Bhubaneswar. An AI enthusiast, she enjoys staying updated on the latest advancements. Shreya is particularly interested in the real-life applications of cutting-edge technology, especially in the field of data science.

🐝 Join the Fastest Growing AI Research Newsletter Read by Researchers from Google + NVIDIA + Meta + Stanford + MIT + Microsoft and many others…


Credit: Source link

ShareTweetSendSharePin

Related Posts

Fastino Releases GLiNER2.5-Decide: A 340M Open-Weight Decision Model That Runs on CPU
AI & Technology

Fastino Releases GLiNER2.5-Decide: A 340M Open-Weight Decision Model That Runs on CPU

September 25, 2026
Black Forest Labs Releases FLUX 3 Action: A 7B Open-Weights World Action Model That Tops RoboLab-120
AI & Technology

Black Forest Labs Releases FLUX 3 Action: A 7B Open-Weights World Action Model That Tops RoboLab-120

September 25, 2026
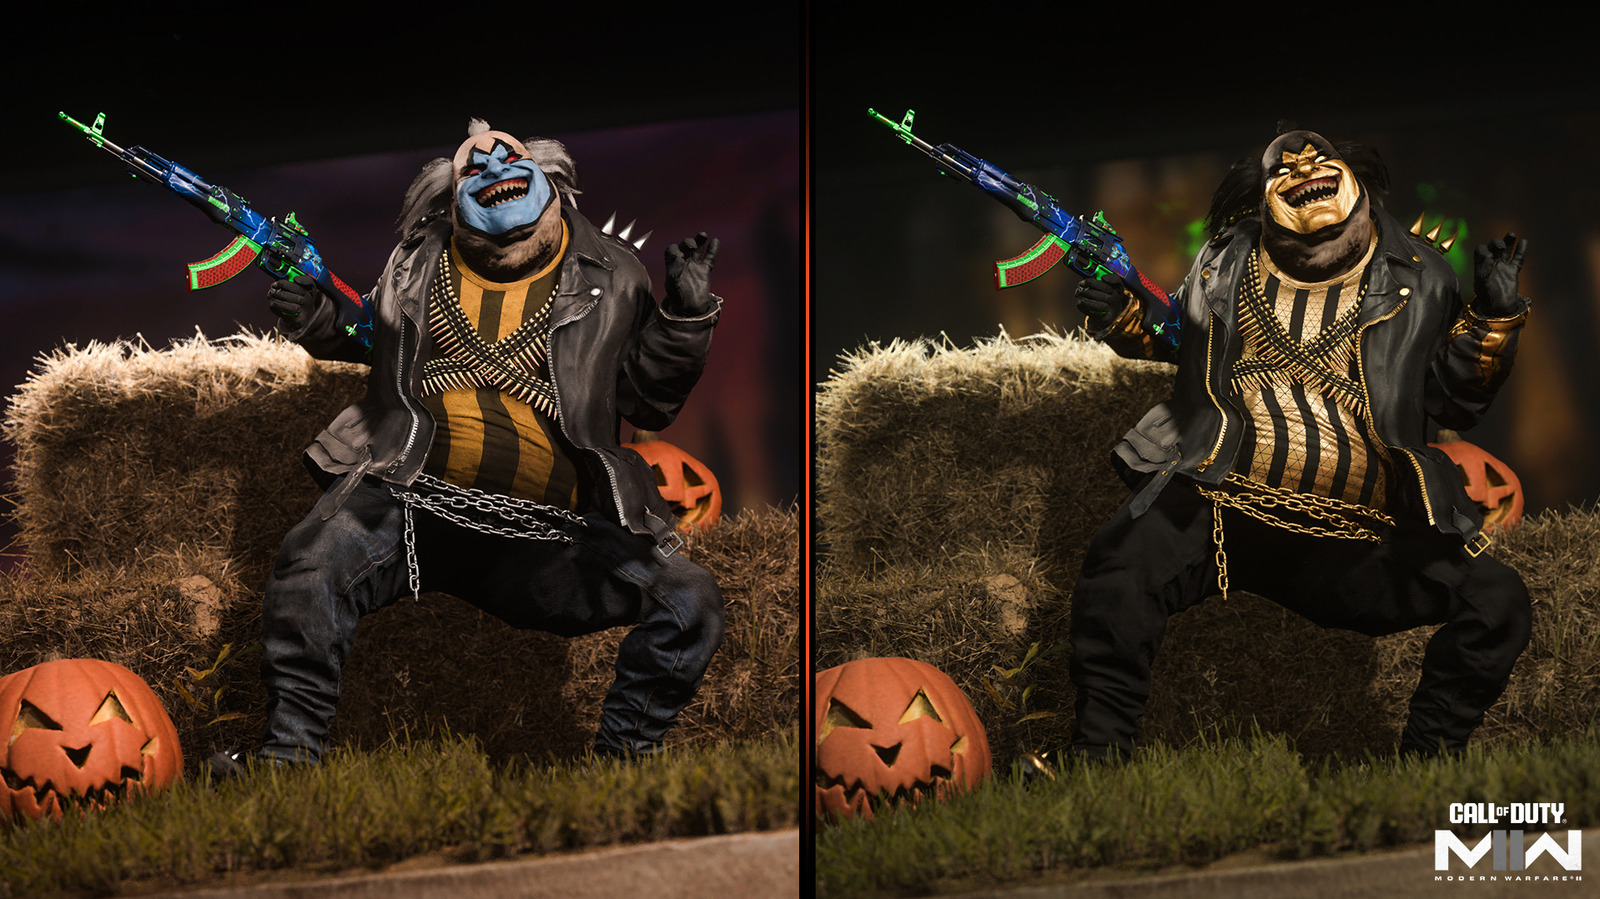
Warzone Is Adding A Button To Hide All The Goofy Skins
AI & Technology

Warzone Is Adding A Button To Hide All The Goofy Skins

September 24, 2026
How These AI Glasses Compare
AI & Technology

How These AI Glasses Compare

September 24, 2026
Next Post
Apple’s AI Upgrades to Miss Launch of iOS 18 Overhaul

Apple’s AI Upgrades to Miss Launch of iOS 18 Overhaul

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
LIVE: Treasury Secretary Bessent details economic sanctions against Iran | NBC News

LIVE: Treasury Secretary Bessent details economic sanctions against Iran | NBC News

September 25, 2026
New AI Glasses, A Mixed Reality Headset And More

New AI Glasses, A Mixed Reality Headset And More

September 18, 2026
Now Trump Says He’s Creating An AI Force

Now Trump Says He’s Creating An AI Force

September 19, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!