• bitcoinBitcoin(BTC)$84,972.005.58%
  • ethereumEthereum(ETH)$2,722.365.54%
  • tetherTether(USDT)$1.000.02%
  • binancecoinBNB(BNB)$789.924.90%
  • rippleXRP(XRP)$1.497.79%
  • usd-coinUSDC(USDC)$1.000.01%
  • solanaSolana(SOL)$116.677.42%
  • tronTRON(TRX)$0.3439790.41%
  • zcashZcash(ZEC)$1,553.317.06%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.000.00%
  • HyperliquidHyperliquid(HYPE)$95.504.44%
  • dogecoinDogecoin(DOGE)$0.0934379.66%
  • moneroMonero(XMR)$573.269.31%
  • whitebitWhiteBIT Coin(WBT)$86.145.23%
  • RainRain(RAIN)$0.0140936.88%
  • chainlinkChainlink(LINK)$13.068.01%
  • USDSUSDS(USDS)$1.000.02%
  • cardanoCardano(ADA)$0.2419949.06%
  • leo-tokenLEO Token(LEO)$8.940.20%
  • stellarStellar(XLM)$0.21126510.74%
  • uniswapUniswap(UNI)$8.861.03%
  • nearNEAR Protocol(NEAR)$4.1615.55%
  • bitcoin-cashBitcoin Cash(BCH)$266.668.03%
  • avalanche-2Avalanche(AVAX)$11.339.79%
  • Ethena USDeEthena USDe(USDE)$1.000.02%
  • litecoinLitecoin(LTC)$60.285.34%
  • daiDai(DAI)$1.000.01%
  • CantonCanton(CC)$0.1143599.42%
  • USD1USD1(USD1)$1.000.01%
  • suiSui(SUI)$1.0223.62%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.423.48%
  • hedera-hashgraphHedera(HBAR)$0.08987110.14%
  • MemeCoreMemeCore(M)$1.51-0.93%
  • shiba-inuShiba Inu(SHIB)$0.0000066.55%
  • Global DollarGlobal Dollar(USDG)$1.000.01%
  • BittensorBittensor(TAO)$284.2112.93%
  • crypto-com-chainCronos(CRO)$0.0632918.74%
  • paypal-usdPayPal USD(PYUSD)$1.000.03%
  • tether-goldTether Gold(XAUT)$4,371.330.01%
  • okbOKB(OKB)$121.985.19%
  • Circle USYCCircle USYC(USYC)$1.140.00%
  • Ripple USDRipple USD(RLUSD)$1.000.02%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • BitwayBitway(BTW)$0.8620.56%
  • aaveAave(AAVE)$145.977.47%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.15-0.32%
  • EthenaEthena(ENA)$0.2221645.73%
  • OndoOndo(ONDO)$0.4542439.54%
  • mantleMantle(MNT)$0.636.49%
  • Pump.funPump.fun(PUMP)$0.0044188.76%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

Researchers at the University of Wisconsin-Madison Propose a Finetuning Approach Utilizing a Carefully Designed Synthetic Dataset Comprising Numerical Key-Value Retrieval Tasks

July 3, 2024
in AI & Technology
Reading Time: 4 mins read
A A
Researchers at the University of Wisconsin-Madison Propose a Finetuning Approach Utilizing a Carefully Designed Synthetic Dataset Comprising Numerical Key-Value Retrieval Tasks
ShareShareShareShareShare

It is observed that LLMs often struggle to retrieve relevant information from the middle of long input contexts, exhibiting a “lost-in-the-middle” behavior. The research paper addresses the critical issue of the performance of large language models (LLMs) when handling longer-context inputs. Specifically, LLMs like GPT-3.5 Turbo and Mistral 7B often struggle with accurately retrieving information and maintaining reasoning capabilities across extensive textual data. This limitation hampers their effectiveness in tasks that require processing and reasoning over long passages, such as multi-document question answering (MDQA) and flexible length question answering (FLenQA). 

Current methods to enhance the performance of LLMs in long-context settings typically involve finetuning on real-world datasets. However, these datasets often include outdated or irrelevant information, which can lead to hallucinations and other inaccuracies. Traditional datasets such as MDQA and FLenQA have shown that LLMs tend to exhibit a “lost-in-the-middle” behavior, where their performance is optimal at the beginning or end of the input context but deteriorates for information in the middle.

YOU MAY ALSO LIKE

How AI Modernizes Lending Alongside Legacy Banking Systems Without a Teardown – Unite.AI

Best Voice Cloning APIs in 2026: Speaker Similarity, Consent Checks, and Price per 1M Characters

A team of researchers from the University of Wisconsin-Madison proposes a novel finetuning approach utilizing a carefully designed synthetic dataset to address these challenges. This dataset comprises numerical key-value retrieval tasks designed to enhance the LLMs’ ability to handle long contexts more effectively. By using synthetic data that avoids the pitfalls of outdated or irrelevant information, the researchers aim to improve LLMs’ information retrieval and reasoning capabilities without introducing hallucinations.

The proposed synthetic dataset consists of simple dictionary key-value retrieval tasks, where each task involves multiple dictionaries with a few keys each. For instance, the dataset for Mistral 7B includes 350 samples, each containing 85 dictionaries, resulting in prompts with roughly 3900 tokens. Finetuning is conducted on the answer part of these tasks, masking out other elements to focus the model’s learning process.

Experiments demonstrate that this approach significantly enhances the performance of LLMs in long-context tasks. For example, finetuning GPT-3.5 Turbo on the synthetic data resulted in a 10.5% improvement on the 20 documents MDQA benchmark at the tenth position. Moreover, this method mitigates the “lost-in-the-middle” phenomenon and reduces the primacy bias, leading to more accurate information retrieval across the entire input context. The performance of models finetuned on the synthetic data was compared against those finetuned on real-world datasets, with the synthetic approach showing superior results in maintaining consistent accuracy across different context positions. 

The study introduces an innovative approach to finetuning LLMs using synthetic data, significantly enhancing their performance in long-context settings. The proposed method demonstrates substantial improvements over traditional finetuning techniques by addressing the “lost-in-the-middle” phenomenon and reducing primacy bias. This research highlights the potential of synthetic datasets in overcoming the limitations of real-world data, paving the way for more effective and reliable LLMs in handling extensive textual information.


Check out the Paper. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter. 

Join our Telegram Channel and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our 45k+ ML SubReddit


Shreya Maji is a consulting intern at MarktechPost. She is pursued her B.Tech at the Indian Institute of Technology (IIT), Bhubaneswar. An AI enthusiast, she enjoys staying updated on the latest advancements. Shreya is particularly interested in the real-life applications of cutting-edge technology, especially in the field of data science.

🐝 Join the Fastest Growing AI Research Newsletter Read by Researchers from Google + NVIDIA + Meta + Stanford + MIT + Microsoft and many others…


Credit: Source link

ShareTweetSendSharePin

Related Posts

How AI Modernizes Lending Alongside Legacy Banking Systems Without a Teardown – Unite.AI
AI & Technology

How AI Modernizes Lending Alongside Legacy Banking Systems Without a Teardown – Unite.AI

September 21, 2026
Best Voice Cloning APIs in 2026: Speaker Similarity, Consent Checks, and Price per 1M Characters
AI & Technology

Best Voice Cloning APIs in 2026: Speaker Similarity, Consent Checks, and Price per 1M Characters

September 21, 2026
What Is iPhone Handoff And Which Carriers Support It?
AI & Technology

What Is iPhone Handoff And Which Carriers Support It?

September 21, 2026
Which Should You Choose For Your Home?
AI & Technology

Which Should You Choose For Your Home?

September 21, 2026
Next Post
Dave Ramsey has a stern message for Gen Z

Dave Ramsey has a stern message for Gen Z

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
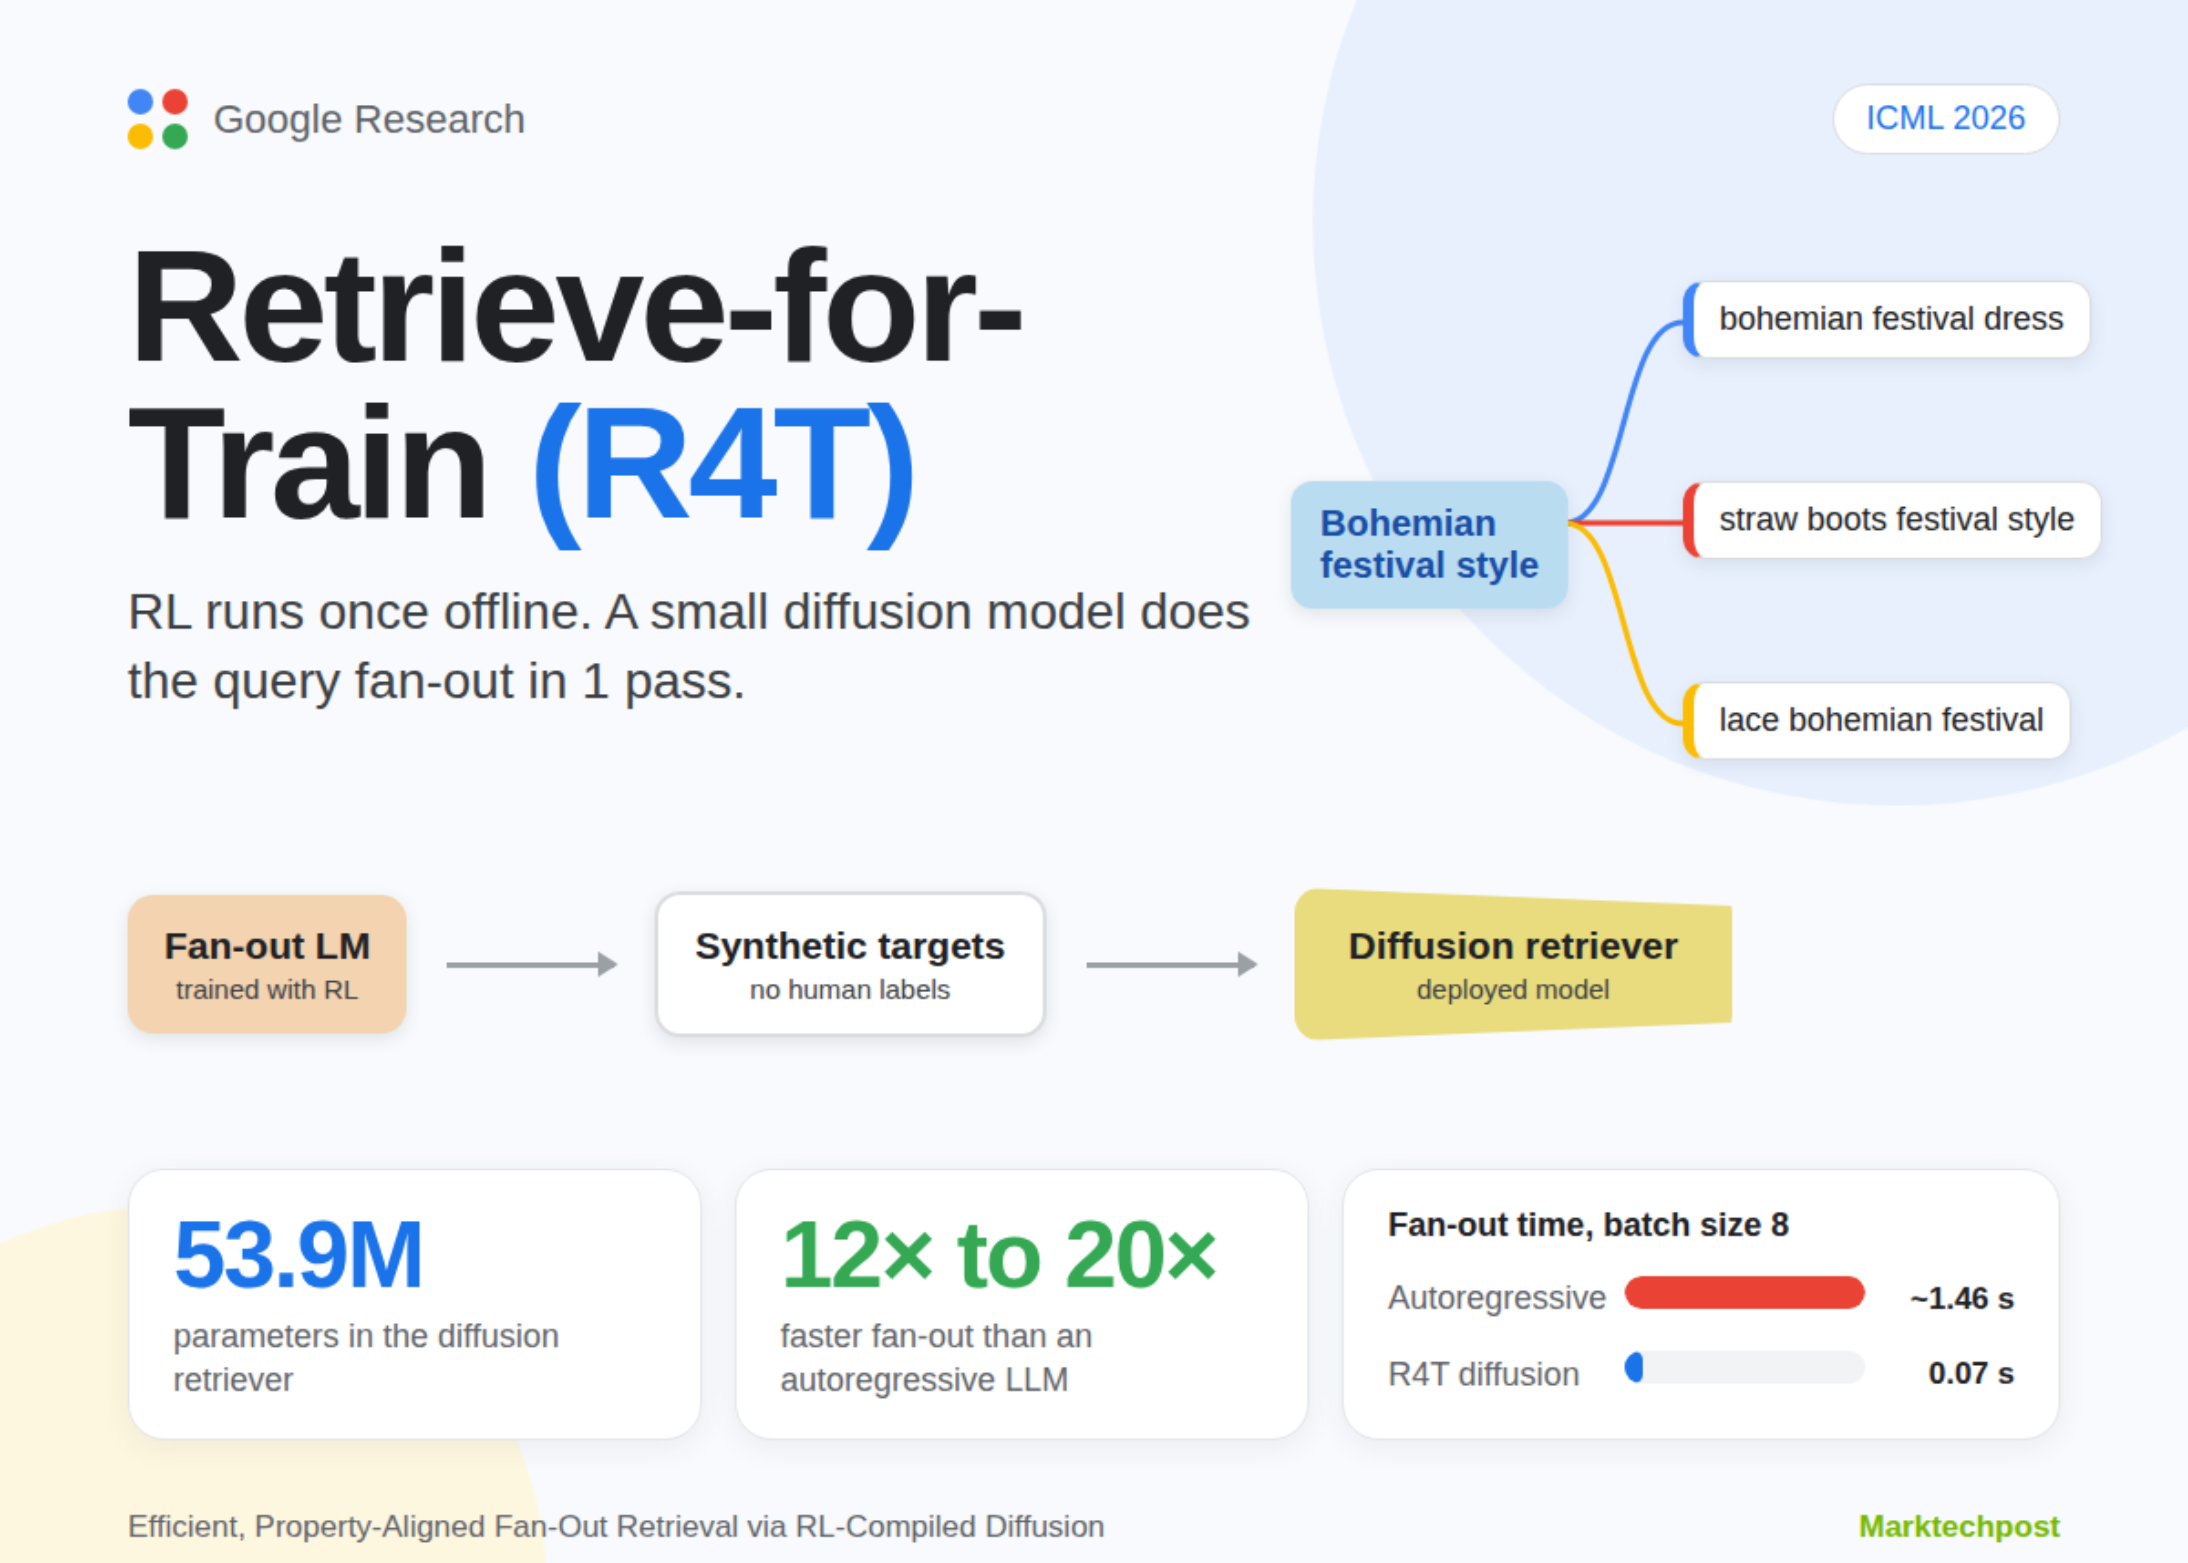
Google Research Introduces Retrieve-for-Train (R4T): An RL-Compiled Diffusion Retriever for 12× to 20× Faster Query Fan-Out

Google Research Introduces Retrieve-for-Train (R4T): An RL-Compiled Diffusion Retriever for 12× to 20× Faster Query Fan-Out

September 17, 2026
Tropical Storm Edouard hits Gulf Coast

Tropical Storm Edouard hits Gulf Coast

September 19, 2026
Ex-CNN anchor Brooke Baldwin reveals dad beat her with belt until she was ‘black and blue on my backside’

Ex-CNN anchor Brooke Baldwin reveals dad beat her with belt until she was ‘black and blue on my backside’

September 14, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!