• bitcoinBitcoin(BTC)$76,488.001.19%
  • ethereumEthereum(ETH)$2,443.801.91%
  • tetherTether(USDT)$1.00-0.02%
  • binancecoinBNB(BNB)$725.662.74%
  • rippleXRP(XRP)$1.301.65%
  • usd-coinUSDC(USDC)$1.00-0.01%
  • solanaSolana(SOL)$100.203.52%
  • tronTRON(TRX)$0.3350230.07%
  • zcashZcash(ZEC)$1,384.0316.78%
  • Figure HelocFigure Heloc(FIGR_HELOC)$1.032.65%
  • HyperliquidHyperliquid(HYPE)$80.173.52%
  • dogecoinDogecoin(DOGE)$0.0814912.73%
  • USDSUSDS(USDS)$1.000.00%
  • moneroMonero(XMR)$493.57-1.76%
  • whitebitWhiteBIT Coin(WBT)$78.681.19%
  • RainRain(RAIN)$0.012211-11.52%
  • chainlinkChainlink(LINK)$11.224.61%
  • leo-tokenLEO Token(LEO)$8.930.39%
  • cardanoCardano(ADA)$0.1994313.44%
  • stellarStellar(XLM)$0.1833625.46%
  • Ethena USDeEthena USDe(USDE)$1.000.03%
  • daiDai(DAI)$1.00-0.01%
  • bitcoin-cashBitcoin Cash(BCH)$223.332.60%
  • uniswapUniswap(UNI)$7.0312.42%
  • USD1USD1(USD1)$1.00-0.02%
  • litecoinLitecoin(LTC)$52.834.17%
  • CantonCanton(CC)$0.10110211.15%
  • the-open-networkGram (prev. Toncoin)(GRAM)$1.320.75%
  • nearNEAR Protocol(NEAR)$2.7617.63%
  • avalanche-2Avalanche(AVAX)$7.585.28%
  • Global DollarGlobal Dollar(USDG)$1.000.00%
  • hedera-hashgraphHedera(HBAR)$0.0739650.08%
  • shiba-inuShiba Inu(SHIB)$0.0000054.10%
  • suiSui(SUI)$0.725.83%
  • crypto-com-chainCronos(CRO)$0.0580875.82%
  • paypal-usdPayPal USD(PYUSD)$1.00-0.02%
  • tether-goldTether Gold(XAUT)$4,311.04-0.34%
  • BlackRock USD Institutional Digital Liquidity FundBlackRock USD Institutional Digital Liquidity Fund(BUIDL)$1.000.00%
  • BittensorBittensor(TAO)$227.916.44%
  • MemeCoreMemeCore(M)$1.132.66%
  • Circle USYCCircle USYC(USYC)$1.140.01%
  • okbOKB(OKB)$112.272.41%
  • Ripple USDRipple USD(RLUSD)$1.00-0.02%
  • Ondo US Dollar YieldOndo US Dollar Yield(USDY)$1.150.13%
  • AsterAster(ASTER)$0.7410.32%
  • BitwayBitway(BTW)$0.71-8.22%
  • aaveAave(AAVE)$123.824.55%
  • pax-goldPAX Gold(PAXG)$4,312.05-0.44%
  • World Liberty FinancialWorld Liberty Financial(WLFI)$0.0588003.20%
  • mantleMantle(MNT)$0.563.17%
TradePoint.io
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop
No Result
View All Result
TradePoint.io
No Result
View All Result

QoQ and QServe: A New Frontier in Model Quantization Transforming Large Language Model Deployment

May 12, 2024
in AI & Technology
Reading Time: 5 mins read
A A
QoQ and QServe: A New Frontier in Model Quantization Transforming Large Language Model Deployment
ShareShareShareShareShare

Quantization, a method integral to computational linguistics, is essential for managing the vast computational demands of deploying large language models (LLMs). It simplifies data, thereby facilitating quicker computations and more efficient model performance. However, deploying LLMs is inherently complex due to their colossal size and the computational intensity required. Effective deployment strategies must balance performance, accuracy, and computational overhead.

In LLMs, traditional quantization techniques convert high-precision floating-point numbers into lower-precision integers. While this process reduces memory usage and accelerates computation, it often incurs significant computational overhead. This overhead can degrade model accuracy, as the precision reduction can lead to substantial losses in data fidelity.

Researchers from MIT, NVIDIA, UMass Amherst, and MIT-IBM Watson AI Lab introduced the Quattuor-Octo-Quattuor (QoQ) algorithm, a novel approach that refines quantization. This innovative method employs progressive group quantization, which mitigates the accuracy losses typically associated with standard quantization methods. By quantizing weights to an intermediate precision and refining them to the target precision, the QoQ algorithm ensures that all computations are adapted to the capabilities of current-generation GPUs.

The QoQ algorithm utilizes a two-stage quantization process. Initially, weights are quantized to 8 bits using per-channel FP16 scales; these intermediates are further quantized to 4 bits. This approach enables General Matrix Multiplication (GEMM) operations on INT8 tensor cores, enhancing computational throughput and reducing latency. The algorithm also incorporates SmoothAttention, a technique that adjusts the quantization of activation keys to optimize performance further.

The QServe system was developed to support the deployment of the QoQ algorithm. QServe provides a tailored runtime environment that maximizes the efficiency of LLMs by exploiting the algorithm’s full potential. It integrates seamlessly with current GPU architectures, facilitating operations on low-throughput CUDA cores and significantly boosting processing speed. This system design reduces the quantization overhead by focusing on compute-aware weight reordering and fused attention mechanisms, essential for maintaining throughput and minimizing latency in real-time applications.
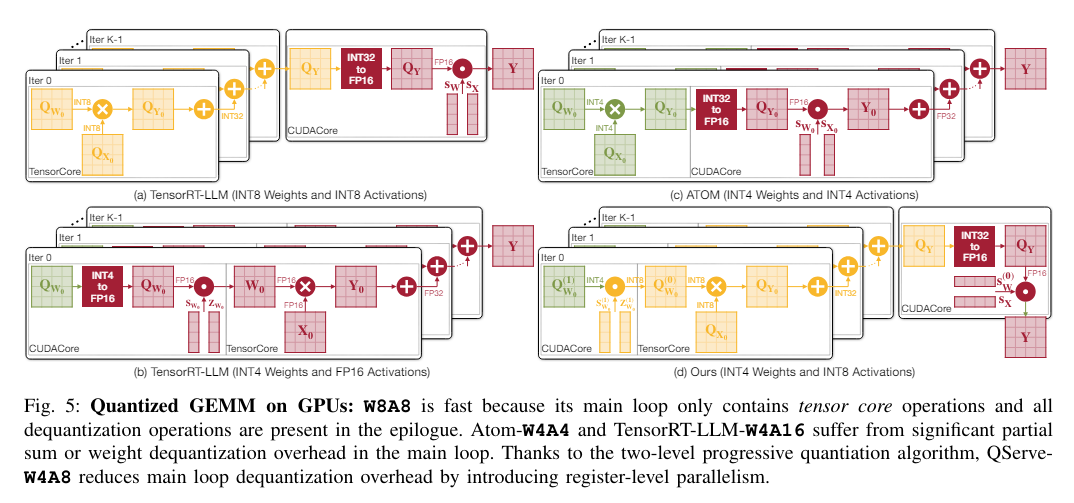
Performance evaluations of the QoQ algorithm indicate substantial improvements over previous methods. In testing, QoQ improved the maximum achievable serving throughput of Llama-3-8B models by up to 1.2 times on NVIDIA A100 GPUs and up to 1.4 times on L40S GPUs. Remarkably, on the L40S platform, QServe, a system designed to support QoQ, achieved throughput enhancements of up to 3.5 times compared to the same model on A100 GPUs, significantly reducing the cost of LLM serving.

In conclusion, the study introduces the QoQ algorithm and QServe system as groundbreaking solutions to the challenges of deploying LLMs efficiently. By addressing the significant computational overhead and accuracy loss inherent in traditional quantization methods, QoQ and QServe markedly enhance LLM serving throughput. The results from the implementation demonstrate up to 2.4 times faster processing on advanced GPUs, substantially reducing both the computational demands and the economic costs associated with LLM deployment. This advancement paves the way for broader adoption and more effective use of large language models in real-world applications.


Check out the Paper. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter. Join our Telegram Channel, Discord Channel, and LinkedIn Group.

If you like our work, you will love our newsletter..

Don’t Forget to join our 42k+ ML SubReddit

YOU MAY ALSO LIKE

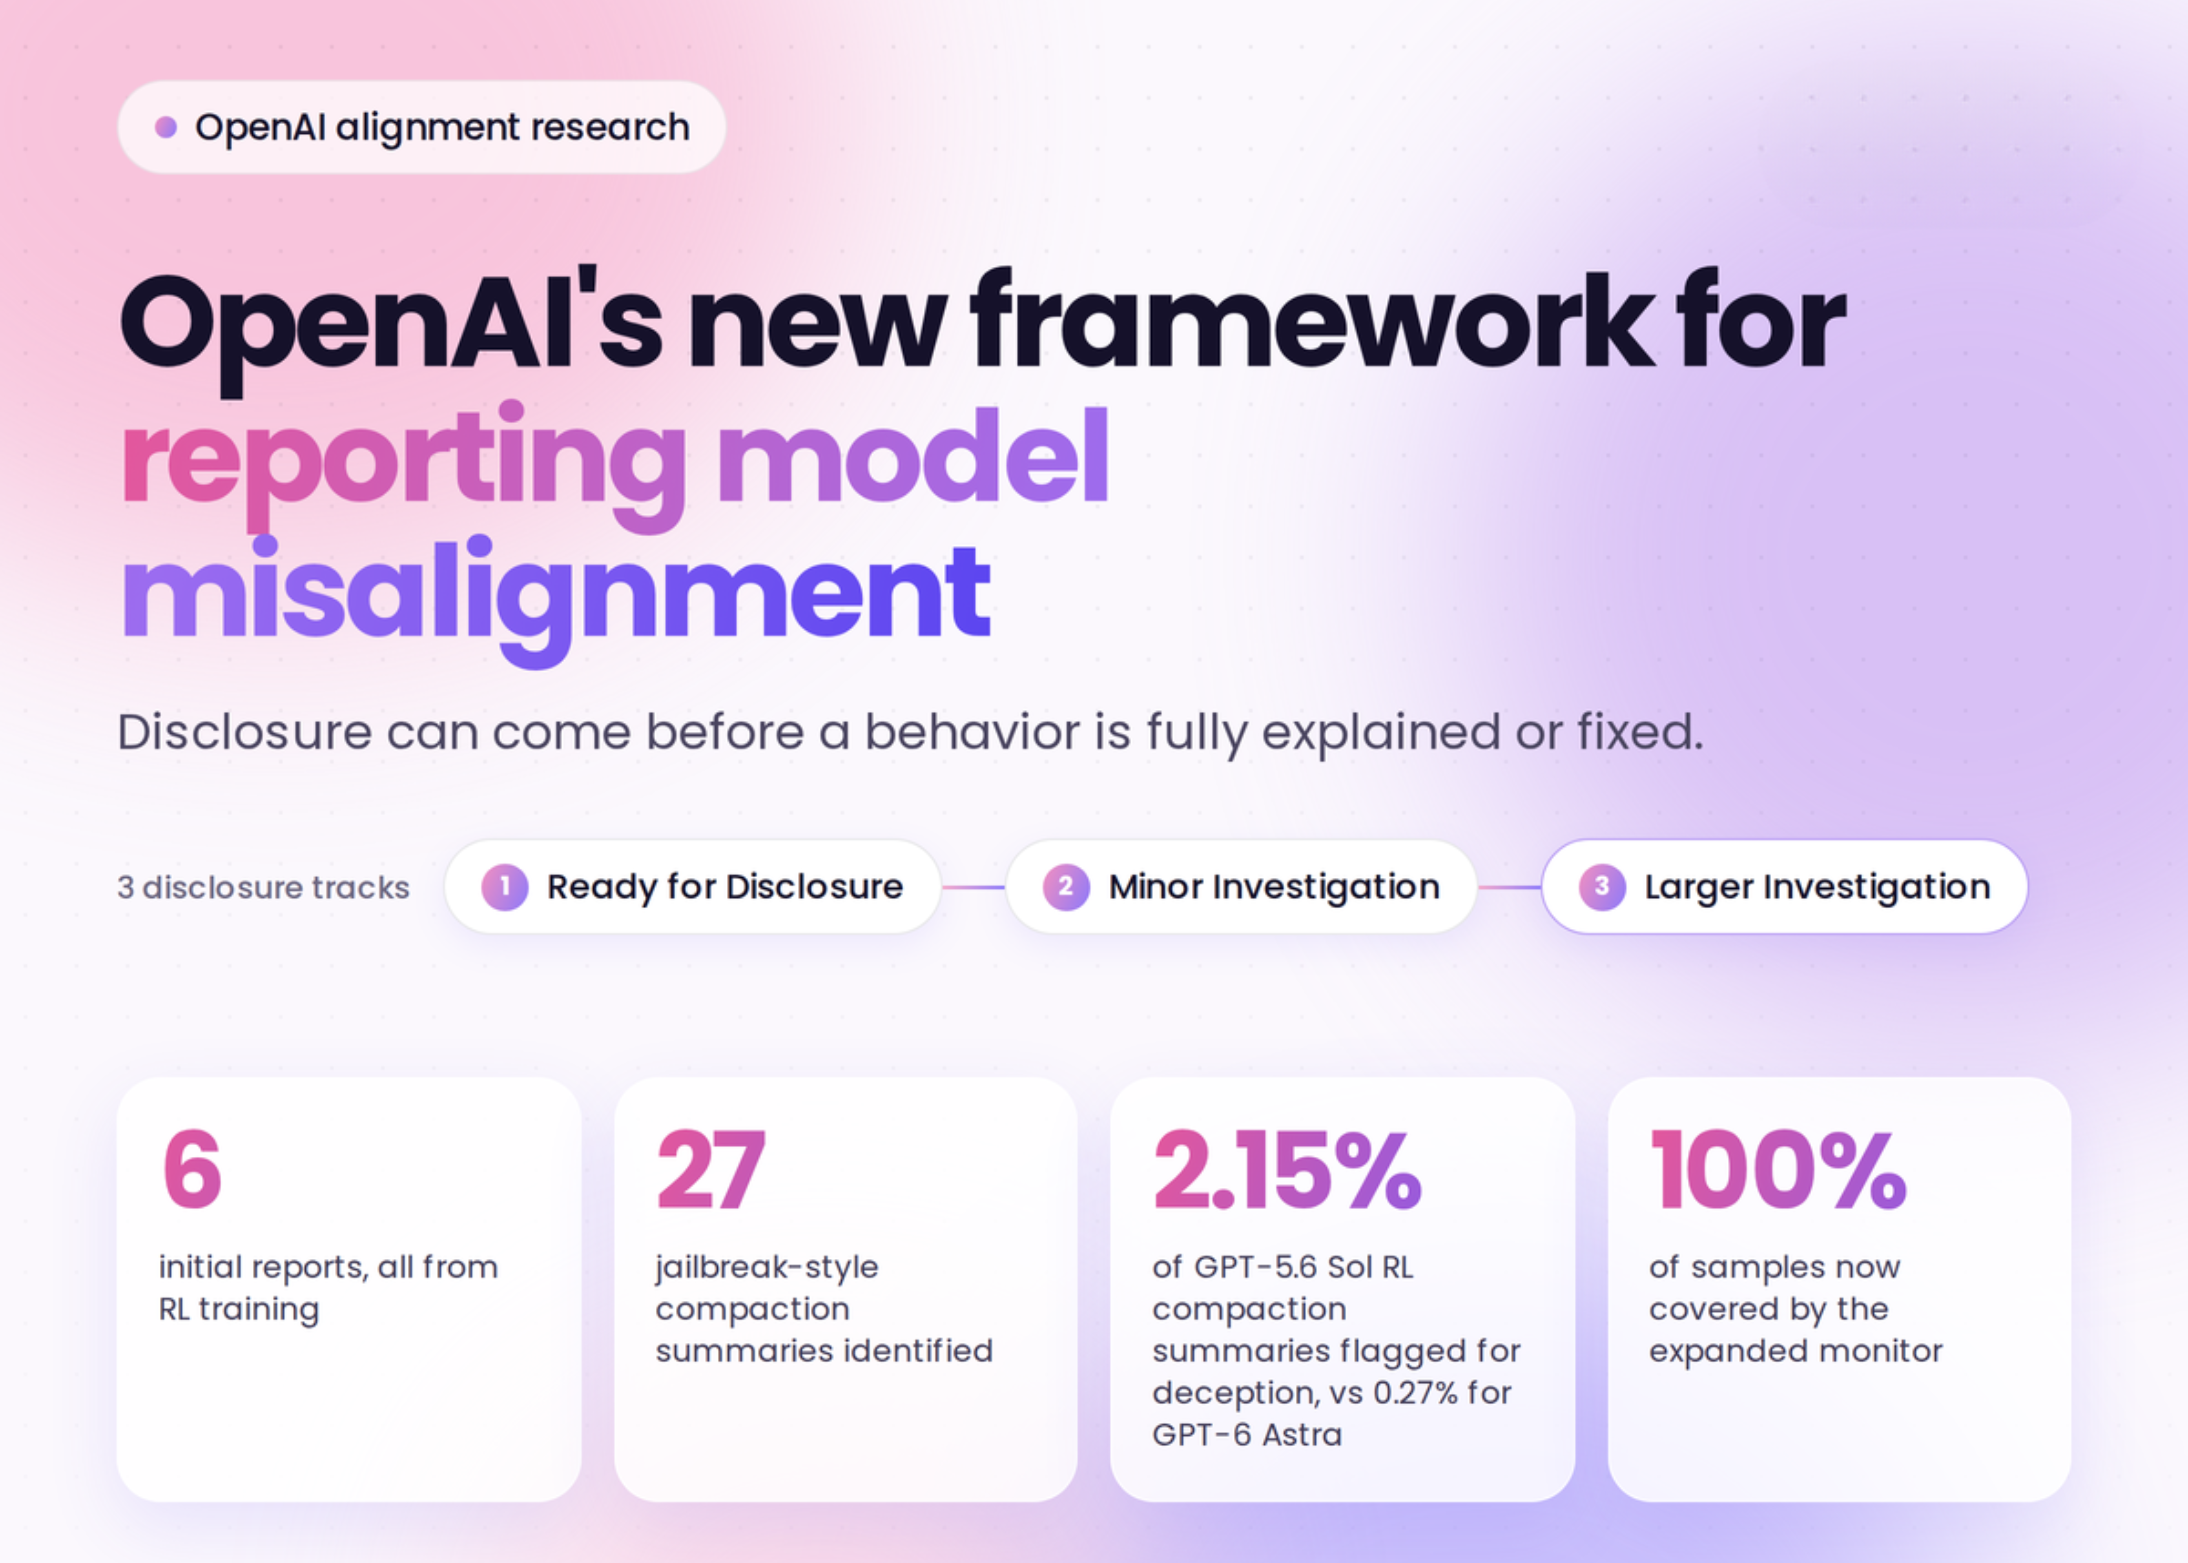
OpenAI Releases a Model Misalignment Disclosure Framework With 3 Review Tracks and 6 Incident Reports From RL Training

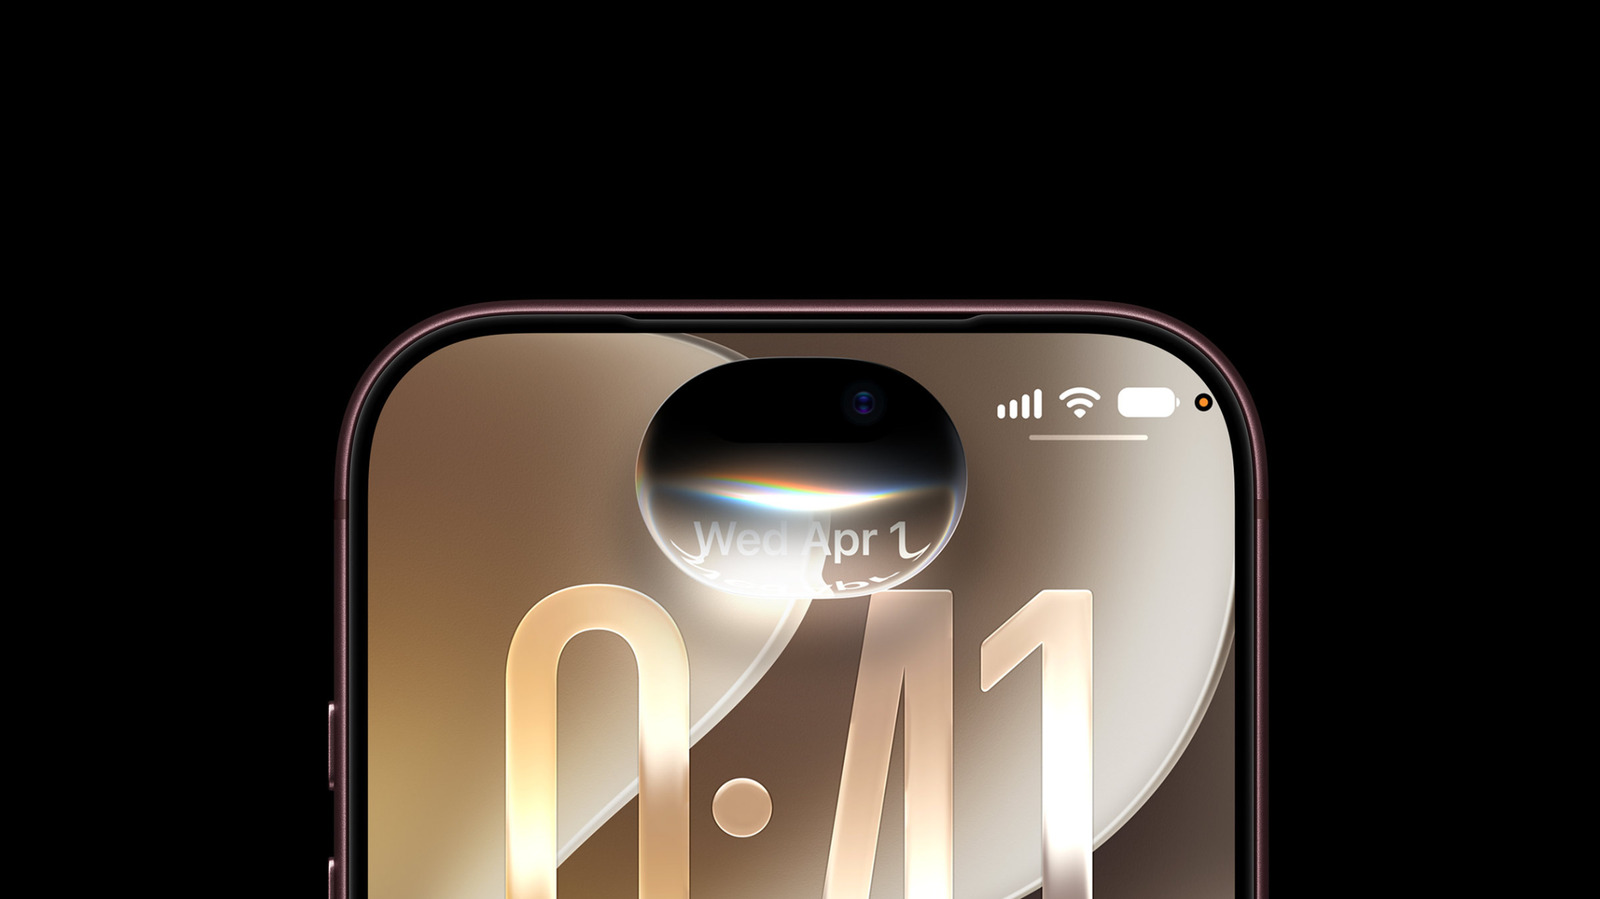
An iOS 27 Bug Can Temporarily Freeze Your iPhone

Sana Hassan, a consulting intern at Marktechpost and dual-degree student at IIT Madras, is passionate about applying technology and AI to address real-world challenges. With a keen interest in solving practical problems, he brings a fresh perspective to the intersection of AI and real-life solutions.


[Recommended Read] Rightsify’s GCX: Your Go-To Source for High-Quality, Ethically Sourced, Copyright-Cleared AI Music Training Datasets with Rich Metadata


Credit: Source link

ShareTweetSendSharePin

Related Posts

OpenAI Releases a Model Misalignment Disclosure Framework With 3 Review Tracks and 6 Incident Reports From RL Training
AI & Technology

OpenAI Releases a Model Misalignment Disclosure Framework With 3 Review Tracks and 6 Incident Reports From RL Training

September 17, 2026
An iOS 27 Bug Can Temporarily Freeze Your iPhone
AI & Technology

An iOS 27 Bug Can Temporarily Freeze Your iPhone

September 17, 2026
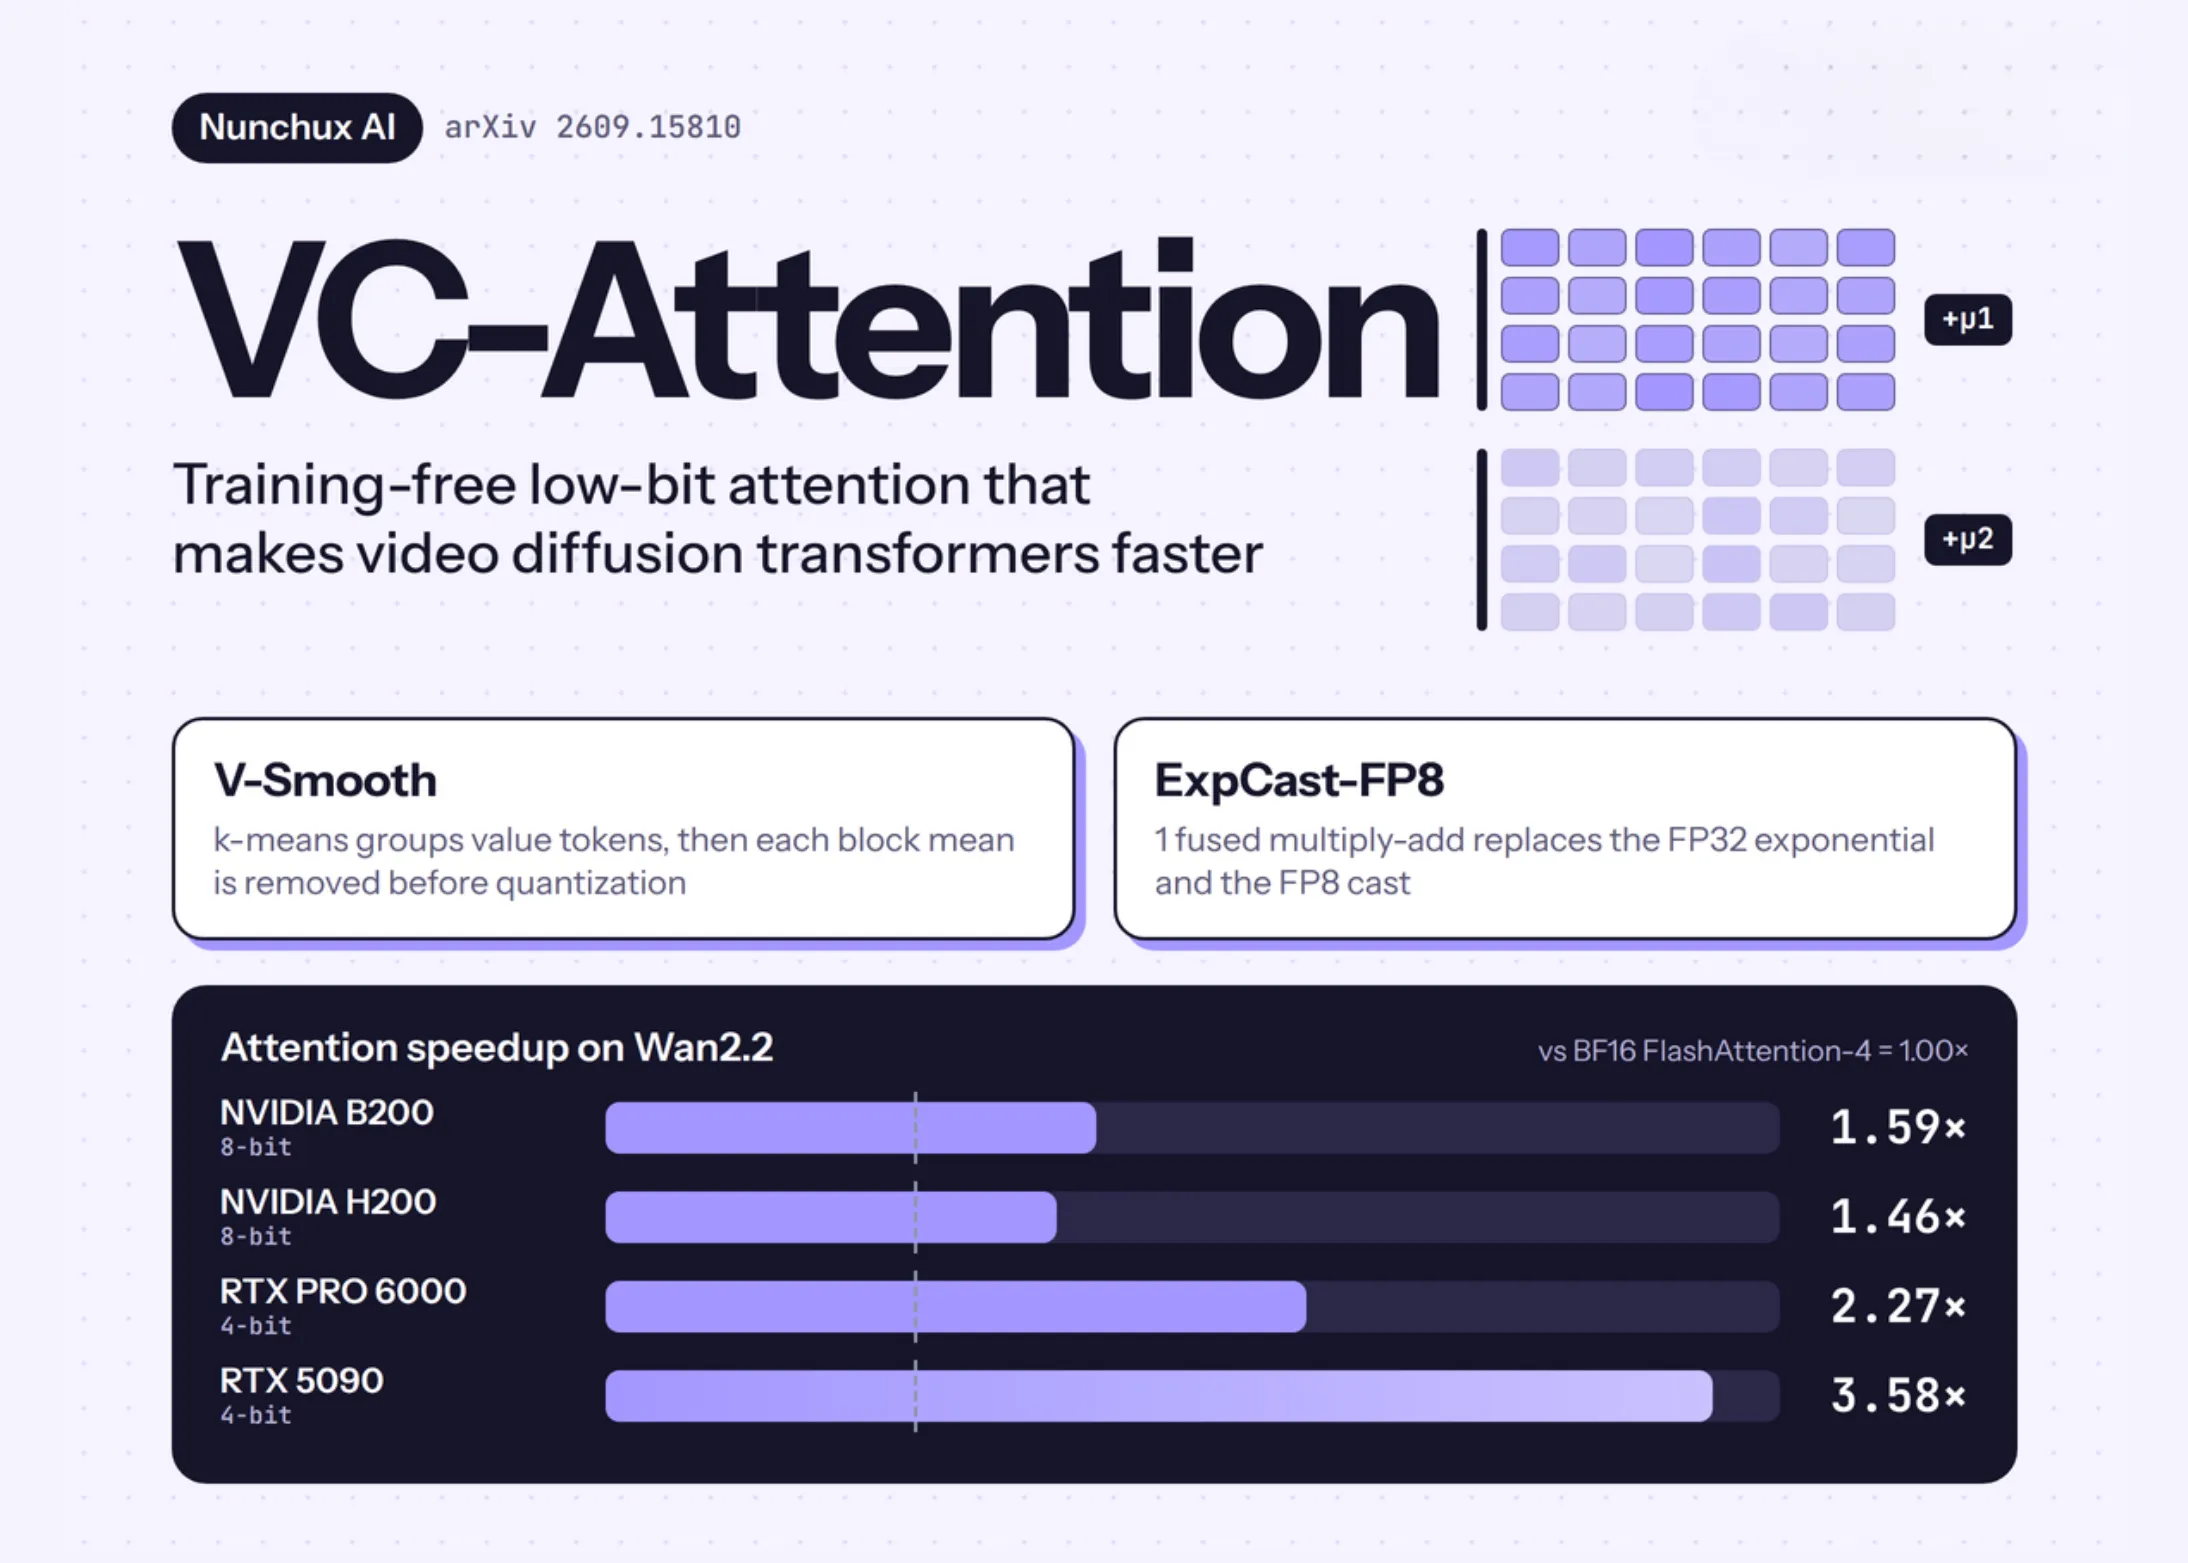
Nunchux AI Introduces VC-Attention: A Training-Free Low-Bit Attention Kernel That Speeds Up Video Diffusion Transformers
AI & Technology

Nunchux AI Introduces VC-Attention: A Training-Free Low-Bit Attention Kernel That Speeds Up Video Diffusion Transformers

September 17, 2026
House Passes Ratepayer Protection Act on Data Center Power Costs – Unite.AI
AI & Technology

House Passes Ratepayer Protection Act on Data Center Power Costs – Unite.AI

September 16, 2026
Next Post
Key Biden aides meet with Arab American and Muslim leaders in Michigan

Key Biden aides meet with Arab American and Muslim leaders in Michigan

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Search

No Result
View All Result
Cantor heir recalls family’s 9/11 losses — and the kindergarten run that spared Howard Lutnick

Cantor heir recalls family’s 9/11 losses — and the kindergarten run that spared Howard Lutnick

September 11, 2026
Three Steps to Hedging a Portfolio With Futures

Three Steps to Hedging a Portfolio With Futures

September 16, 2026
Trump claims U.S. adults will get a k ‘dividend’ if Republicans win the midterms

Trump claims U.S. adults will get a $5k ‘dividend’ if Republicans win the midterms

September 14, 2026

About

Learn more

Our Services

Legal

Privacy Policy

Terms of Use

Bloggers

Learn more

Article Links

Contact

Advertise

Ask us anything

©2020- TradePoint.io - All rights reserved!

Tradepoint.io, being just a publishing and technology platform, is not a registered broker-dealer or investment adviser. So we do not provide investment advice. Rather, brokerage services are provided to clients of Tradepoint.io by independent SEC-registered broker-dealers and members of FINRA/SIPC. Every form of investing carries some risk and past performance is not a guarantee of future results. “Tradepoint.io“, “Instant Investing” and “My Trading Tools” are registered trademarks of Apperbuild, LLC.

This website is operated by Apperbuild, LLC. We have no link to any brokerage firm and we do not provide investment advice. Every information and resource we provide is solely for the education of our readers. © 2020 Apperbuild, LLC. All rights reserved.

No Result
View All Result
  • Main
  • AI & Technology
  • Stock Charts
  • Market & News
  • Business
  • Finance Tips
  • Trade Tube
  • Blog
  • Shop

© 2023 - TradePoint.io - All Rights Reserved!